snapshot of https://github.com/ent/ent.git (master, 2026-09-15; blobs > 131072B omitted)
This commit is contained in:
 upstream-mirror
172
doc/md/aggregate.md
Normal file
172
doc/md/aggregate.md
Normal file
@@ -0,0 +1,172 @@
|
||||
---
|
||||
id: aggregate
|
||||
title: Aggregation
|
||||
---
|
||||
|
||||
## Aggregation
|
||||
|
||||
The `Aggregate` option allows adding one or more aggregation functions.
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/payment"
|
||||
"<project>/ent/pet"
|
||||
)
|
||||
|
||||
func Do(ctx context.Context, client *ent.Client) {
|
||||
// Aggregate one field.
|
||||
sum, err := client.Payment.Query().
|
||||
Aggregate(
|
||||
ent.Sum(payment.Amount),
|
||||
).
|
||||
Int(ctx)
|
||||
|
||||
// Aggregate multiple fields.
|
||||
var v []struct {
|
||||
Sum, Min, Max, Count int
|
||||
}
|
||||
err := client.Pet.Query().
|
||||
Aggregate(
|
||||
ent.Sum(pet.FieldAge),
|
||||
ent.Min(pet.FieldAge),
|
||||
ent.Max(pet.FieldAge),
|
||||
ent.Count(),
|
||||
).
|
||||
Scan(ctx, &v)
|
||||
}
|
||||
```
|
||||
|
||||
## Group By
|
||||
|
||||
Group by `name` and `age` fields of all users, and sum their total age.
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/user"
|
||||
)
|
||||
|
||||
func Do(ctx context.Context, client *ent.Client) {
|
||||
var v []struct {
|
||||
Name string `json:"name"`
|
||||
Age int `json:"age"`
|
||||
Sum int `json:"sum"`
|
||||
Count int `json:"count"`
|
||||
}
|
||||
err := client.User.Query().
|
||||
GroupBy(user.FieldName, user.FieldAge).
|
||||
Aggregate(ent.Count(), ent.Sum(user.FieldAge)).
|
||||
Scan(ctx, &v)
|
||||
}
|
||||
```
|
||||
|
||||
Group by one field.
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/user"
|
||||
)
|
||||
|
||||
func Do(ctx context.Context, client *ent.Client) {
|
||||
names, err := client.User.
|
||||
Query().
|
||||
GroupBy(user.FieldName).
|
||||
Strings(ctx)
|
||||
}
|
||||
```
|
||||
|
||||
## Group By Edge
|
||||
|
||||
Custom aggregation functions can be useful if you want to write your own storage-specific logic.
|
||||
|
||||
The following shows how to group by the `id` and the `name` of all users and calculate the average `age` of their pets.
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/pet"
|
||||
"<project>/ent/user"
|
||||
)
|
||||
|
||||
func Do(ctx context.Context, client *ent.Client) {
|
||||
var users []struct {
|
||||
ID int
|
||||
Name string
|
||||
Average float64
|
||||
}
|
||||
err := client.User.Query().
|
||||
GroupBy(user.FieldID, user.FieldName).
|
||||
Aggregate(func(s *sql.Selector) string {
|
||||
t := sql.Table(pet.Table)
|
||||
s.Join(t).On(s.C(user.FieldID), t.C(pet.OwnerColumn))
|
||||
return sql.As(sql.Avg(t.C(pet.FieldAge)), "average")
|
||||
}).
|
||||
Scan(ctx, &users)
|
||||
}
|
||||
```
|
||||
|
||||
## Having + Group By
|
||||
|
||||
[Custom SQL modifiers](https://entgo.io/docs/feature-flags/#custom-sql-modifiers) can be useful if you want to control all query parts.
|
||||
The following shows how to retrieve the oldest users for each role.
|
||||
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/dialect/sql"
|
||||
"<project>/ent"
|
||||
"<project>/ent/user"
|
||||
)
|
||||
|
||||
func Do(ctx context.Context, client *ent.Client) {
|
||||
var users []struct {
|
||||
Id Int
|
||||
Age Int
|
||||
Role string
|
||||
}
|
||||
err := client.User.Query().
|
||||
Modify(func(s *sql.Selector) {
|
||||
s.GroupBy(user.Role)
|
||||
s.Having(
|
||||
sql.EQ(
|
||||
user.FieldAge,
|
||||
sql.Raw(sql.Max(user.FieldAge)),
|
||||
),
|
||||
)
|
||||
}).
|
||||
ScanX(ctx, &users)
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
**Note:** The `sql.Raw` is crucial to have. It tells the predicate that `sql.Max` is not an argument.
|
||||
|
||||
The above code essentially generates the following SQL query:
|
||||
|
||||
```sql
|
||||
SELECT * FROM user GROUP BY user.role HAVING user.age = MAX(user.age)
|
||||
```
|
||||
386
doc/md/blob-storage.md
Normal file
386
doc/md/blob-storage.md
Normal file
@@ -0,0 +1,386 @@
|
||||
---
|
||||
id: blob-storage
|
||||
title: Blob Storage
|
||||
---
|
||||
|
||||
## Overview
|
||||
|
||||
Ent's `field.Blob` type stores field data in external blob storage (e.g., S3, GCS, local filesystem)
|
||||
rather than in the database. The database only stores a **key** (a short string) referencing the blob.
|
||||
This keeps database rows small while supporting arbitrarily large binary or text payloads.
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Define a schema with blob fields
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"crypto"
|
||||
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
type Document struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (Document) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").Unique(),
|
||||
field.Blob("content"),
|
||||
field.Blob("avatar").Optional(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### 2. Configure blob storage
|
||||
|
||||
Each entity type with blob fields requires a `BlobOpener` — a function that opens a
|
||||
blob bucket for a given field name:
|
||||
|
||||
```go
|
||||
import (
|
||||
"context"
|
||||
|
||||
"myapp/ent"
|
||||
"myapp/ent/document"
|
||||
|
||||
_ "gocloud.dev/blob/s3blob" // or fileblob, gcsblob, etc.
|
||||
)
|
||||
|
||||
client := ent.NewClient(
|
||||
ent.Driver(drv),
|
||||
ent.WithBlobOpeners(ent.BlobOpeners{
|
||||
Document: func(ctx context.Context, field string) (ent.Blob, error) {
|
||||
switch field {
|
||||
case document.FieldContent:
|
||||
return blob.OpenBucket(ctx, "s3://my-bucket/content")
|
||||
case document.FieldAvatar:
|
||||
return blob.OpenBucket(ctx, "s3://my-bucket/avatars")
|
||||
default:
|
||||
return nil, fmt.Errorf("unknown blob field: %s", field)
|
||||
}
|
||||
},
|
||||
}),
|
||||
)
|
||||
```
|
||||
|
||||
### 3. Use the generated API
|
||||
|
||||
```go
|
||||
// Create — pass []byte directly.
|
||||
doc := client.Document.Create().
|
||||
SetName("readme").
|
||||
SetContent([]byte("Hello, World!")).
|
||||
SaveX(ctx)
|
||||
|
||||
// Read — the struct field holds the loaded value.
|
||||
fmt.Println(string(doc.Content)) // "Hello, World!"
|
||||
|
||||
// Update
|
||||
doc = doc.Update().
|
||||
SetContent([]byte("Updated content")).
|
||||
SaveX(ctx)
|
||||
```
|
||||
|
||||
## `field.Blob` API
|
||||
|
||||
| Method | Description |
|
||||
|--------|-------------|
|
||||
| `Optional()` | Field is nullable; not required on create. |
|
||||
| `Nillable()` | Struct field is a pointer (distinguishes zero value from unset). |
|
||||
| `Immutable()` | Field can only be set on create, not updated. |
|
||||
| `Lazy()` | Mutation accepts `io.Reader`; struct field omitted; use Reader method to read. |
|
||||
| `HashKey(h)` | Content-addressable key via hash (default: `crypto.SHA256`). |
|
||||
| `UUIDKey()` | Random UUID v7 key per write. |
|
||||
| `CheckRefs()` | Verify no row still holds a key before deleting the object. Use with `HashKey`. |
|
||||
| `DualWrite(...)` | Migration mode: write to both blob storage and database column. |
|
||||
| `GoType(typ)` | Override the default `[]byte` Go type. |
|
||||
| `ValueScanner(vs)` | Custom codec between Go type and raw bytes (required for non-`[]byte`/`string` GoType). |
|
||||
| `StorageKey(key)` | Override the database column name. |
|
||||
| `StructTag(s)` | Set the struct tag on the generated field. |
|
||||
| `Comment(c)` | Set the field comment. |
|
||||
| `Annotations(...)` | Attach codegen annotations. |
|
||||
| `Deprecated(...)` | Mark the field as deprecated. |
|
||||
|
||||
## Key Strategies
|
||||
|
||||
Every blob field requires a **key function** that determines the storage key for a given
|
||||
piece of data. By default (when neither `UUIDKey` nor `HashKey` is called), blobs use
|
||||
SHA-256 content hashing.
|
||||
|
||||
### HashKey (default)
|
||||
|
||||
Content-addressable storage: the data is hashed to produce the key. Identical content
|
||||
always maps to the same key, enabling deduplication and write-skip optimizations on update.
|
||||
|
||||
```go
|
||||
field.Blob("content").HashKey(crypto.SHA256)
|
||||
```
|
||||
|
||||
On update, if the new content produces the same hash as the existing key, the write to
|
||||
blob storage is skipped entirely.
|
||||
|
||||
Because rows with identical content share one object, pair `HashKey` with
|
||||
[`CheckRefs`](#shared-objects-and-checkrefs) so cleanup does not remove an object another row
|
||||
still points at.
|
||||
|
||||
### UUIDKey
|
||||
|
||||
Each write generates a new random UUID (v7) as the storage key. This guarantees uniqueness
|
||||
but does not deduplicate.
|
||||
|
||||
```go
|
||||
field.Blob("content").UUIDKey()
|
||||
```
|
||||
|
||||
No two rows can hold the same key, so cleanup can remove an object as soon as its row lets go.
|
||||
Leave [`CheckRefs`](#shared-objects-and-checkrefs) off here — the lookup would run on every
|
||||
mutation to answer a question whose answer is fixed.
|
||||
|
||||
## Lazy Fields
|
||||
|
||||
By default, blob data is automatically loaded into the entity struct field when the row is
|
||||
scanned from the database. For large blobs where you don't always need the data in memory,
|
||||
use `Lazy()`:
|
||||
|
||||
```go
|
||||
field.Blob("content").Lazy()
|
||||
```
|
||||
|
||||
With `Lazy()`:
|
||||
- The **mutation builder** accepts an `io.Reader` (which is fully buffered before writing).
|
||||
- The entity **struct field is omitted** — data is not loaded on scan.
|
||||
- A **Reader method** (e.g., `ContentReader`) is generated to explicitly open a reader from storage.
|
||||
|
||||
```go
|
||||
// Create with io.Reader.
|
||||
doc := client.Document.Create().
|
||||
SetName("large-file").
|
||||
SetContent(bytes.NewReader(largeData)).
|
||||
SaveX(ctx)
|
||||
|
||||
// Read explicitly via the Reader method.
|
||||
rc, err := doc.ContentReader(ctx)
|
||||
if err != nil { ... }
|
||||
defer rc.Close()
|
||||
data, _ := io.ReadAll(rc)
|
||||
```
|
||||
|
||||
## DualWrite (Migration Mode)
|
||||
|
||||
`DualWrite()` preserves the original bytes column alongside the blob key column. This is
|
||||
useful when migrating an existing column to blob storage:
|
||||
|
||||
```go
|
||||
field.Blob("payload").
|
||||
DualWrite(map[string]string{
|
||||
dialect.MySQL: "json",
|
||||
dialect.Postgres: "jsonb",
|
||||
dialect.SQLite: "json",
|
||||
})
|
||||
```
|
||||
|
||||
In DualWrite mode:
|
||||
- **Writes** go to both blob storage and the database column.
|
||||
- **Reads** prefer blob storage (if a key exists) and fall back to the database column.
|
||||
|
||||
The optional `columnType` argument overrides the database column type per dialect to prevent
|
||||
schema drift when migrating from an existing column definition.
|
||||
|
||||
## Custom GoType
|
||||
|
||||
Blob fields default to `[]byte`. You can override the Go type:
|
||||
|
||||
```go
|
||||
// String type (automatic conversion).
|
||||
field.Blob("description").GoType("")
|
||||
|
||||
// Custom struct with a ValueScanner.
|
||||
field.Blob("config").
|
||||
GoType(&MyConfig{}).
|
||||
ValueScanner(configScanner{})
|
||||
```
|
||||
|
||||
When using a custom `GoType` other than `string`, a `ValueScanner` must be provided
|
||||
to encode/decode between the Go type and the raw bytes stored in blob storage.
|
||||
|
||||
## Blob Interface
|
||||
|
||||
Any blob storage backend must implement the `ent.Blob` interface:
|
||||
|
||||
```go
|
||||
type Blob interface {
|
||||
NewReader(ctx context.Context, key string) (io.ReadCloser, error)
|
||||
NewWriter(ctx context.Context, key string) (io.WriteCloser, error)
|
||||
Delete(ctx context.Context, key string) error
|
||||
Close() error
|
||||
}
|
||||
```
|
||||
|
||||
- `NewReader` should return `fs.ErrNotExist` (or a wrapping error) when the key does not exist.
|
||||
- `Delete` should return `nil` (not an error) when the key does not exist.
|
||||
|
||||
The [Go CDK `blob` package](https://gocloud.dev/howto/blob/) provides implementations
|
||||
for S3, GCS, Azure, and local filesystem that satisfy this interface via a thin adapter.
|
||||
|
||||
## Lifecycle and Cleanup
|
||||
|
||||
### Shared objects and `CheckRefs`
|
||||
|
||||
By default, cleanup removes a blob object as soon as the row that wrote it goes away or moves
|
||||
off the key. That is correct exactly when no two rows can hold the same key — the guarantee
|
||||
[`UUIDKey`](#uuidkey) gives you, since every write generates a fresh key.
|
||||
|
||||
It is **not** correct for `HashKey`. There the key *is* the content, so any two rows holding
|
||||
identical content point at one object in storage. That is what makes deduplication work, and
|
||||
it means removing the object because one row let go can strand every other row still pointing
|
||||
at it. Concretely, without the check:
|
||||
|
||||
- A failed INSERT rolls back "its" blob — which may be the object an existing row with the
|
||||
same content already points at.
|
||||
- Deleting one of two rows with identical content removes the object the other still uses.
|
||||
- Updating a row off a shared key removes an object another row still holds.
|
||||
|
||||
`CheckRefs` turns on the guard. Add it to every content-addressed blob field:
|
||||
|
||||
```go
|
||||
field.Blob("content").
|
||||
HashKey(crypto.SHA256).
|
||||
CheckRefs()
|
||||
```
|
||||
|
||||
It is opt-in and per field, so a schema can mix strategies: pay for the lookup on the
|
||||
content-addressed fields and skip it on the UUID-keyed ones, where the answer is always the
|
||||
same. With it on, every cleanup path looks up the keys it is about to remove in their key
|
||||
columns and skips the ones a row still holds.
|
||||
|
||||
The lookup is timed so the table already reads the way the mutation will leave it — before
|
||||
the INSERT for blobs written ahead of a row, after the UPDATE or DELETE for keys the mutation
|
||||
gives up — and always while the statement and its transaction are still open. A row inserted
|
||||
concurrently between the lookup and the delete is not seen. Closing that window entirely
|
||||
requires reference counting or a periodic sweep of the bucket against the key columns.
|
||||
|
||||
### Index the key columns
|
||||
|
||||
**Index the key column of every field using `CheckRefs`.** The lookup asks only *whether* a
|
||||
key is still in use, never how often, so an index lets it stop at the first matching row
|
||||
instead of scanning the table. Every create, update, and delete touching that field runs the
|
||||
query, so an unindexed key column turns each of those mutations into a full table scan.
|
||||
|
||||
Declare the index by **field** name — for a blob field, `index.Fields` targets the generated
|
||||
key column (`<field>_key` by default):
|
||||
|
||||
```go
|
||||
func (Document) Indexes() []ent.Index {
|
||||
return []ent.Index{
|
||||
index.Fields("content"), // indexes content_key
|
||||
index.Fields("avatar"), // indexes avatar_key
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Leave them non-unique — rows sharing content share a key, which is the whole point.
|
||||
|
||||
One exception: a `DualWrite` field that is not also `Lazy()` keeps a real data column, and
|
||||
`index.Fields` targets *that* column rather than the key column. For those fields, create the
|
||||
index on `<field>_key` outside the schema.
|
||||
|
||||
Fields without `CheckRefs` need no such index — they never run the lookup.
|
||||
|
||||
### Create
|
||||
|
||||
Blobs are written **before** the database row is inserted. If the SQL INSERT fails
|
||||
(e.g., constraint violation), the generated code deletes the just-written blobs — except,
|
||||
for `CheckRefs` fields, any that rows in the database already reference.
|
||||
|
||||
### Update
|
||||
|
||||
On update:
|
||||
1. New blob data is written to storage.
|
||||
2. The SQL UPDATE executes.
|
||||
3. On success, old blobs are deleted — for `CheckRefs` fields, unless another row still
|
||||
references them.
|
||||
4. On SQL failure, newly-written blobs are rolled back (deleted) under the same rule.
|
||||
|
||||
When using `HashKey`, if the content hasn't changed (same hash), the write is skipped entirely.
|
||||
|
||||
### Delete
|
||||
|
||||
Generated delete builders query existing blob keys before deleting the row, then remove
|
||||
the blobs from storage after a successful SQL DELETE — keeping, for `CheckRefs` fields, any
|
||||
object that rows outside the deleted set still reference.
|
||||
|
||||
## OnConflict (Upsert)
|
||||
|
||||
Blob fields work with `OnConflict` / upsert builders. Blobs are written to storage
|
||||
**before** the SQL executes. If the INSERT succeeds (no conflict), the new key is stored.
|
||||
If there is a conflict, behavior depends on the conflict action and key strategy.
|
||||
|
||||
The following per-field methods are generated on the upsert builder:
|
||||
|
||||
- **`Update<Field>()`** — Sets the blob key column (and data column for DualWrite fields) to
|
||||
the value provided on create.
|
||||
- **`Clear<Field>()`** — Nulls the blob key column (and data column for DualWrite). Only
|
||||
generated for optional fields. **Note:** this does not delete the old blob from storage —
|
||||
the previously-referenced blob becomes orphaned. Use a regular Update with `Clear<Field>()`
|
||||
if you need storage cleanup.
|
||||
|
||||
```go
|
||||
client.Document.Create().
|
||||
SetName("readme").
|
||||
SetContent([]byte("data")).
|
||||
SetAttachment([]byte("file")).
|
||||
OnConflict().
|
||||
UpdateContent(). // update only the content blob
|
||||
UpdateAttachment(). // update only the attachment blob
|
||||
ExecX(ctx)
|
||||
```
|
||||
|
||||
You can also use `UpdateNewValues()` to update all fields (including all blob key columns)
|
||||
at once.
|
||||
|
||||
### With HashKey (content-addressable)
|
||||
|
||||
Since the key is derived from content, identical data always produces the same key:
|
||||
|
||||
- **`Update<Field>()`** — The SQL updates the key column to the new key. If the content
|
||||
matches what the row already held, the key is unchanged and it is a no-op in storage.
|
||||
If the content differs, the row moves to the new key and the old object is left behind —
|
||||
`OnConflict` does not query old keys the way a regular Update does.
|
||||
- **`Ignore()`** — The SQL sets each column to itself. If the content differs from the
|
||||
existing row's, the blob written to storage has no database reference.
|
||||
- **`DoNothing()`** — No row is inserted, which surfaces as `sql.ErrNoRows`. The blob
|
||||
written to storage is deleted, unless the conflicting row already references that same
|
||||
key — the common case when the content is identical.
|
||||
|
||||
Upserting identical content is idempotent in storage: the write lands on the key that is
|
||||
already there, and cleanup leaves it in place because the existing row references it.
|
||||
|
||||
```go
|
||||
client.Document.Create().
|
||||
SetName("readme").
|
||||
SetContent([]byte("data")).
|
||||
OnConflict().
|
||||
UpdateContent().
|
||||
ExecX(ctx)
|
||||
```
|
||||
|
||||
### With UUIDKey (random keys)
|
||||
|
||||
Each write generates a new unique key. This means the blob written before the SQL is always
|
||||
at a **new** key that didn't previously exist:
|
||||
|
||||
- **`Update<Field>()`** — The SQL updates the key column to the new UUID key. The old blob
|
||||
at the previous key becomes orphaned and is **not** automatically cleaned up (OnConflict
|
||||
does not query old keys like a regular Update does).
|
||||
- **`Ignore()`** — The SQL succeeds without changing anything; the row keeps its existing
|
||||
key. The newly-written blob is orphaned in storage with no database reference.
|
||||
- **`DoNothing()`** — No row is inserted, which surfaces as `sql.ErrNoRows`. Because a fresh
|
||||
UUID is referenced by nobody, the newly-written blob is deleted.
|
||||
|
||||
For these reasons, `UUIDKey` is **not recommended** with `OnConflict`. If you need upsert
|
||||
semantics, prefer `HashKey` which is inherently idempotent.
|
||||
293
doc/md/ci.mdx
Normal file
293
doc/md/ci.mdx
Normal file
@@ -0,0 +1,293 @@
|
||||
---
|
||||
id: ci
|
||||
title: Continuous Integration
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
To ensure the quality of their software, teams often apply _Continuous
|
||||
Integration_ workflows, commonly known as CI. With CI, teams continuously run a suite
|
||||
of automated verifications against every change to the code-base. During CI,
|
||||
teams may run many kinds of verifications:
|
||||
* Compilation or build of the most recent version to make sure it
|
||||
isn't broken.
|
||||
* Linting to enforce any accepted code-style standards.
|
||||
* Unit tests that verify individual components work as expected
|
||||
and that changes to the codebase do not cause regressions in
|
||||
other areas.
|
||||
* Security scans to make sure no known vulnerabilities are introduced
|
||||
to the codebase.
|
||||
* And much more!
|
||||
|
||||
From our discussions with the Ent community, we have learned
|
||||
that many teams using Ent already use CI and would like to enforce some
|
||||
Ent-specific verifications into their workflows.
|
||||
|
||||
To support the community with this effort we have started this guide which
|
||||
documents common best practices to verify in CI and introduces
|
||||
[ent/contrib/ci](https://github.com/ent/contrib/tree/master/ci) a GitHub Action
|
||||
we maintain that codifies them.
|
||||
|
||||
## Verify all generated files are checked in
|
||||
|
||||
Ent heavily relies on code generation. In our experience, generated code
|
||||
should always be checked into source control. This is done for two reasons:
|
||||
* If generated code is checked into source control, it can be read
|
||||
along with the main application code. Having generated code present when
|
||||
the code is reviewed or when a repository is browsed is essential to get
|
||||
a complete picture of how things work.
|
||||
* Differences in development environments between team members can easily be
|
||||
spotted and remedied. This further reduces the chance of "it works on my
|
||||
machine" type issues since everyone is running the same code.
|
||||
|
||||
If you're using GitHub for source control, it's easy to verify that all generated
|
||||
files are checked in with the `ent/contrib/ci` GitHub Action.
|
||||
Otherwise, we supply a simple bash script that you can integrate in your existing
|
||||
CI flow.
|
||||
|
||||
<Tabs
|
||||
defaultValue="gh"
|
||||
values={[
|
||||
{label: 'GitHub Action', value: 'gh'},
|
||||
{label: 'Bash', value: 'bash'},
|
||||
]}>
|
||||
<TabItem value="gh">
|
||||
Simply add a file named `.github/workflows/ent-ci.yaml` in your repository:
|
||||
|
||||
```yaml
|
||||
name: EntCI
|
||||
on:
|
||||
push:
|
||||
# Run whenever code is changed in the master.
|
||||
branches:
|
||||
- master
|
||||
# Run on PRs where something changed under the `ent/` directory.
|
||||
pull_request:
|
||||
paths:
|
||||
- 'ent/*'
|
||||
jobs:
|
||||
ent:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3.0.1
|
||||
- uses: actions/setup-go@v3
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
- uses: ent/contrib/ci@master
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="bash">
|
||||
|
||||
```bash
|
||||
go generate ./...
|
||||
status=$(git status --porcelain)
|
||||
if [ -n "$status" ]; then
|
||||
echo "you need to run 'go generate ./...' and commit the changes"
|
||||
echo "$status"
|
||||
exit 1
|
||||
fi
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Lint migration files
|
||||
|
||||
Changes to your project's Ent schema almost always result in a modification
|
||||
of your database. If you are using [Versioned Migrations](/docs/versioned-migrations)
|
||||
to manage changes to your database schema, you can run [migration linting](https://atlasgo.io/versioned/lint)
|
||||
as part of your continuous integration flow. This is done for multiple reasons:
|
||||
|
||||
* Linting replays your migration directory on a [database container](https://atlasgo.io/concepts/dev-database) to
|
||||
make sure all SQL statements are valid and in the correct order.
|
||||
* [Migration directory integrity](/docs/versioned-migrations#atlas-migration-directory-integrity-file)
|
||||
is enforced - ensuring that history wasn't accidentally changed and that migrations that are
|
||||
planned in parallel are unified to a clean linear history.
|
||||
* Destructive changes are detected notifying you of any potential data loss that may be
|
||||
caused by your migrations way before they reach your production database.
|
||||
* Linting detects data-dependant changes that _may_ fail upon deployment and require
|
||||
more careful review from your side.
|
||||
|
||||
If you're using GitHub, you can use the [Official Atlas Action](https://github.com/ariga/atlas-action)
|
||||
to run migration linting during CI.
|
||||
|
||||
Add `.github/workflows/atlas-ci.yaml` to your repo with the following contents:
|
||||
<Tabs
|
||||
defaultValue="mysql"
|
||||
values={[
|
||||
{label: 'MySQL', value: 'mysql'},
|
||||
{label: 'MariaDB', value: 'maria'},
|
||||
{label: 'PostgreSQL', value: 'postgres'},
|
||||
{label: 'SQLite', value: 'sqlite'},
|
||||
]}>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```yaml
|
||||
name: Atlas CI
|
||||
on:
|
||||
# Run whenever code is changed in the master branch,
|
||||
# change this to your root branch.
|
||||
push:
|
||||
branches:
|
||||
- master
|
||||
# Run on PRs where something changed under the `ent/migrate/migrations/` directory.
|
||||
pull_request:
|
||||
paths:
|
||||
- 'ent/migrate/migrations/*'
|
||||
jobs:
|
||||
lint:
|
||||
services:
|
||||
# Spin up a mysql:8.0.29 container to be used as the dev-database for analysis.
|
||||
mysql:
|
||||
image: mysql:8.0.29
|
||||
env:
|
||||
MYSQL_ROOT_PASSWORD: pass
|
||||
MYSQL_DATABASE: test
|
||||
ports:
|
||||
- "3306:3306"
|
||||
options: >-
|
||||
--health-cmd "mysqladmin ping -ppass"
|
||||
--health-interval 10s
|
||||
--health-start-period 10s
|
||||
--health-timeout 5s
|
||||
--health-retries 10
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: ariga/setup-atlas@v0
|
||||
with:
|
||||
cloud-token: ${{ secrets.ATLAS_CLOUD_TOKEN }}
|
||||
- uses: ariga/atlas-action/migrate/lint@v1
|
||||
with:
|
||||
dir: 'file://ent/migrate/migrations'
|
||||
dir-name: 'my-project' # The name of the project in Atlas Cloud
|
||||
dev-url: "mysql://root:pass@localhost:3306/dev"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="maria">
|
||||
|
||||
```yaml
|
||||
name: Atlas CI
|
||||
on:
|
||||
# Run whenever code is changed in the master branch,
|
||||
# change this to your root branch.
|
||||
push:
|
||||
branches:
|
||||
- master
|
||||
# Run on PRs where something changed under the `ent/migrate/migrations/` directory.
|
||||
pull_request:
|
||||
paths:
|
||||
- 'ent/migrate/migrations/*'
|
||||
jobs:
|
||||
lint:
|
||||
services:
|
||||
# Spin up a maria:11 container to be used as the dev-database for analysis.
|
||||
mariadb:
|
||||
image: mariadb:11
|
||||
env:
|
||||
MYSQL_DATABASE: dev
|
||||
MYSQL_ROOT_PASSWORD: pass
|
||||
ports:
|
||||
- "3306:3306"
|
||||
options: >-
|
||||
--health-cmd "healthcheck.sh --su-mysql --connect --innodb_initialized"
|
||||
--health-interval 10s
|
||||
--health-start-period 10s
|
||||
--health-timeout 5s
|
||||
--health-retries 10
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: ariga/setup-atlas@v0
|
||||
with:
|
||||
cloud-token: ${{ secrets.ATLAS_CLOUD_TOKEN }}
|
||||
- uses: ariga/atlas-action/migrate/lint@v1
|
||||
with:
|
||||
dir: 'file://ent/migrate/migrations'
|
||||
dir-name: 'my-project' # The name of the project in Atlas Cloud
|
||||
dev-url: "maria://root:pass@localhost:3306/dev"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="postgres">
|
||||
|
||||
```yaml
|
||||
name: Atlas CI
|
||||
on:
|
||||
# Run whenever code is changed in the master branch,
|
||||
# change this to your root branch.
|
||||
push:
|
||||
branches:
|
||||
- master
|
||||
# Run on PRs where something changed under the `ent/migrate/migrations/` directory.
|
||||
pull_request:
|
||||
paths:
|
||||
- 'ent/migrate/migrations/*'
|
||||
jobs:
|
||||
lint:
|
||||
services:
|
||||
# Spin up a postgres:15 container to be used as the dev-database for analysis.
|
||||
postgres:
|
||||
image: postgres:15
|
||||
env:
|
||||
POSTGRES_DB: dev
|
||||
POSTGRES_PASSWORD: pass
|
||||
ports:
|
||||
- 5432:5432
|
||||
options: >-
|
||||
--health-cmd pg_isready
|
||||
--health-interval 10s
|
||||
--health-start-period 10s
|
||||
--health-timeout 5s
|
||||
--health-retries 5
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: ariga/setup-atlas@v0
|
||||
with:
|
||||
cloud-token: ${{ secrets.ATLAS_CLOUD_TOKEN }}
|
||||
- uses: ariga/atlas-action/migrate/lint@v1
|
||||
with:
|
||||
dir: 'file://ent/migrate/migrations'
|
||||
dir-name: 'my-project' # The name of the project in Atlas Cloud
|
||||
dev-url: postgres://postgres:pass@localhost:5432/dev?sslmode=disable
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sqlite">
|
||||
|
||||
```yaml
|
||||
name: Atlas CI
|
||||
on:
|
||||
# Run whenever code is changed in the master branch,
|
||||
# change this to your root branch.
|
||||
push:
|
||||
branches:
|
||||
- master
|
||||
# Run on PRs where something changed under the `ent/migrate/migrations/` directory.
|
||||
pull_request:
|
||||
paths:
|
||||
- 'ent/migrate/migrations/*'
|
||||
jobs:
|
||||
lint:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: ariga/setup-atlas@v0
|
||||
with:
|
||||
cloud-token: ${{ secrets.ATLAS_CLOUD_TOKEN }}
|
||||
- uses: ariga/atlas-action/migrate/lint@v1
|
||||
with:
|
||||
dir: 'file://ent/migrate/migrations'
|
||||
dir-name: 'my-project' # The name of the project in Atlas Cloud
|
||||
dev-url: sqlite://file?mode=memory&_fk=1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
Notice that running `atlas migrate lint` requires a clean [dev-database](https://atlasgo.io/concepts/dev-database)
|
||||
which is provided by the `services` block in the example code above.
|
||||
296
doc/md/code-gen.md
Normal file
296
doc/md/code-gen.md
Normal file
@@ -0,0 +1,296 @@
|
||||
---
|
||||
id: code-gen
|
||||
title: Introduction
|
||||
---
|
||||
|
||||
## Installation
|
||||
|
||||
The project comes with a codegen tool called `ent`. In order to install
|
||||
`ent` run the following command:
|
||||
|
||||
```bash
|
||||
go get entgo.io/ent/cmd/ent
|
||||
```
|
||||
|
||||
## Initialize A New Schema
|
||||
|
||||
In order to generate one or more schema templates, run `ent init` as follows:
|
||||
|
||||
```bash
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new User Pet
|
||||
```
|
||||
|
||||
`init` will create the 2 schemas (`user.go` and `pet.go`) under the `ent/schema` directory.
|
||||
If the `ent` directory does not exist, it will create it as well. The convention
|
||||
is to have an `ent` directory under the root directory of the project.
|
||||
|
||||
## Generate Assets
|
||||
|
||||
After adding a few [fields](schema-fields.mdx) and [edges](schema-edges.mdx), you want to generate
|
||||
the assets for working with your entities. Run `ent generate` from the root directory of the project,
|
||||
or use `go generate`:
|
||||
|
||||
|
||||
```bash
|
||||
go generate ./ent
|
||||
```
|
||||
|
||||
The `generate` command generates the following assets for the schemas:
|
||||
|
||||
- `Client` and `Tx` objects used for interacting with the graph.
|
||||
- CRUD builders for each schema type. See [CRUD](crud.mdx) for more info.
|
||||
- Entity object (Go struct) for each of the schema types.
|
||||
- Package containing constants and predicates used for interacting with the builders.
|
||||
- A `migrate` package for SQL dialects. See [Migration](migrate.md) for more info.
|
||||
- A `hook` package for adding mutation middlewares. See [Hooks](hooks.md) for more info.
|
||||
|
||||
## Version Compatibility Between `entc` And `ent`
|
||||
|
||||
When working with `ent` CLI in a project, you want to make sure the version being
|
||||
used by the CLI is **identical** to the `ent` version used by your project.
|
||||
|
||||
One of the options for achieving this is asking `go generate` to use the version
|
||||
mentioned in the `go.mod` file when running `ent`. If your project does not use
|
||||
[Go modules](https://github.com/golang/go/wiki/Modules#quick-start), setup one as follows:
|
||||
|
||||
```console
|
||||
go mod init <project>
|
||||
```
|
||||
|
||||
And then, re-run the following command in order to add `ent` to your `go.mod` file:
|
||||
|
||||
```console
|
||||
go get entgo.io/ent/cmd/ent
|
||||
```
|
||||
|
||||
Add a `generate.go` file to your project under `<project>/ent`:
|
||||
|
||||
```go
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entgo.io/ent/cmd/ent generate ./schema
|
||||
```
|
||||
|
||||
Finally, you can run `go generate ./ent` from the root directory of your project
|
||||
in order to run `ent` code generation on your project schemas.
|
||||
|
||||
## Code Generation Options
|
||||
|
||||
For more info about codegen options, run `ent generate -h`:
|
||||
|
||||
```console
|
||||
generate go code for the schema directory
|
||||
|
||||
Usage:
|
||||
ent generate [flags] path
|
||||
|
||||
Examples:
|
||||
ent generate ./ent/schema
|
||||
ent generate github.com/a8m/x
|
||||
|
||||
Flags:
|
||||
--feature strings extend codegen with additional features
|
||||
--header string override codegen header
|
||||
-h, --help help for generate
|
||||
--storage string storage driver to support in codegen (default "sql")
|
||||
--target string target directory for codegen
|
||||
--template strings external templates to execute
|
||||
```
|
||||
|
||||
## Storage Options
|
||||
|
||||
`ent` can generate assets for both SQL and Gremlin dialect. The default dialect is SQL.
|
||||
|
||||
## External Templates
|
||||
|
||||
`ent` accepts external Go templates to execute. If the template name already defined by
|
||||
`ent`, it will override the existing one. Otherwise, it will write the execution output to
|
||||
a file with the same name as the template. The flag format supports `file`, `dir` and `glob`
|
||||
as follows:
|
||||
|
||||
```console
|
||||
go run -mod=mod entgo.io/ent/cmd/ent generate --template <dir-path> --template glob="path/to/*.tmpl" ./ent/schema
|
||||
```
|
||||
|
||||
More information and examples can be found in the [external templates doc](templates.md).
|
||||
|
||||
## Use `entc` as a Package
|
||||
|
||||
Another option for running `ent` code generation is to create a file named `ent/entc.go` with the following content,
|
||||
and then the `ent/generate.go` file to execute it:
|
||||
|
||||
```go title="ent/entc.go"
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
func main() {
|
||||
if err := entc.Generate("./schema", &gen.Config{}); err != nil {
|
||||
log.Fatal("running ent codegen:", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```go title="ent/generate.go"
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entc.go
|
||||
```
|
||||
|
||||
The full example exists in [GitHub](https://github.com/ent/ent/tree/master/examples/entcpkg).
|
||||
|
||||
## Schema Description
|
||||
|
||||
In order to get a description of your graph schema, run:
|
||||
|
||||
```bash
|
||||
go run -mod=mod entgo.io/ent/cmd/ent describe ./ent/schema
|
||||
```
|
||||
|
||||
An example for the output is as follows:
|
||||
|
||||
```console
|
||||
Pet:
|
||||
+-------+---------+--------+----------+----------+---------+---------------+-----------+-----------------------+------------+
|
||||
| Field | Type | Unique | Optional | Nillable | Default | UpdateDefault | Immutable | StructTag | Validators |
|
||||
+-------+---------+--------+----------+----------+---------+---------------+-----------+-----------------------+------------+
|
||||
| id | int | false | false | false | false | false | false | json:"id,omitempty" | 0 |
|
||||
| name | string | false | false | false | false | false | false | json:"name,omitempty" | 0 |
|
||||
+-------+---------+--------+----------+----------+---------+---------------+-----------+-----------------------+------------+
|
||||
+-------+------+---------+---------+----------+--------+----------+
|
||||
| Edge | Type | Inverse | BackRef | Relation | Unique | Optional |
|
||||
+-------+------+---------+---------+----------+--------+----------+
|
||||
| owner | User | true | pets | M2O | true | true |
|
||||
+-------+------+---------+---------+----------+--------+----------+
|
||||
|
||||
User:
|
||||
+-------+---------+--------+----------+----------+---------+---------------+-----------+-----------------------+------------+
|
||||
| Field | Type | Unique | Optional | Nillable | Default | UpdateDefault | Immutable | StructTag | Validators |
|
||||
+-------+---------+--------+----------+----------+---------+---------------+-----------+-----------------------+------------+
|
||||
| id | int | false | false | false | false | false | false | json:"id,omitempty" | 0 |
|
||||
| age | int | false | false | false | false | false | false | json:"age,omitempty" | 0 |
|
||||
| name | string | false | false | false | false | false | false | json:"name,omitempty" | 0 |
|
||||
+-------+---------+--------+----------+----------+---------+---------------+-----------+-----------------------+------------+
|
||||
+------+------+---------+---------+----------+--------+----------+
|
||||
| Edge | Type | Inverse | BackRef | Relation | Unique | Optional |
|
||||
+------+------+---------+---------+----------+--------+----------+
|
||||
| pets | Pet | false | | O2M | false | true |
|
||||
+------+------+---------+---------+----------+--------+----------+
|
||||
```
|
||||
|
||||
## Code Generation Hooks
|
||||
|
||||
The `entc` package provides an option to add a list of hooks (middlewares) to the code-generation phase.
|
||||
This option is ideal for adding custom validators for the schema, or for generating additional assets
|
||||
using the graph schema.
|
||||
|
||||
```go
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"log"
|
||||
"reflect"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
)
|
||||
|
||||
func main() {
|
||||
err := entc.Generate("./schema", &gen.Config{
|
||||
Hooks: []gen.Hook{
|
||||
EnsureStructTag("json"),
|
||||
},
|
||||
})
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
|
||||
// EnsureStructTag ensures all fields in the graph have a specific tag name.
|
||||
func EnsureStructTag(name string) gen.Hook {
|
||||
return func(next gen.Generator) gen.Generator {
|
||||
return gen.GenerateFunc(func(g *gen.Graph) error {
|
||||
for _, node := range g.Nodes {
|
||||
for _, field := range node.Fields {
|
||||
tag := reflect.StructTag(field.StructTag)
|
||||
if _, ok := tag.Lookup(name); !ok {
|
||||
return fmt.Errorf("struct tag %q is missing for field %s.%s", name, node.Name, field.Name)
|
||||
}
|
||||
}
|
||||
}
|
||||
return next.Generate(g)
|
||||
})
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## External Dependencies
|
||||
|
||||
In order to extend the generated client and builders under the `ent` package, and inject them external
|
||||
dependencies as struct fields, use the `entc.Dependency` option in your [`ent/entc.go`](#use-entc-as-a-package)
|
||||
file:
|
||||
|
||||
```go title="ent/entc.go" {3-12}
|
||||
func main() {
|
||||
opts := []entc.Option{
|
||||
entc.Dependency(
|
||||
entc.DependencyType(&http.Client{}),
|
||||
),
|
||||
entc.Dependency(
|
||||
entc.DependencyName("Writer"),
|
||||
entc.DependencyTypeInfo(&field.TypeInfo{
|
||||
Ident: "io.Writer",
|
||||
PkgPath: "io",
|
||||
}),
|
||||
),
|
||||
}
|
||||
if err := entc.Generate("./schema", &gen.Config{}, opts...); err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Then, use it in your application:
|
||||
|
||||
```go title="example_test.go" {5-6,15-16}
|
||||
func Example_Deps() {
|
||||
client, err := ent.Open(
|
||||
"sqlite3",
|
||||
"file:ent?mode=memory&cache=shared&_fk=1",
|
||||
ent.Writer(os.Stdout),
|
||||
ent.HTTPClient(http.DefaultClient),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to sqlite: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
// An example for using the injected dependencies in the generated builders.
|
||||
client.User.Use(func(next ent.Mutator) ent.Mutator {
|
||||
return hook.UserFunc(func(ctx context.Context, m *ent.UserMutation) (ent.Value, error) {
|
||||
_ = m.HTTPClient
|
||||
_ = m.Writer
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
})
|
||||
// ...
|
||||
}
|
||||
```
|
||||
|
||||
The full example exists in [GitHub](https://github.com/ent/ent/tree/master/examples/entcpkg).
|
||||
|
||||
## Feature Flags
|
||||
|
||||
The `entc` package provides a collection of code-generation features that be added or removed using flags.
|
||||
|
||||
For more information, please see the [features-flags page](features.md).
|
||||
17
doc/md/community.md
Normal file
17
doc/md/community.md
Normal file
@@ -0,0 +1,17 @@
|
||||
---
|
||||
id: community
|
||||
title: Join our Community
|
||||
---
|
||||
|
||||
Ent maintainers, contributors and users hang out in our Discord server and the #ent channel in the Gophers Slack workspace.
|
||||
|
||||
### Discord
|
||||
|
||||
To Join our Discord server, click [here](https://discord.gg/qZmPgTE6RX).
|
||||
|
||||
### Slack
|
||||
|
||||
To join the discussion in slack:
|
||||
|
||||
1. Sign up to the Gophers Slack workspace via the [invite link](https://invite.slack.golangbridge.org/).
|
||||
2. Join the #ent channel manually or via [this link](https://app.slack.com/client/T029RQSE6/C01FMSQDT53). (it will work only if you are logged in to slack from your browser)
|
||||
48
doc/md/components/_atlas_migrate_apply.mdx
Normal file
48
doc/md/components/_atlas_migrate_apply.mdx
Normal file
@@ -0,0 +1,48 @@
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
<Tabs
|
||||
defaultValue="mysql"
|
||||
values={[
|
||||
{label: 'MySQL', value: 'mysql'},
|
||||
{label: 'MariaDB', value: 'maria'},
|
||||
{label: 'PostgreSQL', value: 'postgres'},
|
||||
{label: 'SQLite', value: 'sqlite'},
|
||||
]}>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```shell
|
||||
atlas migrate apply \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--url "mysql://root:pass@localhost:3306/example"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="maria">
|
||||
|
||||
```shell
|
||||
atlas migrate apply \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--url "maria://root:pass@localhost:3306/example"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="postgres">
|
||||
|
||||
```shell
|
||||
atlas migrate apply \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sqlite">
|
||||
|
||||
```shell
|
||||
atlas migrate apply \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--url "sqlite://file.db?_fk=1"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
52
doc/md/components/_atlas_migrate_diff.mdx
Normal file
52
doc/md/components/_atlas_migrate_diff.mdx
Normal file
@@ -0,0 +1,52 @@
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
<Tabs
|
||||
defaultValue="mysql"
|
||||
values={[
|
||||
{label: 'MySQL', value: 'mysql'},
|
||||
{label: 'MariaDB', value: 'maria'},
|
||||
{label: 'PostgreSQL', value: 'postgres'},
|
||||
{label: 'SQLite', value: 'sqlite'},
|
||||
]}>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```shell
|
||||
atlas migrate diff migration_name \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://mysql/8/ent"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="maria">
|
||||
|
||||
```shell
|
||||
atlas migrate diff migration_name \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://mariadb/latest/test"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="postgres">
|
||||
|
||||
```shell
|
||||
atlas migrate diff migration_name \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://postgres/15/test?search_path=public"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sqlite">
|
||||
|
||||
```shell
|
||||
atlas migrate diff migration_name \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "sqlite://file?mode=memory&_fk=1"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
53
doc/md/components/_installation_instructions.mdx
Normal file
53
doc/md/components/_installation_instructions.mdx
Normal file
@@ -0,0 +1,53 @@
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
To install the latest release of Atlas, simply run one of the following commands in your terminal, or check out the
|
||||
[Atlas website](https://atlasgo.io/getting-started#installation):
|
||||
|
||||
<Tabs
|
||||
defaultValue="apple-intel-plain+linux"
|
||||
values={[
|
||||
{label: 'macOS + Linux', value: 'apple-intel-plain+linux'},
|
||||
{label: 'Homebrew', value: 'apple-intel-brew'},
|
||||
{label: 'Docker', value: 'docker'},
|
||||
{label: 'Windows', value: 'windows'},
|
||||
]}>
|
||||
<TabItem value="apple-intel-plain+linux">
|
||||
|
||||
```shell
|
||||
curl -sSf https://atlasgo.sh | sh
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="apple-intel-brew">
|
||||
|
||||
```shell
|
||||
brew install ariga/tap/atlas
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="docker">
|
||||
|
||||
```shell
|
||||
docker pull arigaio/atlas
|
||||
docker run --rm arigaio/atlas --help
|
||||
```
|
||||
|
||||
If the container needs access to the host network or a local directory, use the `--net=host` flag and mount the desired
|
||||
directory:
|
||||
|
||||
```shell
|
||||
docker run --rm --net=host \
|
||||
-v $(pwd)/migrations:/migrations \
|
||||
arigaio/atlas migrate apply
|
||||
--url "mysql://root:pass@:3306/test"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="windows">
|
||||
|
||||
Download the [latest release](https://release.ariga.io/atlas/atlas-windows-amd64-latest.exe) and
|
||||
move the atlas binary to a file location on your system PATH.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
144
doc/md/contributors.md
Normal file
144
doc/md/contributors.md
Normal file
@@ -0,0 +1,144 @@
|
||||
---
|
||||
id: contributors
|
||||
title: Contributors
|
||||
---
|
||||
|
||||
Thanks goes to these wonderful people ([emoji key](https://allcontributors.org/docs/en/emoji-key)):
|
||||
|
||||
<!-- ALL-CONTRIBUTORS-LIST:START - Do not remove or modify this section -->
|
||||
<!-- prettier-ignore-start -->
|
||||
<!-- markdownlint-disable -->
|
||||
<table>
|
||||
<tbody>
|
||||
<tr>
|
||||
<td align="center"><a href="https://github.com/a8m"><img src="https://avatars.githubusercontent.com/u/7413593?v=4?s=100" width="100px;" alt="Ariel Mashraki"/><br /><sub><b>Ariel Mashraki</b></sub></a><br /><a href="#maintenance-a8m" title="Maintenance">🚧</a> <a href="https://github.com/ent/ent/commits?author=a8m" title="Documentation">📖</a> <a href="https://github.com/ent/ent/commits?author=a8m" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/alexsn"><img src="https://avatars.githubusercontent.com/u/987019?v=4?s=100" width="100px;" alt="Alex Snast"/><br /><sub><b>Alex Snast</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=alexsn" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://rotemtam.com/"><img src="https://avatars.githubusercontent.com/u/1522681?v=4?s=100" width="100px;" alt="Rotem Tamir"/><br /><sub><b>Rotem Tamir</b></sub></a><br /><a href="#maintenance-rotemtam" title="Maintenance">🚧</a> <a href="https://github.com/ent/ent/commits?author=rotemtam" title="Documentation">📖</a> <a href="https://github.com/ent/ent/commits?author=rotemtam" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/cliedeman"><img src="https://avatars.githubusercontent.com/u/3578740?v=4?s=100" width="100px;" alt="Ciaran Liedeman"/><br /><sub><b>Ciaran Liedeman</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=cliedeman" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://www.marwan.io/"><img src="https://avatars.githubusercontent.com/u/16294261?v=4?s=100" width="100px;" alt="Marwan Sulaiman"/><br /><sub><b>Marwan Sulaiman</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=marwan-at-work" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://nathaniel.peiffer.com.au/"><img src="https://avatars.githubusercontent.com/u/8946502?v=4?s=100" width="100px;" alt="Nathaniel Peiffer"/><br /><sub><b>Nathaniel Peiffer</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=napei" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/tmc"><img src="https://avatars.githubusercontent.com/u/3977?v=4?s=100" width="100px;" alt="Travis Cline"/><br /><sub><b>Travis Cline</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=tmc" title="Code">💻</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="https://cloudsjhan.github.io/"><img src="https://avatars.githubusercontent.com/u/7600925?v=4?s=100" width="100px;" alt="Jeremy"/><br /><sub><b>Jeremy</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=hantmac" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/aca"><img src="https://avatars.githubusercontent.com/u/50316549?v=4?s=100" width="100px;" alt="aca"/><br /><sub><b>aca</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=aca" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/BrentChesny"><img src="https://avatars.githubusercontent.com/u/1449435?v=4?s=100" width="100px;" alt="BrentChesny"/><br /><sub><b>BrentChesny</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=BrentChesny" title="Code">💻</a> <a href="https://github.com/ent/ent/commits?author=BrentChesny" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/giautm"><img src="https://avatars.githubusercontent.com/u/12751435?v=4?s=100" width="100px;" alt="Giau. Tran Minh"/><br /><sub><b>Giau. Tran Minh</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=giautm" title="Code">💻</a> <a href="https://github.com/ent/ent/pulls?q=is%3Apr+reviewed-by%3Agiautm" title="Reviewed Pull Requests">👀</a></td>
|
||||
<td align="center"><a href="https://htdvisser.dev/"><img src="https://avatars.githubusercontent.com/u/181308?v=4?s=100" width="100px;" alt="Hylke Visser"/><br /><sub><b>Hylke Visser</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=htdvisser" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/kerbelp"><img src="https://avatars.githubusercontent.com/u/3934990?v=4?s=100" width="100px;" alt="Pavel Kerbel"/><br /><sub><b>Pavel Kerbel</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=kerbelp" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/day-dreams"><img src="https://avatars.githubusercontent.com/u/24593904?v=4?s=100" width="100px;" alt="zhangnan"/><br /><sub><b>zhangnan</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=day-dreams" title="Code">💻</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="https://github.com/uta-mori"><img src="https://avatars.githubusercontent.com/u/59682979?v=4?s=100" width="100px;" alt="mori yuta"/><br /><sub><b>mori yuta</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=uta-mori" title="Code">💻</a> <a href="#translation-uta-mori" title="Translation">🌍</a> <a href="https://github.com/ent/ent/pulls?q=is%3Apr+reviewed-by%3Auta-mori" title="Reviewed Pull Requests">👀</a></td>
|
||||
<td align="center"><a href="http://lollyrock.com/"><img src="https://avatars.githubusercontent.com/u/1178413?v=4?s=100" width="100px;" alt="Christoph Hartmann"/><br /><sub><b>Christoph Hartmann</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=chris-rock" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/rubensayshi"><img src="https://avatars.githubusercontent.com/u/649160?v=4?s=100" width="100px;" alt="Ruben de Vries"/><br /><sub><b>Ruben de Vries</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=rubensayshi" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://keybase.io/ernado"><img src="https://avatars.githubusercontent.com/u/866677?v=4?s=100" width="100px;" alt="Aleksandr Razumov"/><br /><sub><b>Aleksandr Razumov</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=ernado" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/apbuteau"><img src="https://avatars.githubusercontent.com/u/6796073?v=4?s=100" width="100px;" alt="apbuteau"/><br /><sub><b>apbuteau</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=apbuteau" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/ichord"><img src="https://avatars.githubusercontent.com/u/1324791?v=4?s=100" width="100px;" alt="Harold.Luo"/><br /><sub><b>Harold.Luo</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=ichord" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/idoshveki"><img src="https://avatars.githubusercontent.com/u/11615669?v=4?s=100" width="100px;" alt="ido shveki"/><br /><sub><b>ido shveki</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=idoshveki" title="Code">💻</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="https://github.com/masseelch"><img src="https://avatars.githubusercontent.com/u/12862103?v=4?s=100" width="100px;" alt="MasseElch"/><br /><sub><b>MasseElch</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=masseelch" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/kidlj"><img src="https://avatars.githubusercontent.com/u/300616?v=4?s=100" width="100px;" alt="Jian Li"/><br /><sub><b>Jian Li</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=kidlj" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://noah.je/"><img src="https://avatars.githubusercontent.com/u/5778728?v=4?s=100" width="100px;" alt="Noah-Jerome Lotzer"/><br /><sub><b>Noah-Jerome Lotzer</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=nolotz" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/danf0rth"><img src="https://avatars.githubusercontent.com/u/14220891?v=4?s=100" width="100px;" alt="danforth"/><br /><sub><b>danforth</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=danf0rth" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/maxiloEmmmm"><img src="https://avatars.githubusercontent.com/u/16779121?v=4?s=100" width="100px;" alt="maxilozoz"/><br /><sub><b>maxilozoz</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=maxiloEmmmm" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://gist.github.com/zzwx"><img src="https://avatars.githubusercontent.com/u/8169082?v=4?s=100" width="100px;" alt="zzwx"/><br /><sub><b>zzwx</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=zzwx" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/ix64"><img src="https://avatars.githubusercontent.com/u/13902388?v=4?s=100" width="100px;" alt="MengYX"/><br /><sub><b>MengYX</b></sub></a><br /><a href="#translation-ix64" title="Translation">🌍</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="https://mattn.kaoriya.net/"><img src="https://avatars.githubusercontent.com/u/10111?v=4?s=100" width="100px;" alt="mattn"/><br /><sub><b>mattn</b></sub></a><br /><a href="#translation-mattn" title="Translation">🌍</a></td>
|
||||
<td align="center"><a href="https://github.com/Bladrak"><img src="https://avatars.githubusercontent.com/u/1321977?v=4?s=100" width="100px;" alt="Hugo Briand"/><br /><sub><b>Hugo Briand</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=Bladrak" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://danielenman.com/"><img src="https://avatars.githubusercontent.com/u/432487?v=4?s=100" width="100px;" alt="Dan Enman"/><br /><sub><b>Dan Enman</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=enmand" title="Code">💻</a></td>
|
||||
<td align="center"><a href="http://www.l2junity.org/"><img src="https://avatars.githubusercontent.com/u/2185291?v=4?s=100" width="100px;" alt="Rumen Nikiforov"/><br /><sub><b>Rumen Nikiforov</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=UnAfraid" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://wener.me"><img src="https://avatars.githubusercontent.com/u/1777211?v=4?s=100" width="100px;" alt="陈杨文"/><br /><sub><b>陈杨文</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=wenerme" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://djwong.net"><img src="https://avatars.githubusercontent.com/u/1635441?v=4?s=100" width="100px;" alt="Qiaosen (Joeson) Huang"/><br /><sub><b>Qiaosen (Joeson) Huang</b></sub></a><br /><a href="https://github.com/ent/ent/issues?q=author%3Ajoesonw" title="Bug reports">🐛</a></td>
|
||||
<td align="center"><a href="https://github.com/davebehr1"><img src="https://avatars.githubusercontent.com/u/16716239?v=4?s=100" width="100px;" alt="AlonDavidBehr"/><br /><sub><b>AlonDavidBehr</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=davebehr1" title="Code">💻</a> <a href="https://github.com/ent/ent/pulls?q=is%3Apr+reviewed-by%3Adavebehr1" title="Reviewed Pull Requests">👀</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="http://duglaser.dev"><img src="https://avatars.githubusercontent.com/u/50506482?v=4?s=100" width="100px;" alt="DuGlaser"/><br /><sub><b>DuGlaser</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=DuGlaser" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/shanna"><img src="https://avatars.githubusercontent.com/u/28489?v=4?s=100" width="100px;" alt="Shane Hanna"/><br /><sub><b>Shane Hanna</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=shanna" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://www.linkedin.com/in/mahmud2011"><img src="https://avatars.githubusercontent.com/u/5278142?v=4?s=100" width="100px;" alt="Mahmudul Haque"/><br /><sub><b>Mahmudul Haque</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=mahmud2011" title="Code">💻</a></td>
|
||||
<td align="center"><a href="http://blog.scaleprocess.net"><img src="https://avatars.githubusercontent.com/u/862607?v=4?s=100" width="100px;" alt="Benjamin Bourgeais"/><br /><sub><b>Benjamin Bourgeais</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=sywesk" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://about.8ay.ac/"><img src="https://avatars.githubusercontent.com/u/29266382?v=4?s=100" width="100px;" alt="8ayac(Yoshinori Hayashi)"/><br /><sub><b>8ayac(Yoshinori Hayashi)</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=8ayac" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/y-yagi"><img src="https://avatars.githubusercontent.com/u/987638?v=4?s=100" width="100px;" alt="y-yagi"/><br /><sub><b>y-yagi</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=y-yagi" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/Sacro"><img src="https://avatars.githubusercontent.com/u/2659869?v=4?s=100" width="100px;" alt="Ben Woodward"/><br /><sub><b>Ben Woodward</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=Sacro" title="Code">💻</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="https://github.com/wzyjerry"><img src="https://avatars.githubusercontent.com/u/11435169?v=4?s=100" width="100px;" alt="WzyJerry"/><br /><sub><b>WzyJerry</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=wzyjerry" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/tarrencev"><img src="https://avatars.githubusercontent.com/u/4740651?v=4?s=100" width="100px;" alt="Tarrence van As"/><br /><sub><b>Tarrence van As</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=tarrencev" title="Documentation">📖</a> <a href="https://github.com/ent/ent/commits?author=tarrencev" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://mo7ka.com"><img src="https://avatars.githubusercontent.com/u/32859963?v=4?s=100" width="100px;" alt="Yuya Sumie"/><br /><sub><b>Yuya Sumie</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=MONAKA0721" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="http://jasminek.net"><img src="https://avatars.githubusercontent.com/u/7853732?v=4?s=100" width="100px;" alt="Michal Mazurek"/><br /><sub><b>Michal Mazurek</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=akfaew" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/nmemoto"><img src="https://avatars.githubusercontent.com/u/1522332?v=4?s=100" width="100px;" alt="Takafumi Umemoto"/><br /><sub><b>Takafumi Umemoto</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=nmemoto" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="http://www.linkedin.com/in/khadija-sidhpuri-87709316a"><img src="https://avatars.githubusercontent.com/u/59063821?v=4?s=100" width="100px;" alt="Khadija Sidhpuri"/><br /><sub><b>Khadija Sidhpuri</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=squarebat" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/neel229"><img src="https://avatars.githubusercontent.com/u/53475167?v=4?s=100" width="100px;" alt="Neel Modi"/><br /><sub><b>Neel Modi</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=neel229" title="Code">💻</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="https://ie.linkedin.com/in/boris-shomodjvarac-51970879"><img src="https://avatars.githubusercontent.com/u/304768?v=4?s=100" width="100px;" alt="Boris Shomodjvarac"/><br /><sub><b>Boris Shomodjvarac</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=shomodj" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/sadmansakib"><img src="https://avatars.githubusercontent.com/u/17023844?v=4?s=100" width="100px;" alt="Sadman Sakib"/><br /><sub><b>Sadman Sakib</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=sadmansakib" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/dakimura"><img src="https://avatars.githubusercontent.com/u/34202807?v=4?s=100" width="100px;" alt="dakimura"/><br /><sub><b>dakimura</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=dakimura" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/RiskyFeryansyahP"><img src="https://avatars.githubusercontent.com/u/36788585?v=4?s=100" width="100px;" alt="Risky Feryansyah"/><br /><sub><b>Risky Feryansyah</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=RiskyFeryansyahP" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/seiichi1101"><img src="https://avatars.githubusercontent.com/u/20941952?v=4?s=100" width="100px;" alt="seiichi "/><br /><sub><b>seiichi </b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=seiichi1101" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://orijtech.com/"><img src="https://avatars.githubusercontent.com/u/4898263?v=4?s=100" width="100px;" alt="Emmanuel T Odeke"/><br /><sub><b>Emmanuel T Odeke</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=odeke-em" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://isoppp.com"><img src="https://avatars.githubusercontent.com/u/16318727?v=4?s=100" width="100px;" alt="Hiroki Isogai"/><br /><sub><b>Hiroki Isogai</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=isoppp" title="Documentation">📖</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="https://github.com/tsingsun"><img src="https://avatars.githubusercontent.com/u/5848549?v=4?s=100" width="100px;" alt="李清山"/><br /><sub><b>李清山</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=tsingsun" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/s-takehana"><img src="https://avatars.githubusercontent.com/u/3423547?v=4?s=100" width="100px;" alt="s-takehana"/><br /><sub><b>s-takehana</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=s-takehana" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/EndlessIdea"><img src="https://avatars.githubusercontent.com/u/1527796?v=4?s=100" width="100px;" alt="Kuiba"/><br /><sub><b>Kuiba</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=EndlessIdea" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/storyicon"><img src="https://avatars.githubusercontent.com/u/29772821?v=4?s=100" width="100px;" alt="storyicon"/><br /><sub><b>storyicon</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=storyicon" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/evanlurvey"><img src="https://avatars.githubusercontent.com/u/54965655?v=4?s=100" width="100px;" alt="Evan Lurvey"/><br /><sub><b>Evan Lurvey</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=evanlurvey" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/attackordie"><img src="https://avatars.githubusercontent.com/u/20145334?v=4?s=100" width="100px;" alt="Brian"/><br /><sub><b>Brian</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=attackordie" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="http://www.thinkontrol.com"><img src="https://avatars.githubusercontent.com/u/11331554?v=4?s=100" width="100px;" alt="Shen Yang"/><br /><sub><b>Shen Yang</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=ThinkontrolSY" title="Code">💻</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="https://twitter.com/sivchari"><img src="https://avatars.githubusercontent.com/u/55221074?v=4?s=100" width="100px;" alt="sivchari"/><br /><sub><b>sivchari</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=sivchari" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://blog.mookjp.io"><img src="https://avatars.githubusercontent.com/u/1519309?v=4?s=100" width="100px;" alt="mook"/><br /><sub><b>mook</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=mookjp" title="Code">💻</a></td>
|
||||
<td align="center"><a href="http://www.entiros.se"><img src="https://avatars.githubusercontent.com/u/1607668?v=4?s=100" width="100px;" alt="heliumbrain"/><br /><sub><b>heliumbrain</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=heliumbrain" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/JeremyV2014"><img src="https://avatars.githubusercontent.com/u/9276415?v=4?s=100" width="100px;" alt="Jeremy Maxey-Vesperman"/><br /><sub><b>Jeremy Maxey-Vesperman</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=JeremyV2014" title="Code">💻</a> <a href="https://github.com/ent/ent/commits?author=JeremyV2014" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/tankbusta"><img src="https://avatars.githubusercontent.com/u/592749?v=4?s=100" width="100px;" alt="Christopher Schmitt"/><br /><sub><b>Christopher Schmitt</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=tankbusta" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/grevych"><img src="https://avatars.githubusercontent.com/u/3792003?v=4?s=100" width="100px;" alt="Gerardo Reyes"/><br /><sub><b>Gerardo Reyes</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=grevych" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/naormatania"><img src="https://avatars.githubusercontent.com/u/6978437?v=4?s=100" width="100px;" alt="Naor Matania"/><br /><sub><b>Naor Matania</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=naormatania" title="Code">💻</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="https://github.com/idc77"><img src="https://avatars.githubusercontent.com/u/87644834?v=4?s=100" width="100px;" alt="idc77"/><br /><sub><b>idc77</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=idc77" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="http://ethanhur.me"><img src="https://avatars.githubusercontent.com/u/8033896?v=4?s=100" width="100px;" alt="Sungyun Hur"/><br /><sub><b>Sungyun Hur</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=HurSungYun" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/peanut-cc"><img src="https://avatars.githubusercontent.com/u/55480838?v=4?s=100" width="100px;" alt="peanut-pg"/><br /><sub><b>peanut-pg</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=peanut-cc" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/m3hm3t"><img src="https://avatars.githubusercontent.com/u/22320354?v=4?s=100" width="100px;" alt="Mehmet Yılmaz"/><br /><sub><b>Mehmet Yılmaz</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=m3hm3t" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/Laconty"><img src="https://avatars.githubusercontent.com/u/17760166?v=4?s=100" width="100px;" alt="Roman Maklakov"/><br /><sub><b>Roman Maklakov</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=Laconty" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/genevieve"><img src="https://avatars.githubusercontent.com/u/12158641?v=4?s=100" width="100px;" alt="Genevieve"/><br /><sub><b>Genevieve</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=genevieve" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/cjraa"><img src="https://avatars.githubusercontent.com/u/62199269?v=4?s=100" width="100px;" alt="Clarence"/><br /><sub><b>Clarence</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=cjraa" title="Code">💻</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="https://www.linkedin.com/in/iamnande/"><img src="https://avatars.githubusercontent.com/u/7806510?v=4?s=100" width="100px;" alt="Nicholas Anderson"/><br /><sub><b>Nicholas Anderson</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=iamnande" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/hezhizhen"><img src="https://avatars.githubusercontent.com/u/7611700?v=4?s=100" width="100px;" alt="Zhizhen He"/><br /><sub><b>Zhizhen He</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=hezhizhen" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://pedro.dev.br"><img src="https://avatars.githubusercontent.com/u/1251151?v=4?s=100" width="100px;" alt="Pedro Henrique"/><br /><sub><b>Pedro Henrique</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=crossworth" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://2jp.de"><img src="https://avatars.githubusercontent.com/u/7414374?v=4?s=100" width="100px;" alt="MrParano1d"/><br /><sub><b>MrParano1d</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=MrParano1d" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/tprebs"><img src="https://avatars.githubusercontent.com/u/6523587?v=4?s=100" width="100px;" alt="Thomas Prebble"/><br /><sub><b>Thomas Prebble</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=tprebs" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://huytq.com"><img src="https://avatars.githubusercontent.com/u/5723282?v=4?s=100" width="100px;" alt="Huy TQ"/><br /><sub><b>Huy TQ</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=imhuytq" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/maorlipchuk"><img src="https://avatars.githubusercontent.com/u/7034637?v=4?s=100" width="100px;" alt="maorlipchuk"/><br /><sub><b>maorlipchuk</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=maorlipchuk" title="Code">💻</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="https://mobcov.hatenadiary.org/"><img src="https://avatars.githubusercontent.com/u/121048?v=4?s=100" width="100px;" alt="Motonori Iwata"/><br /><sub><b>Motonori Iwata</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=iwata" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="https://github.com/CharlesGe129"><img src="https://avatars.githubusercontent.com/u/20162173?v=4?s=100" width="100px;" alt="Charles Ge"/><br /><sub><b>Charles Ge</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=CharlesGe129" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/thmeitz"><img src="https://avatars.githubusercontent.com/u/92851940?v=4?s=100" width="100px;" alt="Thomas Meitz"/><br /><sub><b>Thomas Meitz</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=thmeitz" title="Code">💻</a> <a href="https://github.com/ent/ent/commits?author=thmeitz" title="Documentation">📖</a></td>
|
||||
<td align="center"><a href="http://justinjohnson.org"><img src="https://avatars.githubusercontent.com/u/181567?v=4?s=100" width="100px;" alt="Justin Johnson"/><br /><sub><b>Justin Johnson</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=booleangate" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/hax10"><img src="https://avatars.githubusercontent.com/u/85743468?v=4?s=100" width="100px;" alt="hax10"/><br /><sub><b>hax10</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=hax10" title="Code">💻</a></td>
|
||||
<td align="center"><a href="https://github.com/water-a"><img src="https://avatars.githubusercontent.com/u/38114545?v=4?s=100" width="100px;" alt="water-a"/><br /><sub><b>water-a</b></sub></a><br /><a href="https://github.com/ent/ent/issues?q=author%3Awater-a" title="Bug reports">🐛</a></td>
|
||||
<td align="center"><a href="https://github.com/jhwz"><img src="https://avatars.githubusercontent.com/u/52683873?v=4?s=100" width="100px;" alt="jhwz"/><br /><sub><b>jhwz</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=jhwz" title="Documentation">📖</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><a href="https://kortschak.io/"><img src="https://avatars.githubusercontent.com/u/275221?v=4?s=100" width="100px;" alt="Dan Kortschak"/><br /><sub><b>Dan Kortschak</b></sub></a><br /><a href="https://github.com/ent/ent/commits?author=kortschak" title="Documentation">📖</a></td>
|
||||
</tr>
|
||||
</tbody>
|
||||
<tfoot>
|
||||
|
||||
</tfoot>
|
||||
</table>
|
||||
|
||||
<!-- markdownlint-restore -->
|
||||
<!-- prettier-ignore-end -->
|
||||
|
||||
<!-- ALL-CONTRIBUTORS-LIST:END -->
|
||||
|
||||
This project follows the [all-contributors](https://github.com/all-contributors/all-contributors) specification. Contributions of any kind welcome!
|
||||
637
doc/md/crud.mdx
Normal file
637
doc/md/crud.mdx
Normal file
@@ -0,0 +1,637 @@
|
||||
---
|
||||
id: crud
|
||||
title: CRUD API
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
As mentioned in the [introduction](code-gen.md) section, running `ent` on the schemas,
|
||||
will generate the following assets:
|
||||
|
||||
- `Client` and `Tx` objects used for interacting with the graph.
|
||||
- CRUD builders for each schema type.
|
||||
- Entity object (Go struct) for each of the schema type.
|
||||
- Package containing constants and predicates used for interacting with the builders.
|
||||
- A `migrate` package for SQL dialects. See [Migration](migrate.md) for more info.
|
||||
|
||||
## Create A New Client
|
||||
|
||||
<Tabs
|
||||
defaultValue="sqlite"
|
||||
values={[
|
||||
{label: 'SQLite', value: 'sqlite'},
|
||||
{label: 'PostgreSQL', value: 'postgres'},
|
||||
{label: 'MySQL', value: 'mysql'},
|
||||
{label: 'Gremlin (AWS Neptune)', value: 'gremlin'},
|
||||
]}>
|
||||
<TabItem value="sqlite">
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"entdemo/ent"
|
||||
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to sqlite: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
// Run the auto migration tool.
|
||||
if err := client.Schema.Create(context.Background()); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="postgres">
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"entdemo/ent"
|
||||
|
||||
_ "github.com/lib/pq"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("postgres","host=<host> port=<port> user=<user> dbname=<database> password=<pass>")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to postgres: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
// Run the auto migration tool.
|
||||
if err := client.Schema.Create(context.Background()); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"entdemo/ent"
|
||||
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "<user>:<pass>@tcp(<host>:<port>)/<database>?parseTime=True")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
// Run the auto migration tool.
|
||||
if err := client.Schema.Create(context.Background()); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="gremlin">
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entdemo/ent"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("gremlin", "http://localhost:8182")
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Create An Entity
|
||||
|
||||
**Save** a user.
|
||||
|
||||
```go
|
||||
a8m, err := client.User. // UserClient.
|
||||
Create(). // User create builder.
|
||||
SetName("a8m"). // Set field value.
|
||||
SetNillableAge(age). // Avoid nil checks.
|
||||
AddGroups(g1, g2). // Add many edges.
|
||||
SetSpouse(nati). // Set unique edge.
|
||||
Save(ctx) // Create and return.
|
||||
```
|
||||
|
||||
**SaveX** a pet; Unlike **Save**, **SaveX** panics if an error occurs.
|
||||
|
||||
```go
|
||||
pedro := client.Pet. // PetClient.
|
||||
Create(). // Pet create builder.
|
||||
SetName("pedro"). // Set field value.
|
||||
SetOwner(a8m). // Set owner (unique edge).
|
||||
SaveX(ctx) // Create and return.
|
||||
```
|
||||
|
||||
## Create Many
|
||||
|
||||
**Save** a bulk of pets.
|
||||
|
||||
```go {1,8}
|
||||
pets, err := client.Pet.CreateBulk(
|
||||
client.Pet.Create().SetName("pedro").SetOwner(a8m),
|
||||
client.Pet.Create().SetName("xabi").SetOwner(a8m),
|
||||
client.Pet.Create().SetName("layla").SetOwner(a8m),
|
||||
).Save(ctx)
|
||||
|
||||
names := []string{"pedro", "xabi", "layla"}
|
||||
pets, err := client.Pet.MapCreateBulk(names, func(c *ent.PetCreate, i int) {
|
||||
c.SetName(names[i]).SetOwner(a8m)
|
||||
}).Save(ctx)
|
||||
```
|
||||
|
||||
## Update One
|
||||
|
||||
Update an entity that was returned from the database.
|
||||
|
||||
```go
|
||||
a8m, err = a8m.Update(). // User update builder.
|
||||
RemoveGroup(g2). // Remove a specific edge.
|
||||
ClearCard(). // Clear a unique edge.
|
||||
SetAge(30). // Set a field value.
|
||||
AddRank(10). // Increment a field value.
|
||||
AppendInts([]int{1}). // Append values to a JSON array.
|
||||
Save(ctx) // Save and return.
|
||||
```
|
||||
|
||||
|
||||
## Update By ID
|
||||
|
||||
```go
|
||||
pedro, err := client.Pet. // PetClient.
|
||||
UpdateOneID(id). // Pet update builder.
|
||||
SetName("pedro"). // Set field name.
|
||||
SetOwnerID(owner). // Set unique edge, using id.
|
||||
Save(ctx) // Save and return.
|
||||
```
|
||||
|
||||
|
||||
#### Update One With Condition
|
||||
|
||||
In some projects, the "update many" operation is not allowed and is blocked using hooks. However, there is still a need
|
||||
to update a single entity by its ID while ensuring it meets a specific condition. In this case, you can use the `Where`
|
||||
option as follows:
|
||||
|
||||
<Tabs>
|
||||
<TabItem label="By ID" value="by-id" default>
|
||||
|
||||
```go
|
||||
err := client.Todo.
|
||||
UpdateOneID(id).
|
||||
SetStatus(todo.StatusDone).
|
||||
AddVersion(1).
|
||||
Where(
|
||||
todo.Version(currentVersion),
|
||||
).
|
||||
Exec(ctx)
|
||||
switch {
|
||||
// If the entity does not meet a specific condition,
|
||||
// the operation will return an "ent.NotFoundError".
|
||||
case ent.IsNotFound(err):
|
||||
fmt.Println("todo item was not found")
|
||||
// Any other error.
|
||||
case err != nil:
|
||||
fmt.Println("update error:", err)
|
||||
}
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem label="By Entity" value="by-entity" default>
|
||||
|
||||
```go
|
||||
err := client.Todo.
|
||||
UpdateOne(node).
|
||||
SetStatus(todo.StatusDone).
|
||||
AddVersion(1).
|
||||
Where(
|
||||
todo.Version(currentVersion),
|
||||
).
|
||||
Exec(ctx)
|
||||
switch {
|
||||
// If the entity does not meet a specific condition,
|
||||
// the operation will return an "ent.NotFoundError".
|
||||
case ent.IsNotFound(err):
|
||||
fmt.Println("todo item was not found")
|
||||
// Any other error.
|
||||
case err != nil:
|
||||
fmt.Println("update error:", err)
|
||||
}
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem label="Update Directly" value="update-directly" default>
|
||||
|
||||
```go
|
||||
firstTodo, err = firstTodo.
|
||||
Update().
|
||||
SetStatus(todo.StatusDone).
|
||||
AddVersion(1).
|
||||
Where(
|
||||
// Ensure the current version matches the one in the database.
|
||||
todo.Version(firstTodo.Version),
|
||||
).
|
||||
Save(ctx)
|
||||
switch {
|
||||
// If the entity does not meet a specific condition,
|
||||
// the operation will return an "ent.NotFoundError".
|
||||
case ent.IsNotFound(err):
|
||||
fmt.Println("todo item was not found")
|
||||
// Any other error.
|
||||
case err != nil:
|
||||
fmt.Println("update error:", err)
|
||||
}
|
||||
```
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Update Many
|
||||
|
||||
Filter using predicates.
|
||||
|
||||
```go
|
||||
n, err := client.User. // UserClient.
|
||||
Update(). // User update builder.
|
||||
Where( //
|
||||
user.Or( // (age >= 30 OR name = "bar")
|
||||
user.AgeGT(30), //
|
||||
user.Name("bar"), // AND
|
||||
), //
|
||||
user.HasFollowers(), // UserHasFollowers()
|
||||
). //
|
||||
SetName("foo"). // Set field name.
|
||||
Save(ctx) // exec and return.
|
||||
```
|
||||
|
||||
Query edge-predicates.
|
||||
|
||||
```go
|
||||
n, err := client.User. // UserClient.
|
||||
Update(). // User update builder.
|
||||
Where( //
|
||||
user.HasFriendsWith( // UserHasFriendsWith (
|
||||
user.Or( // age = 20
|
||||
user.Age(20), // OR
|
||||
user.Age(30), // age = 30
|
||||
) // )
|
||||
), //
|
||||
). //
|
||||
SetName("a8m"). // Set field name.
|
||||
Save(ctx) // exec and return.
|
||||
```
|
||||
|
||||
## Upsert One
|
||||
|
||||
Ent supports [upsert](https://en.wikipedia.org/wiki/Merge_(SQL)) records using the [`sql/upsert`](features.md#upsert)
|
||||
feature-flag.
|
||||
|
||||
```go
|
||||
err := client.User.
|
||||
Create().
|
||||
SetAge(30).
|
||||
SetName("Ariel").
|
||||
OnConflict().
|
||||
// Use the new values that were set on create.
|
||||
UpdateNewValues().
|
||||
Exec(ctx)
|
||||
|
||||
id, err := client.User.
|
||||
Create().
|
||||
SetAge(30).
|
||||
SetName("Ariel").
|
||||
OnConflict().
|
||||
// Use the "age" that was set on create.
|
||||
UpdateAge().
|
||||
// Set a different "name" in case of conflict.
|
||||
SetName("Mashraki").
|
||||
ID(ctx)
|
||||
|
||||
// Customize the UPDATE clause.
|
||||
err := client.User.
|
||||
Create().
|
||||
SetAge(30).
|
||||
SetName("Ariel").
|
||||
OnConflict().
|
||||
UpdateNewValues().
|
||||
// Override some of the fields with a custom update.
|
||||
Update(func(u *ent.UserUpsert) {
|
||||
u.SetAddress("localhost")
|
||||
u.AddCount(1)
|
||||
u.ClearPhone()
|
||||
}).
|
||||
Exec(ctx)
|
||||
```
|
||||
|
||||
In PostgreSQL, the [conflict target](https://www.postgresql.org/docs/current/sql-insert.html#SQL-ON-CONFLICT) is required:
|
||||
|
||||
```go
|
||||
// Setting the column names using the fluent API.
|
||||
err := client.User.
|
||||
Create().
|
||||
SetName("Ariel").
|
||||
OnConflictColumns(user.FieldName).
|
||||
UpdateNewValues().
|
||||
Exec(ctx)
|
||||
|
||||
// Setting the column names using the SQL API.
|
||||
err := client.User.
|
||||
Create().
|
||||
SetName("Ariel").
|
||||
OnConflict(
|
||||
sql.ConflictColumns(user.FieldName),
|
||||
).
|
||||
UpdateNewValues().
|
||||
Exec(ctx)
|
||||
|
||||
// Setting the constraint name using the SQL API.
|
||||
err := client.User.
|
||||
Create().
|
||||
SetName("Ariel").
|
||||
OnConflict(
|
||||
sql.ConflictConstraint(constraint),
|
||||
).
|
||||
UpdateNewValues().
|
||||
Exec(ctx)
|
||||
```
|
||||
|
||||
In order to customize the executed statement, use the SQL API:
|
||||
|
||||
```go
|
||||
id, err := client.User.
|
||||
Create().
|
||||
OnConflict(
|
||||
sql.ConflictColumns(...),
|
||||
sql.ConflictWhere(...),
|
||||
sql.UpdateWhere(...),
|
||||
).
|
||||
Update(func(u *ent.UserUpsert) {
|
||||
u.SetAge(30)
|
||||
u.UpdateName()
|
||||
}).
|
||||
ID(ctx)
|
||||
|
||||
// INSERT INTO "users" (...) VALUES (...) ON CONFLICT WHERE ... DO UPDATE SET ... WHERE ...
|
||||
```
|
||||
|
||||
:::info
|
||||
Since the upsert API is implemented using the `ON CONFLICT` clause (and `ON DUPLICATE KEY` in MySQL),
|
||||
Ent executes only one statement to the database, and therefore, only create [hooks](hooks.md) are applied
|
||||
for such operations.
|
||||
:::
|
||||
|
||||
## Upsert Many
|
||||
|
||||
```go
|
||||
err := client.User. // UserClient
|
||||
CreateBulk(builders...). // User bulk create.
|
||||
OnConflict(). // User bulk upsert.
|
||||
UpdateNewValues(). // Use the values that were set on create in case of conflict.
|
||||
Exec(ctx) // Execute the statement.
|
||||
```
|
||||
|
||||
## Query The Graph
|
||||
|
||||
Get all users with followers.
|
||||
```go
|
||||
users, err := client.User. // UserClient.
|
||||
Query(). // User query builder.
|
||||
Where(user.HasFollowers()). // filter only users with followers.
|
||||
All(ctx) // query and return.
|
||||
```
|
||||
|
||||
Get all followers of a specific user; Start the traversal from a node in the graph.
|
||||
```go
|
||||
users, err := a8m.
|
||||
QueryFollowers().
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
Get all pets of the followers of a user.
|
||||
```go
|
||||
users, err := a8m.
|
||||
QueryFollowers().
|
||||
QueryPets().
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
Count the number of posts without comments.
|
||||
```go
|
||||
n, err := client.Post.
|
||||
Query().
|
||||
Where(
|
||||
post.Not(
|
||||
post.HasComments(),
|
||||
)
|
||||
).
|
||||
Count(ctx)
|
||||
```
|
||||
|
||||
More advance traversals can be found in the [next section](traversals.md).
|
||||
|
||||
## Field Selection
|
||||
|
||||
Get all pet names.
|
||||
|
||||
```go
|
||||
names, err := client.Pet.
|
||||
Query().
|
||||
Select(pet.FieldName).
|
||||
Strings(ctx)
|
||||
```
|
||||
|
||||
Get all unique pet names.
|
||||
|
||||
```go
|
||||
names, err := client.Pet.
|
||||
Query().
|
||||
Unique(true).
|
||||
Select(pet.FieldName).
|
||||
Strings(ctx)
|
||||
```
|
||||
|
||||
Count the number of unique pet names.
|
||||
|
||||
```go
|
||||
n, err := client.Pet.
|
||||
Query().
|
||||
Unique(true).
|
||||
Select(pet.FieldName).
|
||||
Count(ctx)
|
||||
```
|
||||
|
||||
Select partial objects and partial associations.
|
||||
Get all pets and their owners, but select and fill only the `ID` and `Name` fields.
|
||||
|
||||
```go
|
||||
pets, err := client.Pet.
|
||||
Query().
|
||||
Select(pet.FieldName).
|
||||
WithOwner(func (q *ent.UserQuery) {
|
||||
q.Select(user.FieldName)
|
||||
}).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
Scan all pet names and ages to custom struct.
|
||||
|
||||
```go
|
||||
var v []struct {
|
||||
Age int `json:"age"`
|
||||
Name string `json:"name"`
|
||||
}
|
||||
err := client.Pet.
|
||||
Query().
|
||||
Select(pet.FieldAge, pet.FieldName).
|
||||
Scan(ctx, &v)
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
```
|
||||
|
||||
Update an entity and return a partial of it.
|
||||
|
||||
```go
|
||||
pedro, err := client.Pet.
|
||||
UpdateOneID(id).
|
||||
SetAge(9).
|
||||
SetName("pedro").
|
||||
// Select allows selecting one or more fields (columns) of the returned entity.
|
||||
// The default is selecting all fields defined in the entity schema.
|
||||
Select(pet.FieldName).
|
||||
Save(ctx)
|
||||
```
|
||||
|
||||
## Delete One
|
||||
|
||||
Delete an entity:
|
||||
|
||||
```go
|
||||
err := client.User.
|
||||
DeleteOne(a8m).
|
||||
Exec(ctx)
|
||||
```
|
||||
|
||||
Delete by ID:
|
||||
|
||||
```go
|
||||
err := client.User.
|
||||
DeleteOneID(id).
|
||||
Exec(ctx)
|
||||
```
|
||||
|
||||
#### Delete One With Condition
|
||||
|
||||
In some projects, the "delete many" operation is not allowed and is blocked using hooks. However, there is still a need
|
||||
to delete a single entity by its ID while ensuring it meets a specific condition. In this case, you can use the `Where`
|
||||
option as follows:
|
||||
|
||||
```go
|
||||
err := client.Todo.
|
||||
DeleteOneID(id).
|
||||
Where(
|
||||
// Allow deleting only expired todos.
|
||||
todo.ExpireLT(time.Now()),
|
||||
).
|
||||
Exec(ctx)
|
||||
switch {
|
||||
// If the entity does not meet a specific condition,
|
||||
// the operation will return an "ent.NotFoundError".
|
||||
case ent.IsNotFound(err):
|
||||
fmt.Println("todo item was not found")
|
||||
// Any other error.
|
||||
case err != nil:
|
||||
fmt.Println("deletion error:", err)
|
||||
}
|
||||
```
|
||||
|
||||
|
||||
## Delete Many
|
||||
|
||||
Delete using predicates:
|
||||
|
||||
```go
|
||||
affected, err := client.File.
|
||||
Delete().
|
||||
Where(file.UpdatedAtLT(date)).
|
||||
Exec(ctx)
|
||||
```
|
||||
|
||||
## Mutation
|
||||
|
||||
Each generated node type has its own type of mutation. For example, all [`User` builders](crud.mdx#create-an-entity), share
|
||||
the same generated `UserMutation` object.
|
||||
However, all builder types implement the generic <a target="_blank" href="https://pkg.go.dev/entgo.io/ent?tab=doc#Mutation">`ent.Mutation`</a> interface.
|
||||
|
||||
For example, in order to write a generic code that apply a set of methods on both `ent.UserCreate`
|
||||
and `ent.UserUpdate`, use the `UserMutation` object:
|
||||
|
||||
```go
|
||||
func Do() {
|
||||
creator := client.User.Create()
|
||||
SetAgeName(creator.Mutation())
|
||||
updater := client.User.UpdateOneID(id)
|
||||
SetAgeName(updater.Mutation())
|
||||
}
|
||||
|
||||
// SetAgeName sets the age and the name for any mutation.
|
||||
func SetAgeName(m *ent.UserMutation) {
|
||||
m.SetAge(32)
|
||||
m.SetName("Ariel")
|
||||
}
|
||||
```
|
||||
|
||||
In some cases, you want to apply a set of methods on multiple types.
|
||||
For cases like this, either use the generic `ent.Mutation` interface,
|
||||
or create your own interface.
|
||||
|
||||
```go
|
||||
func Do() {
|
||||
creator1 := client.User.Create()
|
||||
SetName(creator1.Mutation(), "a8m")
|
||||
|
||||
creator2 := client.Pet.Create()
|
||||
SetName(creator2.Mutation(), "pedro")
|
||||
}
|
||||
|
||||
// SetNamer wraps the 2 methods for getting
|
||||
// and setting the "name" field in mutations.
|
||||
type SetNamer interface {
|
||||
SetName(string)
|
||||
Name() (string, bool)
|
||||
}
|
||||
|
||||
func SetName(m SetNamer, name string) {
|
||||
if _, exist := m.Name(); !exist {
|
||||
m.SetName(name)
|
||||
}
|
||||
}
|
||||
```
|
||||
316
doc/md/data-migrations.mdx
Normal file
316
doc/md/data-migrations.mdx
Normal file
@@ -0,0 +1,316 @@
|
||||
---
|
||||
id: data-migrations
|
||||
title: Data Migrations
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
Migrations are usually used for changing the database schema, but in some cases, there is a need to modify the data
|
||||
stored in the database. For example, adding seed data, or back-filling empty columns with custom default values.
|
||||
|
||||
Migrations of this type are called data migrations. In this document, we will discuss how to use Ent to plan data
|
||||
migrations and integrate them into your regular schema migrations workflow.
|
||||
|
||||
### Migration Types
|
||||
|
||||
Ent currently supports two types of migrations, [versioned migration](versioned-migrations.mdx) and [declarative migration](migrate.md)
|
||||
(also known as automatic migration). Data migrations can be executed in both types of migrations.
|
||||
|
||||
## Versioned Migrations
|
||||
|
||||
When using versioned migrations, data migrations should be stored on the same `migrations` directory and executed the
|
||||
same way as regular migrations. It is recommended, however, to store data migrations and schema migrations in separate
|
||||
files so that they can be easily tested.
|
||||
|
||||
The format used for such migrations is SQL, as the file can be safely executed (and stored without changes) even if
|
||||
the Ent schema was modified and the generated code is not compatible with the data migration file anymore.
|
||||
|
||||
There are two ways to create data migrations scripts, manually and generated. By manually editing, users write all the SQL
|
||||
statements and can control exactly what will be executed. Alternatively, users can use Ent to generate the data migrations
|
||||
for them. It is recommended to verify that the generated file was correctly generated, as in some cases it may need to
|
||||
be manually fixed or edited.
|
||||
|
||||
### Manual Creation
|
||||
|
||||
1\. If you don't have Atlas installed, check out its [getting-started](https://atlasgo.io/getting-started/#installation)
|
||||
guide.
|
||||
|
||||
2\. Create a new migration file using [Atlas](https://atlasgo.io/versioned/new):
|
||||
```shell
|
||||
atlas migrate new <migration_name> \
|
||||
--dir "file://my/project/migrations"
|
||||
```
|
||||
|
||||
3\. Edit the migration file and add the custom data migration there. For example:
|
||||
```sql title="ent/migrate/migrations/20221126185750_backfill_data.sql"
|
||||
-- Backfill NULL or null tags with a default value.
|
||||
UPDATE `users` SET `tags` = '["foo","bar"]' WHERE `tags` IS NULL OR JSON_CONTAINS(`tags`, 'null', '$');
|
||||
```
|
||||
|
||||
4\. Update the migration directory [integrity file](https://atlasgo.io/concepts/migration-directory-integrity):
|
||||
```shell
|
||||
atlas migrate hash \
|
||||
--dir "file://my/project/migrations"
|
||||
```
|
||||
|
||||
Check out the [Testing](#testing) section below if you're unsure how to test the data migration file.
|
||||
|
||||
### Generated Scripts
|
||||
|
||||
Currently, Ent provides initial support for generating data migration files. By using this option, users can simplify the
|
||||
process of writing complex SQL statements manually in most cases. Still, it is recommended to verify that the generated
|
||||
file was correctly generated, as in some edge cases it may need to be manually edited.
|
||||
|
||||
1\. Create your [versioned-migration setup](/docs/versioned/intro), in case it
|
||||
is not set.
|
||||
|
||||
2\. Create your first data-migration function. Below, you will find some examples that demonstrate how to write such a
|
||||
function:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="single" label="Single Statement" default>
|
||||
|
||||
```go title="ent/migrate/migratedata/migratedata.go"
|
||||
package migratedata
|
||||
|
||||
// BackfillUnknown back-fills all empty users' names with the default value 'Unknown'.
|
||||
func BackfillUnknown(dir *migrate.LocalDir) error {
|
||||
w := &schema.DirWriter{Dir: dir}
|
||||
client := ent.NewClient(ent.Driver(schema.NewWriteDriver(dialect.MySQL, w)))
|
||||
|
||||
// Change all empty names to 'unknown'.
|
||||
err := client.User.
|
||||
Update().
|
||||
Where(
|
||||
user.NameEQ(""),
|
||||
).
|
||||
SetName("Unknown").
|
||||
Exec(context.Background())
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed generating statement: %w", err)
|
||||
}
|
||||
|
||||
// Write the content to the migration directory.
|
||||
return w.FlushChange(
|
||||
"unknown_names",
|
||||
"Backfill all empty user names with default value 'unknown'.",
|
||||
)
|
||||
}
|
||||
```
|
||||
|
||||
Then, using this function in `ent/migrate/main.go` will generate the following migration file:
|
||||
|
||||
```sql title="migrations/20221126185750_unknown_names.sql"
|
||||
-- Backfill all empty user names with default value 'unknown'.
|
||||
UPDATE `users` SET `name` = 'Unknown' WHERE `users`.`name` = '';
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="multi" label="Multi Statement">
|
||||
|
||||
```go title="ent/migrate/migratedata/migratedata.go"
|
||||
package migratedata
|
||||
|
||||
// BackfillUserTags is used to generate the migration file '20221126185750_backfill_user_tags.sql'.
|
||||
func BackfillUserTags(dir *migrate.LocalDir) error {
|
||||
w := &schema.DirWriter{Dir: dir}
|
||||
client := ent.NewClient(ent.Driver(schema.NewWriteDriver(dialect.MySQL, w)))
|
||||
|
||||
// Add defaults "foo" and "bar" tags for users without any.
|
||||
err := client.User.
|
||||
Update().
|
||||
Where(func(s *sql.Selector) {
|
||||
s.Where(
|
||||
sql.Or(
|
||||
sql.IsNull(user.FieldTags),
|
||||
sqljson.ValueIsNull(user.FieldTags),
|
||||
),
|
||||
)
|
||||
}).
|
||||
SetTags([]string{"foo", "bar"}).
|
||||
Exec(context.Background())
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed generating backfill statement: %w", err)
|
||||
}
|
||||
// Document all changes until now with a custom comment.
|
||||
w.Change("Backfill NULL or null tags with a default value.")
|
||||
|
||||
// Append the "org" special tag for users with a specific prefix or suffix.
|
||||
err = client.User.
|
||||
Update().
|
||||
Where(
|
||||
user.Or(
|
||||
user.NameHasPrefix("org-"),
|
||||
user.NameHasSuffix("-org"),
|
||||
),
|
||||
// Append to only those without this tag.
|
||||
func(s *sql.Selector) {
|
||||
s.Where(
|
||||
sql.Not(sqljson.ValueContains(user.FieldTags, "org")),
|
||||
)
|
||||
},
|
||||
).
|
||||
AppendTags([]string{"org"}).
|
||||
Exec(context.Background())
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed generating backfill statement: %w", err)
|
||||
}
|
||||
// Document all changes until now with a custom comment.
|
||||
w.Change("Append the 'org' tag for organization accounts in case they don't have it.")
|
||||
|
||||
// Write the content to the migration directory.
|
||||
return w.Flush("backfill_user_tags")
|
||||
}
|
||||
```
|
||||
|
||||
Then, using this function in `ent/migrate/main.go` will generate the following migration file:
|
||||
|
||||
```sql title="migrations/20221126185750_backfill_user_tags.sql"
|
||||
-- Backfill NULL or null tags with a default value.
|
||||
UPDATE `users` SET `tags` = '["foo","bar"]' WHERE `tags` IS NULL OR JSON_CONTAINS(`tags`, 'null', '$');
|
||||
-- Append the 'org' tag for organization accounts in case they don't have it.
|
||||
UPDATE `users` SET `tags` = CASE WHEN (JSON_TYPE(JSON_EXTRACT(`tags`, '$')) IS NULL OR JSON_TYPE(JSON_EXTRACT(`tags`, '$')) = 'NULL') THEN JSON_ARRAY('org') ELSE JSON_ARRAY_APPEND(`tags`, '$', 'org') END WHERE (`users`.`name` LIKE 'org-%' OR `users`.`name` LIKE '%-org') AND (NOT (JSON_CONTAINS(`tags`, '"org"', '$') = 1));
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="seed" label="Data Seeding">
|
||||
|
||||
```go title="ent/migrate/migratedata/migratedata.go"
|
||||
package migratedata
|
||||
|
||||
// SeedUsers add the initial users to the database.
|
||||
func SeedUsers(dir *migrate.LocalDir) error {
|
||||
w := &schema.DirWriter{Dir: dir}
|
||||
client := ent.NewClient(ent.Driver(schema.NewWriteDriver(dialect.MySQL, w)))
|
||||
|
||||
// The statement that generates the INSERT statement.
|
||||
err := client.User.CreateBulk(
|
||||
client.User.Create().SetName("a8m").SetAge(1).SetTags([]string{"foo"}),
|
||||
client.User.Create().SetName("nati").SetAge(1).SetTags([]string{"bar"}),
|
||||
).Exec(context.Background())
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed generating statement: %w", err)
|
||||
}
|
||||
|
||||
// Write the content to the migration directory.
|
||||
return w.FlushChange(
|
||||
"seed_users",
|
||||
"Add the initial users to the database.",
|
||||
)
|
||||
}
|
||||
```
|
||||
|
||||
Then, using this function in `ent/migrate/main.go` will generate the following migration file:
|
||||
|
||||
```sql title="migrations/20221126212120_seed_users.sql"
|
||||
-- Add the initial users to the database.
|
||||
INSERT INTO `users` (`age`, `name`, `tags`) VALUES (1, 'a8m', '["foo"]'), (1, 'nati', '["bar"]');
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
3\. In case the generated file was edited, the migration directory [integrity file](https://atlasgo.io/concepts/migration-directory-integrity)
|
||||
needs to be updated with the following command:
|
||||
|
||||
```shell
|
||||
atlas migrate hash \
|
||||
--dir "file://my/project/migrations"
|
||||
```
|
||||
|
||||
### Testing
|
||||
|
||||
After adding the migration files, it is highly recommended that you apply them on a local database to ensure they are
|
||||
valid and achieve the intended results. The following process can be done manually or automated by a program.
|
||||
|
||||
1\. Execute all migration files until the last created one, the data migration file:
|
||||
|
||||
```shell
|
||||
# Total number of files.
|
||||
number_of_files=$(ls ent/migrate/migrations/*.sql | wc -l)
|
||||
|
||||
# Execute all files without the latest.
|
||||
atlas migrate apply $[number_of_files-1] \
|
||||
--dir "file://my/project/migrations" \
|
||||
-u "mysql://root:pass@localhost:3306/test"
|
||||
```
|
||||
|
||||
2\. Ensure the last migration file is pending execution:
|
||||
|
||||
```shell
|
||||
atlas migrate status \
|
||||
--dir "file://my/project/migrations" \
|
||||
-u "mysql://root:pass@localhost:3306/test"
|
||||
|
||||
Migration Status: PENDING
|
||||
-- Current Version: <VERSION_N-1>
|
||||
-- Next Version: <VERSION_N>
|
||||
-- Executed Files: <N-1>
|
||||
-- Pending Files: 1
|
||||
```
|
||||
|
||||
3\. Fill the local database with temporary data that represents the production database before running the data
|
||||
migration file.
|
||||
|
||||
4\. Run `atlas migrate apply` and ensure it was executed successfully.
|
||||
|
||||
```shell
|
||||
atlas migrate apply \
|
||||
--dir "file://my/project/migrations" \
|
||||
-u "mysql://root:pass@localhost:3306/test"
|
||||
```
|
||||
|
||||
Note, by using `atlas schema clean` you can clean the database you use for local development and repeat this process
|
||||
until the data migration file achieves the desired result.
|
||||
|
||||
|
||||
## Automatic Migrations
|
||||
|
||||
In the declarative workflow, data migrations are implemented using Diff or Apply [Hooks](migrate.md#atlas-diff-and-apply-hooks).
|
||||
This is because, unlike the versioned option, migrations of this type do not hold a name or a version when they are applied.
|
||||
Therefore, when a data is written using hooks, the type of the `schema.Change` must be checked before its
|
||||
execution to ensure the data migration was not applied more than once.
|
||||
|
||||
```go
|
||||
func FillNullValues(dbdialect string) schema.ApplyHook {
|
||||
return func(next schema.Applier) schema.Applier {
|
||||
return schema.ApplyFunc(func(ctx context.Context, conn dialect.ExecQuerier, plan *migrate.Plan) error {
|
||||
//highlight-next-line-info
|
||||
// Search the schema.Change that triggers the data migration.
|
||||
hasC := func() bool {
|
||||
for _, c := range plan.Changes {
|
||||
m, ok := c.Source.(*schema.ModifyTable)
|
||||
if ok && m.T.Name == user.Table && schema.Changes(m.Changes).IndexModifyColumn(user.FieldName) != -1 {
|
||||
return true
|
||||
}
|
||||
}
|
||||
return false
|
||||
}()
|
||||
// Change was found, apply the data migration.
|
||||
if hasC {
|
||||
//highlight-info-start
|
||||
// At this stage, there are three ways to UPDATE the NULL values to "Unknown".
|
||||
// Append a custom migrate.Change to migrate.Plan, execute an SQL statement
|
||||
// directly on the dialect.ExecQuerier, or use the generated ent.Client.
|
||||
//highlight-info-end
|
||||
|
||||
// Create a temporary client from the migration connection.
|
||||
client := ent.NewClient(
|
||||
ent.Driver(sql.NewDriver(dbdialect, sql.Conn{ExecQuerier: conn.(*sql.Tx)})),
|
||||
)
|
||||
if err := client.User.
|
||||
Update().
|
||||
SetName("Unknown").
|
||||
Where(user.NameIsNil()).
|
||||
Exec(ctx); err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
return next.Apply(ctx, conn, plan)
|
||||
})
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
For more examples, check out the [Apply Hook](migrate.md#apply-hook-example) examples section.
|
||||
41
doc/md/dialects.md
Normal file
41
doc/md/dialects.md
Normal file
@@ -0,0 +1,41 @@
|
||||
---
|
||||
id: dialects
|
||||
title: Supported Dialects
|
||||
---
|
||||
|
||||
## MySQL
|
||||
|
||||
MySQL supports all the features that are mentioned in the [Migration](migrate.md) section,
|
||||
and it's being tested constantly on the following 3 versions: `5.6.35`, `5.7.26` and `8`.
|
||||
|
||||
## MariaDB
|
||||
|
||||
MariaDB supports all the features that are mentioned in the [Migration](migrate.md) section,
|
||||
and it's being tested constantly on the following 3 versions: `10.2`, `10.3` and latest version.
|
||||
|
||||
## PostgreSQL
|
||||
|
||||
PostgreSQL supports all the features that are mentioned in the [Migration](migrate.md) section,
|
||||
and it's being tested constantly on the following 8 versions: `10`, `11`, `12`, `13`, `14`, `15`, `16`, and `17`.
|
||||
|
||||
## CockroachDB **(<ins>preview</ins>)**
|
||||
|
||||
CockroachDB support is in preview and requires the [Atlas migration engine](migrate.md#atlas-integration).
|
||||
The integration with CRDB is currently tested on versions `v21.2.11`.
|
||||
|
||||
## SQLite
|
||||
|
||||
Using [Atlas](https://github.com/ariga/atlas), the SQLite driver supports all the features that
|
||||
are mentioned in the [Migration](migrate.md) section. Note that some changes, like column modification,
|
||||
are performed on a temporary table using the sequence of operations described in [SQLite official documentation](https://www.sqlite.org/lang_altertable.html#otheralter).
|
||||
|
||||
## Gremlin
|
||||
|
||||
Gremlin does not support migration nor indexes, and **<ins>it's considered experimental</ins>**.
|
||||
|
||||
## TiDB **(<ins>preview</ins>)**
|
||||
|
||||
TiDB support is in preview and requires the [Atlas migration engine](migrate.md#atlas-integration).
|
||||
TiDB is MySQL compatible and thus any feature that works on MySQL _should_ work on TiDB as well.
|
||||
For a list of known compatibility issues, visit: https://docs.pingcap.com/tidb/stable/mysql-compatibility
|
||||
The integration with TiDB is currently tested on versions `5.4.0`, `6.0.0`.
|
||||
192
doc/md/eager-load.mdx
Normal file
192
doc/md/eager-load.mdx
Normal file
@@ -0,0 +1,192 @@
|
||||
---
|
||||
id: eager-load
|
||||
title: Eager Loading
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
## Overview
|
||||
|
||||
`ent` supports querying entities with their associations (through their edges). The associated entities
|
||||
are populated to the `Edges` field in the returned object.
|
||||
|
||||
Let's give an example of what the API looks like for the following schema:
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
**Query all users with their pets:**
|
||||
```go
|
||||
users, err := client.User.
|
||||
Query().
|
||||
WithPets().
|
||||
All(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
// The returned users look as follows:
|
||||
//
|
||||
// [
|
||||
// User {
|
||||
// ID: 1,
|
||||
// Name: "a8m",
|
||||
// Edges: {
|
||||
// Pets: [Pet(...), ...]
|
||||
// ...
|
||||
// }
|
||||
// },
|
||||
// ...
|
||||
// ]
|
||||
//
|
||||
for _, u := range users {
|
||||
for _, p := range u.Edges.Pets {
|
||||
fmt.Printf("User(%v) -> Pet(%v)\n", u.ID, p.ID)
|
||||
// Output:
|
||||
// User(...) -> Pet(...)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Eager loading allows to query more than one association (including nested), and also
|
||||
filter, sort or limit their result. For example:
|
||||
|
||||
```go
|
||||
admins, err := client.User.
|
||||
Query().
|
||||
Where(user.Admin(true)).
|
||||
// Populate the `pets` that associated with the `admins`.
|
||||
WithPets().
|
||||
// Populate the first 5 `groups` that associated with the `admins`.
|
||||
WithGroups(func(q *ent.GroupQuery) {
|
||||
q.Limit(5) // Limit to 5.
|
||||
q.WithUsers() // Populate the `users` of each `groups`.
|
||||
}).
|
||||
All(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
// The returned users look as follows:
|
||||
//
|
||||
// [
|
||||
// User {
|
||||
// ID: 1,
|
||||
// Name: "admin1",
|
||||
// Edges: {
|
||||
// Pets: [Pet(...), ...]
|
||||
// Groups: [
|
||||
// Group {
|
||||
// ID: 7,
|
||||
// Name: "GitHub",
|
||||
// Edges: {
|
||||
// Users: [User(...), ...]
|
||||
// ...
|
||||
// }
|
||||
// }
|
||||
// ]
|
||||
// }
|
||||
// },
|
||||
// ...
|
||||
// ]
|
||||
//
|
||||
for _, admin := range admins {
|
||||
for _, p := range admin.Edges.Pets {
|
||||
fmt.Printf("Admin(%v) -> Pet(%v)\n", u.ID, p.ID)
|
||||
// Output:
|
||||
// Admin(...) -> Pet(...)
|
||||
}
|
||||
for _, g := range admin.Edges.Groups {
|
||||
for _, u := range g.Edges.Users {
|
||||
fmt.Printf("Admin(%v) -> Group(%v) -> User(%v)\n", u.ID, g.ID, u.ID)
|
||||
// Output:
|
||||
// Admin(...) -> Group(...) -> User(...)
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## API
|
||||
|
||||
Each query-builder has a list of methods in the form of `With<E>(...func(<N>Query))` for each of its edges.
|
||||
`<E>` stands for the edge name (like, `WithGroups`) and `<N>` for the edge type (like, `GroupQuery`).
|
||||
|
||||
Note that only SQL dialects support this feature.
|
||||
|
||||
## Named Edges
|
||||
|
||||
In some cases there is a need for preloading edges with custom names. For example, a GraphQL query that has two aliases
|
||||
referencing the same edge with different arguments. For this situation, Ent provides another API named `WithNamed<E>`
|
||||
that can be enabled using the [`namedges`](features.md#named-edges) feature-flag and seamlessly integrated with
|
||||
[EntGQL Fields Collection](tutorial-todo-gql-field-collection.md).
|
||||
|
||||
<Tabs
|
||||
defaultValue="ent"
|
||||
values={[
|
||||
{label: 'Ent', value: 'ent'},
|
||||
{label: 'GraphQL', value: 'graphql'},
|
||||
]}>
|
||||
<TabItem value="ent">
|
||||
|
||||
See the GraphQL tab to learn more about the motivation behind this API.
|
||||
|
||||
```go
|
||||
posts, err := client.Post.Query().
|
||||
WithNamedComments("published", func(q *ent.CommentQuery) {
|
||||
q.Where(comment.StatusEQ(comment.StatusPublished))
|
||||
})
|
||||
WithNamedComments("draft", func(q *ent.CommentQuery) {
|
||||
q.Where(comment.StatusEQ(comment.StatusDraft))
|
||||
}).
|
||||
Paginate(...)
|
||||
|
||||
// Get the preloaded edges by their name:
|
||||
for _, p := range posts {
|
||||
published, err := p.Edges.NamedComments("published")
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
draft, err := p.Edges.NamedComments("draft")
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="graphql">
|
||||
|
||||
An example of a GraphQL query that has two aliases referencing the same edge with different arguments.
|
||||
|
||||
```graphql
|
||||
query {
|
||||
posts {
|
||||
id
|
||||
title
|
||||
published: comments(where: { status: PUBLISHED }) {
|
||||
edges {
|
||||
node {
|
||||
text
|
||||
}
|
||||
}
|
||||
}
|
||||
draft: comments(where: { status: DRAFT }) {
|
||||
edges {
|
||||
node {
|
||||
text
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Implementation
|
||||
|
||||
Since an Ent query can eager-load more than one edge, it is not possible to load all associations in a single
|
||||
`JOIN` operation. Therefore, Ent executes additional query to load each association. This expected to be optimized
|
||||
in future versions.
|
||||
232
doc/md/extension.md
Normal file
232
doc/md/extension.md
Normal file
@@ -0,0 +1,232 @@
|
||||
---
|
||||
id: extensions
|
||||
title: Extensions
|
||||
---
|
||||
|
||||
### Introduction
|
||||
|
||||
The Ent [Extension API](https://pkg.go.dev/entgo.io/ent/entc#Extension)
|
||||
facilitates the creation of code-generation extensions that bundle together [codegen hooks](code-gen.md#code-generation-hooks),
|
||||
[templates](templates.md) and [annotations](templates.md#annotations) to create reusable components
|
||||
that add new rich functionality to Ent's core. For example, Ent's [entgql plugin](https://pkg.go.dev/entgo.io/contrib/entgql#Extension)
|
||||
exposes an `Extension` that automatically generates GraphQL servers from an Ent schema.
|
||||
|
||||
### Defining a New Extension
|
||||
|
||||
All extension's must implement the [Extension](https://pkg.go.dev/entgo.io/ent/entc#Extension) interface:
|
||||
|
||||
```go
|
||||
type Extension interface {
|
||||
// Hooks holds an optional list of Hooks to apply
|
||||
// on the graph before/after the code-generation.
|
||||
Hooks() []gen.Hook
|
||||
|
||||
// Annotations injects global annotations to the gen.Config object that
|
||||
// can be accessed globally in all templates. Unlike schema annotations,
|
||||
// being serializable to JSON raw value is not mandatory.
|
||||
//
|
||||
// {{- with $.Config.Annotations.GQL }}
|
||||
// {{/* Annotation usage goes here. */}}
|
||||
// {{- end }}
|
||||
//
|
||||
Annotations() []Annotation
|
||||
|
||||
// Templates specifies a list of alternative templates
|
||||
// to execute or to override the default.
|
||||
Templates() []*gen.Template
|
||||
|
||||
// Options specifies a list of entc.Options to evaluate on
|
||||
// the gen.Config before executing the code generation.
|
||||
Options() []Option
|
||||
}
|
||||
```
|
||||
To simplify the development of new extensions, developers can embed [entc.DefaultExtension](https://pkg.go.dev/entgo.io/ent/entc#DefaultExtension)
|
||||
to create extensions without implementing all methods:
|
||||
|
||||
```go
|
||||
package hello
|
||||
|
||||
// GreetExtension implements entc.Extension.
|
||||
type GreetExtension struct {
|
||||
entc.DefaultExtension
|
||||
}
|
||||
```
|
||||
|
||||
### Adding Templates
|
||||
|
||||
Ent supports adding [external templates](templates.md) that will be rendered during
|
||||
code generation. To bundle such external templates on an extension, implement the `Templates`
|
||||
method:
|
||||
```gotemplate title="templates/greet.tmpl"
|
||||
{{/* Tell Intellij/GoLand to enable the autocompletion based on the *gen.Graph type. */}}
|
||||
{{/* gotype: entgo.io/ent/entc/gen.Graph */}}
|
||||
|
||||
{{ define "greet" }}
|
||||
|
||||
{{/* Add the base header for the generated file */}}
|
||||
{{ $pkg := base $.Config.Package }}
|
||||
{{ template "header" $ }}
|
||||
|
||||
{{/* Loop over all nodes and add the Greet method */}}
|
||||
{{ range $n := $.Nodes }}
|
||||
{{ $receiver := $n.Receiver }}
|
||||
func ({{ $receiver }} *{{ $n.Name }}) Greet() string {
|
||||
return "Hello, {{ $n.Name }}"
|
||||
}
|
||||
{{ end }}
|
||||
|
||||
{{ end }}
|
||||
```
|
||||
```go
|
||||
func (*GreetExtension) Templates() []*gen.Template {
|
||||
return []*gen.Template{
|
||||
gen.MustParse(gen.NewTemplate("greet").ParseFiles("templates/greet.tmpl")),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Adding Global Annotations
|
||||
|
||||
Annotations are a convenient way to supply users of our extension with an API
|
||||
to modify the behavior of code generation. To add annotations to our extension,
|
||||
implement the `Annotations` method. Let's say in our `GreetExtension` we want
|
||||
to provide users with the ability to configure the greeting word in the generated
|
||||
code:
|
||||
|
||||
```go
|
||||
// GreetingWord implements entc.Annotation.
|
||||
type GreetingWord string
|
||||
|
||||
// Name of the annotation. Used by the codegen templates.
|
||||
func (GreetingWord) Name() string {
|
||||
return "GreetingWord"
|
||||
}
|
||||
```
|
||||
Then add it to the `GreetExtension` struct:
|
||||
```go
|
||||
type GreetExtension struct {
|
||||
entc.DefaultExtension
|
||||
word GreetingWord
|
||||
}
|
||||
```
|
||||
Next, implement the `Annotations` method:
|
||||
```go
|
||||
func (s *GreetExtension) Annotations() []entc.Annotation {
|
||||
return []entc.Annotation{
|
||||
s.word,
|
||||
}
|
||||
}
|
||||
```
|
||||
Now, from within your templates you can access the `GreetingWord` annotation:
|
||||
```gotemplate
|
||||
func ({{ $receiver }} *{{ $n.Name }}) Greet() string {
|
||||
return "{{ $.Annotations.GreetingWord }}, {{ $n.Name }}"
|
||||
}
|
||||
```
|
||||
|
||||
### Adding Hooks
|
||||
|
||||
The entc package provides an option to add a list of [hooks](code-gen.md#code-generation-hooks)
|
||||
(middlewares) to the code-generation phase. This option is ideal for adding custom validators for the
|
||||
schema, or for generating additional assets using the graph schema. To bundle
|
||||
code generation hooks with your extension, implement the `Hooks` method:
|
||||
|
||||
```go
|
||||
func (s *GreetExtension) Hooks() []gen.Hook {
|
||||
return []gen.Hook{
|
||||
DisallowTypeName("Shalom"),
|
||||
}
|
||||
}
|
||||
|
||||
// DisallowTypeName ensures there is no ent.Schema with the given name in the graph.
|
||||
func DisallowTypeName(name string) gen.Hook {
|
||||
return func(next gen.Generator) gen.Generator {
|
||||
return gen.GenerateFunc(func(g *gen.Graph) error {
|
||||
for _, node := range g.Nodes {
|
||||
if node.Name == name {
|
||||
return fmt.Errorf("entc: validation failed, type named %q not allowed", name)
|
||||
}
|
||||
}
|
||||
return next.Generate(g)
|
||||
})
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Using an Extension in Code Generation
|
||||
|
||||
To use an extension in our code-generation configuration, use `entc.Extensions`, a helper
|
||||
method that returns an `entc.Option` that applies our chosen extensions:
|
||||
|
||||
```go title="ent/entc.go"
|
||||
//+build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
)
|
||||
|
||||
func main() {
|
||||
err := entc.Generate("./schema",
|
||||
&gen.Config{},
|
||||
entc.Extensions(&GreetExtension{
|
||||
word: GreetingWord("Shalom"),
|
||||
}),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatal("running ent codegen:", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Community Extensions
|
||||
|
||||
- **[entoas](https://github.com/ent/contrib/tree/master/entoas)**
|
||||
`entoas` is an extension that originates from `elk` and was ported into its own extension and is now the official
|
||||
generator for and opinionated OpenAPI Specification document. You can use this to rapidly develop and document a
|
||||
RESTful HTTP server. There will be a new extension released soon providing a generated implementation integrating for
|
||||
the document provided by `entoas` using `ent`.
|
||||
|
||||
- **[entrest](https://github.com/lrstanley/entrest)**
|
||||
`entrest` is an alternative to `entoas`(+ `ogent`) and `elk` (before it was discontinued). entrest generates a compliant,
|
||||
efficient, and feature-complete OpenAPI specification from your Ent schema, along with a functional RESTful API server
|
||||
implementation. The highlight features include: toggleable pagination, advanced filtering/querying capabilities, sorting
|
||||
(even through relationships), eager-loading edges, and a bunch more.
|
||||
|
||||
- **[entgql](https://github.com/ent/contrib/tree/master/entgql)**
|
||||
This extension helps users build [GraphQL](https://graphql.org/) servers from Ent schemas. `entgql` integrates
|
||||
with [gqlgen](https://github.com/99designs/gqlgen), a popular, schema-first Go library for building GraphQL servers.
|
||||
The extension includes the generation of type-safe GraphQL filters, which enable users to effortlessly map GraphQL
|
||||
queries to Ent queries.
|
||||
Follow [this tutorial](https://entgo.io/docs/tutorial-todo-gql) to get started.
|
||||
|
||||
- **[entproto](https://github.com/ent/contrib/tree/master/entproto)**
|
||||
`entproto` generates Protobuf message definitions and gRPC service definitions from Ent schemas. The project also
|
||||
includes `protoc-gen-entgrpc`, a `protoc` (Protobuf compiler) plugin that is used to generate a working implementation
|
||||
of the gRPC service definition generated by Entproto. In this manner, we can easily create a gRPC server that can
|
||||
serve requests to our service without writing any code (aside from defining the Ent schema)!
|
||||
To learn how to use and set up `entproto`, read [this tutorial](https://entgo.io/docs/grpc-intro). For more background
|
||||
you can read [this blog post](https://entgo.io/blog/2021/03/18/generating-a-grpc-server-with-ent),
|
||||
or [this blog post](https://entgo.io/blog/2021/06/28/gprc-ready-for-use/) discussing more `entproto` features.
|
||||
|
||||
- **[elk (discontinued)](https://github.com/masseelch/elk)**
|
||||
`elk` is an extension that generates RESTful API endpoints from Ent schemas. The extension generates HTTP CRUD
|
||||
handlers from the Ent schema, as well as an OpenAPI JSON file. By using it, you can easily build a RESTful HTTP server
|
||||
for your application. **Please note, that `elk` has been discontinued in favor of `entoas`**. An implementation generator
|
||||
is in the works.
|
||||
Read [this blog post](https://entgo.io/blog/2021/07/29/generate-a-fully-working-go-crud-http-api-with-ent) on how to
|
||||
work with `elk`, and [this blog post](https://entgo.io/blog/2021/09/10/openapi-generator) on how to generate
|
||||
an [OpenAPI Specification](https://swagger.io/resources/open-api/).
|
||||
|
||||
- **[entviz (discontinued)](https://github.com/hedwigz/entviz)**
|
||||
`entviz` is an extension that generates visual diagrams from Ent schemas. These diagrams visualize the schema in a web
|
||||
browser, and stay updated as we continue coding. `entviz` can be configured in such a way that every time we
|
||||
regenerate the schema, the diagram is automatically updated, making it easy to view the changes being made.
|
||||
Learn how to integrate `entviz` in your project
|
||||
in [this blog post](https://entgo.io/blog/2021/08/26/visualizing-your-data-graph-using-entviz). **This extension has been
|
||||
archived by the maintainer as of 2023-09-16**.
|
||||
849
doc/md/faq.md
Normal file
849
doc/md/faq.md
Normal file
@@ -0,0 +1,849 @@
|
||||
---
|
||||
id: faq
|
||||
title: Frequently Asked Questions (FAQ)
|
||||
sidebar_label: FAQ
|
||||
---
|
||||
|
||||
## Questions
|
||||
|
||||
[How to create an entity from a struct `T`?](#how-to-create-an-entity-from-a-struct-t)
|
||||
[How to create a struct (or a mutation) level validator?](#how-to-create-a-mutation-level-validator)
|
||||
[How to write an audit-log extension?](#how-to-write-an-audit-log-extension)
|
||||
[How to write custom predicates?](#how-to-write-custom-predicates)
|
||||
[How to add custom predicates to the codegen assets?](#how-to-add-custom-predicates-to-the-codegen-assets)
|
||||
[How to define a network address field in PostgreSQL?](#how-to-define-a-network-address-field-in-postgresql)
|
||||
[How to customize time fields to type `DATETIME` in MySQL?](#how-to-customize-time-fields-to-type-datetime-in-mysql)
|
||||
[How to use a custom generator of IDs?](#how-to-use-a-custom-generator-of-ids)
|
||||
[How to use a custom XID globally unique ID?](#how-to-use-a-custom-xid-globally-unique-id)
|
||||
[How to define a spatial data type field in MySQL?](#how-to-define-a-spatial-data-type-field-in-mysql)
|
||||
[How to extend the generated models?](#how-to-extend-the-generated-models)
|
||||
[How to extend the generated builders?](#how-to-extend-the-generated-builders)
|
||||
[How to store Protobuf objects in a BLOB column?](#how-to-store-protobuf-objects-in-a-blob-column)
|
||||
[How to add `CHECK` constraints to table?](#how-to-add-check-constraints-to-table)
|
||||
[How to define a custom precision numeric field?](#how-to-define-a-custom-precision-numeric-field)
|
||||
[How to configure two or more `DB` to separate read and write?](#how-to-configure-two-or-more-db-to-separate-read-and-write)
|
||||
[How to configure `json.Marshal` to inline the `edges` keys in the top level object?](#how-to-configure-jsonmarshal-to-inline-the-edges-keys-in-the-top-level-object)
|
||||
|
||||
## Answers
|
||||
|
||||
#### How to create an entity from a struct `T`?
|
||||
|
||||
The different builders don't support the option of setting the entity fields (or edges) from a given struct `T`.
|
||||
The reason is that there's no way to distinguish between zero/real values when updating the database (for example, `&ent.T{Age: 0, Name: ""}`).
|
||||
Setting these values, may set incorrect values in the database or update unnecessary columns.
|
||||
|
||||
However, the [external template](templates.md) option lets you extend the default code-generation assets by adding custom logic.
|
||||
For example, in order to generate a method for each of the create-builders, that accepts a struct as an input and configure the builder,
|
||||
use the following template:
|
||||
|
||||
```gotemplate
|
||||
{{ range $n := $.Nodes }}
|
||||
{{ $builder := $n.CreateName }}
|
||||
{{ $receiver := $n.CreateReceiver }}
|
||||
|
||||
func ({{ $receiver }} *{{ $builder }}) Set{{ $n.Name }}(input *{{ $n.Name }}) *{{ $builder }} {
|
||||
{{- range $f := $n.Fields }}
|
||||
{{- $setter := print "Set" $f.StructField }}
|
||||
{{ $receiver }}.{{ $setter }}(input.{{ $f.StructField }})
|
||||
{{- end }}
|
||||
return {{ $receiver }}
|
||||
}
|
||||
{{ end }}
|
||||
```
|
||||
|
||||
#### How to create a mutation level validator?
|
||||
|
||||
In order to implement a mutation-level validator, you can either use [schema hooks](hooks.md#schema-hooks) for validating
|
||||
changes applied on one entity type, or use [transaction hooks](transactions.md#hooks) for validating mutations that being
|
||||
applied on multiple entity types (e.g. a GraphQL mutation). For example:
|
||||
|
||||
```go
|
||||
// A VersionHook is a dummy example for a hook that validates the "version" field
|
||||
// is incremented by 1 on each update. Note that this is just a dummy example, and
|
||||
// it doesn't promise consistency in the database.
|
||||
func VersionHook() ent.Hook {
|
||||
type OldSetVersion interface {
|
||||
SetVersion(int)
|
||||
Version() (int, bool)
|
||||
OldVersion(context.Context) (int, error)
|
||||
}
|
||||
return func(next ent.Mutator) ent.Mutator {
|
||||
return ent.MutateFunc(func(ctx context.Context, m ent.Mutation) (ent.Value, error) {
|
||||
ver, ok := m.(OldSetVersion)
|
||||
if !ok {
|
||||
return next.Mutate(ctx, m)
|
||||
}
|
||||
oldV, err := ver.OldVersion(ctx)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
curV, exists := ver.Version()
|
||||
if !exists {
|
||||
return nil, fmt.Errorf("version field is required in update mutation")
|
||||
}
|
||||
if curV != oldV+1 {
|
||||
return nil, fmt.Errorf("version field must be incremented by 1")
|
||||
}
|
||||
// Add an SQL predicate that validates the "version" column is equal
|
||||
// to "oldV" (ensure it wasn't changed during the mutation by others).
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
#### How to write an audit-log extension?
|
||||
|
||||
The preferred way for writing such an extension is to use [ent.Mixin](schema-mixin.md). Use the `Fields` option for
|
||||
setting the fields that are shared between all schemas that import the mixed-schema, and use the `Hooks` option for
|
||||
attaching a mutation-hook for all mutations that are being applied on these schemas. Here's an example, based on a
|
||||
discussion in the [repository issue-tracker](https://github.com/ent/ent/issues/830):
|
||||
|
||||
```go
|
||||
// AuditMixin implements the ent.Mixin for sharing
|
||||
// audit-log capabilities with package schemas.
|
||||
type AuditMixin struct{
|
||||
mixin.Schema
|
||||
}
|
||||
|
||||
// Fields of the AuditMixin.
|
||||
func (AuditMixin) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Time("created_at").
|
||||
Immutable().
|
||||
Default(time.Now),
|
||||
field.Int("created_by").
|
||||
Optional(),
|
||||
field.Time("updated_at").
|
||||
Default(time.Now).
|
||||
UpdateDefault(time.Now),
|
||||
field.Int("updated_by").
|
||||
Optional(),
|
||||
}
|
||||
}
|
||||
|
||||
// Hooks of the AuditMixin.
|
||||
func (AuditMixin) Hooks() []ent.Hook {
|
||||
return []ent.Hook{
|
||||
hooks.AuditHook,
|
||||
}
|
||||
}
|
||||
|
||||
// A AuditHook is an example for audit-log hook.
|
||||
func AuditHook(next ent.Mutator) ent.Mutator {
|
||||
// AuditLogger wraps the methods that are shared between all mutations of
|
||||
// schemas that embed the AuditLog mixin. The variable "exists" is true, if
|
||||
// the field already exists in the mutation (e.g. was set by a different hook).
|
||||
type AuditLogger interface {
|
||||
SetCreatedAt(time.Time)
|
||||
CreatedAt() (value time.Time, exists bool)
|
||||
SetCreatedBy(int)
|
||||
CreatedBy() (id int, exists bool)
|
||||
SetUpdatedAt(time.Time)
|
||||
UpdatedAt() (value time.Time, exists bool)
|
||||
SetUpdatedBy(int)
|
||||
UpdatedBy() (id int, exists bool)
|
||||
}
|
||||
return ent.MutateFunc(func(ctx context.Context, m ent.Mutation) (ent.Value, error) {
|
||||
ml, ok := m.(AuditLogger)
|
||||
if !ok {
|
||||
return nil, fmt.Errorf("unexpected audit-log call from mutation type %T", m)
|
||||
}
|
||||
usr, err := viewer.UserFromContext(ctx)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
switch op := m.Op(); {
|
||||
case op.Is(ent.OpCreate):
|
||||
ml.SetCreatedAt(time.Now())
|
||||
if _, exists := ml.CreatedBy(); !exists {
|
||||
ml.SetCreatedBy(usr.ID)
|
||||
}
|
||||
case op.Is(ent.OpUpdateOne | ent.OpUpdate):
|
||||
ml.SetUpdatedAt(time.Now())
|
||||
if _, exists := ml.UpdatedBy(); !exists {
|
||||
ml.SetUpdatedBy(usr.ID)
|
||||
}
|
||||
}
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
}
|
||||
```
|
||||
|
||||
#### How to write custom predicates?
|
||||
|
||||
Users can provide custom predicates to apply on the query before it's executed. For example:
|
||||
|
||||
```go
|
||||
pets := client.Pet.
|
||||
Query().
|
||||
Where(predicate.Pet(func(s *sql.Selector) {
|
||||
s.Where(sql.InInts(pet.OwnerColumn, 1, 2, 3))
|
||||
})).
|
||||
AllX(ctx)
|
||||
|
||||
users := client.User.
|
||||
Query().
|
||||
Where(predicate.User(func(s *sql.Selector) {
|
||||
s.Where(sqljson.ValueContains(user.FieldTags, "tag"))
|
||||
})).
|
||||
AllX(ctx)
|
||||
```
|
||||
|
||||
For more examples, go to the [predicates](predicates.md#custom-predicates) page, or search in the repository
|
||||
issue-tracker for more advance examples like [issue-842](https://github.com/ent/ent/issues/842#issuecomment-707896368).
|
||||
|
||||
#### How to add custom predicates to the codegen assets?
|
||||
|
||||
The [template](templates.md) option enables the capability for extending or overriding the default codegen assets.
|
||||
In order to generate a type-safe predicate for the [example above](#how-to-write-custom-predicates), use the template
|
||||
option for doing it as follows:
|
||||
|
||||
```gotemplate
|
||||
{{/* A template that adds the "<F>Glob" predicate for all string fields. */}}
|
||||
{{ define "where/additional/strings" }}
|
||||
{{ range $f := $.Fields }}
|
||||
{{ if $f.IsString }}
|
||||
{{ $func := print $f.StructField "Glob" }}
|
||||
// {{ $func }} applies the Glob predicate on the {{ quote $f.Name }} field.
|
||||
func {{ $func }}(pattern string) predicate.{{ $.Name }} {
|
||||
return predicate.{{ $.Name }}(func(s *sql.Selector) {
|
||||
s.Where(sql.P(func(b *sql.Builder) {
|
||||
b.Ident(s.C({{ $f.Constant }})).WriteString(" glob" ).Arg(pattern)
|
||||
}))
|
||||
})
|
||||
}
|
||||
{{ end }}
|
||||
{{ end }}
|
||||
{{ end }}
|
||||
```
|
||||
|
||||
#### How to define a network address field in PostgreSQL?
|
||||
|
||||
The [GoType](schema-fields.mdx#go-type) and the [SchemaType](schema-fields.mdx#database-type)
|
||||
options allow users to define database-specific fields. For example, in order to define a
|
||||
[`macaddr`](https://www.postgresql.org/docs/13/datatype-net-types.html#DATATYPE-MACADDR) field, use the following configuration:
|
||||
|
||||
```go
|
||||
func (T) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("mac").
|
||||
GoType(&MAC{}).
|
||||
SchemaType(map[string]string{
|
||||
dialect.Postgres: "macaddr",
|
||||
}).
|
||||
Validate(func(s string) error {
|
||||
_, err := net.ParseMAC(s)
|
||||
return err
|
||||
}),
|
||||
}
|
||||
}
|
||||
|
||||
// MAC represents a physical hardware address.
|
||||
type MAC struct {
|
||||
net.HardwareAddr
|
||||
}
|
||||
|
||||
// Scan implements the Scanner interface.
|
||||
func (m *MAC) Scan(value any) (err error) {
|
||||
switch v := value.(type) {
|
||||
case nil:
|
||||
case []byte:
|
||||
m.HardwareAddr, err = net.ParseMAC(string(v))
|
||||
case string:
|
||||
m.HardwareAddr, err = net.ParseMAC(v)
|
||||
default:
|
||||
err = fmt.Errorf("unexpected type %T", v)
|
||||
}
|
||||
return
|
||||
}
|
||||
|
||||
// Value implements the driver Valuer interface.
|
||||
func (m MAC) Value() (driver.Value, error) {
|
||||
return m.HardwareAddr.String(), nil
|
||||
}
|
||||
```
|
||||
Note that, if the database doesn't support the `macaddr` type (e.g. SQLite on testing), the field fallback to its
|
||||
native type (i.e. `string`).
|
||||
|
||||
`inet` example:
|
||||
|
||||
```go
|
||||
func (T) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("ip").
|
||||
GoType(&Inet{}).
|
||||
SchemaType(map[string]string{
|
||||
dialect.Postgres: "inet",
|
||||
}).
|
||||
Validate(func(s string) error {
|
||||
if net.ParseIP(s) == nil {
|
||||
return fmt.Errorf("invalid value for ip %q", s)
|
||||
}
|
||||
return nil
|
||||
}),
|
||||
}
|
||||
}
|
||||
|
||||
// Inet represents a single IP address
|
||||
type Inet struct {
|
||||
net.IP
|
||||
}
|
||||
|
||||
// Scan implements the Scanner interface
|
||||
func (i *Inet) Scan(value any) (err error) {
|
||||
switch v := value.(type) {
|
||||
case nil:
|
||||
case []byte:
|
||||
if i.IP = net.ParseIP(string(v)); i.IP == nil {
|
||||
err = fmt.Errorf("invalid value for ip %q", v)
|
||||
}
|
||||
case string:
|
||||
if i.IP = net.ParseIP(v); i.IP == nil {
|
||||
err = fmt.Errorf("invalid value for ip %q", v)
|
||||
}
|
||||
default:
|
||||
err = fmt.Errorf("unexpected type %T", v)
|
||||
}
|
||||
return
|
||||
}
|
||||
|
||||
// Value implements the driver Valuer interface
|
||||
func (i Inet) Value() (driver.Value, error) {
|
||||
return i.IP.String(), nil
|
||||
}
|
||||
```
|
||||
|
||||
#### How to customize time fields to type `DATETIME` in MySQL?
|
||||
|
||||
`Time` fields use the MySQL `TIMESTAMP` type in the schema creation by default, and this type
|
||||
has a range of '1970-01-01 00:00:01' UTC to '2038-01-19 03:14:07' UTC (see, [MySQL docs](https://dev.mysql.com/doc/refman/5.6/en/datetime.html)).
|
||||
|
||||
In order to customize time fields for a wider range, use the MySQL `DATETIME` as follows:
|
||||
```go
|
||||
field.Time("birth_date").
|
||||
Optional().
|
||||
SchemaType(map[string]string{
|
||||
dialect.MySQL: "datetime",
|
||||
}),
|
||||
```
|
||||
|
||||
#### How to use a custom generator of IDs?
|
||||
|
||||
If you're using a custom ID generator instead of using auto-incrementing IDs in
|
||||
your database (e.g. Twitter's [Snowflake](https://github.com/twitter-archive/snowflake/tree/snowflake-2010)),
|
||||
you will need to write a custom ID field which automatically calls the generator
|
||||
on resource creation.
|
||||
|
||||
To achieve this, you can either make use of `DefaultFunc` or of schema hooks -
|
||||
depending on your use case. If the generator does not return an error,
|
||||
`DefaultFunc` is more concise, whereas setting a hook on resource creation
|
||||
will allow you to capture errors as well. An example of how to use
|
||||
`DefaultFunc` can be seen in the section regarding [the ID field](schema-fields.mdx#id-field).
|
||||
|
||||
Here is an example of how to use a custom generator with hooks, taking as an
|
||||
example [sonyflake](https://github.com/sony/sonyflake).
|
||||
|
||||
```go
|
||||
// BaseMixin to be shared will all different schemas.
|
||||
type BaseMixin struct {
|
||||
mixin.Schema
|
||||
}
|
||||
|
||||
// Fields of the Mixin.
|
||||
func (BaseMixin) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Uint64("id"),
|
||||
}
|
||||
}
|
||||
|
||||
// Hooks of the Mixin.
|
||||
func (BaseMixin) Hooks() []ent.Hook {
|
||||
return []ent.Hook{
|
||||
hook.On(IDHook(), ent.OpCreate),
|
||||
}
|
||||
}
|
||||
|
||||
func IDHook() ent.Hook {
|
||||
sf := sonyflake.NewSonyflake(sonyflake.Settings{})
|
||||
type IDSetter interface {
|
||||
SetID(uint64)
|
||||
}
|
||||
return func(next ent.Mutator) ent.Mutator {
|
||||
return ent.MutateFunc(func(ctx context.Context, m ent.Mutation) (ent.Value, error) {
|
||||
is, ok := m.(IDSetter)
|
||||
if !ok {
|
||||
return nil, fmt.Errorf("unexpected mutation %T", m)
|
||||
}
|
||||
id, err := sf.NextID()
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
is.SetID(id)
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Mixin of the User.
|
||||
func (User) Mixin() []ent.Mixin {
|
||||
return []ent.Mixin{
|
||||
// Embed the BaseMixin in the user schema.
|
||||
BaseMixin{},
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
#### How to use a custom XID globally unique ID?
|
||||
|
||||
Package [xid](https://github.com/rs/xid) is a globally unique ID generator library that uses the [Mongo Object ID](https://docs.mongodb.org/manual/reference/object-id/)
|
||||
algorithm to generate a 12 byte, 20 character ID with no configuration. The xid package comes with [database/sql](https://pkg.go.dev/database/sql) `sql.Scanner` and `driver.Valuer` interfaces required by Ent for serialization.
|
||||
|
||||
To store an XID in any string field use the [GoType](schema-fields.mdx#go-type) schema configuration:
|
||||
|
||||
```go
|
||||
// Fields of type T.
|
||||
func (T) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("id").
|
||||
GoType(xid.ID{}).
|
||||
DefaultFunc(xid.New),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Or as a reusable [Mixin](schema-mixin.md) across multiple schemas:
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
"entgo.io/ent/schema/mixin"
|
||||
"github.com/rs/xid"
|
||||
)
|
||||
|
||||
// BaseMixin to be shared will all different schemas.
|
||||
type BaseMixin struct {
|
||||
mixin.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (BaseMixin) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("id").
|
||||
GoType(xid.ID{}).
|
||||
DefaultFunc(xid.New),
|
||||
}
|
||||
}
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Mixin of the User.
|
||||
func (User) Mixin() []ent.Mixin {
|
||||
return []ent.Mixin{
|
||||
// Embed the BaseMixin in the user schema.
|
||||
BaseMixin{},
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
In order to use extended identifiers (XIDs) with gqlgen, follow the configuration mentioned in the [issue tracker](https://github.com/ent/ent/issues/1526#issuecomment-831034884).
|
||||
|
||||
#### How to define a spatial data type field in MySQL?
|
||||
|
||||
The [GoType](schema-fields.mdx#go-type) and the [SchemaType](schema-fields.mdx#database-type)
|
||||
options allow users to define database-specific fields. For example, in order to define a
|
||||
[`POINT`](https://dev.mysql.com/doc/refman/8.0/en/spatial-type-overview.html) field, use the following configuration:
|
||||
|
||||
```go
|
||||
// Fields of the Location.
|
||||
func (Location) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.Other("coords", &Point{}).
|
||||
SchemaType(Point{}.SchemaType()),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"database/sql/driver"
|
||||
"fmt"
|
||||
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/sql"
|
||||
"github.com/paulmach/orb"
|
||||
"github.com/paulmach/orb/encoding/wkb"
|
||||
)
|
||||
|
||||
// A Point consists of (X,Y) or (Lat, Lon) coordinates
|
||||
// and it is stored in MySQL the POINT spatial data type.
|
||||
type Point [2]float64
|
||||
|
||||
// Scan implements the Scanner interface.
|
||||
func (p *Point) Scan(value any) error {
|
||||
bin, ok := value.([]byte)
|
||||
if !ok {
|
||||
return fmt.Errorf("invalid binary value for point")
|
||||
}
|
||||
var op orb.Point
|
||||
if err := wkb.Scanner(&op).Scan(bin[4:]); err != nil {
|
||||
return err
|
||||
}
|
||||
p[0], p[1] = op.X(), op.Y()
|
||||
return nil
|
||||
}
|
||||
|
||||
// Value implements the driver Valuer interface.
|
||||
func (p Point) Value() (driver.Value, error) {
|
||||
op := orb.Point{p[0], p[1]}
|
||||
return wkb.Value(op).Value()
|
||||
}
|
||||
|
||||
// FormatParam implements the sql.ParamFormatter interface to tell the SQL
|
||||
// builder that the placeholder for a Point parameter needs to be formatted.
|
||||
func (p Point) FormatParam(placeholder string, info *sql.StmtInfo) string {
|
||||
if info.Dialect == dialect.MySQL {
|
||||
return "ST_GeomFromWKB(" + placeholder + ")"
|
||||
}
|
||||
return placeholder
|
||||
}
|
||||
|
||||
// SchemaType defines the schema-type of the Point object.
|
||||
func (Point) SchemaType() map[string]string {
|
||||
return map[string]string{
|
||||
dialect.MySQL: "POINT",
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
A full example exists in the [example repository](https://github.com/a8m/entspatial).
|
||||
|
||||
|
||||
#### How to extend the generated models?
|
||||
|
||||
Ent supports extending generated types (both global types and models) using custom templates. For example, in order to
|
||||
add additional struct fields or methods to the generated model, we can override the `model/fields/additional` template like in this
|
||||
[example](https://github.com/ent/ent/blob/dd4792f5b30bdd2db0d9a593a977a54cb3f0c1ce/examples/entcpkg/ent/template/static.tmpl).
|
||||
|
||||
|
||||
If your custom fields/methods require additional imports, you can add those imports using custom templates as well:
|
||||
|
||||
```gotemplate
|
||||
{{- define "import/additional/field_types" -}}
|
||||
"github.com/path/to/your/custom/type"
|
||||
{{- end -}}
|
||||
|
||||
{{- define "import/additional/client_dependencies" -}}
|
||||
"github.com/path/to/your/custom/type"
|
||||
{{- end -}}
|
||||
```
|
||||
|
||||
#### How to extend the generated builders?
|
||||
|
||||
See the *[Injecting External Dependencies](code-gen.md#external-dependencies)* section, or follow the
|
||||
example on [GitHub](https://github.com/ent/ent/tree/master/examples/entcpkg).
|
||||
|
||||
#### How to store Protobuf objects in a BLOB column?
|
||||
|
||||
Assuming we have a Protobuf message defined:
|
||||
```protobuf
|
||||
syntax = "proto3";
|
||||
|
||||
package pb;
|
||||
|
||||
option go_package = "project/pb";
|
||||
|
||||
message Hi {
|
||||
string Greeting = 1;
|
||||
}
|
||||
```
|
||||
|
||||
We add receiver methods to the generated protobuf struct such that it implements [ValueScanner](https://pkg.go.dev/entgo.io/ent/schema/field#ValueScanner)
|
||||
|
||||
```go
|
||||
func (x *Hi) Value() (driver.Value, error) {
|
||||
return proto.Marshal(x)
|
||||
}
|
||||
|
||||
func (x *Hi) Scan(src any) error {
|
||||
if src == nil {
|
||||
return nil
|
||||
}
|
||||
if b, ok := src.([]byte); ok {
|
||||
if err := proto.Unmarshal(b, x); err != nil {
|
||||
return err
|
||||
}
|
||||
return nil
|
||||
}
|
||||
return fmt.Errorf("unexpected type %T", src)
|
||||
}
|
||||
```
|
||||
|
||||
We add a new `field.Bytes` to our schema, setting the generated protobuf struct as its underlying `GoType`:
|
||||
|
||||
```go
|
||||
// Fields of the Message.
|
||||
func (Message) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Bytes("hi").
|
||||
GoType(&pb.Hi{}),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Test that it works:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"testing"
|
||||
|
||||
"project/ent/enttest"
|
||||
"project/pb"
|
||||
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
"github.com/stretchr/testify/require"
|
||||
)
|
||||
|
||||
func TestMain(t *testing.T) {
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
defer client.Close()
|
||||
|
||||
msg := client.Message.Create().
|
||||
SetHi(&pb.Hi{
|
||||
Greeting: "hello",
|
||||
}).
|
||||
SaveX(context.TODO())
|
||||
|
||||
ret := client.Message.GetX(context.TODO(), msg.ID)
|
||||
require.Equal(t, "hello", ret.Hi.Greeting)
|
||||
}
|
||||
```
|
||||
|
||||
#### How to add `CHECK` constraints to table?
|
||||
|
||||
The [`entsql.Annotation`](schema-annotations.md) option allows adding custom `CHECK` constraints to the `CREATE TABLE`
|
||||
statement. In order to add `CHECK` constraints to your schema, use the following example:
|
||||
|
||||
```go
|
||||
func (User) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
&entsql.Annotation{
|
||||
// The `Check` option allows adding an
|
||||
// unnamed CHECK constraint to table DDL.
|
||||
Check: "website <> 'entgo.io'",
|
||||
|
||||
// The `Checks` option allows adding multiple CHECK constraints
|
||||
// to table creation. The keys are used as the constraint names.
|
||||
Checks: map[string]string{
|
||||
"valid_nickname": "nickname <> firstname",
|
||||
"valid_firstname": "length(first_name) > 1",
|
||||
},
|
||||
},
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
#### How to define a custom precision numeric field?
|
||||
|
||||
Using [GoType](schema-fields.mdx#go-type) and [SchemaType](schema-fields.mdx#database-type) it is possible to define
|
||||
custom precision numeric fields. For example, defining a field that uses [big.Int](https://pkg.go.dev/math/big).
|
||||
|
||||
```go
|
||||
func (T) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Int("precise").
|
||||
GoType(new(BigInt)).
|
||||
SchemaType(map[string]string{
|
||||
dialect.SQLite: "numeric(78, 0)",
|
||||
dialect.Postgres: "numeric(78, 0)",
|
||||
}),
|
||||
}
|
||||
}
|
||||
|
||||
type BigInt struct {
|
||||
big.Int
|
||||
}
|
||||
|
||||
func (b *BigInt) Scan(src any) error {
|
||||
var i sql.NullString
|
||||
if err := i.Scan(src); err != nil {
|
||||
return err
|
||||
}
|
||||
if !i.Valid {
|
||||
return nil
|
||||
}
|
||||
if _, ok := b.Int.SetString(i.String, 10); ok {
|
||||
return nil
|
||||
}
|
||||
return fmt.Errorf("could not scan type %T with value %v into BigInt", src, src)
|
||||
}
|
||||
|
||||
func (b *BigInt) Value() (driver.Value, error) {
|
||||
return b.String(), nil
|
||||
}
|
||||
```
|
||||
|
||||
#### How to configure two or more `DB` to separate read and write?
|
||||
|
||||
You can wrap the `dialect.Driver` with your own driver and implement this logic. For example.
|
||||
|
||||
You can extend it, add support for multiple read replicas and add some load-balancing magic.
|
||||
|
||||
```go
|
||||
func main() {
|
||||
// ...
|
||||
wd, err := sql.Open(dialect.MySQL, "root:pass@tcp(<addr>)/<database>?parseTime=True")
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
rd, err := sql.Open(dialect.MySQL, "readonly:pass@tcp(<addr>)/<database>?parseTime=True")
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
client := ent.NewClient(ent.Driver(&multiDriver{w: wd, r: rd}))
|
||||
defer client.Close()
|
||||
// Use the client here.
|
||||
}
|
||||
|
||||
type multiDriver struct {
|
||||
r, w dialect.Driver
|
||||
}
|
||||
|
||||
var _ dialect.Driver = (*multiDriver)(nil)
|
||||
|
||||
func (d *multiDriver) Query(ctx context.Context, query string, args, v any) error {
|
||||
e := d.r
|
||||
// Mutation statements that use the RETURNING clause.
|
||||
if ent.QueryFromContext(ctx) == nil {
|
||||
e = d.w
|
||||
}
|
||||
return e.Query(ctx, query, args, v)
|
||||
}
|
||||
|
||||
func (d *multiDriver) Exec(ctx context.Context, query string, args, v any) error {
|
||||
return d.w.Exec(ctx, query, args, v)
|
||||
}
|
||||
|
||||
func (d *multiDriver) Tx(ctx context.Context) (dialect.Tx, error) {
|
||||
return d.w.Tx(ctx)
|
||||
}
|
||||
|
||||
func (d *multiDriver) BeginTx(ctx context.Context, opts *sql.TxOptions) (dialect.Tx, error) {
|
||||
return d.w.(interface {
|
||||
BeginTx(context.Context, *sql.TxOptions) (dialect.Tx, error)
|
||||
}).BeginTx(ctx, opts)
|
||||
}
|
||||
|
||||
func (d *multiDriver) Close() error {
|
||||
rerr := d.r.Close()
|
||||
werr := d.w.Close()
|
||||
if rerr != nil {
|
||||
return rerr
|
||||
}
|
||||
if werr != nil {
|
||||
return werr
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
func (d *multiDriver) Dialect() string {
|
||||
return d.r.Dialect()
|
||||
}
|
||||
```
|
||||
|
||||
#### How to configure `json.Marshal` to inline the `edges` keys in the top level object?
|
||||
|
||||
To encode entities without the `edges` attribute, users can follow these two steps:
|
||||
|
||||
1. Omit the default `edges` tag generated by Ent.
|
||||
2. Extend the generated models with a custom MarshalJSON method.
|
||||
|
||||
These two steps can be automated using [codegen extensions](extension.md), and a full working example is available under
|
||||
the [examples/jsonencode](https://github.com/ent/ent/tree/master/examples/jsonencode) directory.
|
||||
|
||||
```go title="ent/entc.go" {17,28}
|
||||
//go:build ignore
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
"entgo.io/ent/schema/edge"
|
||||
)
|
||||
|
||||
func main() {
|
||||
opts := []entc.Option{
|
||||
entc.Extensions{
|
||||
&EncodeExtension{},
|
||||
),
|
||||
}
|
||||
err := entc.Generate("./schema", &gen.Config{}, opts...)
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
|
||||
// EncodeExtension is an implementation of entc.Extension that adds a MarshalJSON
|
||||
// method to each generated type <T> and inlines the Edges field to the top level JSON.
|
||||
type EncodeExtension struct {
|
||||
entc.DefaultExtension
|
||||
}
|
||||
|
||||
// Templates of the extension.
|
||||
func (e *EncodeExtension) Templates() []*gen.Template {
|
||||
return []*gen.Template{
|
||||
gen.MustParse(gen.NewTemplate("model/additional/jsonencode").
|
||||
Parse(`
|
||||
{{ if $.Edges }}
|
||||
// MarshalJSON implements the json.Marshaler interface.
|
||||
func ({{ $.Receiver }} *{{ $.Name }}) MarshalJSON() ([]byte, error) {
|
||||
type Alias {{ $.Name }}
|
||||
return json.Marshal(&struct {
|
||||
*Alias
|
||||
{{ $.Name }}Edges
|
||||
}{
|
||||
Alias: (*Alias)({{ $.Receiver }}),
|
||||
{{ $.Name }}Edges: {{ $.Receiver }}.Edges,
|
||||
})
|
||||
}
|
||||
{{ end }}
|
||||
`)),
|
||||
}
|
||||
}
|
||||
|
||||
// Hooks of the extension.
|
||||
func (e *EncodeExtension) Hooks() []gen.Hook {
|
||||
return []gen.Hook{
|
||||
func(next gen.Generator) gen.Generator {
|
||||
return gen.GenerateFunc(func(g *gen.Graph) error {
|
||||
tag := edge.Annotation{StructTag: `json:"-"`}
|
||||
for _, n := range g.Nodes {
|
||||
n.Annotations.Set(tag.Name(), tag)
|
||||
}
|
||||
return next.Generate(g)
|
||||
})
|
||||
},
|
||||
}
|
||||
}
|
||||
```
|
||||
436
doc/md/features.md
Normal file
436
doc/md/features.md
Normal file
@@ -0,0 +1,436 @@
|
||||
---
|
||||
id: feature-flags
|
||||
title: Feature Flags
|
||||
sidebar_label: Feature Flags
|
||||
---
|
||||
|
||||
The framework provides a collection of code-generation features that be added or removed using flags.
|
||||
|
||||
## Usage
|
||||
|
||||
Feature flags can be provided either by CLI flags or as arguments to the `gen` package.
|
||||
|
||||
#### CLI
|
||||
|
||||
```console
|
||||
go run -mod=mod entgo.io/ent/cmd/ent generate --feature privacy,entql ./ent/schema
|
||||
```
|
||||
|
||||
#### Go
|
||||
|
||||
```go
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
"text/template"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
)
|
||||
|
||||
func main() {
|
||||
err := entc.Generate("./schema", &gen.Config{
|
||||
Features: []gen.Feature{
|
||||
gen.FeaturePrivacy,
|
||||
gen.FeatureEntQL,
|
||||
},
|
||||
Templates: []*gen.Template{
|
||||
gen.MustParse(gen.NewTemplate("static").
|
||||
Funcs(template.FuncMap{"title": strings.ToTitle}).
|
||||
ParseFiles("template/static.tmpl")),
|
||||
},
|
||||
})
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## List of Features
|
||||
|
||||
### Auto-Solve Merge Conflicts
|
||||
|
||||
The `schema/snapshot` option tells `entc` (ent codegen) to store a snapshot of the latest schema in an internal package,
|
||||
and use it to automatically solve merge conflicts when user's schema can't be built.
|
||||
|
||||
This option can be added to a project using the `--feature schema/snapshot` flag, but please see
|
||||
[ent/ent/issues/852](https://github.com/ent/ent/issues/852) to get more context about it.
|
||||
|
||||
### Privacy Layer
|
||||
|
||||
The privacy layer allows configuring privacy policy for queries and mutations of entities in the database.
|
||||
|
||||
This option can be added to a project using the `--feature privacy` flag, and you can learn more about in the
|
||||
[privacy](privacy.mdx) documentation.
|
||||
|
||||
### EntQL Filtering
|
||||
|
||||
The `entql` option provides a generic and dynamic filtering capability at runtime for the different query builders.
|
||||
|
||||
This option can be added to a project using the `--feature entql` flag, and you can learn more about in the
|
||||
[privacy](privacy.mdx#multi-tenancy) documentation.
|
||||
|
||||
### Named Edges
|
||||
|
||||
The `namedges` option provides an API for preloading edges with custom names.
|
||||
|
||||
This option can be added to a project using the `--feature namedges` flag, and you can learn more about in the
|
||||
[Eager Loading](eager-load.mdx) documentation.
|
||||
|
||||
### Bidirectional Edge Refs
|
||||
|
||||
The `bidiedges` option guides Ent to set two-way references when eager-loading (O2M/O2O) edges.
|
||||
|
||||
This option can be added to a project using the `--feature bidiedges` flag.
|
||||
|
||||
:::note
|
||||
Users that use the standard encoding/json.MarshalJSON should detach the circular references before calling `json.Marshal`.
|
||||
:::
|
||||
|
||||
### Schema Config
|
||||
|
||||
The `sql/schemaconfig` option lets you pass alternate SQL database names to models. This is useful when your models don't all live under one database and are spread out across different schemas.
|
||||
|
||||
This option can be added to a project using the `--feature sql/schemaconfig` flag. Once you generate the code, you can now use a new option as such:
|
||||
|
||||
```go
|
||||
c, err := ent.Open(dialect, conn, ent.AlternateSchema(ent.SchemaConfig{
|
||||
User: "usersdb",
|
||||
Car: "carsdb",
|
||||
}))
|
||||
c.User.Query().All(ctx) // SELECT * FROM `usersdb`.`users`
|
||||
c.Car.Query().All(ctx) // SELECT * FROM `carsdb`.`cars`
|
||||
```
|
||||
|
||||
### Row-level Locks
|
||||
|
||||
The `sql/lock` option lets configure row-level locking using the SQL `SELECT ... FOR {UPDATE | SHARE}` syntax.
|
||||
|
||||
This option can be added to a project using the `--feature sql/lock` flag.
|
||||
|
||||
```go
|
||||
tx, err := client.Tx(ctx)
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
|
||||
tx.Pet.Query().
|
||||
Where(pet.Name(name)).
|
||||
ForUpdate().
|
||||
Only(ctx)
|
||||
|
||||
tx.Pet.Query().
|
||||
Where(pet.ID(id)).
|
||||
ForShare(
|
||||
sql.WithLockTables(pet.Table),
|
||||
sql.WithLockAction(sql.NoWait),
|
||||
).
|
||||
Only(ctx)
|
||||
```
|
||||
|
||||
### Custom SQL Modifiers
|
||||
|
||||
The `sql/modifier` option lets add custom SQL modifiers to the builders and mutate the statements before they are executed.
|
||||
|
||||
This option can be added to a project using the `--feature sql/modifier` flag.
|
||||
|
||||
#### Modify Example 1
|
||||
|
||||
```go
|
||||
client.Pet.
|
||||
Query().
|
||||
Modify(func(s *sql.Selector) {
|
||||
s.Select("SUM(LENGTH(name))")
|
||||
}).
|
||||
IntX(ctx)
|
||||
```
|
||||
|
||||
The above code will produce the following SQL query:
|
||||
|
||||
```sql
|
||||
SELECT SUM(LENGTH(name)) FROM `pet`
|
||||
```
|
||||
|
||||
#### Select and Scan Dynamic Values
|
||||
|
||||
If you work with SQL modifiers and need to scan dynamic values not present in your Ent schema definition, such as
|
||||
aggregation or custom ordering, you can apply `AppendSelect`/`AppendSelectAs` to the `sql.Selector`. You can later
|
||||
access their values using the `Value` method defined on each entity:
|
||||
|
||||
```go {6,11}
|
||||
const as = "name_length"
|
||||
|
||||
// Query the entity with the dynamic value.
|
||||
p := client.Pet.Query().
|
||||
Modify(func(s *sql.Selector) {
|
||||
s.AppendSelectAs("LENGTH(name)", as)
|
||||
}).
|
||||
FirstX(ctx)
|
||||
|
||||
// Read the value from the entity.
|
||||
n, err := p.Value(as)
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
fmt.Println("Name length: %d == %d", n, len(p.Name))
|
||||
```
|
||||
|
||||
#### Modify Example 2
|
||||
|
||||
```go
|
||||
var p1 []struct {
|
||||
ent.Pet
|
||||
NameLength int `sql:"length"`
|
||||
}
|
||||
|
||||
client.Pet.Query().
|
||||
Order(ent.Asc(pet.FieldID)).
|
||||
Modify(func(s *sql.Selector) {
|
||||
s.AppendSelect("LENGTH(name)")
|
||||
}).
|
||||
ScanX(ctx, &p1)
|
||||
```
|
||||
|
||||
The above code will produce the following SQL query:
|
||||
|
||||
```sql
|
||||
SELECT `pet`.*, LENGTH(name) FROM `pet` ORDER BY `pet`.`id` ASC
|
||||
```
|
||||
|
||||
#### Modify Example 3
|
||||
|
||||
```go
|
||||
var v []struct {
|
||||
Count int `json:"count"`
|
||||
Price int `json:"price"`
|
||||
CreatedAt time.Time `json:"created_at"`
|
||||
}
|
||||
|
||||
client.User.
|
||||
Query().
|
||||
Where(
|
||||
user.CreatedAtGT(x),
|
||||
user.CreatedAtLT(y),
|
||||
).
|
||||
Modify(func(s *sql.Selector) {
|
||||
s.Select(
|
||||
sql.As(sql.Count("*"), "count"),
|
||||
sql.As(sql.Sum("price"), "price"),
|
||||
sql.As("DATE(created_at)", "created_at"),
|
||||
).
|
||||
GroupBy("DATE(created_at)").
|
||||
OrderBy(sql.Desc("DATE(created_at)"))
|
||||
}).
|
||||
ScanX(ctx, &v)
|
||||
```
|
||||
|
||||
The above code will produce the following SQL query:
|
||||
|
||||
```sql
|
||||
SELECT
|
||||
COUNT(*) AS `count`,
|
||||
SUM(`price`) AS `price`,
|
||||
DATE(created_at) AS `created_at`
|
||||
FROM
|
||||
`users`
|
||||
WHERE
|
||||
`created_at` > x AND `created_at` < y
|
||||
GROUP BY
|
||||
DATE(created_at)
|
||||
ORDER BY
|
||||
DATE(created_at) DESC
|
||||
```
|
||||
|
||||
#### Modify Example 4
|
||||
|
||||
```go
|
||||
var gs []struct {
|
||||
ent.Group
|
||||
UsersCount int `sql:"users_count"`
|
||||
}
|
||||
|
||||
client.Group.Query().
|
||||
Order(ent.Asc(group.FieldID)).
|
||||
Modify(func(s *sql.Selector) {
|
||||
t := sql.Table(group.UsersTable)
|
||||
s.LeftJoin(t).
|
||||
On(
|
||||
s.C(group.FieldID),
|
||||
t.C(group.UsersPrimaryKey[1]),
|
||||
).
|
||||
// Append the "users_count" column to the selected columns.
|
||||
AppendSelect(
|
||||
sql.As(sql.Count(t.C(group.UsersPrimaryKey[1])), "users_count"),
|
||||
).
|
||||
GroupBy(s.C(group.FieldID))
|
||||
}).
|
||||
ScanX(ctx, &gs)
|
||||
```
|
||||
|
||||
The above code will produce the following SQL query:
|
||||
|
||||
```sql
|
||||
SELECT
|
||||
`groups`.*,
|
||||
COUNT(`t1`.`group_id`) AS `users_count`
|
||||
FROM
|
||||
`groups` LEFT JOIN `user_groups` AS `t1`
|
||||
ON
|
||||
`groups`.`id` = `t1`.`group_id`
|
||||
GROUP BY
|
||||
`groups`.`id`
|
||||
ORDER BY
|
||||
`groups`.`id` ASC
|
||||
```
|
||||
|
||||
|
||||
#### Modify Example 5
|
||||
|
||||
```go
|
||||
client.User.Update().
|
||||
Modify(func(s *sql.UpdateBuilder) {
|
||||
s.Set(user.FieldName, sql.Expr(fmt.Sprintf("UPPER(%s)", user.FieldName)))
|
||||
}).
|
||||
ExecX(ctx)
|
||||
```
|
||||
|
||||
The above code will produce the following SQL query:
|
||||
|
||||
```sql
|
||||
UPDATE `users` SET `name` = UPPER(`name`)
|
||||
```
|
||||
|
||||
#### Modify Example 6
|
||||
|
||||
```go
|
||||
client.User.Update().
|
||||
Modify(func(u *sql.UpdateBuilder) {
|
||||
u.Set(user.FieldID, sql.ExprFunc(func(b *sql.Builder) {
|
||||
b.Ident(user.FieldID).WriteOp(sql.OpAdd).Arg(1)
|
||||
}))
|
||||
u.OrderBy(sql.Desc(user.FieldID))
|
||||
}).
|
||||
ExecX(ctx)
|
||||
```
|
||||
|
||||
The above code will produce the following SQL query:
|
||||
|
||||
```sql
|
||||
UPDATE `users` SET `id` = `id` + 1 ORDER BY `id` DESC
|
||||
```
|
||||
|
||||
#### Modify Example 7
|
||||
|
||||
Append elements to the `values` array in a JSON column:
|
||||
|
||||
```go
|
||||
client.User.Update().
|
||||
Modify(func(u *sql.UpdateBuilder) {
|
||||
sqljson.Append(u, user.FieldTags, []string{"tag1", "tag2"}, sqljson.Path("values"))
|
||||
}).
|
||||
ExecX(ctx)
|
||||
```
|
||||
|
||||
The above code will produce the following SQL query:
|
||||
|
||||
```sql
|
||||
UPDATE `users` SET `tags` = CASE
|
||||
WHEN (JSON_TYPE(JSON_EXTRACT(`tags`, '$.values')) IS NULL OR JSON_TYPE(JSON_EXTRACT(`tags`, '$.values')) = 'NULL')
|
||||
THEN JSON_SET(`tags`, '$.values', JSON_ARRAY(?, ?))
|
||||
ELSE JSON_ARRAY_APPEND(`tags`, '$.values', ?, '$.values', ?) END
|
||||
WHERE `id` = ?
|
||||
```
|
||||
|
||||
### SQL Raw API
|
||||
|
||||
The `sql/execquery` option allows executing statements using the `ExecContext`/`QueryContext` methods of the underlying
|
||||
driver. For full documentation, see: [DB.ExecContext](https://pkg.go.dev/database/sql#DB.ExecContext), and
|
||||
[DB.QueryContext](https://pkg.go.dev/database/sql#DB.QueryContext).
|
||||
|
||||
```go
|
||||
// From ent.Client.
|
||||
if _, err := client.ExecContext(ctx, "TRUNCATE t1"); err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
// From ent.Tx.
|
||||
tx, err := client.Tx(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
if err := tx.User.Create().Exec(ctx); err != nil {
|
||||
return err
|
||||
}
|
||||
if _, err := tx.ExecContext("SAVEPOINT user_created"); err != nil {
|
||||
return err
|
||||
}
|
||||
// ...
|
||||
```
|
||||
|
||||
:::warning Note
|
||||
Statements executed using `ExecContext`/`QueryContext` do not go through Ent, and may skip fundamental layers in your
|
||||
application such as hooks, privacy (authorization), and validators.
|
||||
:::
|
||||
|
||||
### Upsert
|
||||
|
||||
The `sql/upsert` option lets configure upsert and bulk-upsert logic using the SQL `ON CONFLICT` / `ON DUPLICATE KEY`
|
||||
syntax. For full documentation, go to the [Upsert API](crud.mdx#upsert-one).
|
||||
|
||||
This option can be added to a project using the `--feature sql/upsert` flag.
|
||||
|
||||
```go
|
||||
// Use the new values that were set on create.
|
||||
id, err := client.User.
|
||||
Create().
|
||||
SetAge(30).
|
||||
SetName("Ariel").
|
||||
OnConflict().
|
||||
UpdateNewValues().
|
||||
ID(ctx)
|
||||
|
||||
// In PostgreSQL, the conflict target is required.
|
||||
err := client.User.
|
||||
Create().
|
||||
SetAge(30).
|
||||
SetName("Ariel").
|
||||
OnConflictColumns(user.FieldName).
|
||||
UpdateNewValues().
|
||||
Exec(ctx)
|
||||
|
||||
// Bulk upsert is also supported.
|
||||
client.User.
|
||||
CreateBulk(builders...).
|
||||
OnConflict(
|
||||
sql.ConflictWhere(...),
|
||||
sql.UpdateWhere(...),
|
||||
).
|
||||
UpdateNewValues().
|
||||
Exec(ctx)
|
||||
|
||||
// INSERT INTO "users" (...) VALUES ... ON CONFLICT WHERE ... DO UPDATE SET ... WHERE ...
|
||||
```
|
||||
|
||||
### Globally Unique ID
|
||||
|
||||
By default, SQL primary-keys start from 1 for each table; which means that multiple entities of different types
|
||||
can share the same ID. Unlike AWS Neptune, where node IDs are UUIDs.
|
||||
|
||||
This does not work well if you work with [GraphQL](https://graphql.org/learn/schema/#scalar-types), which requires
|
||||
the object ID to be unique.
|
||||
|
||||
To enable the Universal-IDs support for your project, simply use the `--feature sql/globalid` flag.
|
||||
|
||||
:::warning Note
|
||||
If you have used the `migrate.WithGlobalUniqueID(true)` migration option in the past, please read
|
||||
[this guide](globalid-migrate) before you switch your project to use the new globalid feature.
|
||||
:::
|
||||
|
||||
**How does it work?** `ent` migration allocates a 1<<32 range for the IDs of each entity (table),
|
||||
and store this information alongside your generated code (`internal/globalid.go`). For example, type `A` will have the
|
||||
range of `[1,4294967296)` for its IDs, and type `B` will have the range of `[4294967296,8589934592)`, etc.
|
||||
|
||||
Note that if this option is enabled, the maximum number of possible tables is **65535**.
|
||||
225
doc/md/generating-ent-schemas.md
Normal file
225
doc/md/generating-ent-schemas.md
Normal file
@@ -0,0 +1,225 @@
|
||||
---
|
||||
id: generating-ent-schemas
|
||||
title: Generating Schemas
|
||||
---
|
||||
|
||||
## Introduction
|
||||
|
||||
To facilitate the creation of tooling that generates `ent.Schema`s programmatically, `ent` supports the manipulation of
|
||||
the `schema/` directory using the `entgo.io/contrib/schemast` package.
|
||||
|
||||
## API
|
||||
|
||||
### Loading
|
||||
|
||||
In order to manipulate an existing schema directory we must first load it into a `schemast.Context` object:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"log"
|
||||
|
||||
"entgo.io/contrib/schemast"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ctx, err := schemast.Load("./ent/schema")
|
||||
if err != nil {
|
||||
log.Fatalf("failed: %v", err)
|
||||
}
|
||||
if ctx.HasType("user") {
|
||||
fmt.Println("schema directory contains a schema named User!")
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Printing
|
||||
|
||||
To print back out our context to a target directory, use `schemast.Print`:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/contrib/schemast"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ctx, err := schemast.Load("./ent/schema")
|
||||
if err != nil {
|
||||
log.Fatalf("failed: %v", err)
|
||||
}
|
||||
// A no-op since we did not manipulate the Context at all.
|
||||
if err := schemast.Print("./ent/schema"); err != nil {
|
||||
log.Fatalf("failed: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Mutators
|
||||
|
||||
To mutate the `ent/schema` directory, we can use `schemast.Mutate`, which takes a list of
|
||||
`schemast.Mutator`s to apply to the context:
|
||||
|
||||
```go
|
||||
package schemast
|
||||
|
||||
// Mutator changes a Context.
|
||||
type Mutator interface {
|
||||
Mutate(ctx *Context) error
|
||||
}
|
||||
```
|
||||
|
||||
Currently, only a single type of `schemast.Mutator` is implemented, `UpsertSchema`:
|
||||
|
||||
```go
|
||||
package schemast
|
||||
|
||||
// UpsertSchema implements Mutator. UpsertSchema will add to the Context the type named
|
||||
// Name if not present and rewrite the type's Fields, Edges, Indexes and Annotations methods.
|
||||
type UpsertSchema struct {
|
||||
Name string
|
||||
Fields []ent.Field
|
||||
Edges []ent.Edge
|
||||
Indexes []ent.Index
|
||||
Annotations []schema.Annotation
|
||||
}
|
||||
```
|
||||
|
||||
To use it:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/contrib/schemast"
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ctx, err := schemast.Load("./ent/schema")
|
||||
if err != nil {
|
||||
log.Fatalf("failed: %v", err)
|
||||
}
|
||||
mutations := []schemast.Mutator{
|
||||
&schemast.UpsertSchema{
|
||||
Name: "User",
|
||||
Fields: []ent.Field{
|
||||
field.String("name"),
|
||||
},
|
||||
},
|
||||
&schemast.UpsertSchema{
|
||||
Name: "Team",
|
||||
Fields: []ent.Field{
|
||||
field.String("name"),
|
||||
},
|
||||
},
|
||||
}
|
||||
err = schemast.Mutate(ctx, mutations...)
|
||||
if err := ctx.Print("./ent/schema"); err != nil {
|
||||
log.Fatalf("failed: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
After running this program, observe two new files exist in the schema directory: `user.go` and `team.go`:
|
||||
|
||||
```go
|
||||
// user.go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{field.String("name")}
|
||||
}
|
||||
func (User) Edges() []ent.Edge {
|
||||
return nil
|
||||
}
|
||||
func (User) Annotations() []schema.Annotation {
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
type Team struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (Team) Fields() []ent.Field {
|
||||
return []ent.Field{field.String("name")}
|
||||
}
|
||||
func (Team) Edges() []ent.Edge {
|
||||
return nil
|
||||
}
|
||||
func (Team) Annotations() []schema.Annotation {
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
### Working with Edges
|
||||
|
||||
Edges are defined in `ent` this way:
|
||||
|
||||
```go
|
||||
edge.To("edge_name", OtherSchema.Type)
|
||||
```
|
||||
|
||||
This syntax relies on the fact that the `OtherSchema` struct already exists when we define the edge so we can refer to
|
||||
its `Type` method. When we are generating schemas programmatically, obviously we need somehow to describe the edge to
|
||||
the code-generator before the type definitions exist. To do this you can do something like:
|
||||
|
||||
```go
|
||||
type placeholder struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func withType(e ent.Edge, typeName string) ent.Edge {
|
||||
e.Descriptor().Type = typeName
|
||||
return e
|
||||
}
|
||||
|
||||
func newEdgeTo(edgeName, otherType string) ent.Edge {
|
||||
// we pass a placeholder type to the edge constructor:
|
||||
e := edge.To(edgeName, placeholder.Type)
|
||||
// then we override the other type's name directly on the edge descriptor:
|
||||
return withType(e, otherType)
|
||||
}
|
||||
```
|
||||
|
||||
## Examples
|
||||
|
||||
The `protoc-gen-ent` ([doc](https://github.com/ent/contrib/tree/master/entproto/cmd/protoc-gen-ent)) is a protoc plugin
|
||||
that programmatically generates `ent.Schema`s from .proto files, it uses the `schemast` to manipulate the
|
||||
target `schema` directory. To see
|
||||
how, [read the source code](https://github.com/ent/contrib/blob/master/entproto/cmd/protoc-gen-ent/main.go#L34).
|
||||
|
||||
## Caveats
|
||||
|
||||
`schemast` is still experimental, APIs are subject to change in the future. In addition, a small portion of
|
||||
the `ent.Field` definition API is unsupported at this point in time, to see a full list of unsupported features see
|
||||
the [source code](https://github.com/ent/contrib/blob/aed7a43a3e54550c1dd9a1a066ce1236b4bae56c/schemast/field.go#L158).
|
||||
|
||||
701
doc/md/getting-started.mdx
Normal file
701
doc/md/getting-started.mdx
Normal file
@@ -0,0 +1,701 @@
|
||||
---
|
||||
id: getting-started
|
||||
title: Quick Introduction
|
||||
sidebar_label: Quick Introduction
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import AtlasMigrateDiff from './components/_atlas_migrate_diff.mdx';
|
||||
import AtlasMigrateApply from './components/_atlas_migrate_apply.mdx';
|
||||
import InstallationInstructions from './components/_installation_instructions.mdx';
|
||||
|
||||
**ent** is a simple, yet powerful entity framework for Go, that makes it easy to build
|
||||
and maintain applications with large data-models and sticks with the following principles:
|
||||
|
||||
- Easily model database schema as a graph structure.
|
||||
- Define schema as a programmatic Go code.
|
||||
- Static typing based on code generation.
|
||||
- Database queries and graph traversals are easy to write.
|
||||
- Simple to extend and customize using Go templates.
|
||||
|
||||

|
||||
|
||||
## Setup A Go Environment
|
||||
|
||||
If your project directory is outside [GOPATH](https://github.com/golang/go/wiki/GOPATH) or you are not familiar with
|
||||
GOPATH, setup a [Go module](https://github.com/golang/go/wiki/Modules#quick-start) project as follows:
|
||||
|
||||
```console
|
||||
go mod init entdemo
|
||||
```
|
||||
|
||||
## Create Your First Schema
|
||||
|
||||
Go to the root directory of your project, and run:
|
||||
|
||||
```console
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new User
|
||||
```
|
||||
|
||||
The command above will generate the schema for `User` under `entdemo/ent/schema/` directory:
|
||||
|
||||
```go title="entdemo/ent/schema/user.go"
|
||||
|
||||
package schema
|
||||
|
||||
import "entgo.io/ent"
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return nil
|
||||
}
|
||||
|
||||
// Edges of the User.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return nil
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
Add 2 fields to the `User` schema:
|
||||
|
||||
```go title="entdemo/ent/schema/user.go"
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Int("age").
|
||||
Positive(),
|
||||
field.String("name").
|
||||
Default("unknown"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Run `go generate` from the root directory of the project as follows:
|
||||
|
||||
```go
|
||||
go generate ./ent
|
||||
```
|
||||
|
||||
This produces the following files:
|
||||
```console {12-20}
|
||||
ent
|
||||
├── client.go
|
||||
├── config.go
|
||||
├── context.go
|
||||
├── ent.go
|
||||
├── generate.go
|
||||
├── mutation.go
|
||||
... truncated
|
||||
├── schema
|
||||
│ └── user.go
|
||||
├── tx.go
|
||||
├── user
|
||||
│ ├── user.go
|
||||
│ └── where.go
|
||||
├── user.go
|
||||
├── user_create.go
|
||||
├── user_delete.go
|
||||
├── user_query.go
|
||||
└── user_update.go
|
||||
```
|
||||
|
||||
|
||||
## Create Your First Entity
|
||||
|
||||
To get started, create a new `Client` to run schema migration and interact with your entities:
|
||||
|
||||
<Tabs
|
||||
defaultValue="sqlite"
|
||||
values={[
|
||||
{label: 'SQLite', value: 'sqlite'},
|
||||
{label: 'PostgreSQL', value: 'postgres'},
|
||||
{label: 'MySQL (MariaDB)', value: 'mysql'},
|
||||
]}>
|
||||
<TabItem value="sqlite">
|
||||
|
||||
```go title="entdemo/start.go"
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"entdemo/ent"
|
||||
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to sqlite: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
// Run the auto migration tool.
|
||||
// highlight-start
|
||||
if err := client.Schema.Create(context.Background()); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
// highlight-end
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="postgres">
|
||||
|
||||
```go title="entdemo/start.go"
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"entdemo/ent"
|
||||
|
||||
_ "github.com/lib/pq"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("postgres","host=<host> port=<port> user=<user> dbname=<database> password=<pass>")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to postgres: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
// Run the auto migration tool.
|
||||
// highlight-start
|
||||
if err := client.Schema.Create(context.Background()); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
// highlight-end
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```go title="entdemo/start.go"
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"entdemo/ent"
|
||||
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "<user>:<pass>@tcp(<host>:<port>)/<database>?parseTime=True")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
// Run the auto migration tool.
|
||||
// highlight-start
|
||||
if err := client.Schema.Create(context.Background()); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
// highlight-end
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
After running schema migration, we're ready to create our user. For the sake of this example, let's name this function
|
||||
_CreateUser_:
|
||||
|
||||
```go title="entdemo/start.go"
|
||||
func CreateUser(ctx context.Context, client *ent.Client) (*ent.User, error) {
|
||||
u, err := client.User.
|
||||
Create().
|
||||
SetAge(30).
|
||||
SetName("a8m").
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("failed creating user: %w", err)
|
||||
}
|
||||
log.Println("user was created: ", u)
|
||||
return u, nil
|
||||
}
|
||||
```
|
||||
|
||||
## Query Your Entities
|
||||
|
||||
`ent` generates a package for each entity schema that contains its predicates, default values, validators
|
||||
and additional information about storage elements (column names, primary keys, etc).
|
||||
|
||||
```go title="entdemo/start.go"
|
||||
func QueryUser(ctx context.Context, client *ent.Client) (*ent.User, error) {
|
||||
u, err := client.User.
|
||||
Query().
|
||||
Where(user.Name("a8m")).
|
||||
// `Only` fails if no user found,
|
||||
// or more than 1 user returned.
|
||||
Only(ctx)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("failed querying user: %w", err)
|
||||
}
|
||||
log.Println("user returned: ", u)
|
||||
return u, nil
|
||||
}
|
||||
```
|
||||
|
||||
|
||||
## Add Your First Edge (Relation)
|
||||
|
||||
In this part of the tutorial, we want to declare an edge (relation) to another entity in the schema.
|
||||
Let's create 2 additional entities named `Car` and `Group` with a few fields. We use `ent` CLI
|
||||
to generate the initial schemas:
|
||||
|
||||
```console
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new Car Group
|
||||
```
|
||||
|
||||
And then we add the rest of the fields manually:
|
||||
|
||||
```go title="entdemo/ent/schema/car.go"
|
||||
// Fields of the Car.
|
||||
func (Car) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("model"),
|
||||
field.Time("registered_at"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```go title="entdemo/ent/schema/group.go"
|
||||
// Fields of the Group.
|
||||
func (Group) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
// Regexp validation for group name.
|
||||
Match(regexp.MustCompile("[a-zA-Z_]+$")),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Let's define our first relation. An edge from `User` to `Car` defining that a user
|
||||
can **have 1 or more** cars, but a car **has only one** owner (one-to-many relation).
|
||||
|
||||

|
||||
|
||||
Let's add the `"cars"` edge to the `User` schema, and run `go generate ./ent`:
|
||||
|
||||
```go title="entdemo/ent/schema/user.go"
|
||||
// Edges of the User.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("cars", Car.Type),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
We continue our example by creating 2 cars and adding them to a user.
|
||||
|
||||
```go title="entdemo/start.go"
|
||||
func CreateCars(ctx context.Context, client *ent.Client) (*ent.User, error) {
|
||||
// Create a new car with model "Tesla".
|
||||
tesla, err := client.Car.
|
||||
Create().
|
||||
SetModel("Tesla").
|
||||
SetRegisteredAt(time.Now()).
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("failed creating car: %w", err)
|
||||
}
|
||||
log.Println("car was created: ", tesla)
|
||||
|
||||
// Create a new car with model "Ford".
|
||||
ford, err := client.Car.
|
||||
Create().
|
||||
SetModel("Ford").
|
||||
SetRegisteredAt(time.Now()).
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("failed creating car: %w", err)
|
||||
}
|
||||
log.Println("car was created: ", ford)
|
||||
|
||||
// Create a new user, and add it the 2 cars.
|
||||
a8m, err := client.User.
|
||||
Create().
|
||||
SetAge(30).
|
||||
SetName("a8m").
|
||||
AddCars(tesla, ford).
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("failed creating user: %w", err)
|
||||
}
|
||||
log.Println("user was created: ", a8m)
|
||||
return a8m, nil
|
||||
}
|
||||
```
|
||||
But what about querying the `cars` edge (relation)? Here's how we do it:
|
||||
|
||||
```go title="entdemo/start.go"
|
||||
func QueryCars(ctx context.Context, a8m *ent.User) error {
|
||||
cars, err := a8m.QueryCars().All(ctx)
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed querying user cars: %w", err)
|
||||
}
|
||||
log.Println("returned cars:", cars)
|
||||
|
||||
// What about filtering specific cars.
|
||||
ford, err := a8m.QueryCars().
|
||||
Where(car.Model("Ford")).
|
||||
Only(ctx)
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed querying user cars: %w", err)
|
||||
}
|
||||
log.Println(ford)
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
## Add Your First Inverse Edge (BackRef)
|
||||
Assume we have a `Car` object and we want to get its owner; the user that this car belongs to.
|
||||
For this, we have another type of edge called "inverse edge" that is defined using the `edge.From`
|
||||
function.
|
||||
|
||||

|
||||
|
||||
The new edge created in the diagram above is translucent, to emphasize that we don't create another
|
||||
edge in the database. It's just a back-reference to the real edge (relation).
|
||||
|
||||
Let's add an inverse edge named `owner` to the `Car` schema, reference it to the `cars` edge
|
||||
in the `User` schema, and run `go generate ./ent`.
|
||||
|
||||
```go title="entdemo/ent/schema/car.go"
|
||||
// Edges of the Car.
|
||||
func (Car) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
// Create an inverse-edge called "owner" of type `User`
|
||||
// and reference it to the "cars" edge (in User schema)
|
||||
// explicitly using the `Ref` method.
|
||||
edge.From("owner", User.Type).
|
||||
Ref("cars").
|
||||
// setting the edge to unique, ensure
|
||||
// that a car can have only one owner.
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
We'll continue the user/cars example above by querying the inverse edge.
|
||||
|
||||
```go title="entdemo/start.go"
|
||||
func QueryCarUsers(ctx context.Context, a8m *ent.User) error {
|
||||
cars, err := a8m.QueryCars().All(ctx)
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed querying user cars: %w", err)
|
||||
}
|
||||
// Query the inverse edge.
|
||||
for _, c := range cars {
|
||||
owner, err := c.QueryOwner().Only(ctx)
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed querying car %q owner: %w", c.Model, err)
|
||||
}
|
||||
log.Printf("car %q owner: %q\n", c.Model, owner.Name)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
## Visualize the Schema
|
||||
|
||||
If you have reached this point, you have successfully executed the schema migration and created several entities in the
|
||||
database. To view the SQL schema generated by Ent for the database, install [Atlas](https://github.com/ariga/atlas)
|
||||
and run the following command:
|
||||
|
||||
#### Install Atlas
|
||||
|
||||
<InstallationInstructions />
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ERD Schema">
|
||||
|
||||
#### Inspect The Ent Schema
|
||||
|
||||
```bash
|
||||
atlas schema inspect \
|
||||
-u "ent://ent/schema" \
|
||||
--dev-url "sqlite://file?mode=memory&_fk=1" \
|
||||
-w
|
||||
```
|
||||
|
||||
#### ERD and SQL Schema
|
||||
|
||||
[](https://gh.atlasgo.cloud/explore/40d83919)
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="SQL Schema">
|
||||
|
||||
#### Inspect The Ent Schema
|
||||
|
||||
```bash
|
||||
atlas schema inspect \
|
||||
-u "ent://ent/schema" \
|
||||
--dev-url "sqlite://file?mode=memory&_fk=1" \
|
||||
--format '{{ sql . " " }}'
|
||||
```
|
||||
|
||||
#### SQL Output
|
||||
|
||||
```sql
|
||||
-- Create "cars" table
|
||||
CREATE TABLE `cars` (
|
||||
`id` integer NOT NULL PRIMARY KEY AUTOINCREMENT,
|
||||
`model` text NOT NULL,
|
||||
`registered_at` datetime NOT NULL,
|
||||
`user_cars` integer NULL,
|
||||
CONSTRAINT `cars_users_cars` FOREIGN KEY (`user_cars`) REFERENCES `users` (`id`) ON DELETE SET NULL
|
||||
);
|
||||
|
||||
-- Create "users" table
|
||||
CREATE TABLE `users` (
|
||||
`id` integer NOT NULL PRIMARY KEY AUTOINCREMENT,
|
||||
`age` integer NOT NULL,
|
||||
`name` text NOT NULL DEFAULT 'unknown'
|
||||
);
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Create Your Second Edge
|
||||
|
||||
We'll continue our example by creating a M2M (many-to-many) relationship between users and groups.
|
||||
|
||||

|
||||
|
||||
As you can see, each group entity can **have many** users, and a user can **be connected to many** groups;
|
||||
a simple "many-to-many" relationship. In the above illustration, the `Group` schema is the owner
|
||||
of the `users` edge (relation), and the `User` entity has a back-reference/inverse edge to this
|
||||
relationship named `groups`. Let's define this relationship in our schemas:
|
||||
|
||||
```go title="entdemo/ent/schema/group.go"
|
||||
// Edges of the Group.
|
||||
func (Group) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("users", User.Type),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```go title="entdemo/ent/schema/user.go"
|
||||
// Edges of the User.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("cars", Car.Type),
|
||||
// Create an inverse-edge called "groups" of type `Group`
|
||||
// and reference it to the "users" edge (in Group schema)
|
||||
// explicitly using the `Ref` method.
|
||||
edge.From("groups", Group.Type).
|
||||
Ref("users"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
We run `ent` on the schema directory to re-generate the assets.
|
||||
```console
|
||||
go generate ./ent
|
||||
```
|
||||
|
||||
## Run Your First Graph Traversal
|
||||
|
||||
In order to run our first graph traversal, we need to generate some data (nodes and edges, or in other words,
|
||||
entities and relations). Let's create the following graph using the framework:
|
||||
|
||||

|
||||
|
||||
|
||||
```go title="entdemo/start.go"
|
||||
func CreateGraph(ctx context.Context, client *ent.Client) error {
|
||||
// First, create the users.
|
||||
a8m, err := client.User.
|
||||
Create().
|
||||
SetAge(30).
|
||||
SetName("Ariel").
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
neta, err := client.User.
|
||||
Create().
|
||||
SetAge(28).
|
||||
SetName("Neta").
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
// Then, create the cars, and attach them to the users created above.
|
||||
err = client.Car.
|
||||
Create().
|
||||
SetModel("Tesla").
|
||||
SetRegisteredAt(time.Now()).
|
||||
// Attach this car to Ariel.
|
||||
SetOwner(a8m).
|
||||
Exec(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
err = client.Car.
|
||||
Create().
|
||||
SetModel("Mazda").
|
||||
SetRegisteredAt(time.Now()).
|
||||
// Attach this car to Ariel.
|
||||
SetOwner(a8m).
|
||||
Exec(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
err = client.Car.
|
||||
Create().
|
||||
SetModel("Ford").
|
||||
SetRegisteredAt(time.Now()).
|
||||
// Attach this car to Neta.
|
||||
SetOwner(neta).
|
||||
Exec(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
// Create the groups, and add their users in the creation.
|
||||
err = client.Group.
|
||||
Create().
|
||||
SetName("GitLab").
|
||||
AddUsers(neta, a8m).
|
||||
Exec(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
err = client.Group.
|
||||
Create().
|
||||
SetName("GitHub").
|
||||
AddUsers(a8m).
|
||||
Exec(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
log.Println("The graph was created successfully")
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
Now when we have a graph with data, we can run a few queries on it:
|
||||
|
||||
1. Get all user's cars within the group named "GitHub":
|
||||
|
||||
```go title="entdemo/start.go"
|
||||
func QueryGithub(ctx context.Context, client *ent.Client) error {
|
||||
cars, err := client.Group.
|
||||
Query().
|
||||
Where(group.Name("GitHub")). // (Group(Name=GitHub),)
|
||||
QueryUsers(). // (User(Name=Ariel, Age=30),)
|
||||
QueryCars(). // (Car(Model=Tesla, RegisteredAt=<Time>), Car(Model=Mazda, RegisteredAt=<Time>),)
|
||||
All(ctx)
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed getting cars: %w", err)
|
||||
}
|
||||
log.Println("cars returned:", cars)
|
||||
// Output: (Car(Model=Tesla, RegisteredAt=<Time>), Car(Model=Mazda, RegisteredAt=<Time>),)
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
2. Change the query above, so that the source of the traversal is the user *Ariel*:
|
||||
|
||||
```go title="entdemo/start.go"
|
||||
func QueryArielCars(ctx context.Context, client *ent.Client) error {
|
||||
// Get "Ariel" from previous steps.
|
||||
a8m := client.User.
|
||||
Query().
|
||||
Where(
|
||||
user.HasCars(),
|
||||
user.Name("Ariel"),
|
||||
).
|
||||
OnlyX(ctx)
|
||||
cars, err := a8m. // Get the groups, that a8m is connected to:
|
||||
QueryGroups(). // (Group(Name=GitHub), Group(Name=GitLab),)
|
||||
QueryUsers(). // (User(Name=Ariel, Age=30), User(Name=Neta, Age=28),)
|
||||
QueryCars(). //
|
||||
Where( //
|
||||
car.Not( // Get Neta and Ariel cars, but filter out
|
||||
car.Model("Mazda"), // those who named "Mazda"
|
||||
), //
|
||||
). //
|
||||
All(ctx)
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed getting cars: %w", err)
|
||||
}
|
||||
log.Println("cars returned:", cars)
|
||||
// Output: (Car(Model=Tesla, RegisteredAt=<Time>), Car(Model=Ford, RegisteredAt=<Time>),)
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
3. Get all groups that have users (query with a look-aside predicate):
|
||||
|
||||
```go title="entdemo/start.go"
|
||||
func QueryGroupWithUsers(ctx context.Context, client *ent.Client) error {
|
||||
groups, err := client.Group.
|
||||
Query().
|
||||
Where(group.HasUsers()).
|
||||
All(ctx)
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed getting groups: %w", err)
|
||||
}
|
||||
log.Println("groups returned:", groups)
|
||||
// Output: (Group(Name=GitHub), Group(Name=GitLab),)
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
## Schema Migration
|
||||
|
||||
Ent provides two approaches for running schema migrations: [Automatic Migrations](/docs/migrate) and
|
||||
[Versioned migrations](/docs/versioned-migrations). Here is a brief overview of each approach:
|
||||
|
||||
### Automatic Migrations
|
||||
|
||||
With Automatic Migrations, users can use the following API to keep the database schema aligned with the schema objects
|
||||
defined in the generated SQL schema `ent/migrate/schema.go`:
|
||||
```go
|
||||
if err := client.Schema.Create(ctx); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
```
|
||||
|
||||
This approach is mostly useful for prototyping, development, or testing. Therefore, it is recommended to use the
|
||||
_Versioned Migration_ approach for mission-critical production environments. By using versioned migrations, users know
|
||||
beforehand what changes are being applied to their database, and can easily tune them depending on their needs.
|
||||
|
||||
Read more about this approach in the [Automatic Migration](/docs/migrate) documentation.
|
||||
|
||||
### Versioned Migrations
|
||||
|
||||
Unlike _Automatic Migrations_, the _Version Migrations_ approach uses Atlas to automatically generate a set of migration
|
||||
files containing the necessary SQL statements to migrate the database. These files can be edited to meet specific needs
|
||||
and applied using existing migration tools like Atlas, golang-migrate, Flyway, and Liquibase. The API for this approach
|
||||
involves two primary steps.
|
||||
|
||||
#### Generating migrations
|
||||
|
||||
<AtlasMigrateDiff/>
|
||||
|
||||
#### Applying migrations
|
||||
|
||||
<AtlasMigrateApply/>
|
||||
|
||||
Read more about this approach in the [Versioned Migrations](/docs/versioned-migrations) documentation.
|
||||
|
||||
## Full Example
|
||||
|
||||
The full example exists in [GitHub](https://github.com/ent/ent/tree/master/examples/start).
|
||||
170
doc/md/globalid.mdx
Normal file
170
doc/md/globalid.mdx
Normal file
@@ -0,0 +1,170 @@
|
||||
---
|
||||
id: globalid-migrate
|
||||
title: Migrate Globally Unique ID
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
Prior to the baked-in global id feature flag, the migration tool had a `WithGlobalUniqueID` option that allowed users to
|
||||
migrate their schema to use globally unique ids. This option is now deprecated and users should use the global id
|
||||
feature flag instead. Existing users can migrate their schema to use globally unique ids by following the steps below.
|
||||
|
||||
The previous solution utilized a table called `ent_types` to store mapping information between an Ent schema, and it's
|
||||
associated id range. The new solution uses a static configuration file to store this mapping. In order to migrate to the
|
||||
new globalid feature, one can use the `entfix` command to migrate an existing `ent_types` table to the new configuration
|
||||
file.
|
||||
|
||||
:::warning Attention
|
||||
Please note, that the 'ent_types' table might differ between different environments where your app is deployed. This is
|
||||
especially true if you are using auto-migration instead of versioned migrations. Please check, that all 'ent_types'
|
||||
tables for all deployments are equal. If they aren't you cannot convert to the new global id feature.
|
||||
:::
|
||||
|
||||
The first step is to install the `entfix` tool by running the following command:
|
||||
|
||||
```shell
|
||||
go install entgo.io/ent/cmd/entfix@latest
|
||||
```
|
||||
|
||||
Next, you can run the `entfix globalid` command to migrate your schema to use the global id feature. The command
|
||||
requires access to a database to read the `ent_types` table. You can either connect to your deployed database, or
|
||||
connect to a read replica or in case of versioned migrations, to an ephemeral database where you have applied all your
|
||||
migrations.
|
||||
|
||||
```shell
|
||||
entfix globalid --dialect mysql --dsn "root:pass@tcp(localhost:3306)/app" --path ./ent
|
||||
IMPORTANT INFORMATION
|
||||
|
||||
'entfix globalid' will convert the allocated id ranges for your nodes from the
|
||||
database stored 'ent_types' table to the new static configuration on the ent
|
||||
schema itself.
|
||||
|
||||
Please note, that the 'ent_types' table might differ between different environments
|
||||
where your app is deployed. This is especially true if you are using
|
||||
auto-migration instead of versioned migrations.
|
||||
|
||||
Please check, that all 'ent_types' tables for all deployments are equal!
|
||||
|
||||
Only 'yes' will be accepted to approve.
|
||||
|
||||
Enter a value: yes
|
||||
|
||||
Success! Please run code generation to complete the process.
|
||||
```
|
||||
|
||||
Finish the migration by running once again the code generation once. You should see a new file `internal/globalid.go`
|
||||
in the generated code, containing just one line starting with `const IncrementStarts`, indicating the process finished
|
||||
successfully. Last step is to make sure to remove the `migrate.WithGlobalUniqueID(true)` option from your migration
|
||||
setup.
|
||||
|
||||
# Optional: Keep `ent_types` table
|
||||
|
||||
It might be desired to keep the `ent_types` in the database and not drop it until you are sure you do not need to
|
||||
rollback compute. You can do this by using an Atlas composite schema:
|
||||
|
||||
<Tabs
|
||||
defaultValue="schema"
|
||||
values={[
|
||||
{label: 'schema.my.sql', value: 'schema'},
|
||||
{label: 'atlas-hcl', value: 'atlas'},
|
||||
]}>
|
||||
<TabItem value="schema">
|
||||
|
||||
```hcl
|
||||
schema "ent" {}
|
||||
|
||||
table "ent_types" {
|
||||
schema = schema.ent
|
||||
collate = "utf8mb4_bin"
|
||||
column "id" {
|
||||
null = false
|
||||
type = bigint
|
||||
unsigned = true
|
||||
auto_increment = true
|
||||
}
|
||||
column "type" {
|
||||
null = false
|
||||
type = varchar(255)
|
||||
}
|
||||
primary_key {
|
||||
columns = [column.id]
|
||||
}
|
||||
index "type" {
|
||||
unique = true
|
||||
columns = [column.type]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="atlas">
|
||||
|
||||
```hcl
|
||||
data "composite_schema" "ent" {
|
||||
schema "ent" {
|
||||
url = "ent://./ent/schema?globalid=static"
|
||||
}
|
||||
# This exists to not delete the ent_types table yet.
|
||||
schema "ent" {
|
||||
url = "file://./schema.my.hcl"
|
||||
}
|
||||
}
|
||||
|
||||
env {
|
||||
name = atlas.env
|
||||
src = data.composite_schema.ent.url
|
||||
dev = "docker://mysql/8/ent"
|
||||
migration {
|
||||
dir = "file://./ent/migrate/migrations"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Universal IDs (deprecated migration option)
|
||||
|
||||
By default, SQL primary-keys start from 1 for each table; which means that multiple entities of different types
|
||||
can share the same ID. Unlike AWS Neptune, where node IDs are UUIDs.
|
||||
|
||||
This does not work well if you work with [GraphQL](https://graphql.org/learn/schema/#scalar-types), which requires the object ID to be unique.
|
||||
|
||||
To enable the Universal-IDs support for your project, pass the `WithGlobalUniqueID` option to the migration.
|
||||
|
||||
:::note
|
||||
Versioned-migration users should follow [the documentation](versioned-migrations.mdx#a-word-on-global-unique-ids)
|
||||
when using `WithGlobalUniqueID` on MySQL 5.*.
|
||||
:::
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/migrate"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Run migration.
|
||||
if err := client.Schema.Create(ctx, migrate.WithGlobalUniqueID(true)); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**How does it work?** `ent` migration allocates a 1<<32 range for the IDs of each entity (table),
|
||||
and store this information in a table named `ent_types`. For example, type `A` will have the range
|
||||
of `[1,4294967296)` for its IDs, and type `B` will have the range of `[4294967296,8589934592)`, etc.
|
||||
|
||||
Note that if this option is enabled, the maximum number of possible tables is **65535**.
|
||||
373
doc/md/graphql.md
Normal file
373
doc/md/graphql.md
Normal file
@@ -0,0 +1,373 @@
|
||||
---
|
||||
id: graphql
|
||||
title: GraphQL Integration
|
||||
---
|
||||
|
||||
The Ent framework supports GraphQL using the [99designs/gqlgen](https://github.com/99designs/gqlgen) library and
|
||||
provides various integrations, such as:
|
||||
1. Generating a GraphQL schema for nodes and edges defined in an Ent schema.
|
||||
2. Auto-generated `Query` and `Mutation` resolvers and provide seamless integration with the [Relay framework](https://relay.dev/).
|
||||
3. Filtering, pagination (including nested) and compliant support with the [Relay Cursor Connections Spec](https://relay.dev/graphql/connections.htm).
|
||||
4. Efficient [field collection](tutorial-todo-gql-field-collection.md) to overcome the N+1 problem without requiring data
|
||||
loaders.
|
||||
5. [Transactional mutations](tutorial-todo-gql-tx-mutation.md) to ensure consistency in case of failures.
|
||||
|
||||
Check out the website's [GraphQL tutorial](tutorial-todo-gql.mdx#basic-setup) for more information.
|
||||
|
||||
|
||||
## Quick Introduction
|
||||
|
||||
In order to enable the [`entgql`](https://github.com/ent/contrib/tree/master/entgql) extension to your
|
||||
project, you need to use the `entc` (ent codegen) package as described [here](code-gen.md#use-entc-as-a-package).
|
||||
Follow these 3 steps to enable it to your project:
|
||||
|
||||
1\. Create a new Go file named `ent/entc.go`, and paste the following content:
|
||||
|
||||
```go title="ent/entc.go"
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
"entgo.io/contrib/entgql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ex, err := entgql.NewExtension()
|
||||
if err != nil {
|
||||
log.Fatalf("creating entgql extension: %v", err)
|
||||
}
|
||||
if err := entc.Generate("./schema", &gen.Config{}, entc.Extensions(ex)); err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
2\. Edit the `ent/generate.go` file to execute the `ent/entc.go` file:
|
||||
|
||||
```go title="ent/generate.go"
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entc.go
|
||||
```
|
||||
|
||||
Note that `ent/entc.go` is ignored using a build tag, and it's executed by the `go generate` command
|
||||
through the `generate.go` file. The full example can be found in the [ent/contrib repository](https://github.com/ent/contrib/blob/master/entgql/internal/todo).
|
||||
|
||||
|
||||
3\. Run codegen for your ent project:
|
||||
|
||||
```console
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
After running codegen, the following add-ons will be added to your project.
|
||||
|
||||
## Node API
|
||||
|
||||
A new file named `ent/gql_node.go` was created that implements the [Relay Node interface](https://relay.dev/graphql/objectidentification.htm).
|
||||
|
||||
In order to use the new generated `ent.Noder` interface in the [GraphQL resolver](https://gqlgen.com/reference/resolvers/),
|
||||
add the `Node` method to the query resolver, and look at the [configuration](#gql-configuration) section to understand
|
||||
how to use it.
|
||||
|
||||
If you are using the [Universal IDs](migrate.md#universal-ids) option in the schema migration, the NodeType is derived
|
||||
from the id value and can be used as follows:
|
||||
|
||||
```go
|
||||
func (r *queryResolver) Node(ctx context.Context, id int) (ent.Noder, error) {
|
||||
return r.client.Noder(ctx, id)
|
||||
}
|
||||
```
|
||||
|
||||
However, if you use a custom format for the global unique identifiers, you can control the NodeType as follows:
|
||||
|
||||
```go
|
||||
func (r *queryResolver) Node(ctx context.Context, guid string) (ent.Noder, error) {
|
||||
typ, id := parseGUID(guid)
|
||||
return r.client.Noder(ctx, id, ent.WithFixedNodeType(typ))
|
||||
}
|
||||
```
|
||||
|
||||
|
||||
## GQL Configuration
|
||||
|
||||
Here's a configuration example for a todo app as exists in [ent/contrib/entgql/todo](https://github.com/ent/contrib/tree/master/entgql/internal/todo).
|
||||
|
||||
```yaml
|
||||
schema:
|
||||
- todo.graphql
|
||||
|
||||
resolver:
|
||||
# Tell gqlgen to generate resolvers next to the schema file.
|
||||
layout: follow-schema
|
||||
dir: .
|
||||
|
||||
# gqlgen will search for any type names in the schema in the generated
|
||||
# ent package. If they match it will use them, otherwise it will new ones.
|
||||
autobind:
|
||||
- entgo.io/contrib/entgql/internal/todo/ent
|
||||
|
||||
models:
|
||||
ID:
|
||||
model:
|
||||
- github.com/99designs/gqlgen/graphql.IntID
|
||||
Node:
|
||||
model:
|
||||
# ent.Noder is the new interface generated by the Node template.
|
||||
- entgo.io/contrib/entgql/internal/todo/ent.Noder
|
||||
```
|
||||
|
||||
## Pagination
|
||||
|
||||
The pagination template adds a pagination support according to the _Relay Cursor Connections Spec_. More info
|
||||
about the Relay Spec can be found in its [website](https://relay.dev/graphql/connections.htm).
|
||||
|
||||
## Connection Ordering
|
||||
|
||||
The ordering option allows us to apply an ordering on the edges returned from a connection.
|
||||
|
||||
### Usage Notes
|
||||
|
||||
- The generated types will be `autobind`ed to GraphQL types if a naming convention is preserved (see example below).
|
||||
- Ordering fields should normally be [indexed](schema-indexes.md) to avoid full table DB scan.
|
||||
- Pagination queries can be sorted by a single field (no order by ... then by ... semantics).
|
||||
|
||||
### Example
|
||||
|
||||
Let's go over the steps needed in order to add ordering to an existing GraphQL type.
|
||||
The code example is based on a todo-app that can be found in [ent/contrib/entql/todo](https://github.com/ent/contrib/tree/master/entgql/internal/todo).
|
||||
|
||||
### Defining order fields in ent/schema
|
||||
|
||||
Ordering can be defined on any comparable field of ent by annotating it with `entgql.Annotation`.
|
||||
Note that the given `OrderField` name must match its enum value in graphql schema.
|
||||
```go
|
||||
func (Todo) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Time("created_at").
|
||||
Default(time.Now).
|
||||
Immutable().
|
||||
Annotations(
|
||||
entgql.OrderField("CREATED_AT"),
|
||||
),
|
||||
field.Enum("status").
|
||||
NamedValues(
|
||||
"InProgress", "IN_PROGRESS",
|
||||
"Completed", "COMPLETED",
|
||||
).
|
||||
Annotations(
|
||||
entgql.OrderField("STATUS"),
|
||||
),
|
||||
field.Int("priority").
|
||||
Default(0).
|
||||
Annotations(
|
||||
entgql.OrderField("PRIORITY"),
|
||||
),
|
||||
field.Text("text").
|
||||
NotEmpty().
|
||||
Annotations(
|
||||
entgql.OrderField("TEXT"),
|
||||
),
|
||||
}
|
||||
}
|
||||
```
|
||||
That's all the schema changes required, make sure to run `go generate` to apply them.
|
||||
|
||||
### Define ordering types in GraphQL schema
|
||||
|
||||
Next we need to define the ordering types in graphql schema:
|
||||
```graphql
|
||||
enum OrderDirection {
|
||||
ASC
|
||||
DESC
|
||||
}
|
||||
|
||||
enum TodoOrderField {
|
||||
CREATED_AT
|
||||
PRIORITY
|
||||
STATUS
|
||||
TEXT
|
||||
}
|
||||
|
||||
input TodoOrder {
|
||||
direction: OrderDirection!
|
||||
field: TodoOrderField
|
||||
}
|
||||
```
|
||||
Note that the naming must take the form of `<T>OrderField` / `<T>Order` for `autobind`ing to the generated ent types.
|
||||
Alternatively [@goModel](https://gqlgen.com/config/#inline-config-with-directives) directive can be used for manual type binding.
|
||||
|
||||
### Adding orderBy argument to the pagination query
|
||||
```graphql
|
||||
type Query {
|
||||
todos(
|
||||
after: Cursor
|
||||
first: Int
|
||||
before: Cursor
|
||||
last: Int
|
||||
orderBy: TodoOrder
|
||||
): TodoConnection!
|
||||
}
|
||||
```
|
||||
That's all for the GraphQL schema changes, let's run `gqlgen` code generation.
|
||||
|
||||
### Update the underlying resolver
|
||||
|
||||
Head over to the Todo resolver and update it to pass `orderBy` argument to `.Paginate()` call:
|
||||
|
||||
```go
|
||||
func (r *queryResolver) Todos(ctx context.Context, after *ent.Cursor, first *int, before *ent.Cursor, last *int, orderBy *ent.TodoOrder) (*ent.TodoConnection, error) {
|
||||
return r.client.Todo.Query().
|
||||
Paginate(ctx, after, first, before, last,
|
||||
ent.WithTodoOrder(orderBy),
|
||||
)
|
||||
}
|
||||
```
|
||||
|
||||
### Use in GraphQL
|
||||
|
||||
```graphql
|
||||
query {
|
||||
todos(first: 3, orderBy: {direction: DESC, field: TEXT}) {
|
||||
edges {
|
||||
node {
|
||||
text
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Fields Collection
|
||||
|
||||
The collection template adds support for automatic [GraphQL fields collection](https://spec.graphql.org/June2018/#sec-Field-Collection)
|
||||
for ent-edges using eager-loading. That means, if a query asks for nodes and their edges, entgql will add automatically [`With<E>`](eager-load.mdx#api)
|
||||
steps to the root query, and as a result, the client will execute constant number of queries to the database - and it works recursively.
|
||||
|
||||
For example, given this GraphQL query:
|
||||
|
||||
```graphql
|
||||
query {
|
||||
users(first: 100) {
|
||||
edges {
|
||||
node {
|
||||
photos {
|
||||
link
|
||||
}
|
||||
posts {
|
||||
content
|
||||
comments {
|
||||
content
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The client will execute 1 query for getting the users, 1 for getting the photos, and another 2 for getting the posts,
|
||||
and their comments (4 in total). This logic works both for root queries/resolvers and for the node(s) API.
|
||||
|
||||
### Schema configuration
|
||||
|
||||
In order to configure this option to specific edges, use the `entgql.Annotation` as follows:
|
||||
|
||||
```go
|
||||
func (Todo) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("children", Todo.Type).
|
||||
Annotations(entgql.Bind()).
|
||||
From("parent").
|
||||
// Bind implies the edge name in graphql schema is
|
||||
// equivalent to the name used in ent schema.
|
||||
Annotations(entgql.Bind()).
|
||||
Unique(),
|
||||
edge.From("owner", User.Type).
|
||||
Ref("tasks").
|
||||
// Map edge names as defined in graphql schema.
|
||||
Annotations(entgql.MapsTo("taskOwner")),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Usage and Configuration
|
||||
|
||||
The GraphQL extension generates also edge-resolvers for the nodes under the `gql_edge.go` file as follows:
|
||||
```go
|
||||
func (t *Todo) Children(ctx context.Context) ([]*Todo, error) {
|
||||
result, err := t.Edges.ChildrenOrErr()
|
||||
if IsNotLoaded(err) {
|
||||
result, err = t.QueryChildren().All(ctx)
|
||||
}
|
||||
return result, err
|
||||
}
|
||||
```
|
||||
|
||||
However, if you need to explicitly write these resolvers by hand, you can add the
|
||||
[`forceResolver`](https://gqlgen.com/master/config#inline-config-with-directives) option to your GraphQL schema:
|
||||
|
||||
```graphql
|
||||
type Todo implements Node {
|
||||
id: ID!
|
||||
children: [Todo]! @goField(forceResolver: true)
|
||||
}
|
||||
```
|
||||
|
||||
Then, you can implement it on your type resolver.
|
||||
|
||||
```go
|
||||
func (r *todoResolver) Children(ctx context.Context, obj *ent.Todo) ([]*ent.Todo, error) {
|
||||
// Do something here.
|
||||
return obj.Edges.ChildrenOrErr()
|
||||
}
|
||||
```
|
||||
|
||||
## Enum Implementation
|
||||
|
||||
The enum template implements the MarshalGQL/UnmarshalGQL methods for enums generated by ent.
|
||||
|
||||
## Transactional Mutations
|
||||
|
||||
The `entgql.Transactioner` handler executes each GraphQL mutation in a transaction. The injected client for the resolver
|
||||
is a [transactional `ent.Client`](transactions.md#transactional-client).
|
||||
Hence, code that uses `ent.Client` won't need to be changed. In order to use it, follow these steps:
|
||||
|
||||
|
||||
1\. In the GraphQL server initialization, use the `entgql.Transactioner` handler as follows:
|
||||
|
||||
```go
|
||||
srv := handler.NewDefaultServer(todo.NewSchema(client))
|
||||
srv.Use(entgql.Transactioner{TxOpener: client})
|
||||
```
|
||||
|
||||
2\. Then, in the GraphQL mutations, use the client from context as follows:
|
||||
```go
|
||||
func (mutationResolver) CreateTodo(ctx context.Context, todo TodoInput) (*ent.Todo, error) {
|
||||
client := ent.FromContext(ctx)
|
||||
return client.Todo.
|
||||
Create().
|
||||
SetStatus(todo.Status).
|
||||
SetNillablePriority(todo.Priority).
|
||||
SetText(todo.Text).
|
||||
SetNillableParentID(todo.Parent).
|
||||
Save(ctx)
|
||||
}
|
||||
```
|
||||
|
||||
## Examples
|
||||
|
||||
The [ent/contrib](https://github.com/ent/contrib) contains several examples at the moment:
|
||||
1. A complete GraphQL server with a simple [Todo App](https://github.com/ent/contrib/tree/master/entgql/internal/todo) with numeric ID field
|
||||
2. The same [Todo App](https://github.com/ent/contrib/tree/master/entgql/internal/todouuid) in 1, but with UUID type for the ID field
|
||||
3. The same [Todo App](https://github.com/ent/contrib/tree/master/entgql/internal/todopulid) in 1 and 2, but with a prefixed [ULID](https://github.com/ulid/spec) or `PULID` as the ID field. This example supports the Relay Node API by prefixing IDs with the entity type rather than employing the ID space partitioning in [Universal IDs](migrate.md#universal-ids).
|
||||
|
||||
---
|
||||
|
||||
Please note that this documentation is under development. All code parts reside in [ent/contrib/entgql](https://github.com/ent/contrib/tree/master/entgql),
|
||||
and an example of a todo-app can be found in [ent/contrib/entgql/todo](https://github.com/ent/contrib/tree/master/entgql/internal/todo).
|
||||
300
doc/md/hooks.md
Normal file
300
doc/md/hooks.md
Normal file
@@ -0,0 +1,300 @@
|
||||
---
|
||||
id: hooks
|
||||
title: Hooks
|
||||
---
|
||||
|
||||
The `Hooks` option allows adding custom logic before and after operations that mutate the graph.
|
||||
|
||||
## Mutation
|
||||
|
||||
A mutation operation is an operation that mutates the database. For example, adding
|
||||
a new node to the graph, remove an edge between 2 nodes or delete multiple nodes.
|
||||
|
||||
There are 5 types of mutations:
|
||||
- `Create` - Create node in the graph.
|
||||
- `UpdateOne` - Update a node in the graph. For example, increment its field.
|
||||
- `Update` - Update multiple nodes in the graph that match a predicate.
|
||||
- `DeleteOne` - Delete a node from the graph.
|
||||
- `Delete` - Delete all nodes that match a predicate.
|
||||
|
||||
Each generated node type has its own type of mutation. For example, all [`User` builders](crud.mdx#create-an-entity), share
|
||||
the same generated `UserMutation` object. However, all builder types implement the generic <a target="_blank" href="https://pkg.go.dev/entgo.io/ent?tab=doc#Mutation">`ent.Mutation`</a> interface.
|
||||
|
||||
:::info Support For Database Triggers
|
||||
Unlike database triggers, hooks are executed at the application level, not the database level. If you need to execute
|
||||
specific logic on the database level, use database triggers as explained in the [schema migration guide](/docs/migration/triggers).
|
||||
:::
|
||||
|
||||
## Hooks
|
||||
|
||||
Hooks are functions that get an <a target="_blank" href="https://pkg.go.dev/entgo.io/ent?tab=doc#Mutator">`ent.Mutator`</a> and return a mutator back.
|
||||
They function as middleware between mutators. It's similar to the popular HTTP middleware pattern.
|
||||
|
||||
```go
|
||||
type (
|
||||
// Mutator is the interface that wraps the Mutate method.
|
||||
Mutator interface {
|
||||
// Mutate apply the given mutation on the graph.
|
||||
Mutate(context.Context, Mutation) (Value, error)
|
||||
}
|
||||
|
||||
// Hook defines the "mutation middleware". A function that gets a Mutator
|
||||
// and returns a Mutator. For example:
|
||||
//
|
||||
// hook := func(next ent.Mutator) ent.Mutator {
|
||||
// return ent.MutateFunc(func(ctx context.Context, m ent.Mutation) (ent.Value, error) {
|
||||
// fmt.Printf("Type: %s, Operation: %s, ConcreteType: %T\n", m.Type(), m.Op(), m)
|
||||
// return next.Mutate(ctx, m)
|
||||
// })
|
||||
// }
|
||||
//
|
||||
Hook func(Mutator) Mutator
|
||||
)
|
||||
```
|
||||
|
||||
There are 2 types of mutation hooks - **schema hooks** and **runtime hooks**.
|
||||
**Schema hooks** are mainly used for defining custom mutation logic in the schema,
|
||||
and **runtime hooks** are used for adding things like logging, metrics, tracing, etc.
|
||||
Let's go over the 2 versions:
|
||||
|
||||
## Runtime hooks
|
||||
|
||||
Let's start with a short example that logs all mutation operations of all types:
|
||||
|
||||
```go
|
||||
func main() {
|
||||
client, err := ent.Open("sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to sqlite: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Run the auto migration tool.
|
||||
if err := client.Schema.Create(ctx); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
// Add a global hook that runs on all types and all operations.
|
||||
client.Use(func(next ent.Mutator) ent.Mutator {
|
||||
return ent.MutateFunc(func(ctx context.Context, m ent.Mutation) (ent.Value, error) {
|
||||
start := time.Now()
|
||||
defer func() {
|
||||
log.Printf("Op=%s\tType=%s\tTime=%s\tConcreteType=%T\n", m.Op(), m.Type(), time.Since(start), m)
|
||||
}()
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
})
|
||||
client.User.Create().SetName("a8m").SaveX(ctx)
|
||||
// Output:
|
||||
// 2020/03/21 10:59:10 Op=Create Type=User Time=46.23µs ConcreteType=*ent.UserMutation
|
||||
}
|
||||
```
|
||||
|
||||
Global hooks are useful for adding traces, metrics, logs and more. But sometimes, users want more granularity:
|
||||
|
||||
```go
|
||||
func main() {
|
||||
// <client was defined in the previous block>
|
||||
|
||||
// Add a hook only on user mutations.
|
||||
client.User.Use(func(next ent.Mutator) ent.Mutator {
|
||||
// Use the "<project>/ent/hook" to get the concrete type of the mutation.
|
||||
return hook.UserFunc(func(ctx context.Context, m *ent.UserMutation) (ent.Value, error) {
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
})
|
||||
|
||||
// Add a hook only on update operations.
|
||||
client.Use(hook.On(Logger(), ent.OpUpdate|ent.OpUpdateOne))
|
||||
|
||||
// Reject delete operations.
|
||||
client.Use(hook.Reject(ent.OpDelete|ent.OpDeleteOne))
|
||||
}
|
||||
```
|
||||
|
||||
Assume you want to share a hook that mutate a field between multiple types (e.g. `Group` and `User`).
|
||||
There are ~2 ways to do this:
|
||||
|
||||
```go
|
||||
// Option 1: use type assertion.
|
||||
client.Use(func(next ent.Mutator) ent.Mutator {
|
||||
type NameSetter interface {
|
||||
SetName(value string)
|
||||
}
|
||||
return ent.MutateFunc(func(ctx context.Context, m ent.Mutation) (ent.Value, error) {
|
||||
// A schema with a "name" field must implement the NameSetter interface.
|
||||
if ns, ok := m.(NameSetter); ok {
|
||||
ns.SetName("Ariel Mashraki")
|
||||
}
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
})
|
||||
|
||||
// Option 2: use the generic ent.Mutation interface.
|
||||
client.Use(func(next ent.Mutator) ent.Mutator {
|
||||
return ent.MutateFunc(func(ctx context.Context, m ent.Mutation) (ent.Value, error) {
|
||||
if err := m.SetField("name", "Ariel Mashraki"); err != nil {
|
||||
// An error is returned, if the field is not defined in
|
||||
// the schema, or if the type mismatch the field type.
|
||||
}
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
})
|
||||
```
|
||||
|
||||
## Schema hooks
|
||||
|
||||
Schema hooks are defined in the type schema and applied only on mutations that match the
|
||||
schema type. The motivation for defining hooks in the schema is to gather all logic
|
||||
regarding the node type in one place, which is the schema.
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"context"
|
||||
"fmt"
|
||||
|
||||
gen "<project>/ent"
|
||||
"<project>/ent/hook"
|
||||
|
||||
"entgo.io/ent"
|
||||
)
|
||||
|
||||
// Card holds the schema definition for the CreditCard entity.
|
||||
type Card struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Hooks of the Card.
|
||||
func (Card) Hooks() []ent.Hook {
|
||||
return []ent.Hook{
|
||||
// First hook.
|
||||
hook.On(
|
||||
func(next ent.Mutator) ent.Mutator {
|
||||
return hook.CardFunc(func(ctx context.Context, m *gen.CardMutation) (ent.Value, error) {
|
||||
if num, ok := m.Number(); ok && len(num) < 10 {
|
||||
return nil, fmt.Errorf("card number is too short")
|
||||
}
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
},
|
||||
// Limit the hook only for these operations.
|
||||
ent.OpCreate|ent.OpUpdate|ent.OpUpdateOne,
|
||||
),
|
||||
// Second hook.
|
||||
func(next ent.Mutator) ent.Mutator {
|
||||
return ent.MutateFunc(func(ctx context.Context, m ent.Mutation) (ent.Value, error) {
|
||||
if s, ok := m.(interface{ SetName(string) }); ok {
|
||||
s.SetName("Boring")
|
||||
}
|
||||
v, err := next.Mutate(ctx, m)
|
||||
// Post mutation action.
|
||||
fmt.Println("new value:", v)
|
||||
return v, err
|
||||
})
|
||||
},
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Hooks Registration
|
||||
|
||||
When using [**schema hooks**](#schema-hooks), there's a chance of a cyclic import between the schema package,
|
||||
and the generated ent package. To avoid this scenario, ent generates an `ent/runtime` package which is responsible
|
||||
for registering the schema-hooks at runtime.
|
||||
|
||||
:::important
|
||||
Users **MUST** import the `ent/runtime` in order to register the schema hooks.
|
||||
The package can be imported in the `main` package (close to where the database driver is imported),
|
||||
or in the package that creates the `ent.Client`.
|
||||
|
||||
```go
|
||||
import _ "<project>/ent/runtime"
|
||||
```
|
||||
:::
|
||||
|
||||
#### Import Cycle Error
|
||||
|
||||
At the first attempt to set up schema hooks in your project, you may encounter an error like the following:
|
||||
```text
|
||||
entc/load: parse schema dir: import cycle not allowed: [ent/schema ent/hook ent/ ent/schema]
|
||||
To resolve this issue, move the custom types used by the generated code to a separate package: "Type1", "Type2"
|
||||
```
|
||||
|
||||
The error may occur because the generated code relies on custom types defined in the `ent/schema` package, but this
|
||||
package also imports the `ent/hook` package. This indirect import of the `ent` package creates a loop, causing the error
|
||||
to occur. To resolve this issue, follow these instructions:
|
||||
|
||||
- First, comment out any usage of hooks, privacy policy, or interceptors from the `ent/schema`.
|
||||
- Move the custom types defined in the `ent/schema` to a new package, for example, `ent/schema/schematype`.
|
||||
- Run `go generate ./...` to update the generated `ent` package to point to the new package. For example, `schema.T` becomes `schematype.T`.
|
||||
- Uncomment the hooks, privacy policy, or interceptors, and run `go generate ./...` again. The code generation should now pass without error.
|
||||
|
||||
## Evaluation order
|
||||
|
||||
Hooks are called in the order they were registered to the client. Thus, `client.Use(f, g, h)`
|
||||
executes `f(g(h(...)))` on mutations.
|
||||
|
||||
Also note, that **runtime hooks** are called before **schema hooks**. That is, if `g`,
|
||||
and `h` were defined in the schema, and `f` was registered using `client.Use(...)`,
|
||||
they will be executed as follows: `f(g(h(...)))`.
|
||||
|
||||
## Hook helpers
|
||||
|
||||
The generated hooks package provides several helpers that can help you control when a hook will
|
||||
be executed.
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"context"
|
||||
"fmt"
|
||||
|
||||
"<project>/ent/hook"
|
||||
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/mixin"
|
||||
)
|
||||
|
||||
|
||||
type SomeMixin struct {
|
||||
mixin.Schema
|
||||
}
|
||||
|
||||
func (SomeMixin) Hooks() []ent.Hook {
|
||||
return []ent.Hook{
|
||||
// Execute "HookA" only for the UpdateOne and DeleteOne operations.
|
||||
hook.On(HookA(), ent.OpUpdateOne|ent.OpDeleteOne),
|
||||
|
||||
// Don't execute "HookB" on Create operation.
|
||||
hook.Unless(HookB(), ent.OpCreate),
|
||||
|
||||
// Execute "HookC" only if the ent.Mutation is changing the "status" field,
|
||||
// and clearing the "dirty" field.
|
||||
hook.If(HookC(), hook.And(hook.HasFields("status"), hook.HasClearedFields("dirty"))),
|
||||
|
||||
// Disallow changing the "password" field on Update (many) operation.
|
||||
hook.If(
|
||||
hook.FixedError(errors.New("password cannot be edited on update many")),
|
||||
hook.And(
|
||||
hook.HasOp(ent.OpUpdate),
|
||||
hook.Or(
|
||||
hook.HasFields("password"),
|
||||
hook.HasClearedFields("password"),
|
||||
),
|
||||
),
|
||||
),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Transaction Hooks
|
||||
|
||||
Hooks can also be registered on active transactions, and will be executed on `Tx.Commit` or `Tx.Rollback`.
|
||||
For more information, read about it in the [transactions page](transactions.md#hooks).
|
||||
|
||||
## Codegen Hooks
|
||||
|
||||
The `entc` package provides an option to add a list of hooks (middlewares) to the code-generation phase.
|
||||
For more information, read about it in the [codegen page](code-gen.md#code-generation-hooks).
|
||||
416
doc/md/interceptors.mdx
Normal file
416
doc/md/interceptors.mdx
Normal file
@@ -0,0 +1,416 @@
|
||||
---
|
||||
id: interceptors
|
||||
title: Interceptors
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
Interceptors are execution middleware for various types of Ent queries. Contrary to hooks, interceptors are applied on
|
||||
the read-path and implemented as interfaces, allows them to intercept and modify the query at different stages, providing
|
||||
more fine-grained control over queries' behavior. For example, see the [Traverser interface](#defining-a-traverser) below.
|
||||
|
||||
## Defining an Interceptor
|
||||
|
||||
To define an `Interceptor`, users can declare a struct that implements the `Intercept` method or use the predefined
|
||||
`ent.InterceptFunc` adapter.
|
||||
|
||||
```go
|
||||
ent.InterceptFunc(func(next ent.Querier) ent.Querier {
|
||||
return ent.QuerierFunc(func(ctx context.Context, query ent.Query) (ent.Value, error) {
|
||||
// Do something before the query execution.
|
||||
value, err := next.Query(ctx, query)
|
||||
// Do something after the query execution.
|
||||
return value, err
|
||||
})
|
||||
})
|
||||
```
|
||||
|
||||
In the example above, the `ent.Query` represents a generated query builder (e.g., `ent.<T>Query`) and accessing its
|
||||
methods requires type assertion. For example:
|
||||
|
||||
```go
|
||||
ent.InterceptFunc(func(next ent.Querier) ent.Querier {
|
||||
return ent.QuerierFunc(func(ctx context.Context, query ent.Query) (ent.Value, error) {
|
||||
if q, ok := query.(*ent.UserQuery); ok {
|
||||
q.Where(user.Name("a8m"))
|
||||
}
|
||||
return next.Query(ctx, query)
|
||||
})
|
||||
})
|
||||
```
|
||||
|
||||
However, the utilities generated by the `intercept` feature flag enable the creation of generic interceptors that can
|
||||
be applied to any query type. The `intercept` feature flag can be added to a project in one of two ways:
|
||||
|
||||
#### Configuration
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="cli" label="CLI" default>
|
||||
|
||||
If you are using the default go generate config, add `--feature intercept` option to the `ent/generate.go` file as follows:
|
||||
|
||||
```go title="ent/generate.go"
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entgo.io/ent/cmd/ent generate --feature intercept ./schema
|
||||
```
|
||||
|
||||
It is recommended to add the [`schema/snapshot`](features.md#auto-solve-merge-conflicts) feature-flag along with the
|
||||
`intercept` flag to enhance the development experience, for example:
|
||||
|
||||
```go
|
||||
//go:generate go run -mod=mod entgo.io/ent/cmd/ent generate --feature intercept,schema/snapshot ./schema
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="entc" label="Go">
|
||||
|
||||
If you are using the configuration from the GraphQL documentation, add the feature flag as follows:
|
||||
|
||||
```go
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
)
|
||||
|
||||
func main() {
|
||||
opts := []entc.Option{
|
||||
entc.FeatureNames("intercept"),
|
||||
}
|
||||
if err := entc.Generate("./schema", &gen.Config{}, opts...); err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
|
||||
It is recommended to add the [`schema/snapshot`](features.md#auto-solve-merge-conflicts) feature-flag along with the
|
||||
`intercept` flag to enhance the development experience, for example:
|
||||
|
||||
```diff
|
||||
opts := []entc.Option{
|
||||
- entc.FeatureNames("intercept"),
|
||||
+ entc.FeatureNames("intercept", "schema/snapshot"),
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### Interceptors Registration
|
||||
|
||||
:::important
|
||||
You should notice that similar to [schema hooks](hooks.md#hooks-registration), if you use the **`Interceptors`** option
|
||||
in your schema, you **MUST** add the following import in the main package, because a circular import is possible between
|
||||
the schema package and the generated ent package:
|
||||
```go
|
||||
import _ "<project>/ent/runtime"
|
||||
```
|
||||
:::
|
||||
|
||||
#### Using the generated `intercept` package
|
||||
|
||||
Once the feature flag was added to your project, the creation of interceptors is possible using the `intercept` package:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="func" label="intercept.Func" default>
|
||||
|
||||
```go
|
||||
client.Intercept(
|
||||
intercept.Func(func(ctx context.Context, q intercept.Query) error {
|
||||
// Limit all queries to 1000 records.
|
||||
q.Limit(1000)
|
||||
return nil
|
||||
})
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="traverse-func" label="intercept.TraverseFunc">
|
||||
|
||||
```go
|
||||
client.Intercept(
|
||||
intercept.TraverseFunc(func(ctx context.Context, q intercept.Query) error {
|
||||
// Apply a predicate/filter to all queries.
|
||||
q.WhereP(predicate)
|
||||
return nil
|
||||
})
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="new-query" label="intercept.NewQuery">
|
||||
|
||||
```go
|
||||
ent.InterceptFunc(func(next ent.Querier) ent.Querier {
|
||||
return ent.QuerierFunc(func(ctx context.Context, query ent.Query) (ent.Value, error) {
|
||||
// Get a generic query from a typed-query.
|
||||
q, err := intercept.NewQuery(query)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
q.Limit(1000)
|
||||
return next.Intercept(ctx, query)
|
||||
})
|
||||
})
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Defining a Traverser
|
||||
|
||||
In some cases, there is a need to intercept [graph traversals](traversals.md) and modify their builders before
|
||||
continuing to the nodes returned by the query. For example, in the query below, we want to ensure that only `active`
|
||||
users are traversed in **any** graph traversals in the system:
|
||||
|
||||
```go
|
||||
intercept.TraverseUser(func(ctx context.Context, q *ent.UserQuery) error {
|
||||
q.Where(user.Active(true))
|
||||
return nil
|
||||
})
|
||||
```
|
||||
|
||||
After defining and registering such Traverser, it will take effect on all graph traversals in the system. For example:
|
||||
|
||||
```go
|
||||
func TestTypedTraverser(t *testing.T) {
|
||||
ctx := context.Background()
|
||||
client := enttest.Open(t, dialect.SQLite, "file:ent?mode=memory&_fk=1")
|
||||
defer client.Close()
|
||||
a8m, nat := client.User.Create().SetName("a8m").SaveX(ctx), client.User.Create().SetName("nati").SetActive(false).SaveX(ctx)
|
||||
client.Pet.CreateBulk(
|
||||
client.Pet.Create().SetName("a").SetOwner(a8m),
|
||||
client.Pet.Create().SetName("b").SetOwner(a8m),
|
||||
client.Pet.Create().SetName("c").SetOwner(nat),
|
||||
).ExecX(ctx)
|
||||
|
||||
// highlight-start
|
||||
// Get pets of all users.
|
||||
if n := client.User.Query().QueryPets().CountX(ctx); n != 3 {
|
||||
t.Errorf("got %d pets, want 3", n)
|
||||
}
|
||||
// highlight-end
|
||||
|
||||
// Add an interceptor that filters out inactive users.
|
||||
client.User.Intercept(
|
||||
intercept.TraverseUser(func(ctx context.Context, q *ent.UserQuery) error {
|
||||
q.Where(user.Active(true))
|
||||
return nil
|
||||
}),
|
||||
)
|
||||
|
||||
// highlight-start
|
||||
// Only pets of active users are returned.
|
||||
if n := client.User.Query().QueryPets().CountX(ctx); n != 2 {
|
||||
t.Errorf("got %d pets, want 2", n)
|
||||
}
|
||||
// highlight-end
|
||||
}
|
||||
```
|
||||
|
||||
## Interceptors vs. Traversers
|
||||
|
||||
Both `Interceptors` and `Traversers` can be used to modify the behavior of queries, but they do so at different stages
|
||||
the execution. Interceptors function as middleware and allow modifying the query before it is executed and modifying
|
||||
the records after they are returned from the database. For this reason, they are applied only in the final stage of the
|
||||
query - during the actual execution of the statement on the database. On the other hand, Traversers are called one stage
|
||||
earlier, at each step of a graph traversal allowing them to modify both intermediate and final queries before they
|
||||
are joined together.
|
||||
|
||||
In summary, a Traverse function is a better fit for adding default filters to graph traversals while using an Intercept
|
||||
function is better for implementing logging or caching capabilities to the application.
|
||||
|
||||
```go
|
||||
client.User.Query().
|
||||
QueryGroups(). // User traverse functions applied.
|
||||
QueryPosts(). // Group traverse functions applied.
|
||||
All(ctx) // Post traverse and intercept functions applied.
|
||||
```
|
||||
|
||||
## Examples
|
||||
|
||||
### Soft Delete
|
||||
|
||||
The soft delete pattern is a common use-case for interceptors and hooks. The example below demonstrates how to add such
|
||||
functionality to all schemas in the project using [`ent.Mixin`](schema-mixin.md):
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="mixin" label="Mixin" default>
|
||||
|
||||
```go
|
||||
// SoftDeleteMixin implements the soft delete pattern for schemas.
|
||||
type SoftDeleteMixin struct {
|
||||
mixin.Schema
|
||||
}
|
||||
|
||||
// Fields of the SoftDeleteMixin.
|
||||
func (SoftDeleteMixin) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Time("delete_time").
|
||||
Optional(),
|
||||
}
|
||||
}
|
||||
|
||||
type softDeleteKey struct{}
|
||||
|
||||
// SkipSoftDelete returns a new context that skips the soft-delete interceptor/mutators.
|
||||
func SkipSoftDelete(parent context.Context) context.Context {
|
||||
return context.WithValue(parent, softDeleteKey{}, true)
|
||||
}
|
||||
|
||||
// Interceptors of the SoftDeleteMixin.
|
||||
func (d SoftDeleteMixin) Interceptors() []ent.Interceptor {
|
||||
return []ent.Interceptor{
|
||||
intercept.TraverseFunc(func(ctx context.Context, q intercept.Query) error {
|
||||
// Skip soft-delete, means include soft-deleted entities.
|
||||
if skip, _ := ctx.Value(softDeleteKey{}).(bool); skip {
|
||||
return nil
|
||||
}
|
||||
d.P(q)
|
||||
return nil
|
||||
}),
|
||||
}
|
||||
}
|
||||
|
||||
// Hooks of the SoftDeleteMixin.
|
||||
func (d SoftDeleteMixin) Hooks() []ent.Hook {
|
||||
return []ent.Hook{
|
||||
hook.On(
|
||||
func(next ent.Mutator) ent.Mutator {
|
||||
return ent.MutateFunc(func(ctx context.Context, m ent.Mutation) (ent.Value, error) {
|
||||
// Skip soft-delete, means delete the entity permanently.
|
||||
if skip, _ := ctx.Value(softDeleteKey{}).(bool); skip {
|
||||
return next.Mutate(ctx, m)
|
||||
}
|
||||
mx, ok := m.(interface {
|
||||
SetOp(ent.Op)
|
||||
Client() *gen.Client
|
||||
SetDeleteTime(time.Time)
|
||||
WhereP(...func(*sql.Selector))
|
||||
})
|
||||
if !ok {
|
||||
return nil, fmt.Errorf("unexpected mutation type %T", m)
|
||||
}
|
||||
d.P(mx)
|
||||
mx.SetOp(ent.OpUpdate)
|
||||
mx.SetDeleteTime(time.Now())
|
||||
return mx.Client().Mutate(ctx, m)
|
||||
})
|
||||
},
|
||||
ent.OpDeleteOne|ent.OpDelete,
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
// P adds a storage-level predicate to the queries and mutations.
|
||||
func (d SoftDeleteMixin) P(w interface{ WhereP(...func(*sql.Selector)) }) {
|
||||
w.WhereP(
|
||||
sql.FieldIsNull(d.Fields()[0].Descriptor().Name),
|
||||
)
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="schema" label="Mixin usage">
|
||||
|
||||
```go
|
||||
// Pet holds the schema definition for the Pet entity.
|
||||
type Pet struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Mixin of the Pet.
|
||||
func (Pet) Mixin() []ent.Mixin {
|
||||
return []ent.Mixin{
|
||||
//highlight-next-line
|
||||
SoftDeleteMixin{},
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="runtime" label="Runtime usage">
|
||||
|
||||
```go
|
||||
// Filter out soft-deleted entities.
|
||||
pets, err := client.Pet.Query().All(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
// Include soft-deleted entities.
|
||||
pets, err := client.Pet.Query().All(schema.SkipSoftDelete(ctx))
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Limit number of records
|
||||
|
||||
The following example demonstrates how to limit the number of records returned from the database using an interceptor
|
||||
function:
|
||||
|
||||
```go
|
||||
client.Intercept(
|
||||
intercept.Func(func(ctx context.Context, q intercept.Query) error {
|
||||
// LimitInterceptor limits the number of records returned from
|
||||
// the database to 1000, in case Limit was not explicitly set.
|
||||
if ent.QueryFromContext(ctx).Limit == nil {
|
||||
q.Limit(1000)
|
||||
}
|
||||
return nil
|
||||
}),
|
||||
)
|
||||
```
|
||||
|
||||
### Multi-project support
|
||||
|
||||
The example below demonstrates how to write a generic interceptor that can be used in multiple projects:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="definition" label="Definition">
|
||||
|
||||
```go
|
||||
// Project-level example. The usage of "entgo" package emphasizes that this interceptor does not rely on any generated code.
|
||||
func SharedLimiter[Q interface{ Limit(int) }](f func(entgo.Query) (Q, error), limit int) entgo.Interceptor {
|
||||
return entgo.InterceptFunc(func(next entgo.Querier) entgo.Querier {
|
||||
return entgo.QuerierFunc(func(ctx context.Context, query entgo.Query) (entgo.Value, error) {
|
||||
l, err := f(query)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
l.Limit(limit)
|
||||
// LimitInterceptor limits the number of records returned from the
|
||||
// database to the configured one, in case Limit was not explicitly set.
|
||||
if entgo.QueryFromContext(ctx).Limit == nil {
|
||||
l.Limit(limit)
|
||||
}
|
||||
return next.Query(ctx, query)
|
||||
})
|
||||
})
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="usage" label="Usage">
|
||||
|
||||
```go
|
||||
client1.Intercept(SharedLimiter(intercept1.NewQuery, limit))
|
||||
|
||||
client2.Intercept(SharedLimiter(intercept2.NewQuery, limit))
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
446
doc/md/migrate.md
Normal file
446
doc/md/migrate.md
Normal file
@@ -0,0 +1,446 @@
|
||||
---
|
||||
id: migrate
|
||||
title: Automatic Migration
|
||||
---
|
||||
|
||||
The migration support for `ent` provides the option for keeping the database schema
|
||||
aligned with the schema objects defined in `ent/migrate/schema.go` under the root of your project.
|
||||
|
||||
## Auto Migration
|
||||
|
||||
Run the auto-migration logic in the initialization of the application:
|
||||
|
||||
```go
|
||||
if err := client.Schema.Create(ctx); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
```
|
||||
|
||||
`Create` creates all database resources needed for your `ent` project. By default, `Create` works
|
||||
in an *"append-only"* mode; which means, it only creates new tables and indexes, appends columns to tables or
|
||||
extends column types. For example, changing `int` to `bigint`.
|
||||
|
||||
What about dropping columns or indexes?
|
||||
|
||||
## Drop Resources
|
||||
|
||||
`WithDropIndex` and `WithDropColumn` are 2 options for dropping table columns and indexes.
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/migrate"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Run migration.
|
||||
err = client.Schema.Create(
|
||||
ctx,
|
||||
migrate.WithDropIndex(true),
|
||||
migrate.WithDropColumn(true),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
In order to run the migration in debug mode (printing all SQL queries), run:
|
||||
|
||||
```go
|
||||
err := client.Debug().Schema.Create(
|
||||
ctx,
|
||||
migrate.WithDropIndex(true),
|
||||
migrate.WithDropColumn(true),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
```
|
||||
|
||||
## Universal IDs
|
||||
|
||||
By default, SQL primary-keys start from 1 for each table; which means that multiple entities of different types
|
||||
can share the same ID. Unlike AWS Neptune, where node IDs are UUIDs. [Read this](features.md#globally-unique-id) to
|
||||
learn how to enable universally unique ids when using Ent with a SQL database.
|
||||
|
||||
## Offline Mode
|
||||
|
||||
**With Atlas becoming the default migration engine soon, offline migration will be replaced
|
||||
by [versioned migrations](versioned-migrations.mdx).**
|
||||
|
||||
Offline mode allows you to write the schema changes to an `io.Writer` before executing them on the database.
|
||||
It's useful for verifying the SQL commands before they're executed on the database, or to get an SQL script
|
||||
to run manually.
|
||||
|
||||
**Print changes**
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"os"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/migrate"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Dump migration changes to stdout.
|
||||
if err := client.Schema.WriteTo(ctx, os.Stdout); err != nil {
|
||||
log.Fatalf("failed printing schema changes: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Write changes to a file**
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"os"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/migrate"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Dump migration changes to an SQL script.
|
||||
f, err := os.Create("migrate.sql")
|
||||
if err != nil {
|
||||
log.Fatalf("create migrate file: %v", err)
|
||||
}
|
||||
defer f.Close()
|
||||
if err := client.Schema.WriteTo(ctx, f); err != nil {
|
||||
log.Fatalf("failed printing schema changes: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Foreign Keys
|
||||
|
||||
By default, `ent` uses foreign-keys when defining relationships (edges) to enforce correctness and consistency on the
|
||||
database side.
|
||||
|
||||
However, `ent` also provide an option to disable this functionality using the `WithForeignKeys` option.
|
||||
You should note that setting this option to `false`, will tell the migration to not create foreign-keys in the
|
||||
schema DDL and the edges validation and clearing must be handled manually by the developer.
|
||||
|
||||
We expect to provide a set of hooks for implementing the foreign-key constraints in the application level in the near future.
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/migrate"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Run migration.
|
||||
err = client.Schema.Create(
|
||||
ctx,
|
||||
migrate.WithForeignKeys(false), // Disable foreign keys.
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Migration Hooks
|
||||
|
||||
The framework provides an option to add hooks (middlewares) to the migration phase.
|
||||
This option is ideal for modifying or filtering the tables that the migration is working on,
|
||||
or for creating custom resources in the database.
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/migrate"
|
||||
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Run migration.
|
||||
err = client.Schema.Create(
|
||||
ctx,
|
||||
schema.WithHooks(func(next schema.Creator) schema.Creator {
|
||||
return schema.CreateFunc(func(ctx context.Context, tables ...*schema.Table) error {
|
||||
// Run custom code here.
|
||||
return next.Create(ctx, tables...)
|
||||
})
|
||||
}),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Atlas Integration
|
||||
|
||||
Starting with v0.10, Ent supports running migration with [Atlas](https://atlasgo.io), which is a more robust
|
||||
migration framework that covers many features that are not supported by current Ent migrate package. In order
|
||||
to execute a migration with the Atlas engine, use the `WithAtlas(true)` option.
|
||||
|
||||
```go {21}
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/migrate"
|
||||
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Run migration.
|
||||
err = client.Schema.Create(ctx, schema.WithAtlas(true))
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
In addition to the standard options (e.g. `WithDropColumn`, `WithGlobalUniqueID`), the Atlas integration provides additional
|
||||
options for hooking into schema migration steps.
|
||||
|
||||

|
||||
|
||||
|
||||
#### Atlas `Diff` and `Apply` Hooks
|
||||
|
||||
Here are two examples that show how to hook into the Atlas `Diff` and `Apply` steps.
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/migrate"
|
||||
|
||||
"ariga.io/atlas/sql/migrate"
|
||||
atlas "ariga.io/atlas/sql/schema"
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Run migration.
|
||||
err := client.Schema.Create(
|
||||
ctx,
|
||||
// Hook into Atlas Diff process.
|
||||
schema.WithDiffHook(func(next schema.Differ) schema.Differ {
|
||||
return schema.DiffFunc(func(current, desired *atlas.Schema) ([]atlas.Change, error) {
|
||||
// Before calculating changes.
|
||||
changes, err := next.Diff(current, desired)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
// After diff, you can filter
|
||||
// changes or return new ones.
|
||||
return changes, nil
|
||||
})
|
||||
}),
|
||||
// Hook into Atlas Apply process.
|
||||
schema.WithApplyHook(func(next schema.Applier) schema.Applier {
|
||||
return schema.ApplyFunc(func(ctx context.Context, conn dialect.ExecQuerier, plan *migrate.Plan) error {
|
||||
// Example to hook into the apply process, or implement
|
||||
// a custom applier. For example, write to a file.
|
||||
//
|
||||
// for _, c := range plan.Changes {
|
||||
// fmt.Printf("%s: %s", c.Comment, c.Cmd)
|
||||
// if err := conn.Exec(ctx, c.Cmd, c.Args, nil); err != nil {
|
||||
// return err
|
||||
// }
|
||||
// }
|
||||
//
|
||||
return next.Apply(ctx, conn, plan)
|
||||
})
|
||||
}),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
#### `Diff` Hook Example
|
||||
|
||||
In case a field was renamed in the `ent/schema`, Ent won't detect this change as renaming and will propose `DropColumn`
|
||||
and `AddColumn` changes in the diff stage. One way to get over this is to use the
|
||||
[StorageKey](schema-fields.mdx#storage-key) option on the field and keep the old column name in the database table.
|
||||
However, using Atlas `Diff` hooks allow replacing the `DropColumn` and `AddColumn` changes with a `RenameColumn` change.
|
||||
|
||||
```go
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
// ...
|
||||
if err := client.Schema.Create(ctx, schema.WithDiffHook(renameColumnHook)); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
|
||||
func renameColumnHook(next schema.Differ) schema.Differ {
|
||||
return schema.DiffFunc(func(current, desired *atlas.Schema) ([]atlas.Change, error) {
|
||||
changes, err := next.Diff(current, desired)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
for _, c := range changes {
|
||||
m, ok := c.(*atlas.ModifyTable)
|
||||
// Skip if the change is not a ModifyTable,
|
||||
// or if the table is not the "users" table.
|
||||
if !ok || m.T.Name != user.Table {
|
||||
continue
|
||||
}
|
||||
changes := atlas.Changes(m.Changes)
|
||||
switch i, j := changes.IndexDropColumn("old_name"), changes.IndexAddColumn("new_name"); {
|
||||
case i != -1 && j != -1:
|
||||
// Append a new renaming change.
|
||||
changes = append(changes, &atlas.RenameColumn{
|
||||
From: changes[i].(*atlas.DropColumn).C,
|
||||
To: changes[j].(*atlas.AddColumn).C,
|
||||
})
|
||||
// Remove the drop and add changes.
|
||||
changes.RemoveIndex(i, j)
|
||||
m.Changes = changes
|
||||
case i != -1 || j != -1:
|
||||
return nil, errors.New("old_name and new_name must be present or absent")
|
||||
}
|
||||
}
|
||||
return changes, nil
|
||||
})
|
||||
}
|
||||
```
|
||||
|
||||
#### `Apply` Hook Example
|
||||
|
||||
The `Apply` hook allows accessing and mutating the migration plan and its raw changes (SQL statements), but in addition
|
||||
to that it is also useful for executing custom SQL statements before or after the plan is applied. For example, changing
|
||||
a nullable column to non-nullable without a default value is not allowed by default. However, we can work around this
|
||||
using an `Apply` hook that `UPDATE`s all rows that contain `NULL` value in this column:
|
||||
|
||||
```go
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
// ...
|
||||
if err := client.Schema.Create(ctx, schema.WithApplyHook(fillNulls)); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
|
||||
func fillNulls(next schema.Applier) schema.Applier {
|
||||
return schema.ApplyFunc(func(ctx context.Context, conn dialect.ExecQuerier, plan *migrate.Plan) error {
|
||||
// There are three ways to UPDATE the NULL values to "Unknown" in this stage.
|
||||
// Append a custom migrate.Change to the plan, execute an SQL statement directly
|
||||
// on the dialect.ExecQuerier, or use the ent.Client used by the project.
|
||||
|
||||
// Execute a custom SQL statement.
|
||||
query, args := sql.Dialect(dialect.MySQL).
|
||||
Update(user.Table).
|
||||
Set(user.FieldDropOptional, "Unknown").
|
||||
Where(sql.IsNull(user.FieldDropOptional)).
|
||||
Query()
|
||||
if err := conn.Exec(ctx, query, args, nil); err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
// Append a custom statement to migrate.Plan.
|
||||
//
|
||||
// plan.Changes = append([]*migrate.Change{
|
||||
// {
|
||||
// Cmd: fmt.Sprintf("UPDATE users SET %[1]s = '%[2]s' WHERE %[1]s IS NULL", user.FieldDropOptional, "Unknown"),
|
||||
// },
|
||||
// }, plan.Changes...)
|
||||
|
||||
// Use the ent.Client used by the project.
|
||||
//
|
||||
// drv := sql.NewDriver(dialect.MySQL, sql.Conn{ExecQuerier: conn.(*sql.Tx)})
|
||||
// if err := ent.NewClient(ent.Driver(drv)).
|
||||
// User.
|
||||
// Update().
|
||||
// SetDropOptional("Unknown").
|
||||
// Where(/* Add predicate to filter only rows with NULL values */).
|
||||
// Exec(ctx); err != nil {
|
||||
// return fmt.Errorf("fix default values to uppercase: %w", err)
|
||||
// }
|
||||
|
||||
return next.Apply(ctx, conn, plan)
|
||||
})
|
||||
}
|
||||
```
|
||||
241
doc/md/migration/composite.mdx
Normal file
241
doc/md/migration/composite.mdx
Normal file
@@ -0,0 +1,241 @@
|
||||
---
|
||||
title: Using Composite Types in Ent Schema
|
||||
id: composite
|
||||
slug: composite-types
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import InstallationInstructions from '../components/_installation_instructions.mdx';
|
||||
|
||||
In PostgreSQL, a composite type is structured like a row or record, consisting of field names and their corresponding
|
||||
data types. Setting an Ent field as a composite type enables you to store complex and structured data in a single column.
|
||||
|
||||
This guide explains how to define a schema field type as a composite type in your Ent schema and configure the schema migration
|
||||
to manage both the composite types and the Ent schema as a single migration unit using Atlas.
|
||||
|
||||
:::info [Atlas Pro Feature](https://atlasgo.io/features#pro-plan)
|
||||
Atlas support for [Composite Types](https://atlasgo.io/atlas-schema/hcl#composite-type) is available exclusively to Pro users.
|
||||
To use this feature, run:
|
||||
```
|
||||
atlas login
|
||||
```
|
||||
:::
|
||||
|
||||
## Install Atlas
|
||||
|
||||
<InstallationInstructions />
|
||||
|
||||
## Login to Atlas
|
||||
|
||||
```shell
|
||||
$ atlas login a8m
|
||||
//highlight-next-line-info
|
||||
You are now connected to "a8m" on Atlas Cloud.
|
||||
```
|
||||
|
||||
## Composite Schema
|
||||
|
||||
An `ent/schema` package is mostly used for defining Ent types (objects), their fields, edges and logic. Composite types,
|
||||
or any other database objects do not have representation in Ent models - A composite type can be defined once,
|
||||
and may be used multiple times in different fields and models.
|
||||
|
||||
In order to extend our PostgreSQL schema to include both custom composite types and our Ent types, we configure Atlas to
|
||||
read the state of the schema from a [Composite Schema](https://atlasgo.io/atlas-schema/projects#data-source-composite_schema)
|
||||
data source. Follow the steps below to configure this for your project:
|
||||
|
||||
1\. Create a `schema.sql` that defines the necessary composite type. In the same way, you can configure the composite type in
|
||||
[Atlas Schema HCL language](https://atlasgo.io/atlas-schema/hcl-types#composite-type):
|
||||
|
||||
<Tabs>
|
||||
<TabItem value={"sql"} label={"Using SQL"}>
|
||||
|
||||
```sql title="schema.sql"
|
||||
CREATE TYPE address AS (
|
||||
street text,
|
||||
city text
|
||||
);
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value={"hcl"} label={"Using HCL"}>
|
||||
|
||||
```hcl title="schema.hcl"
|
||||
schema "public" {}
|
||||
|
||||
composite "address" {
|
||||
schema = schema.public
|
||||
field "street" {
|
||||
type = text
|
||||
}
|
||||
field "city" {
|
||||
type = text
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
2\. In your Ent schema, define a field that uses the composite type only in PostgreSQL dialect:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value={"schema"} label={"Schema"}>
|
||||
|
||||
```go title="ent/schema/user.go" {6-8}
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("address").
|
||||
GoType(&Address{}).
|
||||
SchemaType(map[string]string{
|
||||
dialect.Postgres: "address",
|
||||
}),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
:::note
|
||||
In case a schema with custom driver-specific types is used with other databases, Ent falls back to the default type
|
||||
used by the driver (e.g., "varchar").
|
||||
:::
|
||||
</TabItem>
|
||||
<TabItem value={"address"} label={"Address Type"}>
|
||||
|
||||
```go title="ent/schematype/address.go"
|
||||
type Address struct {
|
||||
Street, City string
|
||||
}
|
||||
|
||||
var _ field.ValueScanner = (*Address)(nil)
|
||||
|
||||
// Scan implements the database/sql.Scanner interface.
|
||||
func (a *Address) Scan(v interface{}) (err error) {
|
||||
switch v := v.(type) {
|
||||
case nil:
|
||||
case string:
|
||||
_, err = fmt.Sscanf(v, "(%q,%q)", &a.Street, &a.City)
|
||||
case []byte:
|
||||
_, err = fmt.Sscanf(string(v), "(%q,%q)", &a.Street, &a.City)
|
||||
}
|
||||
return
|
||||
}
|
||||
|
||||
// Value implements the driver.Valuer interface.
|
||||
func (a *Address) Value() (driver.Value, error) {
|
||||
return fmt.Sprintf("(%q,%q)", a.Street, a.City), nil
|
||||
}
|
||||
```
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
||||
3\. Create a simple `atlas.hcl` config file with a `composite_schema` that includes both your custom types defined in
|
||||
`schema.sql` and your Ent schema:
|
||||
|
||||
```hcl title="atlas.hcl"
|
||||
data "composite_schema" "app" {
|
||||
# Load first custom types first.
|
||||
schema "public" {
|
||||
url = "file://schema.sql"
|
||||
}
|
||||
# Second, load the Ent schema.
|
||||
schema "public" {
|
||||
url = "ent://ent/schema"
|
||||
}
|
||||
}
|
||||
|
||||
env "local" {
|
||||
src = data.composite_schema.app.url
|
||||
dev = "docker://postgres/15/dev?search_path=public"
|
||||
}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
After setting up our schema, we can get its representation using the `atlas schema inspect` command, generate migrations for
|
||||
it, apply them to a database, and more. Below are a few commands to get you started with Atlas:
|
||||
|
||||
#### Inspect the Schema
|
||||
|
||||
The `atlas schema inspect` command is commonly used to inspect databases. However, we can also use it to inspect our
|
||||
`composite_schema` and print the SQL representation of it:
|
||||
|
||||
```shell
|
||||
atlas schema inspect \
|
||||
--env local \
|
||||
--url env://src \
|
||||
--format '{{ sql . }}'
|
||||
```
|
||||
|
||||
The command above prints the following SQL. Note, the `address` composite type is defined in the schema before
|
||||
its usage in the `address` field:
|
||||
|
||||
```sql
|
||||
-- Create composite type "address"
|
||||
CREATE TYPE "address" AS ("street" text, "city" text);
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "address" "address" NOT NULL, PRIMARY KEY ("id"));
|
||||
```
|
||||
|
||||
#### Generate Migrations For the Schema
|
||||
|
||||
To generate a migration for the schema, run the following command:
|
||||
|
||||
```shell
|
||||
atlas migrate diff \
|
||||
--env local
|
||||
```
|
||||
|
||||
Note that a new migration file is created with the following content:
|
||||
|
||||
```sql title="migrations/20240712090543.sql"
|
||||
-- Create composite type "address"
|
||||
CREATE TYPE "address" AS ("street" text, "city" text);
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "address" "address" NOT NULL, PRIMARY KEY ("id"));
|
||||
```
|
||||
|
||||
#### Apply the Migrations
|
||||
|
||||
To apply the migration generated above to a database, run the following command:
|
||||
|
||||
```
|
||||
atlas migrate apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
:::info Apply the Schema Directly on the Database
|
||||
|
||||
Sometimes, there is a need to apply the schema directly to the database without generating a migration file. For example,
|
||||
when experimenting with schema changes, spinning up a database for testing, etc. In such cases, you can use the command
|
||||
below to apply the schema directly to the database:
|
||||
|
||||
```shell
|
||||
atlas schema apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
Or, using the [Atlas Go SDK](https://github.com/ariga/atlas-go-sdk):
|
||||
|
||||
```go
|
||||
ac, err := atlasexec.NewClient(".", "atlas")
|
||||
if err != nil {
|
||||
log.Fatalf("failed to initialize client: %w", err)
|
||||
}
|
||||
// Automatically update the database with the desired schema.
|
||||
// Another option, is to use 'migrate apply' or 'schema apply' manually.
|
||||
if _, err := ac.SchemaApply(ctx, &atlasexec.SchemaApplyParams{
|
||||
Env: "local",
|
||||
URL: "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable",
|
||||
AutoApprove: true,
|
||||
}); err != nil {
|
||||
log.Fatalf("failed to apply schema changes: %w", err)
|
||||
}
|
||||
```
|
||||
|
||||
:::
|
||||
|
||||
The code for this guide can be found in [GitHub](https://github.com/ent/ent/tree/master/examples/compositetypes).
|
||||
208
doc/md/migration/domain.mdx
Normal file
208
doc/md/migration/domain.mdx
Normal file
@@ -0,0 +1,208 @@
|
||||
---
|
||||
title: Using Domain Types in Ent Schema
|
||||
id: domain
|
||||
slug: domain-types
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import InstallationInstructions from '../components/_installation_instructions.mdx';
|
||||
|
||||
PostgreSQL domain types are user-defined data types that extend existing ones, allowing you to add constraints that
|
||||
restrict the values they can hold. Setting a field type as a domain type enables you to enforce data integrity and
|
||||
validation rules at the database level.
|
||||
|
||||
This guide explains how to define a schema field type as a domain type in your Ent schema and configure the schema migration
|
||||
to manage both the domains and the Ent schema as a single migration unit using Atlas.
|
||||
|
||||
:::info [Atlas Pro Feature](https://atlasgo.io/features#pro-plan)
|
||||
Atlas support for [Domain Types](https://atlasgo.io/atlas-schema/hcl#domain) is available exclusively to Pro users.
|
||||
To use this feature, run:
|
||||
```
|
||||
atlas login
|
||||
```
|
||||
:::
|
||||
|
||||
## Install Atlas
|
||||
|
||||
<InstallationInstructions />
|
||||
|
||||
## Login to Atlas
|
||||
|
||||
```shell
|
||||
$ atlas login a8m
|
||||
//highlight-next-line-info
|
||||
You are now connected to "a8m" on Atlas Cloud.
|
||||
```
|
||||
|
||||
## Composite Schema
|
||||
|
||||
An `ent/schema` package is mostly used for defining Ent types (objects), their fields, edges and logic. Domain types,
|
||||
or any other database objects do not have representation in Ent models - A domain type can be defined once,
|
||||
and may be used multiple times in different fields and models.
|
||||
|
||||
In order to extend our PostgreSQL schema to include both custom domain types and our Ent types, we configure Atlas to
|
||||
read the state of the schema from a [Composite Schema](https://atlasgo.io/atlas-schema/projects#data-source-composite_schema)
|
||||
data source. Follow the steps below to configure this for your project:
|
||||
|
||||
1\. Create a `schema.sql` that defines the necessary domain type. In the same way, you can configure the domain type in
|
||||
[Atlas Schema HCL language](https://atlasgo.io/atlas-schema/hcl-types#domain):
|
||||
|
||||
<Tabs>
|
||||
<TabItem value={"sql"} label={"Using SQL"}>
|
||||
|
||||
```sql title="schema.sql"
|
||||
CREATE DOMAIN us_postal_code AS TEXT
|
||||
CHECK(
|
||||
VALUE ~ '^\d{5}$'
|
||||
OR VALUE ~ '^\d{5}-\d{4}$'
|
||||
);
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value={"hcl"} label={"Using HCL"}>
|
||||
|
||||
```hcl title="schema.hcl"
|
||||
schema "public" {}
|
||||
|
||||
domain "us_postal_code" {
|
||||
schema = schema.public
|
||||
type = text
|
||||
null = true
|
||||
check "us_postal_code_check" {
|
||||
expr = "((VALUE ~ '^\\d{5}$'::text) OR (VALUE ~ '^\\d{5}-\\d{4}$'::text))"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
2\. In your Ent schema, define a field that uses the domain type only in PostgreSQL dialect:
|
||||
|
||||
```go title="ent/schema/user.go" {5-7}
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("postal_code").
|
||||
SchemaType(map[string]string{
|
||||
dialect.Postgres: "us_postal_code",
|
||||
}),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
:::note
|
||||
In case a schema with custom driver-specific types is used with other databases, Ent falls back to the default type
|
||||
used by the driver (e.g., "varchar").
|
||||
:::
|
||||
|
||||
3\. Create a simple `atlas.hcl` config file with a `composite_schema` that includes both your custom types defined in
|
||||
`schema.sql` and your Ent schema:
|
||||
|
||||
```hcl title="atlas.hcl"
|
||||
data "composite_schema" "app" {
|
||||
# Load first custom types first.
|
||||
schema "public" {
|
||||
url = "file://schema.sql"
|
||||
}
|
||||
# Second, load the Ent schema.
|
||||
schema "public" {
|
||||
url = "ent://ent/schema"
|
||||
}
|
||||
}
|
||||
|
||||
env "local" {
|
||||
src = data.composite_schema.app.url
|
||||
dev = "docker://postgres/15/dev?search_path=public"
|
||||
}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
After setting up our schema, we can get its representation using the `atlas schema inspect` command, generate migrations for
|
||||
it, apply them to a database, and more. Below are a few commands to get you started with Atlas:
|
||||
|
||||
#### Inspect the Schema
|
||||
|
||||
The `atlas schema inspect` command is commonly used to inspect databases. However, we can also use it to inspect our
|
||||
`composite_schema` and print the SQL representation of it:
|
||||
|
||||
```shell
|
||||
atlas schema inspect \
|
||||
--env local \
|
||||
--url env://src \
|
||||
--format '{{ sql . }}'
|
||||
```
|
||||
|
||||
The command above prints the following SQL. Note, the `us_postal_code` domain type is defined in the schema before
|
||||
its usage in the `postal_code` field:
|
||||
|
||||
```sql
|
||||
-- Create domain type "us_postal_code"
|
||||
CREATE DOMAIN "us_postal_code" AS text CONSTRAINT "us_postal_code_check" CHECK ((VALUE ~ '^\d{5}$'::text) OR (VALUE ~ '^\d{5}-\d{4}$'::text));
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "postal_code" "us_postal_code" NOT NULL, PRIMARY KEY ("id"));
|
||||
```
|
||||
|
||||
#### Generate Migrations For the Schema
|
||||
|
||||
To generate a migration for the schema, run the following command:
|
||||
|
||||
```shell
|
||||
atlas migrate diff \
|
||||
--env local
|
||||
```
|
||||
|
||||
Note that a new migration file is created with the following content:
|
||||
|
||||
```sql title="migrations/20240712090543.sql"
|
||||
-- Create domain type "us_postal_code"
|
||||
CREATE DOMAIN "us_postal_code" AS text CONSTRAINT "us_postal_code_check" CHECK ((VALUE ~ '^\d{5}$'::text) OR (VALUE ~ '^\d{5}-\d{4}$'::text));
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "postal_code" "us_postal_code" NOT NULL, PRIMARY KEY ("id"));
|
||||
```
|
||||
|
||||
#### Apply the Migrations
|
||||
|
||||
To apply the migration generated above to a database, run the following command:
|
||||
|
||||
```
|
||||
atlas migrate apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
:::info Apply the Schema Directly on the Database
|
||||
|
||||
Sometimes, there is a need to apply the schema directly to the database without generating a migration file. For example,
|
||||
when experimenting with schema changes, spinning up a database for testing, etc. In such cases, you can use the command
|
||||
below to apply the schema directly to the database:
|
||||
|
||||
```shell
|
||||
atlas schema apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
Or, using the [Atlas Go SDK](https://github.com/ariga/atlas-go-sdk):
|
||||
|
||||
```go
|
||||
ac, err := atlasexec.NewClient(".", "atlas")
|
||||
if err != nil {
|
||||
log.Fatalf("failed to initialize client: %w", err)
|
||||
}
|
||||
// Automatically update the database with the desired schema.
|
||||
// Another option, is to use 'migrate apply' or 'schema apply' manually.
|
||||
if _, err := ac.SchemaApply(ctx, &atlasexec.SchemaApplyParams{
|
||||
Env: "local",
|
||||
URL: "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable",
|
||||
AutoApprove: true,
|
||||
}); err != nil {
|
||||
log.Fatalf("failed to apply schema changes: %w", err)
|
||||
}
|
||||
```
|
||||
|
||||
:::
|
||||
|
||||
The code for this guide can be found in [GitHub](https://github.com/ent/ent/tree/master/examples/domaintypes).
|
||||
202
doc/md/migration/enum.mdx
Normal file
202
doc/md/migration/enum.mdx
Normal file
@@ -0,0 +1,202 @@
|
||||
---
|
||||
title: Using Postgres Enum Types in Ent Schema
|
||||
id: enum
|
||||
slug: enum-types
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import InstallationInstructions from '../components/_installation_instructions.mdx';
|
||||
|
||||
|
||||
Enum types are data structures that consist of a predefined, ordered set of values. By default, when using `field.Enum`
|
||||
in your Ent schema, Ent uses simple string types to represent the enum values in **PostgreSQL and SQLite**. However, in some
|
||||
cases, you may want to use the native enum types provided by the database.
|
||||
|
||||
This guide explains how to define a schema field that uses a native PostgreSQL enum type and configure the schema migration
|
||||
to manage both Postgres enums and the Ent schema as a single migration unit using Atlas.
|
||||
|
||||
:::info [Atlas Pro Feature](https://atlasgo.io/features#pro-plan)
|
||||
Atlas support for [Composite Schema](https://atlasgo.io/atlas-schema/projects#data-source-composite_schema) used in this
|
||||
guide is available exclusively to Pro users. To use this feature, run:
|
||||
```
|
||||
atlas login
|
||||
```
|
||||
:::
|
||||
|
||||
## Install Atlas
|
||||
|
||||
<InstallationInstructions />
|
||||
|
||||
## Login to Atlas
|
||||
|
||||
```shell
|
||||
$ atlas login a8m
|
||||
//highlight-next-line-info
|
||||
You are now connected to "a8m" on Atlas Cloud.
|
||||
```
|
||||
|
||||
## Composite Schema
|
||||
|
||||
An `ent/schema` package is mostly used for defining Ent types (objects), their fields, edges and logic. External enum types,
|
||||
or any other database objects do not have representation in Ent models - A Postgres enum type can be defined once in your Postgres
|
||||
schema, and may be used multiple times in different fields and models.
|
||||
|
||||
In order to extend our PostgreSQL schema to include both custom enum types and our Ent types, we configure Atlas to
|
||||
read the state of the schema from a [Composite Schema](https://atlasgo.io/atlas-schema/projects#data-source-composite_schema)
|
||||
data source. Follow the steps below to configure this for your project:
|
||||
|
||||
1\. Create a `schema.sql` that defines the necessary enum type there. In the same way, you can define the enum type in
|
||||
[Atlas Schema HCL language](https://atlasgo.io/atlas-schema/hcl-types#enum):
|
||||
|
||||
<Tabs>
|
||||
<TabItem value={"sql"} label={"Using SQL"}>
|
||||
|
||||
```sql title="schema.sql"
|
||||
CREATE TYPE status AS ENUM ('active', 'inactive', 'pending');
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value={"hcl"} label={"Using HCL"}>
|
||||
|
||||
```hcl title="schema.hcl"
|
||||
schema "public" {}
|
||||
|
||||
enum "status" {
|
||||
schema = schema.public
|
||||
values = ["active", "inactive", "pending"]
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
2\. In your Ent schema, define an enum field that uses the underlying Postgres `ENUM` type:
|
||||
|
||||
```go title="ent/schema/user.go" {6-8}
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Enum("status").
|
||||
Values("active", "inactive", "pending").
|
||||
SchemaType(map[string]string{
|
||||
dialect.Postgres: "status",
|
||||
}),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
:::note
|
||||
In case a schema with custom driver-specific types is used with other databases, Ent falls back to the default type
|
||||
used by the driver (e.g., `TEXT` in SQLite and `ENUM (...)` in MariaDB or MySQL)s.
|
||||
:::
|
||||
|
||||
3\. Create a simple `atlas.hcl` config file with a `composite_schema` that includes both your custom enum types defined in
|
||||
`schema.sql` and your Ent schema:
|
||||
|
||||
```hcl title="atlas.hcl"
|
||||
data "composite_schema" "app" {
|
||||
# Load first custom types first.
|
||||
schema "public" {
|
||||
url = "file://schema.sql"
|
||||
}
|
||||
# Second, load the Ent schema.
|
||||
schema "public" {
|
||||
url = "ent://ent/schema"
|
||||
}
|
||||
}
|
||||
|
||||
env "local" {
|
||||
src = data.composite_schema.app.url
|
||||
dev = "docker://postgres/15/dev?search_path=public"
|
||||
}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
After setting up our composite schema, we can get its representation using the `atlas schema inspect` command, generate
|
||||
schema migrations for it, apply them to a database, and more. Below are a few commands to get you started with Atlas:
|
||||
|
||||
#### Inspect the Schema
|
||||
|
||||
The `atlas schema inspect` command is commonly used to inspect databases. However, we can also use it to inspect our
|
||||
`composite_schema` and print the SQL representation of it:
|
||||
|
||||
```shell
|
||||
atlas schema inspect \
|
||||
--env local \
|
||||
--url env://src \
|
||||
--format '{{ sql . }}'
|
||||
```
|
||||
|
||||
The command above prints the following SQL. Note, the `status` enum type is defined in the schema before
|
||||
its usage in the `users.status` column:
|
||||
|
||||
```sql
|
||||
-- Create enum type "status"
|
||||
CREATE TYPE "status" AS ENUM ('active', 'inactive', 'pending');
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "status" "status" NOT NULL, PRIMARY KEY ("id"));
|
||||
```
|
||||
|
||||
#### Generate Migrations For the Schema
|
||||
|
||||
To generate a migration for the schema, run the following command:
|
||||
|
||||
```shell
|
||||
atlas migrate diff \
|
||||
--env local
|
||||
```
|
||||
|
||||
Note that a new migration file is created with the following content:
|
||||
|
||||
```sql title="migrations/20240712090543.sql"
|
||||
-- Create enum type "status"
|
||||
CREATE TYPE "status" AS ENUM ('active', 'inactive', 'pending');
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "status" "status" NOT NULL, PRIMARY KEY ("id"));
|
||||
```
|
||||
|
||||
#### Apply the Migrations
|
||||
|
||||
To apply the migration generated above to a database, run the following command:
|
||||
|
||||
```
|
||||
atlas migrate apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
:::info Apply the Schema Directly on the Database
|
||||
|
||||
Sometimes, there is a need to apply the schema directly to the database without generating a migration file. For example,
|
||||
when experimenting with schema changes, spinning up a database for testing, etc. In such cases, you can use the command
|
||||
below to apply the schema directly to the database:
|
||||
|
||||
```shell
|
||||
atlas schema apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
Or, using the [Atlas Go SDK](https://github.com/ariga/atlas-go-sdk):
|
||||
|
||||
```go
|
||||
ac, err := atlasexec.NewClient(".", "atlas")
|
||||
if err != nil {
|
||||
log.Fatalf("failed to initialize client: %w", err)
|
||||
}
|
||||
// Automatically update the database with the desired schema.
|
||||
// Another option, is to use 'migrate apply' or 'schema apply' manually.
|
||||
if _, err := ac.SchemaApply(ctx, &atlasexec.SchemaApplyParams{
|
||||
Env: "local",
|
||||
URL: "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable",
|
||||
AutoApprove: true,
|
||||
}); err != nil {
|
||||
log.Fatalf("failed to apply schema changes: %w", err)
|
||||
}
|
||||
```
|
||||
|
||||
:::
|
||||
|
||||
The code for this guide can be found in [GitHub](https://github.com/ent/ent/tree/master/examples/enumtypes).
|
||||
223
doc/md/migration/extension.mdx
Normal file
223
doc/md/migration/extension.mdx
Normal file
@@ -0,0 +1,223 @@
|
||||
---
|
||||
title: Using Postgres Extensions in Ent Schema
|
||||
id: extension
|
||||
slug: extensions
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import InstallationInstructions from '../components/_installation_instructions.mdx';
|
||||
|
||||
|
||||
[Postgres extensions](https://www.postgresql.org/docs/current/sql-createextension.html) are add-on modules that extend
|
||||
the functionality of the database by providing new data types, operators, functions, procedural languages, and more.
|
||||
|
||||
This guide explains how to define a schema field that uses a data type provided by the PostGIS extension, and configure
|
||||
the schema migration to manage both Postgres extension installations and the Ent schema as a single migration unit using
|
||||
Atlas.
|
||||
|
||||
:::info [Atlas Pro Feature](https://atlasgo.io/features#pro-plan)
|
||||
Atlas support for [Extensions](https://atlasgo.io/atlas-schema/hcl#extension) is available exclusively to Pro users.
|
||||
To use this feature, run:
|
||||
```
|
||||
atlas login
|
||||
```
|
||||
:::
|
||||
|
||||
## Install Atlas
|
||||
|
||||
<InstallationInstructions />
|
||||
|
||||
## Login to Atlas
|
||||
|
||||
```shell
|
||||
$ atlas login a8m
|
||||
//highlight-next-line-info
|
||||
You are now connected to "a8m" on Atlas Cloud.
|
||||
```
|
||||
|
||||
## Composite Schema
|
||||
|
||||
An `ent/schema` package is mostly used for defining Ent types (objects), their fields, edges and logic. Extensions like
|
||||
`postgis` or `hstore` do not have representation in Ent schema. A Postgres extension can be installed once in your
|
||||
Postgres database, and may be used multiple times in different schemas.
|
||||
|
||||
In order to extend our PostgreSQL schema migration to include both extensions and our Ent types, we configure Atlas to
|
||||
read the state of the schema from a [Composite Schema](https://atlasgo.io/atlas-schema/projects#data-source-composite_schema)
|
||||
data source. Follow the steps below to configure this for your project:
|
||||
|
||||
1\. Create a `schema.sql` that defines the necessary extensions used by your database. In the same way, you can define
|
||||
the extensions in [Atlas Schema HCL language](https://atlasgo.io/atlas-schema/hcl-types#extension):
|
||||
|
||||
<Tabs>
|
||||
<TabItem value={"sql"} label={"Using SQL"}>
|
||||
|
||||
```sql title="schema.sql"
|
||||
-- Install PostGIS extension.
|
||||
CREATE EXTENSION postgis;
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value={"hcl"} label={"Using HCL"}>
|
||||
|
||||
```hcl title="schema.hcl"
|
||||
schema "public" {}
|
||||
|
||||
extension "postgis" {
|
||||
schema = schema.public
|
||||
version = "3.4.2"
|
||||
comment = "PostGIS geometry and geography spatial types and functions"
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
2\. In your Ent schema, define a field that uses the data type provided by the extension. In this example, we use the
|
||||
`GEOMETRY(Point, 4326)` data type provided by the `postgis` extension:
|
||||
|
||||
```go title="ent/schema/user.go" {7-9}
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Bytes("location").
|
||||
// Ideally, we would use a custom GoType
|
||||
// to represent the "geometry" type.
|
||||
SchemaType(map[string]string{
|
||||
dialect.Postgres: "GEOMETRY(Point, 4326)",
|
||||
}),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
3\. Create a simple `atlas.hcl` config file with a `composite_schema` that includes both the extensions defined in
|
||||
`schema.sql` and your Ent schema:
|
||||
|
||||
```hcl title="atlas.hcl"
|
||||
data "composite_schema" "app" {
|
||||
# Install extensions first (PostGIS).
|
||||
schema "public" {
|
||||
url = "file://schema.sql"
|
||||
}
|
||||
# Then, load the Ent schema.
|
||||
schema "public" {
|
||||
url = "ent://ent/schema"
|
||||
}
|
||||
}
|
||||
|
||||
env "local" {
|
||||
src = data.composite_schema.app.url
|
||||
dev = "docker://postgis/latest/dev"
|
||||
format {
|
||||
migrate {
|
||||
diff = "{{ sql . \" \" }}"
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
After setting up our composite schema, we can get its representation using the `atlas schema inspect` command, generate
|
||||
schema migrations for it, apply them to a database, and more. Below are a few commands to get you started with Atlas:
|
||||
|
||||
#### Inspect the Schema
|
||||
|
||||
The `atlas schema inspect` command is commonly used to inspect databases. However, we can also use it to inspect our
|
||||
`composite_schema` and print the SQL representation of it:
|
||||
|
||||
```shell
|
||||
atlas schema inspect \
|
||||
--env local \
|
||||
--url env://src \
|
||||
--format '{{ sql . }}'
|
||||
```
|
||||
|
||||
The command above prints the following SQL.
|
||||
|
||||
```sql
|
||||
-- Add new schema named "public"
|
||||
CREATE SCHEMA IF NOT EXISTS "public";
|
||||
-- Set comment to schema: "public"
|
||||
COMMENT ON SCHEMA "public" IS 'standard public schema';
|
||||
-- Create extension "postgis"
|
||||
CREATE EXTENSION "postgis" WITH SCHEMA "public" VERSION "3.4.2";
|
||||
-- Create "users" table
|
||||
CREATE TABLE "public"."users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "location" public.geometry(point,4326) NOT NULL, PRIMARY KEY ("id"));
|
||||
```
|
||||
|
||||
:::info Extensions Are Database-Level Objects
|
||||
Although the `SCHEMA` argument is supported by the `CREATE EXTENSION` command, it only indicates where the extension's
|
||||
objects will be installed. The extension itself is installed at the database level and cannot be loaded multiple times
|
||||
into different schemas.
|
||||
|
||||
Therefore, to avoid conflicts with other schemas, when working with extensions, the scope of the migration should be set
|
||||
to the database, where objects are qualified with the schema name. Hence, the `search_path` is dropped from the dev-database
|
||||
URL in the `atlas.hcl` file.
|
||||
:::
|
||||
|
||||
#### Generate Migrations For the Schema
|
||||
|
||||
To generate a migration for the schema, run the following command:
|
||||
|
||||
```shell
|
||||
atlas migrate diff \
|
||||
--env local
|
||||
```
|
||||
|
||||
Note that a new migration file is created with the following content:
|
||||
|
||||
```sql title="migrations/20240712090543.sql"
|
||||
-- Create extension "postgis"
|
||||
CREATE EXTENSION "postgis" WITH SCHEMA "public" VERSION "3.4.2";
|
||||
-- Create "users" table
|
||||
CREATE TABLE "public"."users" (
|
||||
"id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY,
|
||||
"location" public.geometry(point,4326) NOT NULL,
|
||||
PRIMARY KEY ("id")
|
||||
);
|
||||
```
|
||||
|
||||
#### Apply the Migrations
|
||||
|
||||
To apply the migration generated above to a database, run the following command:
|
||||
|
||||
```
|
||||
atlas migrate apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
:::info Apply the Schema Directly on the Database
|
||||
|
||||
Sometimes, there is a need to apply the schema directly to the database without generating a migration file. For example,
|
||||
when experimenting with schema changes, spinning up a database for testing, etc. In such cases, you can use the command
|
||||
below to apply the schema directly to the database:
|
||||
|
||||
```shell
|
||||
atlas schema apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?sslmode=disable"
|
||||
```
|
||||
|
||||
Or, using the [Atlas Go SDK](https://github.com/ariga/atlas-go-sdk):
|
||||
|
||||
```go
|
||||
ac, err := atlasexec.NewClient(".", "atlas")
|
||||
if err != nil {
|
||||
log.Fatalf("failed to initialize client: %w", err)
|
||||
}
|
||||
// Automatically update the database with the desired schema.
|
||||
// Another option, is to use 'migrate apply' or 'schema apply' manually.
|
||||
if _, err := ac.SchemaApply(ctx, &atlasexec.SchemaApplyParams{
|
||||
Env: "local",
|
||||
URL: "postgres://postgres:pass@localhost:5432/database?sslmode=disable",
|
||||
AutoApprove: true,
|
||||
}); err != nil {
|
||||
log.Fatalf("failed to apply schema changes: %w", err)
|
||||
}
|
||||
```
|
||||
|
||||
:::
|
||||
|
||||
The code for this guide can be found in [GitHub](https://github.com/ent/ent/tree/master/examples/enumtypes).
|
||||
200
doc/md/migration/functional-indexes.mdx
Normal file
200
doc/md/migration/functional-indexes.mdx
Normal file
@@ -0,0 +1,200 @@
|
||||
---
|
||||
title: Using Functional Indexes in Ent Schema
|
||||
id: functional-indexes
|
||||
slug: functional-indexes
|
||||
---
|
||||
|
||||
import InstallationInstructions from '../components/_installation_instructions.mdx';
|
||||
|
||||
A functional index is an index whose key parts are based on expression values, rather than column values. This index
|
||||
type is helpful for indexing the results of functions or expressions that are not stored in the table. Supported by
|
||||
[MySQL, MariaDB](https://atlasgo.io/guides/mysql/functional-indexes), [PostgreSQL](https://atlasgo.io/guides/postgres/functional-indexes)
|
||||
and [SQLite](https://atlasgo.io/guides/sqlite/functional-indexes).
|
||||
|
||||
This guide explains how to extend your Ent schema with functional indexes, and configure the schema migration to manage
|
||||
both functional indexes and the Ent schema as a single migration unit using Atlas.
|
||||
|
||||
:::info [Atlas Pro Feature](https://atlasgo.io/features#pro-plan)
|
||||
Atlas support for [Composite Schema](https://atlasgo.io/atlas-schema/projects#data-source-composite_schema) used in this
|
||||
guide is available exclusively to Pro users. To use this feature, run:
|
||||
```
|
||||
atlas login
|
||||
```
|
||||
:::
|
||||
|
||||
## Install Atlas
|
||||
|
||||
<InstallationInstructions />
|
||||
|
||||
## Login to Atlas
|
||||
|
||||
```shell
|
||||
$ atlas login a8m
|
||||
//highlight-next-line-info
|
||||
You are now connected to "a8m" on Atlas Cloud.
|
||||
```
|
||||
|
||||
## Composite Schema
|
||||
|
||||
An `ent/schema` package is mostly used for defining Ent types (objects), their fields, edges and logic. Functional indexes,
|
||||
do not have representation in Ent schema, as Ent supports defining indexes on fields, edges (foreign-keys), and the combination
|
||||
of them.
|
||||
|
||||
In order to extend our PostgreSQL schema migration with functional indexes to our Ent types (tables), we configure Atlas to
|
||||
read the state of the schema from a [Composite Schema](https://atlasgo.io/atlas-schema/projects#data-source-composite_schema)
|
||||
data source. Follow the steps below to configure this for your project:
|
||||
|
||||
1\. Let's define a simple schema with one type (table): `User` (table `users`):
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
Comment("A unique index is defined on lower(name) in schema.sql"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
2\. Next step, we define a functional index on the `name` field in the `schema.sql` file:
|
||||
|
||||
```sql title="schema.sql" {2}
|
||||
-- Create a functional (unique) index on the lowercased name column.
|
||||
CREATE UNIQUE INDEX unique_name ON "users" ((lower("name")));
|
||||
```
|
||||
|
||||
3\. Create a simple `atlas.hcl` config file with a `composite_schema` that includes both the functional indexes defined in
|
||||
`schema.sql` and your Ent schema:
|
||||
|
||||
```hcl title="atlas.hcl"
|
||||
data "composite_schema" "app" {
|
||||
# Load the ent schema first with all tables.
|
||||
schema "public" {
|
||||
url = "ent://ent/schema"
|
||||
}
|
||||
# Then, load the functional indexes.
|
||||
schema "public" {
|
||||
url = "file://schema.sql"
|
||||
}
|
||||
}
|
||||
|
||||
env "local" {
|
||||
src = data.composite_schema.app.url
|
||||
dev = "docker://postgres/15/dev?search_path=public"
|
||||
}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
After setting up our composite schema, we can get its representation using the `atlas schema inspect` command, generate
|
||||
schema migrations for it, apply them to a database, and more. Below are a few commands to get you started with Atlas:
|
||||
|
||||
#### Inspect the Schema
|
||||
|
||||
The `atlas schema inspect` command is commonly used to inspect databases. However, we can also use it to inspect our
|
||||
`composite_schema` and print the SQL representation of it:
|
||||
|
||||
```shell
|
||||
atlas schema inspect \
|
||||
--env local \
|
||||
--url env://src \
|
||||
--format '{{ sql . }}'
|
||||
```
|
||||
|
||||
The command above prints the following SQL.
|
||||
|
||||
```sql
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "name" character varying NOT NULL, PRIMARY KEY ("id"));
|
||||
-- Create index "unique_name" to table: "users"
|
||||
CREATE UNIQUE INDEX "unique_name" ON "users" ((lower((name)::text)));
|
||||
```
|
||||
|
||||
Note, our functional index is defined on the `name` field in the `users` table.
|
||||
|
||||
#### Generate Migrations For the Schema
|
||||
|
||||
To generate a migration for the schema, run the following command:
|
||||
|
||||
```shell
|
||||
atlas migrate diff \
|
||||
--env local
|
||||
```
|
||||
|
||||
Note that a new migration file is created with the following content:
|
||||
|
||||
```sql title="migrations/20240712090543.sql"
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "name" character varying NOT NULL, PRIMARY KEY ("id"));
|
||||
-- Create index "unique_name" to table: "users"
|
||||
CREATE UNIQUE INDEX "unique_name" ON "users" ((lower((name)::text)));
|
||||
```
|
||||
|
||||
#### Apply the Migrations
|
||||
|
||||
To apply the migration generated above to a database, run the following command:
|
||||
|
||||
```
|
||||
atlas migrate apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
:::info Apply the Schema Directly on the Database
|
||||
|
||||
Sometimes, there is a need to apply the schema directly to the database without generating a migration file. For example,
|
||||
when experimenting with schema changes, spinning up a database for testing, etc. In such cases, you can use the command
|
||||
below to apply the schema directly to the database:
|
||||
|
||||
```shell
|
||||
atlas schema apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?sslmode=disable"
|
||||
```
|
||||
|
||||
Or, using the [Atlas Go SDK](https://github.com/ariga/atlas-go-sdk):
|
||||
|
||||
```go
|
||||
ac, err := atlasexec.NewClient(".", "atlas")
|
||||
if err != nil {
|
||||
log.Fatalf("failed to initialize client: %w", err)
|
||||
}
|
||||
// Automatically update the database with the desired schema.
|
||||
// Another option, is to use 'migrate apply' or 'schema apply' manually.
|
||||
if _, err := ac.SchemaApply(ctx, &atlasexec.SchemaApplyParams{
|
||||
Env: "local",
|
||||
URL: "postgres://postgres:pass@localhost:5432/database?sslmode=disable",
|
||||
AutoApprove: true,
|
||||
}); err != nil {
|
||||
log.Fatalf("failed to apply schema changes: %w", err)
|
||||
}
|
||||
```
|
||||
|
||||
:::
|
||||
|
||||
## Code Example
|
||||
|
||||
After setting up our Ent schema with functional indexes, we expect the database to enforce the uniqueness of the `name`
|
||||
field in the `users` table:
|
||||
|
||||
```go
|
||||
// Test that the unique index is enforced.
|
||||
client.User.Create().SetName("Ariel").SaveX(ctx)
|
||||
err = client.User.Create().SetName("ariel").Exec(ctx)
|
||||
require.EqualError(t, err, `ent: constraint failed: pq: duplicate key value violates unique constraint "unique_name"`)
|
||||
|
||||
// Type-assert returned error.
|
||||
var pqerr *pq.Error
|
||||
require.True(t, errors.As(err, &pqerr))
|
||||
require.Equal(t, `duplicate key value violates unique constraint "unique_name"`, pqerr.Message)
|
||||
require.Equal(t, user.Table, pqerr.Table)
|
||||
require.Equal(t, "unique_name", pqerr.Constraint)
|
||||
require.Equal(t, pq.ErrorCode("23505"), pqerr.Code, "unique violation")
|
||||
```
|
||||
|
||||
The code for this guide can be found in [GitHub](https://github.com/ent/ent/tree/master/examples/functionalidx).
|
||||
227
doc/md/migration/rls.mdx
Normal file
227
doc/md/migration/rls.mdx
Normal file
@@ -0,0 +1,227 @@
|
||||
---
|
||||
title: Using Row-Level Security in Ent Schema
|
||||
id: rls
|
||||
slug: row-level-security
|
||||
---
|
||||
|
||||
import InstallationInstructions from '../components/_installation_instructions.mdx';
|
||||
|
||||
Row-level security (RLS) in PostgreSQL enables tables to implement policies that limit access or modification of rows
|
||||
according to the user's role, enhancing the basic SQL-standard privileges provided by `GRANT`.
|
||||
|
||||
Once activated, every standard access to the table has to adhere to these policies. If no policies are defined on the table,
|
||||
it defaults to a deny-all rule, meaning no rows can be seen or mutated. These policies can be tailored to specific commands,
|
||||
roles, or both, allowing for detailed management of who can access or change data.
|
||||
|
||||
This guide explains how to attach Row-Level Security (RLS) Policies to your Ent types (objects) and configure the schema
|
||||
migration to manage both the RLS and the Ent schema as a single migration unit using Atlas.
|
||||
|
||||
:::info [Atlas Pro Feature](https://atlasgo.io/features#pro-plan)
|
||||
|
||||
Atlas support for [Row-Level Security Policies](https://atlasgo.io/atlas-schema/hcl#row-level-security-policy) used in
|
||||
this guide is available exclusively to Pro users. To use this feature, run:
|
||||
|
||||
```
|
||||
atlas login
|
||||
```
|
||||
|
||||
:::
|
||||
|
||||
## Install Atlas
|
||||
|
||||
<InstallationInstructions />
|
||||
|
||||
## Login to Atlas
|
||||
|
||||
```shell
|
||||
$ atlas login a8m
|
||||
//highlight-next-line-info
|
||||
You are now connected to "a8m" on Atlas Cloud.
|
||||
```
|
||||
|
||||
## Composite Schema
|
||||
|
||||
An `ent/schema` package is mostly used for defining Ent types (objects), their fields, edges and logic. Table policies
|
||||
or any other database native objects do not have representation in Ent models.
|
||||
|
||||
In order to extend our PostgreSQL schema to include both our Ent types and their policies, we configure Atlas to
|
||||
read the state of the schema from a [Composite Schema](https://atlasgo.io/atlas-schema/projects#data-source-composite_schema)
|
||||
data source. Follow the steps below to configure this for your project:
|
||||
|
||||
1\. Let's define a simple schema with two types (tables): `users` and `tenants`:
|
||||
|
||||
```go title="ent/schema/tenant.go"
|
||||
// Tenant holds the schema definition for the Tenant entity.
|
||||
type Tenant struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Tenant.
|
||||
func (Tenant) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.Int("tenant_id"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
2\. Now, suppose we want to limit access to the `users` table based on the `tenant_id` field. We can achieve this by defining
|
||||
a Row-Level Security (RLS) policy on the `users` table. Below is the SQL code that defines the RLS policy:
|
||||
|
||||
```sql title="schema.sql"
|
||||
--- Enable row-level security on the users table.
|
||||
ALTER TABLE "users" ENABLE ROW LEVEL SECURITY;
|
||||
|
||||
-- Create a policy that restricts access to rows in the users table based on the current tenant.
|
||||
CREATE POLICY tenant_isolation ON "users"
|
||||
USING ("tenant_id" = current_setting('app.current_tenant')::integer);
|
||||
```
|
||||
|
||||
|
||||
3\. Lastly, we create a simple `atlas.hcl` config file with a `composite_schema` that includes both our Ent schema and
|
||||
the custom security policies defined in `schema.sql`:
|
||||
|
||||
```hcl title="atlas.hcl"
|
||||
data "composite_schema" "app" {
|
||||
# Load the ent schema first with all tables.
|
||||
schema "public" {
|
||||
url = "ent://ent/schema"
|
||||
}
|
||||
# Then, load the RLS schema.
|
||||
schema "public" {
|
||||
url = "file://schema.sql"
|
||||
}
|
||||
}
|
||||
|
||||
env "local" {
|
||||
src = data.composite_schema.app.url
|
||||
dev = "docker://postgres/15/dev?search_path=public"
|
||||
}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
After setting up our composite schema, we can get its representation using the `atlas schema inspect` command, generate
|
||||
schema migrations for it, apply them to a database, and more. Below are a few commands to get you started with Atlas:
|
||||
|
||||
#### Inspect the Schema
|
||||
|
||||
The `atlas schema inspect` command is commonly used to inspect databases. However, we can also use it to inspect our
|
||||
`composite_schema` and print the SQL representation of it:
|
||||
|
||||
```shell
|
||||
atlas schema inspect \
|
||||
--env local \
|
||||
--url env://src \
|
||||
--format '{{ sql . }}'
|
||||
```
|
||||
|
||||
The command above prints the following SQL. Note, the `tenant_isolation` policy is defined in the schema after the `users`
|
||||
table:
|
||||
|
||||
```sql
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "name" character varying NOT NULL, "tenant_id" bigint NOT NULL, PRIMARY KEY ("id"));
|
||||
-- Enable row-level security for "users" table
|
||||
ALTER TABLE "users" ENABLE ROW LEVEL SECURITY;
|
||||
-- Create policy "tenant_isolation"
|
||||
CREATE POLICY "tenant_isolation" ON "users" AS PERMISSIVE FOR ALL TO PUBLIC USING (tenant_id = (current_setting('app.current_tenant'::text))::integer);
|
||||
-- Create "tenants" table
|
||||
CREATE TABLE "tenants" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "name" character varying NOT NULL, PRIMARY KEY ("id"));
|
||||
```
|
||||
|
||||
#### Generate Migrations For the Schema
|
||||
|
||||
To generate a migration for the schema, run the following command:
|
||||
|
||||
```shell
|
||||
atlas migrate diff \
|
||||
--env local
|
||||
```
|
||||
|
||||
Note that a new migration file is created with the following content:
|
||||
|
||||
```sql title="migrations/20240712090543.sql"
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "name" character varying NOT NULL, "tenant_id" bigint NOT NULL, PRIMARY KEY ("id"));
|
||||
-- Enable row-level security for "users" table
|
||||
ALTER TABLE "users" ENABLE ROW LEVEL SECURITY;
|
||||
-- Create policy "tenant_isolation"
|
||||
CREATE POLICY "tenant_isolation" ON "users" AS PERMISSIVE FOR ALL TO PUBLIC USING (tenant_id = (current_setting('app.current_tenant'::text))::integer);
|
||||
-- Create "tenants" table
|
||||
CREATE TABLE "tenants" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "name" character varying NOT NULL, PRIMARY KEY ("id"));
|
||||
```
|
||||
|
||||
#### Apply the Migrations
|
||||
|
||||
To apply the migration generated above to a database, run the following command:
|
||||
|
||||
```
|
||||
atlas migrate apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
:::info Apply the Schema Directly on the Database
|
||||
|
||||
Sometimes, there is a need to apply the schema directly to the database without generating a migration file. For example,
|
||||
when experimenting with schema changes, spinning up a database for testing, etc. In such cases, you can use the command
|
||||
below to apply the schema directly to the database:
|
||||
|
||||
```shell
|
||||
atlas schema apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
Or, using the [Atlas Go SDK](https://github.com/ariga/atlas-go-sdk):
|
||||
|
||||
```go
|
||||
ac, err := atlasexec.NewClient(".", "atlas")
|
||||
if err != nil {
|
||||
log.Fatalf("failed to initialize client: %w", err)
|
||||
}
|
||||
// Automatically update the database with the desired schema.
|
||||
// Another option, is to use 'migrate apply' or 'schema apply' manually.
|
||||
if _, err := ac.SchemaApply(ctx, &atlasexec.SchemaApplyParams{
|
||||
Env: "local",
|
||||
URL: "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable",
|
||||
AutoApprove: true,
|
||||
}); err != nil {
|
||||
log.Fatalf("failed to apply schema changes: %w", err)
|
||||
}
|
||||
```
|
||||
|
||||
:::
|
||||
|
||||
## Code Example
|
||||
|
||||
After setting up our Ent schema and the RLS policies, we can open an Ent client and pass the different mutations and
|
||||
queries the relevant tenant ID we work on. This ensures that the database upholds our RLS policy:
|
||||
|
||||
```go
|
||||
ctx1, ctx2 := sql.WithIntVar(ctx, "app.current_tenant", a8m.ID), sql.WithIntVar(ctx, "app.current_tenant", r3m.ID)
|
||||
users1 := client.User.Query().AllX(ctx1)
|
||||
// Users1 can only see users from tenant a8m.
|
||||
users2 := client.User.Query().AllX(ctx2)
|
||||
// Users2 can only see users from tenant r3m.
|
||||
```
|
||||
|
||||
:::info Real World Example
|
||||
In real applications, users can utilize [hooks](/docs/hooks) and [interceptors](/docs/interceptors) to set the `app.current_tenant`
|
||||
variable based on the user's context.
|
||||
:::
|
||||
|
||||
The code for this guide can be found in [GitHub](https://github.com/ent/ent/tree/master/examples/rls).
|
||||
277
doc/md/migration/trigger.mdx
Normal file
277
doc/md/migration/trigger.mdx
Normal file
@@ -0,0 +1,277 @@
|
||||
---
|
||||
title: Using Database Triggers in Ent Schema
|
||||
id: trigger
|
||||
slug: triggers
|
||||
---
|
||||
|
||||
import InstallationInstructions from '../components/_installation_instructions.mdx';
|
||||
|
||||
Triggers are useful tools in relational databases that allow you to execute custom code when specific events occur on a
|
||||
table. For instance, triggers can automatically populate the audit log table whenever a new mutation is applied to a different table.
|
||||
This way we ensure that all changes (including those made by other applications) are meticulously recorded, enabling the enforcement
|
||||
on the database-level and reducing the need for additional code in the applications.
|
||||
|
||||
This guide explains how to attach triggers to your Ent types (objects) and configure the schema migration to manage
|
||||
both the triggers and the Ent schema as a single migration unit using Atlas.
|
||||
|
||||
:::info [Atlas Pro Feature](https://atlasgo.io/features#pro-plan)
|
||||
Atlas support for [Triggers](https://atlasgo.io/atlas-schema/hcl#trigger) used in this guide is available exclusively
|
||||
to Pro users. To use this feature, run:
|
||||
```
|
||||
atlas login
|
||||
```
|
||||
:::
|
||||
|
||||
## Install Atlas
|
||||
|
||||
<InstallationInstructions />
|
||||
|
||||
## Login to Atlas
|
||||
|
||||
```shell
|
||||
$ atlas login a8m
|
||||
//highlight-next-line-info
|
||||
You are now connected to "a8m" on Atlas Cloud.
|
||||
```
|
||||
|
||||
## Composite Schema
|
||||
|
||||
An `ent/schema` package is mostly used for defining Ent types (objects), their fields, edges and logic. Table triggers
|
||||
or any other database native objects do not have representation in Ent models. A trigger function can be defined once,
|
||||
and used in multiple triggers in different tables.
|
||||
|
||||
In order to extend our PostgreSQL schema to include both our Ent types and their triggers, we configure Atlas to
|
||||
read the state of the schema from a [Composite Schema](https://atlasgo.io/atlas-schema/projects#data-source-composite_schema)
|
||||
data source. Follow the steps below to configure this for your project:
|
||||
|
||||
1\. Let's define a simple schema with two types (tables): `users` and `user_audit_logs`:
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
|
||||
// UserAuditLog holds the schema definition for the UserAuditLog entity.
|
||||
type UserAuditLog struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the UserAuditLog.
|
||||
func (UserAuditLog) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("operation_type"),
|
||||
field.String("operation_time"),
|
||||
field.String("old_value").
|
||||
Optional(),
|
||||
field.String("new_value").
|
||||
Optional(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Now, suppose we want to log every change to the `users` table and save it in the `user_audit_logs` table.
|
||||
To achieve this, we need to create a trigger function on `INSERT`, `UPDATE` and `DELETE` operations and attach it to
|
||||
the `users` table.
|
||||
|
||||
2\. Next step, we define a trigger function ( `audit_users_changes`) and attach it to the `users` table using the `CREATE TRIGGER` commands:
|
||||
|
||||
```sql title="schema.sql" {23,26,29}
|
||||
-- Function to audit changes in the users table.
|
||||
CREATE OR REPLACE FUNCTION audit_users_changes()
|
||||
RETURNS TRIGGER AS $$
|
||||
BEGIN
|
||||
IF (TG_OP = 'INSERT') THEN
|
||||
INSERT INTO user_audit_logs(operation_type, operation_time, new_value)
|
||||
VALUES (TG_OP, CURRENT_TIMESTAMP, row_to_json(NEW));
|
||||
RETURN NEW;
|
||||
ELSIF (TG_OP = 'UPDATE') THEN
|
||||
INSERT INTO user_audit_logs(operation_type, operation_time, old_value, new_value)
|
||||
VALUES (TG_OP, CURRENT_TIMESTAMP, row_to_json(OLD), row_to_json(NEW));
|
||||
RETURN NEW;
|
||||
ELSIF (TG_OP = 'DELETE') THEN
|
||||
INSERT INTO user_audit_logs(operation_type, operation_time, old_value)
|
||||
VALUES (TG_OP, CURRENT_TIMESTAMP, row_to_json(OLD));
|
||||
RETURN OLD;
|
||||
END IF;
|
||||
RETURN NULL;
|
||||
END;
|
||||
$$ LANGUAGE plpgsql;
|
||||
|
||||
-- Trigger for INSERT operations.
|
||||
CREATE TRIGGER users_insert_audit AFTER INSERT ON users FOR EACH ROW EXECUTE FUNCTION audit_users_changes();
|
||||
|
||||
-- Trigger for UPDATE operations.
|
||||
CREATE TRIGGER users_update_audit AFTER UPDATE ON users FOR EACH ROW EXECUTE FUNCTION audit_users_changes();
|
||||
|
||||
-- Trigger for DELETE operations.
|
||||
CREATE TRIGGER users_delete_audit AFTER DELETE ON users FOR EACH ROW EXECUTE FUNCTION audit_users_changes();
|
||||
```
|
||||
|
||||
|
||||
3\. Lastly, we create a simple `atlas.hcl` config file with a `composite_schema` that includes both our Ent schema and
|
||||
the custom triggers defined in `schema.sql`:
|
||||
|
||||
```hcl title="atlas.hcl"
|
||||
data "composite_schema" "app" {
|
||||
# Load the ent schema first with all tables.
|
||||
schema "public" {
|
||||
url = "ent://ent/schema"
|
||||
}
|
||||
# Then, load the triggers schema.
|
||||
schema "public" {
|
||||
url = "file://schema.sql"
|
||||
}
|
||||
}
|
||||
|
||||
env "local" {
|
||||
src = data.composite_schema.app.url
|
||||
dev = "docker://postgres/15/dev?search_path=public"
|
||||
}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
After setting up our composite schema, we can get its representation using the `atlas schema inspect` command, generate
|
||||
schema migrations for it, apply them to a database, and more. Below are a few commands to get you started with Atlas:
|
||||
|
||||
#### Inspect the Schema
|
||||
|
||||
The `atlas schema inspect` command is commonly used to inspect databases. However, we can also use it to inspect our
|
||||
`composite_schema` and print the SQL representation of it:
|
||||
|
||||
```shell
|
||||
atlas schema inspect \
|
||||
--env local \
|
||||
--url env://src \
|
||||
--format '{{ sql . }}'
|
||||
```
|
||||
|
||||
The command above prints the following SQL. Note, the `audit_users_changes` function and the triggers are defined after
|
||||
the `users` and `user_audit_logs` tables:
|
||||
|
||||
```sql
|
||||
-- Create "user_audit_logs" table
|
||||
CREATE TABLE "user_audit_logs" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "operation_type" character varying NOT NULL, "operation_time" character varying NOT NULL, "old_value" character varying NULL, "new_value" character varying NULL, PRIMARY KEY ("id"));
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "name" character varying NOT NULL, PRIMARY KEY ("id"));
|
||||
-- Create "audit_users_changes" function
|
||||
CREATE FUNCTION "audit_users_changes" () RETURNS trigger LANGUAGE plpgsql AS $$
|
||||
BEGIN
|
||||
IF (TG_OP = 'INSERT') THEN
|
||||
INSERT INTO user_audit_logs(operation_type, operation_time, new_value)
|
||||
VALUES (TG_OP, CURRENT_TIMESTAMP, row_to_json(NEW));
|
||||
RETURN NEW;
|
||||
ELSIF (TG_OP = 'UPDATE') THEN
|
||||
INSERT INTO user_audit_logs(operation_type, operation_time, old_value, new_value)
|
||||
VALUES (TG_OP, CURRENT_TIMESTAMP, row_to_json(OLD), row_to_json(NEW));
|
||||
RETURN NEW;
|
||||
ELSIF (TG_OP = 'DELETE') THEN
|
||||
INSERT INTO user_audit_logs(operation_type, operation_time, old_value)
|
||||
VALUES (TG_OP, CURRENT_TIMESTAMP, row_to_json(OLD));
|
||||
RETURN OLD;
|
||||
END IF;
|
||||
RETURN NULL;
|
||||
END;
|
||||
$$;
|
||||
-- Create trigger "users_delete_audit"
|
||||
CREATE TRIGGER "users_delete_audit" AFTER DELETE ON "users" FOR EACH ROW EXECUTE FUNCTION "audit_users_changes"();
|
||||
-- Create trigger "users_insert_audit"
|
||||
CREATE TRIGGER "users_insert_audit" AFTER INSERT ON "users" FOR EACH ROW EXECUTE FUNCTION "audit_users_changes"();
|
||||
-- Create trigger "users_update_audit"
|
||||
CREATE TRIGGER "users_update_audit" AFTER UPDATE ON "users" FOR EACH ROW EXECUTE FUNCTION "audit_users_changes"();
|
||||
```
|
||||
|
||||
#### Generate Migrations For the Schema
|
||||
|
||||
To generate a migration for the schema, run the following command:
|
||||
|
||||
```shell
|
||||
atlas migrate diff \
|
||||
--env local
|
||||
```
|
||||
|
||||
Note that a new migration file is created with the following content:
|
||||
|
||||
```sql title="migrations/20240712090543.sql"
|
||||
-- Create "user_audit_logs" table
|
||||
CREATE TABLE "user_audit_logs" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "operation_type" character varying NOT NULL, "operation_time" character varying NOT NULL, "old_value" character varying NULL, "new_value" character varying NULL, PRIMARY KEY ("id"));
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "name" character varying NOT NULL, PRIMARY KEY ("id"));
|
||||
-- Create "audit_users_changes" function
|
||||
CREATE FUNCTION "audit_users_changes" () RETURNS trigger LANGUAGE plpgsql AS $$
|
||||
BEGIN
|
||||
IF (TG_OP = 'INSERT') THEN
|
||||
INSERT INTO user_audit_logs(operation_type, operation_time, new_value)
|
||||
VALUES (TG_OP, CURRENT_TIMESTAMP, row_to_json(NEW));
|
||||
RETURN NEW;
|
||||
ELSIF (TG_OP = 'UPDATE') THEN
|
||||
INSERT INTO user_audit_logs(operation_type, operation_time, old_value, new_value)
|
||||
VALUES (TG_OP, CURRENT_TIMESTAMP, row_to_json(OLD), row_to_json(NEW));
|
||||
RETURN NEW;
|
||||
ELSIF (TG_OP = 'DELETE') THEN
|
||||
INSERT INTO user_audit_logs(operation_type, operation_time, old_value)
|
||||
VALUES (TG_OP, CURRENT_TIMESTAMP, row_to_json(OLD));
|
||||
RETURN OLD;
|
||||
END IF;
|
||||
RETURN NULL;
|
||||
END;
|
||||
$$;
|
||||
-- Create trigger "users_delete_audit"
|
||||
CREATE TRIGGER "users_delete_audit" AFTER DELETE ON "users" FOR EACH ROW EXECUTE FUNCTION "audit_users_changes"();
|
||||
-- Create trigger "users_insert_audit"
|
||||
CREATE TRIGGER "users_insert_audit" AFTER INSERT ON "users" FOR EACH ROW EXECUTE FUNCTION "audit_users_changes"();
|
||||
-- Create trigger "users_update_audit"
|
||||
CREATE TRIGGER "users_update_audit" AFTER UPDATE ON "users" FOR EACH ROW EXECUTE FUNCTION "audit_users_changes"();
|
||||
```
|
||||
|
||||
#### Apply the Migrations
|
||||
|
||||
To apply the migration generated above to a database, run the following command:
|
||||
|
||||
```
|
||||
atlas migrate apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
:::info Apply the Schema Directly on the Database
|
||||
|
||||
Sometimes, there is a need to apply the schema directly to the database without generating a migration file. For example,
|
||||
when experimenting with schema changes, spinning up a database for testing, etc. In such cases, you can use the command
|
||||
below to apply the schema directly to the database:
|
||||
|
||||
```shell
|
||||
atlas schema apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
Or, using the [Atlas Go SDK](https://github.com/ariga/atlas-go-sdk):
|
||||
|
||||
```go
|
||||
ac, err := atlasexec.NewClient(".", "atlas")
|
||||
if err != nil {
|
||||
log.Fatalf("failed to initialize client: %w", err)
|
||||
}
|
||||
// Automatically update the database with the desired schema.
|
||||
// Another option, is to use 'migrate apply' or 'schema apply' manually.
|
||||
if _, err := ac.SchemaApply(ctx, &atlasexec.SchemaApplyParams{
|
||||
Env: "local",
|
||||
URL: "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable",
|
||||
AutoApprove: true,
|
||||
}); err != nil {
|
||||
log.Fatalf("failed to apply schema changes: %w", err)
|
||||
}
|
||||
```
|
||||
|
||||
:::
|
||||
|
||||
The code for this guide can be found in [GitHub](https://github.com/ent/ent/tree/master/examples/triggers).
|
||||
180
doc/md/multischema-migrations.mdx
Normal file
180
doc/md/multischema-migrations.mdx
Normal file
@@ -0,0 +1,180 @@
|
||||
---
|
||||
id: multischema-migrations
|
||||
title: Multi-Schema Migration
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import InstallationInstructions from './components/_installation_instructions.mdx';
|
||||
|
||||
Using the [Atlas](https://atlasgo.io) migration engine, an Ent schema can be defined and managed across multiple
|
||||
database schemas. This guides show how to achieve this with three simple steps:
|
||||
|
||||
:::info [Atlas Pro Feature](https://atlasgo.io/features#pro-plan)
|
||||
The _multi-schema migration_ feature is fully implemented in the Atlas CLI and requires a login to use:
|
||||
```
|
||||
atlas login
|
||||
```
|
||||
:::
|
||||
|
||||
## Install Atlas
|
||||
|
||||
<InstallationInstructions />
|
||||
|
||||
## Login to Atlas
|
||||
|
||||
```shell
|
||||
$ atlas login a8m
|
||||
//highlight-next-line-info
|
||||
You are now connected to "a8m" on Atlas Cloud.
|
||||
```
|
||||
|
||||
## Annotate your Ent schemas
|
||||
|
||||
The `entsql` package allows annotating an Ent schema with a database schema name. For example:
|
||||
|
||||
```go
|
||||
// Annotations of the User.
|
||||
func (User) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entsql.Schema("db3"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
To share the same schema configuration across multiple Ent schemas, you can either use `ent.Mixin` or define and embed a _base_ schema:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="mixin" label="Mixin schema">
|
||||
|
||||
```go title="mixin.go"
|
||||
// Mixin holds the default configuration for most schemas in this package.
|
||||
type Mixin struct {
|
||||
mixin.Schema
|
||||
}
|
||||
|
||||
// Annotations of the Mixin.
|
||||
func (Mixin) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entsql.Schema("db1"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```go title="user.go"
|
||||
// User holds the edge schema definition of the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Mixin defines the schemas that mixed into this schema.
|
||||
func (User) Mixin() []ent.Mixin {
|
||||
return []ent.Mixin{
|
||||
//highlight-next-line
|
||||
Mixin{},
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="base" label="Base schema">
|
||||
|
||||
```go title="base.go"
|
||||
// base holds the default configuration for most schemas in this package.
|
||||
type base struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Annotations of the base schema.
|
||||
func (base) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entsql.Schema("db1"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```go title="user.go"
|
||||
// User holds the edge schema definition of the User entity.
|
||||
type User struct {
|
||||
//highlight-next-line
|
||||
base
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Generate migrations
|
||||
|
||||
To generate a migration, use the `atlas migrate diff` command. For example:
|
||||
|
||||
<Tabs
|
||||
defaultValue="mysql"
|
||||
values={[
|
||||
{label: 'MySQL', value: 'mysql'},
|
||||
{label: 'MariaDB', value: 'maria'},
|
||||
{label: 'PostgreSQL', value: 'postgres'},
|
||||
]}>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```shell
|
||||
atlas migrate diff \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://mysql/8"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="maria">
|
||||
|
||||
```shell
|
||||
atlas migrate diff \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://maria/8"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="postgres">
|
||||
|
||||
```shell
|
||||
atlas migrate diff \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://postgres/15/dev"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
:::note
|
||||
The `migrate` diff command generates a list of SQL statements without indentation by default. If you would like to
|
||||
generate the SQL statements with indentation, use the `--format` flag. For example:
|
||||
|
||||
```shell
|
||||
atlas migrate diff \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://postgres/15/dev" \
|
||||
// highlight-next-line
|
||||
--format "{{ sql . \" \" }}"
|
||||
```
|
||||
:::
|
||||
|
||||
## Controlling the Ent Client
|
||||
|
||||
When the `sql/schemaconfig` feature flag is enabled, Ent automatically uses the schema names defined in your `ent/schema` as the default runtime configuration.
|
||||
This means that any `entsql.Schema("db_name")` annotation is applied by default, and you can optionally override it at runtime if needed.
|
||||
|
||||
To enable the feature for your project, use the `--feature` flag:
|
||||
|
||||
```shell
|
||||
--feature sql/schemaconfig
|
||||
```
|
||||
|
||||
Once enabled, you can also override the schema configuration at runtime using the `ent.AlternateSchema` option:
|
||||
|
||||
```go
|
||||
c, err := ent.Open(dialect, conn, ent.AlternateSchema(ent.SchemaConfig{
|
||||
User: "usersdb",
|
||||
Car: "carsdb",
|
||||
}))
|
||||
c.User.Query().All(ctx) // SELECT * FROM `usersdb`.`users`
|
||||
c.Car.Query().All(ctx) // SELECT * FROM `carsdb`.`cars`
|
||||
```
|
||||
269
doc/md/paging.mdx
Normal file
269
doc/md/paging.mdx
Normal file
@@ -0,0 +1,269 @@
|
||||
---
|
||||
id: paging
|
||||
title: Paging And Ordering
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
## Limit
|
||||
|
||||
`Limit` limits the query result to `n` entities.
|
||||
|
||||
```go
|
||||
users, err := client.User.
|
||||
Query().
|
||||
Limit(n).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
|
||||
## Offset
|
||||
|
||||
`Offset` sets the first node to return from the query.
|
||||
|
||||
```go
|
||||
users, err := client.User.
|
||||
Query().
|
||||
Offset(10).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
## Ordering
|
||||
|
||||
`Order` returns the entities sorted by the values of one or more fields. Note that, an error
|
||||
is returned if the given fields are not valid columns or foreign-keys.
|
||||
|
||||
```go
|
||||
users, err := client.User.Query().
|
||||
Order(ent.Asc(user.FieldName)).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
Starting with version `v0.12.0`, Ent generates type-safe ordering functions for fields and edges. The following
|
||||
example demonstrates how to use these generated functions:
|
||||
|
||||
```go
|
||||
// Get all users sorted by their name (and nickname) in ascending order.
|
||||
users, err := client.User.Query().
|
||||
Order(
|
||||
// highlight-start
|
||||
user.ByName(),
|
||||
user.ByNickname(),
|
||||
// highlight-end
|
||||
).
|
||||
All(ctx)
|
||||
|
||||
// Get all users sorted by their nickname in descending order.
|
||||
users, err := client.User.Query().
|
||||
Order(
|
||||
// highlight-start
|
||||
user.ByNickname(
|
||||
sql.OrderDesc(),
|
||||
),
|
||||
// highlight-end
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
## Order By Edge Count
|
||||
|
||||
`Order` can also be used to sort entities based on the number of edges they have. For example, the following query
|
||||
returns all users sorted by the number of posts they have:
|
||||
|
||||
```go
|
||||
users, err := client.User.Query().
|
||||
Order(
|
||||
// highlight-start
|
||||
// Users without posts are sorted first.
|
||||
user.ByPostsCount(),
|
||||
// highlight-end
|
||||
).
|
||||
All(ctx)
|
||||
|
||||
users, err := client.User.Query().
|
||||
Order(
|
||||
// highlight-start
|
||||
// Users without posts are sorted last.
|
||||
user.ByPostsCount(
|
||||
sql.OrderDesc(),
|
||||
),
|
||||
// highlight-end
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
## Order By Edge Field
|
||||
|
||||
Entities can also be sorted by the value of an edge field. For example, the following query returns all posts sorted by
|
||||
their author's name:
|
||||
|
||||
```go
|
||||
// Posts are sorted by their author's name in ascending
|
||||
// order with NULLs first unless otherwise specified.
|
||||
posts, err := client.Post.Query().
|
||||
Order(
|
||||
// highlight-next-line
|
||||
post.ByAuthorField(user.FieldName),
|
||||
).
|
||||
All(ctx)
|
||||
|
||||
posts, err := client.Post.Query().
|
||||
Order(
|
||||
// highlight-start
|
||||
post.ByAuthorField(
|
||||
user.FieldName,
|
||||
sql.OrderDesc(),
|
||||
sql.OrderNullsFirst(),
|
||||
),
|
||||
// highlight-end
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
## Custom Edge Terms
|
||||
|
||||
The generated edge ordering functions support custom terms. For example, the following query returns all users sorted
|
||||
by the sum of their posts' likes and views:
|
||||
|
||||
```go
|
||||
// Ascending order.
|
||||
posts, err := client.User.Query().
|
||||
Order(
|
||||
// highlight-start
|
||||
user.ByPosts(
|
||||
sql.OrderBySum(post.FieldNumLikes),
|
||||
sql.OrderBySum(post.FieldNumViews),
|
||||
),
|
||||
// highlight-end
|
||||
).
|
||||
All(ctx)
|
||||
|
||||
// Descending order.
|
||||
posts, err := client.User.Query().
|
||||
Order(
|
||||
// highlight-start
|
||||
user.ByPosts(
|
||||
sql.OrderBySum(
|
||||
post.FieldNumLikes,
|
||||
sql.OrderDesc(),
|
||||
),
|
||||
sql.OrderBySum(
|
||||
post.FieldNumViews,
|
||||
sql.OrderDesc(),
|
||||
),
|
||||
),
|
||||
// highlight-end
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
## Select Order Terms
|
||||
|
||||
Ordered terms like `SUM()` and `COUNT()` are not defined in the schema and thus do not exist on the generated entities.
|
||||
However, sometimes there is a need to retrieve their information in order to either display it to the user or implement
|
||||
cursor-based pagination. The `Value` method, defined on each entity, allows you to obtain the order value if it was
|
||||
selected in the query:
|
||||
|
||||
```go
|
||||
// Define the alias for the order term.
|
||||
const as = "pets_count"
|
||||
|
||||
// Query users sorted by the number of pets
|
||||
// they have and select the order term.
|
||||
users := client.User.Query().
|
||||
Order(
|
||||
user.ByPetsCount(
|
||||
sql.OrderDesc(),
|
||||
// highlight-next-line
|
||||
sql.OrderSelectAs(as),
|
||||
),
|
||||
user.ByID(),
|
||||
).
|
||||
AllX(ctx)
|
||||
|
||||
// Retrieve the order term value.
|
||||
for _, u := range users {
|
||||
// highlight-next-line
|
||||
fmt.Println(u.Value(as))
|
||||
}
|
||||
```
|
||||
|
||||
## Custom Ordering
|
||||
|
||||
Custom ordering functions can be useful if you want to write your own storage-specific logic.
|
||||
|
||||
```go
|
||||
names, err := client.Pet.Query().
|
||||
Order(func(s *sql.Selector) {
|
||||
// Logic goes here.
|
||||
}).
|
||||
Select(pet.FieldName).
|
||||
Strings(ctx)
|
||||
```
|
||||
|
||||
#### Order by JSON fields
|
||||
|
||||
The [`sqljson`](https://pkg.go.dev/entgo.io/ent/dialect/sql/sqljson) package allows to easily sort data based on the
|
||||
value of a JSON object:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="value" label="By Value" default>
|
||||
|
||||
```go {3}
|
||||
users := client.User.Query().
|
||||
Order(
|
||||
sqljson.OrderValue(user.FieldData, sqljson.Path("key1", "key2")),
|
||||
).
|
||||
AllX(ctx)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="length" label="By Length">
|
||||
|
||||
```go {3}
|
||||
users := client.User.Query().
|
||||
Order(
|
||||
sqljson.OrderLen(user.FieldData, sqljson.Path("key1", "key2")),
|
||||
).
|
||||
AllX(ctx)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="desc" label="Descending">
|
||||
|
||||
```go {3,9}
|
||||
users := client.User.Query().
|
||||
Order(
|
||||
sqljson.OrderValueDesc(user.FieldData, sqljson.Path("key1", "key2")),
|
||||
).
|
||||
AllX(ctx)
|
||||
|
||||
pets := client.Pet.Query().
|
||||
Order(
|
||||
sqljson.OrderLenDesc(pet.FieldData, sqljson.Path("key1", "key2")),
|
||||
).
|
||||
AllX(ctx)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
<details>
|
||||
<summary>PostgreSQL limitation on <code>ORDER BY</code> expressions with <code>SELECT DISTINCT</code></summary>
|
||||
<div>
|
||||
|
||||
PostgreSQL does not support `ORDER BY` expressions with `SELECT DISTINCT`. Thus, the `Unique` modifier should be set
|
||||
to `false`. However, keep in mind that this may result in duplicate results when performing graph traversals.
|
||||
|
||||
```diff
|
||||
users := client.User.Query().
|
||||
Order(
|
||||
sqljson.OrderValue(user.FieldData, sqljson.Path("key1", "key2")),
|
||||
).
|
||||
+ Unique(false).
|
||||
AllX(ctx)
|
||||
```
|
||||
|
||||
</div>
|
||||
</details>
|
||||
349
doc/md/predicates.md
Normal file
349
doc/md/predicates.md
Normal file
@@ -0,0 +1,349 @@
|
||||
---
|
||||
id: predicates
|
||||
title: Predicates
|
||||
---
|
||||
|
||||
## Field Predicates
|
||||
|
||||
- **Bool**:
|
||||
- =, !=
|
||||
- **Numeric**:
|
||||
- =, !=, >, <, >=, <=,
|
||||
- IN, NOT IN
|
||||
- **Time**:
|
||||
- =, !=, >, <, >=, <=
|
||||
- IN, NOT IN
|
||||
- **String**:
|
||||
- =, !=, >, <, >=, <=
|
||||
- IN, NOT IN
|
||||
- Contains, HasPrefix, HasSuffix
|
||||
- ContainsFold, EqualFold (**SQL** specific)
|
||||
- **JSON**
|
||||
- =, !=
|
||||
- =, !=, >, <, >=, <= on nested values (JSON path).
|
||||
- Contains on nested values (JSON path).
|
||||
- HasKey, Len<P>
|
||||
- `null` checks for nested values (JSON path).
|
||||
- **Optional** fields:
|
||||
- IsNil, NotNil
|
||||
|
||||
## Edge Predicates
|
||||
|
||||
- **HasEdge**. For example, for edge named `owner` of type `Pet`, use:
|
||||
|
||||
```go
|
||||
client.Pet.
|
||||
Query().
|
||||
Where(pet.HasOwner()).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
- **HasEdgeWith**. Add list of predicates for edge predicate.
|
||||
|
||||
```go
|
||||
client.Pet.
|
||||
Query().
|
||||
Where(pet.HasOwnerWith(user.Name("a8m"))).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
|
||||
## Negation (NOT)
|
||||
|
||||
```go
|
||||
client.Pet.
|
||||
Query().
|
||||
Where(pet.Not(pet.NameHasPrefix("Ari"))).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
## Disjunction (OR)
|
||||
|
||||
```go
|
||||
client.Pet.
|
||||
Query().
|
||||
Where(
|
||||
pet.Or(
|
||||
pet.HasOwner(),
|
||||
pet.Not(pet.HasFriends()),
|
||||
)
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
## Conjunction (AND)
|
||||
|
||||
```go
|
||||
client.Pet.
|
||||
Query().
|
||||
Where(
|
||||
pet.And(
|
||||
pet.HasOwner(),
|
||||
pet.Not(pet.HasFriends()),
|
||||
)
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
## Custom Predicates
|
||||
|
||||
Custom predicates can be useful if you want to write your own dialect-specific logic or to control the executed queries.
|
||||
|
||||
#### Get all pets of users 1, 2 and 3
|
||||
|
||||
```go
|
||||
pets := client.Pet.
|
||||
Query().
|
||||
Where(func(s *sql.Selector) {
|
||||
s.Where(sql.InInts(pet.FieldOwnerID, 1, 2, 3))
|
||||
}).
|
||||
AllX(ctx)
|
||||
```
|
||||
The above code will produce the following SQL query:
|
||||
```sql
|
||||
SELECT DISTINCT `pets`.`id`, `pets`.`owner_id` FROM `pets` WHERE `owner_id` IN (1, 2, 3)
|
||||
```
|
||||
|
||||
#### Count the number of users whose JSON field named `URL` contains the `Scheme` key
|
||||
|
||||
```go
|
||||
count := client.User.
|
||||
Query().
|
||||
Where(func(s *sql.Selector) {
|
||||
s.Where(sqljson.HasKey(user.FieldURL, sqljson.Path("Scheme")))
|
||||
}).
|
||||
CountX(ctx)
|
||||
```
|
||||
|
||||
The above code will produce the following SQL query:
|
||||
|
||||
```sql
|
||||
-- PostgreSQL
|
||||
SELECT COUNT(DISTINCT "users"."id") FROM "users" WHERE "url"->'Scheme' IS NOT NULL
|
||||
|
||||
-- SQLite and MySQL
|
||||
SELECT COUNT(DISTINCT `users`.`id`) FROM `users` WHERE JSON_EXTRACT(`url`, "$.Scheme") IS NOT NULL
|
||||
```
|
||||
|
||||
#### Get all users with a `"Tesla"` car
|
||||
|
||||
Consider an ent query such as:
|
||||
|
||||
```go
|
||||
users := client.User.Query().
|
||||
Where(user.HasCarWith(car.Model("Tesla"))).
|
||||
AllX(ctx)
|
||||
```
|
||||
|
||||
This query can be rephrased in 3 different forms: `IN`, `EXISTS` and `JOIN`.
|
||||
|
||||
```go
|
||||
// `IN` version.
|
||||
users := client.User.Query().
|
||||
Where(func(s *sql.Selector) {
|
||||
t := sql.Table(car.Table)
|
||||
s.Where(
|
||||
sql.In(
|
||||
s.C(user.FieldID),
|
||||
sql.Select(t.C(user.FieldID)).From(t).Where(sql.EQ(t.C(car.FieldModel), "Tesla")),
|
||||
),
|
||||
)
|
||||
}).
|
||||
AllX(ctx)
|
||||
|
||||
// `JOIN` version.
|
||||
users := client.User.Query().
|
||||
Where(func(s *sql.Selector) {
|
||||
t := sql.Table(car.Table)
|
||||
s.Join(t).On(s.C(user.FieldID), t.C(car.FieldOwnerID))
|
||||
s.Where(sql.EQ(t.C(car.FieldModel), "Tesla"))
|
||||
}).
|
||||
AllX(ctx)
|
||||
|
||||
// `EXISTS` version.
|
||||
users := client.User.Query().
|
||||
Where(func(s *sql.Selector) {
|
||||
t := sql.Table(car.Table)
|
||||
p := sql.And(
|
||||
sql.EQ(t.C(car.FieldModel), "Tesla"),
|
||||
sql.ColumnsEQ(s.C(user.FieldID), t.C(car.FieldOwnerID)),
|
||||
)
|
||||
s.Where(sql.Exists(sql.Select().From(t).Where(p)))
|
||||
}).
|
||||
AllX(ctx)
|
||||
```
|
||||
|
||||
The above code will produce the following SQL query:
|
||||
|
||||
```sql
|
||||
-- `IN` version.
|
||||
SELECT DISTINCT `users`.`id`, `users`.`age`, `users`.`name` FROM `users` WHERE `users`.`id` IN (SELECT `cars`.`owner_id` FROM `cars` WHERE `cars`.`model` = 'Tesla')
|
||||
|
||||
-- `JOIN` version.
|
||||
SELECT DISTINCT `users`.`id`, `users`.`age`, `users`.`name` FROM `users` JOIN `cars` ON `users`.`id` = `cars`.`owner_id` WHERE `cars`.`model` = 'Tesla'
|
||||
|
||||
-- `EXISTS` version.
|
||||
SELECT DISTINCT `users`.`id`, `users`.`age`, `users`.`name` FROM `users` WHERE EXISTS (SELECT * FROM `cars` WHERE `cars`.`model` = 'Tesla' AND `users`.`id` = `cars`.`owner_id`)
|
||||
```
|
||||
|
||||
#### Get all pets where pet name contains a specific pattern
|
||||
|
||||
The generated code provides the `HasPrefix`, `HasSuffix`, `Contains`, and `ContainsFold` predicates for pattern matching.
|
||||
However, in order to use the `LIKE` operator with a custom pattern, use the following example.
|
||||
|
||||
```go
|
||||
pets := client.Pet.Query().
|
||||
Where(func(s *sql.Selector){
|
||||
s.Where(sql.Like(pet.Name,"_B%"))
|
||||
}).
|
||||
AllX(ctx)
|
||||
```
|
||||
|
||||
The above code will produce the following SQL query:
|
||||
|
||||
```sql
|
||||
SELECT DISTINCT `pets`.`id`, `pets`.`owner_id`, `pets`.`name`, `pets`.`age`, `pets`.`species` FROM `pets` WHERE `name` LIKE '_B%'
|
||||
```
|
||||
|
||||
#### Custom SQL functions
|
||||
|
||||
In order to use built-in SQL functions such as `DATE()`, use one of the following options:
|
||||
|
||||
1\. Pass a dialect-aware predicate function using the `sql.P` option:
|
||||
|
||||
```go
|
||||
users := client.User.Query().
|
||||
Select(user.FieldID).
|
||||
Where(func(s *sql.Selector) {
|
||||
s.Where(sql.P(func(b *sql.Builder) {
|
||||
b.WriteString("DATE(").Ident("last_login_at").WriteByte(')').WriteOp(OpGTE).Arg(value)
|
||||
}))
|
||||
}).
|
||||
AllX(ctx)
|
||||
```
|
||||
|
||||
The above code will produce the following SQL query:
|
||||
|
||||
```sql
|
||||
SELECT `id` FROM `users` WHERE DATE(`last_login_at`) >= ?
|
||||
```
|
||||
|
||||
2\. Inline a predicate expression using the `ExprP()` option:
|
||||
|
||||
```go
|
||||
users := client.User.Query().
|
||||
Select(user.FieldID).
|
||||
Where(func(s *sql.Selector) {
|
||||
s.Where(sql.ExprP("DATE(last_login_at) >= ?", value))
|
||||
}).
|
||||
AllX(ctx)
|
||||
```
|
||||
|
||||
The above code will produce the same SQL query:
|
||||
|
||||
```sql
|
||||
SELECT `id` FROM `users` WHERE DATE(`last_login_at`) >= ?
|
||||
```
|
||||
|
||||
## JSON predicates
|
||||
|
||||
JSON predicates are not generated by default as part of the code generation. However, ent provides an official package
|
||||
named [`sqljson`](https://pkg.go.dev/entgo.io/ent/dialect/sql/sqljson) for applying predicates on JSON columns using the
|
||||
[custom predicates option](#custom-predicates).
|
||||
|
||||
#### Compare a JSON value
|
||||
|
||||
```go
|
||||
sqljson.ValueEQ(user.FieldData, data)
|
||||
|
||||
sqljson.ValueEQ(user.FieldURL, "https", sqljson.Path("Scheme"))
|
||||
|
||||
sqljson.ValueNEQ(user.FieldData, content, sqljson.DotPath("attributes[1].body.content"))
|
||||
|
||||
sqljson.ValueGTE(user.FieldData, status.StatusBadRequest, sqljson.Path("response", "status"))
|
||||
```
|
||||
|
||||
#### Check for the presence of a JSON key
|
||||
|
||||
```go
|
||||
sqljson.HasKey(user.FieldData, sqljson.Path("attributes", "[1]", "body"))
|
||||
|
||||
sqljson.HasKey(user.FieldData, sqljson.DotPath("attributes[1].body"))
|
||||
```
|
||||
|
||||
Note that, a key with the `null` literal as a value also matches this operation.
|
||||
|
||||
#### Check JSON `null` literals
|
||||
|
||||
```go
|
||||
sqljson.ValueIsNull(user.FieldData)
|
||||
|
||||
sqljson.ValueIsNull(user.FieldData, sqljson.Path("attributes"))
|
||||
|
||||
sqljson.ValueIsNull(user.FieldData, sqljson.DotPath("attributes[1].body"))
|
||||
```
|
||||
|
||||
Note that, the `ValueIsNull` returns true if the value is JSON `null`,
|
||||
but not database `NULL`.
|
||||
|
||||
#### Compare the length of a JSON array
|
||||
|
||||
```go
|
||||
sqljson.LenEQ(user.FieldAttrs, 2)
|
||||
|
||||
sql.Or(
|
||||
sqljson.LenGT(user.FieldData, 10, sqljson.Path("attributes")),
|
||||
sqljson.LenLT(user.FieldData, 20, sqljson.Path("attributes")),
|
||||
)
|
||||
```
|
||||
|
||||
#### Check if a JSON value contains another value
|
||||
|
||||
```go
|
||||
sqljson.ValueContains(user.FieldData, data)
|
||||
|
||||
sqljson.ValueContains(user.FieldData, attrs, sqljson.Path("attributes"))
|
||||
|
||||
sqljson.ValueContains(user.FieldData, code, sqljson.DotPath("attributes[0].status_code"))
|
||||
```
|
||||
|
||||
#### Check if a JSON string value contains a given substring or has a given suffix or prefix
|
||||
|
||||
```go
|
||||
sqljson.StringContains(user.FieldURL, "github", sqljson.Path("host"))
|
||||
|
||||
sqljson.StringHasSuffix(user.FieldURL, ".com", sqljson.Path("host"))
|
||||
|
||||
sqljson.StringHasPrefix(user.FieldData, "20", sqljson.DotPath("attributes[0].status_code"))
|
||||
```
|
||||
|
||||
#### Check if a JSON value is equal to any of the values in a list
|
||||
|
||||
```go
|
||||
sqljson.ValueIn(user.FieldURL, []any{"https", "ftp"}, sqljson.Path("Scheme"))
|
||||
|
||||
sqljson.ValueNotIn(user.FieldURL, []any{"github", "gitlab"}, sqljson.Path("Host"))
|
||||
```
|
||||
|
||||
## Comparing Fields
|
||||
|
||||
The `dialect/sql` package provides a set of comparison functions that can be used to compare fields in a query.
|
||||
|
||||
```go
|
||||
client.Order.Query().
|
||||
Where(
|
||||
sql.FieldsEQ(order.FieldTotal, order.FieldTax),
|
||||
sql.FieldsNEQ(order.FieldTotal, order.FieldDiscount),
|
||||
).
|
||||
All(ctx)
|
||||
|
||||
client.Order.Query().
|
||||
Where(
|
||||
order.Or(
|
||||
sql.FieldsGT(order.FieldTotal, order.FieldTax),
|
||||
sql.FieldsLT(order.FieldTotal, order.FieldDiscount),
|
||||
),
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
682
doc/md/privacy.mdx
Normal file
682
doc/md/privacy.mdx
Normal file
@@ -0,0 +1,682 @@
|
||||
---
|
||||
id: privacy
|
||||
title: Privacy
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
The `Policy` option in the schema allows configuring privacy policy for queries and mutations of entities in the database.
|
||||
|
||||

|
||||
|
||||
The main advantage of the privacy layer is that, you write the privacy policy **once** (in the schema), and it is **always**
|
||||
evaluated. No matter where queries and mutations are performed in your codebase, it will always go through the privacy layer.
|
||||
|
||||
In this tutorial, we will start by going over the basic terms we use in the framework, continue with a section for configuring
|
||||
the policy feature to your project, and finish with a few examples.
|
||||
|
||||
## Basic Terms
|
||||
|
||||
### Policy
|
||||
|
||||
The `ent.Policy` interface contains two methods: `EvalQuery` and `EvalMutation`. The first defines the read-policy, and
|
||||
the second defines the write-policy. A policy contains zero or more privacy rules (see below). These rules are evaluated
|
||||
in the same order they are declared in the schema.
|
||||
|
||||
If all rules are evaluated without returning an error, the evaluation finishes successfully, and the executed operation
|
||||
gets access to the target nodes.
|
||||
|
||||

|
||||
|
||||
However, if one of the evaluated rules returns an error or a `privacy.Deny` decision (see below), the executed operation
|
||||
returns an error, and it is cancelled.
|
||||
|
||||

|
||||
|
||||
### Privacy Rules
|
||||
|
||||
Each policy (mutation or query) includes one or more privacy rules. The function signature for these rules is as follows:
|
||||
|
||||
```go
|
||||
// EvalQuery defines the a read-policy rule.
|
||||
func(Policy) EvalQuery(context.Context, Query) error
|
||||
|
||||
// EvalMutation defines the a write-policy rule.
|
||||
func(Policy) EvalMutation(context.Context, Mutation) error
|
||||
```
|
||||
|
||||
### Privacy Decisions
|
||||
|
||||
There are three types of decision that can help you control the privacy rules evaluation.
|
||||
|
||||
- `privacy.Allow` - If returned from a privacy rule, the evaluation stops (next rules will be skipped), and the executed
|
||||
operation (query or mutation) gets access to the target nodes.
|
||||
|
||||
- `privacy.Deny` - If returned from a privacy rule, the evaluation stops (next rules will be skipped), and the executed
|
||||
operation is cancelled. This equivalent to returning any error.
|
||||
|
||||
- `privacy.Skip` - Skip the current rule, and jump to the next privacy rule. This equivalent to returning a `nil` error.
|
||||
|
||||

|
||||
|
||||
Now that we’ve covered the basic terms, let’s start writing some code.
|
||||
|
||||
## Configuration
|
||||
|
||||
In order to enable the privacy option in your code generation, enable the `privacy` feature with one of two options:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="cli" label="CLI" default>
|
||||
|
||||
If you are using the default go generate config, add `--feature privacy` option to the `ent/generate.go` file as follows:
|
||||
|
||||
```go title="ent/generate.go"
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entgo.io/ent/cmd/ent generate --feature privacy ./schema
|
||||
```
|
||||
|
||||
It is recommended to add the [`schema/snapshot`](features.md#auto-solve-merge-conflicts) feature-flag along with the
|
||||
`privacy` flag to enhance the development experience, for example:
|
||||
|
||||
```go
|
||||
//go:generate go run -mod=mod entgo.io/ent/cmd/ent generate --feature privacy,schema/snapshot ./schema
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="entc" label="Go">
|
||||
|
||||
If you are using the configuration from the GraphQL documentation, add the feature flag as follows:
|
||||
|
||||
```go
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
)
|
||||
|
||||
func main() {
|
||||
opts := []entc.Option{
|
||||
entc.FeatureNames("privacy"),
|
||||
}
|
||||
if err := entc.Generate("./schema", &gen.Config{}, opts...); err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
|
||||
It is recommended to add the [`schema/snapshot`](features.md#auto-solve-merge-conflicts) feature-flag along with the
|
||||
`privacy` flag to enhance the development experience, for example:
|
||||
|
||||
```diff
|
||||
opts := []entc.Option{
|
||||
- entc.FeatureNames("privacy"),
|
||||
+ entc.FeatureNames("privacy", "schema/snapshot"),
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### Privacy Policy Registration
|
||||
|
||||
:::important
|
||||
You should notice that similar to [schema hooks](hooks.md#hooks-registration), if you use the **`Policy`** option in your schema,
|
||||
you **MUST** add the following import in the main package, because a circular import is possible between the schema package,
|
||||
and the generated ent package:
|
||||
|
||||
```go
|
||||
import _ "<project>/ent/runtime"
|
||||
```
|
||||
:::
|
||||
|
||||
## Examples
|
||||
|
||||
### Admin Only
|
||||
|
||||
We start with a simple example of an application that lets any user read any data, and accepts mutations only from users
|
||||
with admin role. We will create 2 additional packages for the purpose of the examples:
|
||||
|
||||
- `rule` - for holding the different privacy rules in our schema.
|
||||
- `viewer` - for getting and setting the user/viewer who's executing the operation. In this simple example, it can be
|
||||
either a normal user or an admin.
|
||||
|
||||
After running the code-generation (with the feature-flag for privacy), we add the `Policy` method with 2 generated policy rules.
|
||||
|
||||
```go title="examples/privacyadmin/ent/schema/user.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/examples/privacyadmin/ent/privacy"
|
||||
)
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Policy defines the privacy policy of the User.
|
||||
func (User) Policy() ent.Policy {
|
||||
return privacy.Policy{
|
||||
Mutation: privacy.MutationPolicy{
|
||||
// Deny if not set otherwise.
|
||||
privacy.AlwaysDenyRule(),
|
||||
},
|
||||
Query: privacy.QueryPolicy{
|
||||
// Allow any viewer to read anything.
|
||||
privacy.AlwaysAllowRule(),
|
||||
},
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
We defined a policy that rejects any mutation and accepts any query. However, as mentioned above, in this example,
|
||||
we accept mutations only from viewers with admin role. Let's create 2 privacy rules to enforce this:
|
||||
|
||||
```go title="examples/privacyadmin/rule/rule.go"
|
||||
package rule
|
||||
|
||||
import (
|
||||
"context"
|
||||
|
||||
"entgo.io/ent/examples/privacyadmin/ent/privacy"
|
||||
"entgo.io/ent/examples/privacyadmin/viewer"
|
||||
)
|
||||
|
||||
// DenyIfNoViewer is a rule that returns Deny decision if the viewer is
|
||||
// missing in the context.
|
||||
func DenyIfNoViewer() privacy.QueryMutationRule {
|
||||
return privacy.ContextQueryMutationRule(func(ctx context.Context) error {
|
||||
view := viewer.FromContext(ctx)
|
||||
if view == nil {
|
||||
return privacy.Denyf("viewer-context is missing")
|
||||
}
|
||||
// Skip to the next privacy rule (equivalent to returning nil).
|
||||
return privacy.Skip
|
||||
})
|
||||
}
|
||||
|
||||
// AllowIfAdmin is a rule that returns Allow decision if the viewer is admin.
|
||||
func AllowIfAdmin() privacy.QueryMutationRule {
|
||||
return privacy.ContextQueryMutationRule(func(ctx context.Context) error {
|
||||
view := viewer.FromContext(ctx)
|
||||
if view.Admin() {
|
||||
return privacy.Allow
|
||||
}
|
||||
// Skip to the next privacy rule (equivalent to returning nil).
|
||||
return privacy.Skip
|
||||
})
|
||||
}
|
||||
```
|
||||
|
||||
As you can see, the first rule `DenyIfNoViewer`, makes sure every operation has a viewer in its context,
|
||||
otherwise, the operation rejected. The second rule `AllowIfAdmin`, accepts any operation from viewer with
|
||||
admin role. Let's add them to the schema, and run the code-generation:
|
||||
|
||||
```go title="examples/privacyadmin/ent/schema/user.go"
|
||||
// Policy defines the privacy policy of the User.
|
||||
func (User) Policy() ent.Policy {
|
||||
return privacy.Policy{
|
||||
Mutation: privacy.MutationPolicy{
|
||||
rule.DenyIfNoViewer(),
|
||||
rule.AllowIfAdmin(),
|
||||
privacy.AlwaysDenyRule(),
|
||||
},
|
||||
Query: privacy.QueryPolicy{
|
||||
privacy.AlwaysAllowRule(),
|
||||
},
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Since we define the `DenyIfNoViewer` first, it will be executed before all other rules, and accessing the
|
||||
`viewer.Viewer` object is safe in the `AllowIfAdmin` rule.
|
||||
|
||||
After adding the rules above and running the code-generation, we expect the privacy-layer logic to be applied on
|
||||
`ent.Client` operations.
|
||||
|
||||
```go title="examples/privacyadmin/example_test.go"
|
||||
func Do(ctx context.Context, client *ent.Client) error {
|
||||
// Expect operation to fail, because viewer-context
|
||||
// is missing (first mutation rule check).
|
||||
if err := client.User.Create().Exec(ctx); !errors.Is(err, privacy.Deny) {
|
||||
return fmt.Errorf("expect operation to fail, but got %w", err)
|
||||
}
|
||||
// Apply the same operation with "Admin" role.
|
||||
admin := viewer.NewContext(ctx, viewer.UserViewer{Role: viewer.Admin})
|
||||
if err := client.User.Create().Exec(admin); err != nil {
|
||||
return fmt.Errorf("expect operation to pass, but got %w", err)
|
||||
}
|
||||
// Apply the same operation with "ViewOnly" role.
|
||||
viewOnly := viewer.NewContext(ctx, viewer.UserViewer{Role: viewer.View})
|
||||
if err := client.User.Create().Exec(viewOnly); !errors.Is(err, privacy.Deny) {
|
||||
return fmt.Errorf("expect operation to fail, but got %w", err)
|
||||
}
|
||||
// Allow all viewers to query users.
|
||||
for _, ctx := range []context.Context{ctx, viewOnly, admin} {
|
||||
// Operation should pass for all viewers.
|
||||
count := client.User.Query().CountX(ctx)
|
||||
fmt.Println(count)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
### Decision Context
|
||||
|
||||
Sometimes, we want to bind a specific privacy decision to the `context.Context`. In cases like this, we
|
||||
can use the `privacy.DecisionContext` function to create a new context with a privacy decision attached to it.
|
||||
|
||||
```go title="examples/privacyadmin/example_test.go"
|
||||
func Do(ctx context.Context, client *ent.Client) error {
|
||||
// Bind a privacy decision to the context (bypass all other rules).
|
||||
allow := privacy.DecisionContext(ctx, privacy.Allow)
|
||||
if err := client.User.Create().Exec(allow); err != nil {
|
||||
return fmt.Errorf("expect operation to pass, but got %w", err)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
The full example exists in [GitHub](https://github.com/ent/ent/tree/master/examples/privacyadmin).
|
||||
|
||||
### Multi Tenancy
|
||||
|
||||
In this example, we're going to create a schema with 3 entity types - `Tenant`, `User` and `Group`.
|
||||
The helper packages `viewer` and `rule` (as mentioned above) also exist in this example to help us structure the application.
|
||||
|
||||
|
||||
|
||||
Let's start building this application piece by piece. We begin by creating 3 different schemas (see the full code [here](https://github.com/ent/ent/tree/master/examples/privacytenant/ent/schema)),
|
||||
and since we want to share some logic between them, we create another [mixed-in schema](schema-mixin.md) and add it to all other schemas as follows:
|
||||
|
||||
```go title="examples/privacytenant/ent/schema/mixin.go"
|
||||
// BaseMixin for all schemas in the graph.
|
||||
type BaseMixin struct {
|
||||
mixin.Schema
|
||||
}
|
||||
|
||||
// Policy defines the privacy policy of the BaseMixin.
|
||||
func (BaseMixin) Policy() ent.Policy {
|
||||
return privacy.Policy{
|
||||
Query: privacy.QueryPolicy{
|
||||
// Deny any query operation in case
|
||||
// there is no "viewer context".
|
||||
rule.DenyIfNoViewer(),
|
||||
// Allow admins to query any information.
|
||||
rule.AllowIfAdmin(),
|
||||
},
|
||||
Mutation: privacy.MutationPolicy{
|
||||
// Deny any mutation operation in case
|
||||
// there is no "viewer context".
|
||||
rule.DenyIfNoViewer(),
|
||||
},
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```go title="examples/privacytenant/ent/schema/tenant.go"
|
||||
// Mixin of the Tenant schema.
|
||||
func (Tenant) Mixin() []ent.Mixin {
|
||||
return []ent.Mixin{
|
||||
BaseMixin{},
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
As explained in the first example, the `DenyIfNoViewer` privacy rule, denies the operation if the `context.Context` does not
|
||||
contain the `viewer.Viewer` information.
|
||||
|
||||
Similar to the previous example, we want to add a constraint that only admin users can create tenants (and deny otherwise).
|
||||
We do it by copying the `AllowIfAdmin` rule from above, and adding it to the `Policy` of the `Tenant` schema:
|
||||
|
||||
```go title="examples/privacytenant/ent/schema/tenant.go"
|
||||
// Policy defines the privacy policy of the User.
|
||||
func (Tenant) Policy() ent.Policy {
|
||||
return privacy.Policy{
|
||||
Mutation: privacy.MutationPolicy{
|
||||
// For Tenant type, we only allow admin users to mutate
|
||||
// the tenant information and deny otherwise.
|
||||
rule.AllowIfAdmin(),
|
||||
privacy.AlwaysDenyRule(),
|
||||
},
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Then, we expect the following code to run successfully:
|
||||
|
||||
```go title="examples/privacytenant/example_test.go"
|
||||
|
||||
func Example_CreateTenants(ctx context.Context, client *ent.Client) {
|
||||
// Expect operation to fail in case viewer-context is missing.
|
||||
// First mutation privacy policy rule defined in BaseMixin.
|
||||
if err := client.Tenant.Create().Exec(ctx); !errors.Is(err, privacy.Deny) {
|
||||
log.Fatal("expect tenant creation to fail, but got:", err)
|
||||
}
|
||||
|
||||
// Expect operation to fail in case the ent.User in the viewer-context
|
||||
// is not an admin user. Privacy policy defined in the Tenant schema.
|
||||
viewCtx := viewer.NewContext(ctx, viewer.UserViewer{Role: viewer.View})
|
||||
if err := client.Tenant.Create().Exec(viewCtx); !errors.Is(err, privacy.Deny) {
|
||||
log.Fatal("expect tenant creation to fail, but got:", err)
|
||||
}
|
||||
|
||||
// Operations should pass successfully as the user in the viewer-context
|
||||
// is an admin user. First mutation privacy policy in Tenant schema.
|
||||
adminCtx := viewer.NewContext(ctx, viewer.UserViewer{Role: viewer.Admin})
|
||||
hub, err := client.Tenant.Create().SetName("GitHub").Save(adminCtx)
|
||||
if err != nil {
|
||||
log.Fatal("expect tenant creation to pass, but got:", err)
|
||||
}
|
||||
fmt.Println(hub)
|
||||
|
||||
lab, err := client.Tenant.Create().SetName("GitLab").Save(adminCtx)
|
||||
if err != nil {
|
||||
log.Fatal("expect tenant creation to pass, but got:", err)
|
||||
}
|
||||
fmt.Println(lab)
|
||||
|
||||
// Output:
|
||||
// Tenant(id=1, name=GitHub)
|
||||
// Tenant(id=2, name=GitLab)
|
||||
}
|
||||
```
|
||||
|
||||
We continue by adding the rest of the edges in our data-model (see image above), and since both `User` and `Group` have
|
||||
an edge to the `Tenant` schema, we create a shared [mixed-in schema](schema-mixin.md) named `TenantMixin` for this:
|
||||
|
||||
```go title="examples/privacytenant/ent/schema/mixin.go"
|
||||
// TenantMixin for embedding the tenant info in different schemas.
|
||||
type TenantMixin struct {
|
||||
mixin.Schema
|
||||
}
|
||||
|
||||
// Fields for all schemas that embed TenantMixin.
|
||||
func (TenantMixin) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Int("tenant_id").
|
||||
Immutable(),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges for all schemas that embed TenantMixin.
|
||||
func (TenantMixin) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("tenant", Tenant.Type).
|
||||
Field("tenant_id").
|
||||
Unique().
|
||||
Required().
|
||||
Immutable(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
#### Filter Rules
|
||||
|
||||
Next, we may want to enforce a rule that will limit viewers to only query groups and users that are connected to the tenant they belong to.
|
||||
For use cases like this, Ent has an additional type of privacy rule named `Filter`.
|
||||
We can use `Filter` rules to filter out entities based on the identity of the viewer.
|
||||
Unlike the rules we previously discussed, `Filter` rules can limit the scope of the queries a viewer can make, in addition to returning privacy decisions.
|
||||
|
||||
:::info Note
|
||||
The privacy filtering option needs to be enabled using the [`entql`](features.md#entql-filtering) feature-flag (see instructions [above](#configuration)).
|
||||
:::
|
||||
|
||||
```go title="examples/privacytenant/rule/rule.go"
|
||||
// FilterTenantRule is a query/mutation rule that filters out entities that are not in the tenant.
|
||||
func FilterTenantRule() privacy.QueryMutationRule {
|
||||
// TenantsFilter is an interface to wrap WhereHasTenantWith()
|
||||
// predicate that is used by both `Group` and `User` schemas.
|
||||
type TenantsFilter interface {
|
||||
WhereTenantID(entql.IntP)
|
||||
}
|
||||
return privacy.FilterFunc(func(ctx context.Context, f privacy.Filter) error {
|
||||
view := viewer.FromContext(ctx)
|
||||
tid, ok := view.Tenant()
|
||||
if !ok {
|
||||
return privacy.Denyf("missing tenant information in viewer")
|
||||
}
|
||||
tf, ok := f.(TenantsFilter)
|
||||
if !ok {
|
||||
return privacy.Denyf("unexpected filter type %T", f)
|
||||
}
|
||||
// Make sure that a tenant reads only entities that have an edge to it.
|
||||
tf.WhereTenantID(entql.IntEQ(tid))
|
||||
// Skip to the next privacy rule (equivalent to return nil).
|
||||
return privacy.Skip
|
||||
})
|
||||
}
|
||||
```
|
||||
|
||||
After creating the `FilterTenantRule` privacy rule, we add it to the `TenantMixin` to make sure **all schemas**
|
||||
that use this mixin, will also have this privacy rule.
|
||||
|
||||
```go title="examples/privacytenant/ent/schema/mixin.go"
|
||||
// Policy for all schemas that embed TenantMixin.
|
||||
func (TenantMixin) Policy() ent.Policy {
|
||||
return rule.FilterTenantRule()
|
||||
}
|
||||
```
|
||||
|
||||
Then, after running the code-generation, we expect the privacy-rules to take effect on the client operations.
|
||||
|
||||
```go title="examples/privacytenant/example_test.go"
|
||||
|
||||
func Example_TenantView(ctx context.Context, client *ent.Client) {
|
||||
// Operations should pass successfully as the user in the viewer-context
|
||||
// is an admin user. First mutation privacy policy in Tenant schema.
|
||||
adminCtx := viewer.NewContext(ctx, viewer.UserViewer{Role: viewer.Admin})
|
||||
hub := client.Tenant.Create().SetName("GitHub").SaveX(adminCtx)
|
||||
lab := client.Tenant.Create().SetName("GitLab").SaveX(adminCtx)
|
||||
|
||||
// Create 2 tenant-specific viewer contexts.
|
||||
hubView := viewer.NewContext(ctx, viewer.UserViewer{T: hub})
|
||||
labView := viewer.NewContext(ctx, viewer.UserViewer{T: lab})
|
||||
|
||||
// Create 2 users in each tenant.
|
||||
hubUsers := client.User.CreateBulk(
|
||||
client.User.Create().SetName("a8m").SetTenant(hub),
|
||||
client.User.Create().SetName("nati").SetTenant(hub),
|
||||
).SaveX(hubView)
|
||||
fmt.Println(hubUsers)
|
||||
|
||||
labUsers := client.User.CreateBulk(
|
||||
client.User.Create().SetName("foo").SetTenant(lab),
|
||||
client.User.Create().SetName("bar").SetTenant(lab),
|
||||
).SaveX(labView)
|
||||
fmt.Println(labUsers)
|
||||
|
||||
// Query users should fail in case viewer-context is missing.
|
||||
if _, err := client.User.Query().Count(ctx); !errors.Is(err, privacy.Deny) {
|
||||
log.Fatal("expect user query to fail, but got:", err)
|
||||
}
|
||||
|
||||
// Ensure each tenant can see only its users.
|
||||
// First and only rule in TenantMixin.
|
||||
fmt.Println(client.User.Query().Select(user.FieldName).StringsX(hubView))
|
||||
fmt.Println(client.User.Query().CountX(hubView))
|
||||
fmt.Println(client.User.Query().Select(user.FieldName).StringsX(labView))
|
||||
fmt.Println(client.User.Query().CountX(labView))
|
||||
|
||||
// Expect admin users to see everything. First
|
||||
// query privacy policy defined in BaseMixin.
|
||||
fmt.Println(client.User.Query().CountX(adminCtx)) // 4
|
||||
|
||||
// Update operation with specific tenant-view should update
|
||||
// only the tenant in the viewer-context.
|
||||
client.User.Update().SetFoods([]string{"pizza"}).SaveX(hubView)
|
||||
fmt.Println(client.User.Query().AllX(hubView))
|
||||
fmt.Println(client.User.Query().AllX(labView))
|
||||
|
||||
// Delete operation with specific tenant-view should delete
|
||||
// only the tenant in the viewer-context.
|
||||
client.User.Delete().ExecX(labView)
|
||||
fmt.Println(
|
||||
client.User.Query().CountX(hubView), // 2
|
||||
client.User.Query().CountX(labView), // 0
|
||||
)
|
||||
|
||||
// DeleteOne with wrong viewer-context is nop.
|
||||
client.User.DeleteOne(hubUsers[0]).ExecX(labView)
|
||||
fmt.Println(client.User.Query().CountX(hubView)) // 2
|
||||
|
||||
// Unlike queries, admin users are not allowed to mutate tenant specific data.
|
||||
if err := client.User.DeleteOne(hubUsers[0]).Exec(adminCtx); !errors.Is(err, privacy.Deny) {
|
||||
log.Fatal("expect user deletion to fail, but got:", err)
|
||||
}
|
||||
|
||||
// Output:
|
||||
// [User(id=1, tenant_id=1, name=a8m, foods=[]) User(id=2, tenant_id=1, name=nati, foods=[])]
|
||||
// [User(id=3, tenant_id=2, name=foo, foods=[]) User(id=4, tenant_id=2, name=bar, foods=[])]
|
||||
// [a8m nati]
|
||||
// 2
|
||||
// [foo bar]
|
||||
// 2
|
||||
// 4
|
||||
// [User(id=1, tenant_id=1, name=a8m, foods=[pizza]) User(id=2, tenant_id=1, name=nati, foods=[pizza])]
|
||||
// [User(id=3, tenant_id=2, name=foo, foods=[]) User(id=4, tenant_id=2, name=bar, foods=[])]
|
||||
// 2 0
|
||||
// 2
|
||||
}
|
||||
```
|
||||
|
||||
We finish our example with another privacy-rule named `DenyMismatchedTenants` on the `Group` schema.
|
||||
The `DenyMismatchedTenants` rule rejects group creation if the associated users do not belong to
|
||||
the same tenant as the group.
|
||||
|
||||
```go title="examples/privacytenant/rule/rule.go"
|
||||
// DenyMismatchedTenants is a rule that runs only on create operations and returns a deny
|
||||
// decision if the operation tries to add users to groups that are not in the same tenant.
|
||||
func DenyMismatchedTenants() privacy.MutationRule {
|
||||
return privacy.GroupMutationRuleFunc(func(ctx context.Context, m *ent.GroupMutation) error {
|
||||
tid, exists := m.TenantID()
|
||||
if !exists {
|
||||
return privacy.Denyf("missing tenant information in mutation")
|
||||
}
|
||||
users := m.UsersIDs()
|
||||
// If there are no users in the mutation, skip this rule-check.
|
||||
if len(users) == 0 {
|
||||
return privacy.Skip
|
||||
}
|
||||
// Query the tenant-ids of all attached users. Expect all users to be connected to the same tenant
|
||||
// as the group. Note, we use privacy.DecisionContext to skip the FilterTenantRule defined above.
|
||||
ids, err := m.Client().User.Query().Where(user.IDIn(users...)).Select(user.FieldTenantID).Ints(privacy.DecisionContext(ctx, privacy.Allow))
|
||||
if err != nil {
|
||||
return privacy.Denyf("querying the tenant-ids %v", err)
|
||||
}
|
||||
if len(ids) != len(users) {
|
||||
return privacy.Denyf("one the attached users is not connected to a tenant %v", err)
|
||||
}
|
||||
for _, id := range ids {
|
||||
if id != tid {
|
||||
return privacy.Denyf("mismatch tenant-ids for group/users %d != %d", tid, id)
|
||||
}
|
||||
}
|
||||
// Skip to the next privacy rule (equivalent to return nil).
|
||||
return privacy.Skip
|
||||
})
|
||||
}
|
||||
```
|
||||
|
||||
We add this rule to the `Group` schema and run code-generation.
|
||||
|
||||
```go title="examples/privacytenant/ent/schema/group.go"
|
||||
// Policy defines the privacy policy of the Group.
|
||||
func (Group) Policy() ent.Policy {
|
||||
return privacy.Policy{
|
||||
Mutation: privacy.MutationPolicy{
|
||||
// Limit DenyMismatchedTenants only for
|
||||
// Create operation
|
||||
privacy.OnMutationOperation(
|
||||
rule.DenyMismatchedTenants(),
|
||||
ent.OpCreate,
|
||||
),
|
||||
},
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Again, we expect the privacy-rules to take effect on the client operations.
|
||||
|
||||
```go title="examples/privacytenant/example_test.go"
|
||||
func Example_DenyMismatchedTenants(ctx context.Context, client *ent.Client) {
|
||||
// Operation should pass successfully as the user in the viewer-context
|
||||
// is an admin user. First mutation privacy policy in Tenant schema.
|
||||
adminCtx := viewer.NewContext(ctx, viewer.UserViewer{Role: viewer.Admin})
|
||||
hub := client.Tenant.Create().SetName("GitHub").SaveX(adminCtx)
|
||||
lab := client.Tenant.Create().SetName("GitLab").SaveX(adminCtx)
|
||||
|
||||
// Create 2 tenant-specific viewer contexts.
|
||||
hubView := viewer.NewContext(ctx, viewer.UserViewer{T: hub})
|
||||
labView := viewer.NewContext(ctx, viewer.UserViewer{T: lab})
|
||||
|
||||
// Create 2 users in each tenant.
|
||||
hubUsers := client.User.CreateBulk(
|
||||
client.User.Create().SetName("a8m").SetTenant(hub),
|
||||
client.User.Create().SetName("nati").SetTenant(hub),
|
||||
).SaveX(hubView)
|
||||
fmt.Println(hubUsers)
|
||||
|
||||
labUsers := client.User.CreateBulk(
|
||||
client.User.Create().SetName("foo").SetTenant(lab),
|
||||
client.User.Create().SetName("bar").SetTenant(lab),
|
||||
).SaveX(labView)
|
||||
fmt.Println(labUsers)
|
||||
|
||||
// Expect operation to fail as the DenyMismatchedTenants rule makes
|
||||
// sure the group and the users are connected to the same tenant.
|
||||
if err := client.Group.Create().SetName("entgo.io").SetTenant(hub).AddUsers(labUsers...).Exec(hubView); !errors.Is(err, privacy.Deny) {
|
||||
log.Fatal("expect operation to fail, since labUsers are not connected to the same tenant")
|
||||
}
|
||||
if err := client.Group.Create().SetName("entgo.io").SetTenant(hub).AddUsers(hubUsers[0], labUsers[0]).Exec(hubView); !errors.Is(err, privacy.Deny) {
|
||||
log.Fatal("expect operation to fail, since labUsers[0] is not connected to the same tenant")
|
||||
}
|
||||
// Expect mutation to pass as all users belong to the same tenant as the group.
|
||||
entgo := client.Group.Create().SetName("entgo.io").SetTenant(hub).AddUsers(hubUsers...).SaveX(hubView)
|
||||
fmt.Println(entgo)
|
||||
|
||||
// Output:
|
||||
// [User(id=1, tenant_id=1, name=a8m, foods=[]) User(id=2, tenant_id=1, name=nati, foods=[])]
|
||||
// [User(id=3, tenant_id=2, name=foo, foods=[]) User(id=4, tenant_id=2, name=bar, foods=[])]
|
||||
// Group(id=1, tenant_id=1, name=entgo.io)
|
||||
}
|
||||
```
|
||||
|
||||
In some cases, we want to reject user operations on entities that do not belong to their tenant **without loading
|
||||
these entities from the database** (unlike the `DenyMismatchedTenants` example above).
|
||||
To achieve this, we rely on the `FilterTenantRule` rule to add its filtering on mutations as well, and expect
|
||||
operations to fail with `NotFoundError` in case the `tenant_id` column does not match the one stored in the
|
||||
viewer-context.
|
||||
|
||||
```go title="examples/privacytenant/example_test.go"
|
||||
func Example_DenyMismatchedView(ctx context.Context, client *ent.Client) {
|
||||
// Continuation of the code above.
|
||||
|
||||
// Expect operation to fail, because the FilterTenantRule rule makes sure
|
||||
// that tenants can update and delete only their groups.
|
||||
if err := entgo.Update().SetName("fail.go").Exec(labView); !ent.IsNotFound(err) {
|
||||
log.Fatal("expect operation to fail, since the group (entgo) is managed by a different tenant (hub), but got:", err)
|
||||
}
|
||||
|
||||
// Operation should pass in case it was applied with the right viewer-context.
|
||||
entgo = entgo.Update().SetName("entgo").SaveX(hubView)
|
||||
fmt.Println(entgo)
|
||||
|
||||
// Output:
|
||||
// Group(id=1, tenant_id=1, name=entgo)
|
||||
}
|
||||
```
|
||||
|
||||
The full example exists in [GitHub](https://github.com/ent/ent/tree/master/examples/privacytenant).
|
||||
|
||||
Please note that this documentation is under active development.
|
||||
137
doc/md/schema-annotations.md
Normal file
137
doc/md/schema-annotations.md
Normal file
@@ -0,0 +1,137 @@
|
||||
---
|
||||
id: schema-annotations
|
||||
title: Annotations
|
||||
---
|
||||
|
||||
Schema annotations allow attaching metadata to schema objects like fields and edges and inject them to external templates.
|
||||
An annotation must be a Go type that is serializable to JSON raw value (e.g. struct, map or slice)
|
||||
and implement the [Annotation](https://pkg.go.dev/entgo.io/ent/schema?tab=doc#Annotation) interface.
|
||||
|
||||
The builtin annotations allow configuring the different storage drivers (like SQL) and control the code generation output.
|
||||
|
||||
## Custom Table Name
|
||||
|
||||
A custom table name can be provided for types using the `entsql` annotation as follows:
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/dialect/entsql"
|
||||
"entgo.io/ent/schema"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Annotations of the User.
|
||||
func (User) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entsql.Annotation{Table: "Users"},
|
||||
}
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Int("age"),
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Custom Table Schema
|
||||
|
||||
Using the [Atlas](https://atlasgo.io) migration engine, an Ent schema can be defined and managed across multiple
|
||||
database schemas. Check out the [multi-schema doc](multischema-migrations.mdx) for more information.
|
||||
|
||||
## Foreign Keys Configuration
|
||||
|
||||
Ent allows to customize the foreign key creation and provide a [referential action](https://dev.mysql.com/doc/refman/8.0/en/create-table-foreign-keys.html#foreign-key-referential-actions)
|
||||
for the `ON DELETE` clause:
|
||||
|
||||
```go title="ent/schema/user.go" {27}
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/dialect/entsql"
|
||||
"entgo.io/ent/schema/edge"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
Default("Unknown"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the User.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("posts", Post.Type).
|
||||
Annotations(entsql.OnDelete(entsql.Cascade)),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The example above configures the foreign key to cascade the deletion of rows in the parent table to the matching
|
||||
rows in the child table.
|
||||
|
||||
## Database Comments
|
||||
|
||||
By default, table and column comments are not stored in the database. However, this functionality can be enabled by
|
||||
using the `WithComments(true)` annotation. For example:
|
||||
|
||||
```go title="ent/schema/user.go" {18-21,34-37}
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/dialect/entsql"
|
||||
"entgo.io/ent/schema"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Annotations of the User.
|
||||
func (User) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
// Adding this annotation to the schema enables
|
||||
// comments for the table and all its fields.
|
||||
entsql.WithComments(true),
|
||||
schema.Comment("Comment that appears in both the schema and the generated code"),
|
||||
}
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
Comment("The user's name"),
|
||||
field.Int("age").
|
||||
Comment("The user's age"),
|
||||
field.String("skipped").
|
||||
Comment("This comment won't be stored in the database").
|
||||
// Explicitly disable comments for this field.
|
||||
Annotations(
|
||||
entsql.WithComments(false),
|
||||
),
|
||||
}
|
||||
}
|
||||
```
|
||||
73
doc/md/schema-def.md
Normal file
73
doc/md/schema-def.md
Normal file
@@ -0,0 +1,73 @@
|
||||
---
|
||||
id: schema-def
|
||||
title: Introduction
|
||||
---
|
||||
|
||||
## Quick Summary
|
||||
|
||||
Schema describes the definition of one entity type in the graph, like `User` or `Group`,
|
||||
and can contain the following configurations:
|
||||
- Entity fields (or properties), like: name or age of a `User`.
|
||||
- Entity edges (or relations), like: `User`'s groups, or `User`'s friends.
|
||||
- Database specific options, like: indexes or unique indexes.
|
||||
|
||||
Here's an example of a schema:
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
"entgo.io/ent/schema/edge"
|
||||
"entgo.io/ent/schema/index"
|
||||
)
|
||||
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Int("age"),
|
||||
field.String("name"),
|
||||
field.String("nickname").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("groups", Group.Type),
|
||||
edge.To("friends", User.Type),
|
||||
}
|
||||
}
|
||||
|
||||
func (User) Indexes() []ent.Index {
|
||||
return []ent.Index{
|
||||
index.Fields("age", "name").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Entity schemas are usually stored inside `ent/schema` directory under
|
||||
the root directory of your project, and can be generated by `entc` as follows:
|
||||
|
||||
```console
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new User Group
|
||||
```
|
||||
|
||||
:::note
|
||||
Please note, that some schema names (like `Client`) are not available due to
|
||||
[internal use](https://pkg.go.dev/entgo.io/ent/entc/gen#ValidSchemaName). You can circumvent reserved names by using an
|
||||
annotation as mentioned [here](schema-annotations.md#custom-table-name).
|
||||
:::
|
||||
|
||||
## It's Just Another ORM
|
||||
|
||||
If you are used to the definition of relations over edges, that's fine.
|
||||
The modeling is the same. You can model with `ent` whatever you can model
|
||||
with other traditional ORMs.
|
||||
There are many examples in this website that can help you get started
|
||||
in the [Edges](schema-edges.mdx) section.
|
||||
1687
doc/md/schema-edges.mdx
Normal file
1687
doc/md/schema-edges.mdx
Normal file
File diff suppressed because it is too large
Load Diff
1038
doc/md/schema-fields.mdx
Normal file
1038
doc/md/schema-fields.mdx
Normal file
File diff suppressed because it is too large
Load Diff
300
doc/md/schema-indexes.md
Normal file
300
doc/md/schema-indexes.md
Normal file
@@ -0,0 +1,300 @@
|
||||
---
|
||||
id: schema-indexes
|
||||
title: Indexes
|
||||
---
|
||||
|
||||
## Multiple Fields
|
||||
|
||||
Indexes can be configured on one or more fields in order to improve
|
||||
speed of data retrieval, or defining uniqueness.
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/index"
|
||||
)
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (User) Indexes() []ent.Index {
|
||||
return []ent.Index{
|
||||
// non-unique index.
|
||||
index.Fields("field1", "field2"),
|
||||
// unique index.
|
||||
index.Fields("first_name", "last_name").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Note that for setting a single field as unique, use the `Unique`
|
||||
method on the field builder as follows:
|
||||
|
||||
```go
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("phone").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Index On Edges
|
||||
|
||||
Indexes can be configured on composition of fields and edges. The main use-case
|
||||
is setting uniqueness on fields under a specific relation. Let's take an example:
|
||||
|
||||

|
||||
|
||||
In the example above, we have a `City` with many `Street`s, and we want to set the
|
||||
street name to be unique under each city.
|
||||
|
||||
`ent/schema/city.go`
|
||||
```go
|
||||
// City holds the schema definition for the City entity.
|
||||
type City struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the City.
|
||||
func (City) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the City.
|
||||
func (City) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("streets", Street.Type),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
`ent/schema/street.go`
|
||||
```go
|
||||
// Street holds the schema definition for the Street entity.
|
||||
type Street struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Street.
|
||||
func (Street) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Street.
|
||||
func (Street) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("city", City.Type).
|
||||
Ref("streets").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
|
||||
// Indexes of the Street.
|
||||
func (Street) Indexes() []ent.Index {
|
||||
return []ent.Index{
|
||||
index.Fields("name").
|
||||
Edges("city").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
`example.go`
|
||||
```go
|
||||
func Do(ctx context.Context, client *ent.Client) error {
|
||||
// Unlike `Save`, `SaveX` panics if an error occurs.
|
||||
tlv := client.City.
|
||||
Create().
|
||||
SetName("TLV").
|
||||
SaveX(ctx)
|
||||
nyc := client.City.
|
||||
Create().
|
||||
SetName("NYC").
|
||||
SaveX(ctx)
|
||||
// Add a street "ST" to "TLV".
|
||||
client.Street.
|
||||
Create().
|
||||
SetName("ST").
|
||||
SetCity(tlv).
|
||||
SaveX(ctx)
|
||||
// This operation fails because "ST"
|
||||
// was already created under "TLV".
|
||||
if err := client.Street.
|
||||
Create().
|
||||
SetName("ST").
|
||||
SetCity(tlv).
|
||||
Exec(ctx); err == nil {
|
||||
return fmt.Errorf("expecting creation to fail")
|
||||
}
|
||||
// Add a street "ST" to "NYC".
|
||||
client.Street.
|
||||
Create().
|
||||
SetName("ST").
|
||||
SetCity(nyc).
|
||||
SaveX(ctx)
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
The full example exists in [GitHub](https://github.com/ent/ent/tree/master/examples/edgeindex).
|
||||
|
||||
## Index On Edge Fields
|
||||
|
||||
Currently `Edges` columns are always added after `Fields` columns. However, some indexes require these columns to come first in order to achieve specific optimizations. You can work around this problem by making use of [Edge Fields](schema-edges.mdx#edge-field).
|
||||
|
||||
```go
|
||||
// Card holds the schema definition for the Card entity.
|
||||
type Card struct {
|
||||
ent.Schema
|
||||
}
|
||||
// Fields of the Card.
|
||||
func (Card) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("number").
|
||||
Optional(),
|
||||
field.Int("owner_id").
|
||||
Optional(),
|
||||
}
|
||||
}
|
||||
// Edges of the Card.
|
||||
func (Card) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("owner", User.Type).
|
||||
Ref("card").
|
||||
Field("owner_id").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
// Indexes of the Card.
|
||||
func (Card) Indexes() []ent.Index {
|
||||
return []ent.Index{
|
||||
index.Fields("owner_id", "number"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Dialect Support
|
||||
|
||||
Dialect specific features are allowed using [annotations](schema-annotations.md). For example, in order to use [index prefixes](https://dev.mysql.com/doc/refman/8.0/en/column-indexes.html#column-indexes-prefix)
|
||||
in MySQL, use the following configuration:
|
||||
|
||||
```go
|
||||
// Indexes of the User.
|
||||
func (User) Indexes() []ent.Index {
|
||||
return []ent.Index{
|
||||
index.Fields("description").
|
||||
Annotations(entsql.Prefix(128)),
|
||||
index.Fields("c1", "c2", "c3").
|
||||
Annotations(
|
||||
entsql.PrefixColumn("c1", 100),
|
||||
entsql.PrefixColumn("c2", 200),
|
||||
)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The code above generates the following SQL statements:
|
||||
|
||||
```sql
|
||||
CREATE INDEX `users_description` ON `users`(`description`(128))
|
||||
|
||||
CREATE INDEX `users_c1_c2_c3` ON `users`(`c1`(100), `c2`(200), `c3`)
|
||||
```
|
||||
|
||||
## Atlas Support
|
||||
|
||||
Starting with v0.10, Ent running migration with [Atlas](https://github.com/ariga/atlas). This option provides
|
||||
more control on indexes such as, configuring their types or define indexes in a reverse order.
|
||||
|
||||
```go
|
||||
func (User) Indexes() []ent.Index {
|
||||
return []ent.Index{
|
||||
index.Fields("c1").
|
||||
Annotations(entsql.Desc()),
|
||||
index.Fields("c1", "c2", "c3").
|
||||
Annotations(entsql.DescColumns("c1", "c2")),
|
||||
index.Fields("c4").
|
||||
Annotations(entsql.IndexType("HASH")),
|
||||
// Enable FULLTEXT search on MySQL,
|
||||
// and GIN on PostgreSQL.
|
||||
index.Fields("c5").
|
||||
Annotations(
|
||||
entsql.IndexTypes(map[string]string{
|
||||
dialect.MySQL: "FULLTEXT",
|
||||
dialect.Postgres: "GIN",
|
||||
}),
|
||||
),
|
||||
// For PostgreSQL, we can include in the index
|
||||
// non-key columns.
|
||||
index.Fields("workplace").
|
||||
Annotations(
|
||||
entsql.IncludeColumns("address"),
|
||||
),
|
||||
// Define a partial index on SQLite and PostgreSQL.
|
||||
index.Fields("nickname").
|
||||
Annotations(
|
||||
entsql.IndexWhere("active"),
|
||||
),
|
||||
// Define a custom operator class.
|
||||
index.Fields("phone").
|
||||
Annotations(
|
||||
entsql.OpClass("bpchar_pattern_ops"),
|
||||
),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The code above generates the following SQL statements:
|
||||
|
||||
```sql
|
||||
CREATE INDEX `users_c1` ON `users` (`c1` DESC)
|
||||
|
||||
CREATE INDEX `users_c1_c2_c3` ON `users` (`c1` DESC, `c2` DESC, `c3`)
|
||||
|
||||
CREATE INDEX `users_c4` ON `users` USING HASH (`c4`)
|
||||
|
||||
-- MySQL only.
|
||||
CREATE FULLTEXT INDEX `users_c5` ON `users` (`c5`)
|
||||
|
||||
-- PostgreSQL only.
|
||||
CREATE INDEX "users_c5" ON "users" USING GIN ("c5")
|
||||
|
||||
-- Include index-only scan on PostgreSQL.
|
||||
CREATE INDEX "users_workplace" ON "users" ("workplace") INCLUDE ("address")
|
||||
|
||||
-- Define partial index on SQLite and PostgreSQL.
|
||||
CREATE INDEX "users_nickname" ON "users" ("nickname") WHERE "active"
|
||||
|
||||
-- PostgreSQL only.
|
||||
CREATE INDEX "users_phone" ON "users" ("phone" bpchar_pattern_ops)
|
||||
```
|
||||
|
||||
## Functional Indexes
|
||||
|
||||
The Ent schema supports defining indexes on fields and edges (foreign-keys), but there is no API for defining index
|
||||
parts as expressions, such as function calls. If you are using [Atlas](https://atlasgo.io/docs) for managing schema
|
||||
migrations, you can define functional indexes as described in [this guide](/docs/migration/functional-indexes).
|
||||
|
||||
## Storage Key
|
||||
|
||||
Like Fields, custom index name can be configured using the `StorageKey` method.
|
||||
It's mapped to an index name in SQL dialects.
|
||||
|
||||
```go
|
||||
func (User) Indexes() []ent.Index {
|
||||
return []ent.Index{
|
||||
index.Fields("field1", "field2").
|
||||
StorageKey("custom_index"),
|
||||
}
|
||||
}
|
||||
```
|
||||
152
doc/md/schema-mixin.md
Normal file
152
doc/md/schema-mixin.md
Normal file
@@ -0,0 +1,152 @@
|
||||
---
|
||||
id: schema-mixin
|
||||
title: Mixin
|
||||
---
|
||||
|
||||
A `Mixin` allows you to create reusable pieces of `ent.Schema` code that can be injected into other schemas
|
||||
using composition.
|
||||
|
||||
The `ent.Mixin` interface is as follows:
|
||||
|
||||
```go
|
||||
type Mixin interface {
|
||||
// Fields returns a slice of fields to add to the schema.
|
||||
Fields() []Field
|
||||
// Edges returns a slice of edges to add to the schema.
|
||||
Edges() []Edge
|
||||
// Indexes returns a slice of indexes to add to the schema.
|
||||
Indexes() []Index
|
||||
// Hooks returns a slice of hooks to add to the schema.
|
||||
// Note that mixin hooks are executed before schema hooks.
|
||||
Hooks() []Hook
|
||||
// Policy returns a privacy policy to add to the schema.
|
||||
// Note that mixin policy are executed before schema policy.
|
||||
Policy() Policy
|
||||
// Annotations returns a list of schema annotations to add
|
||||
// to the schema annotations.
|
||||
Annotations() []schema.Annotation
|
||||
}
|
||||
```
|
||||
|
||||
## Example
|
||||
|
||||
A common use case for `Mixin` is to mix-in a list of common fields to your schema.
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"time"
|
||||
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
"entgo.io/ent/schema/mixin"
|
||||
)
|
||||
|
||||
// -------------------------------------------------
|
||||
// Mixin definition
|
||||
|
||||
// TimeMixin implements the ent.Mixin for sharing
|
||||
// time fields with package schemas.
|
||||
type TimeMixin struct{
|
||||
// We embed the `mixin.Schema` to avoid
|
||||
// implementing the rest of the methods.
|
||||
mixin.Schema
|
||||
}
|
||||
|
||||
func (TimeMixin) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Time("created_at").
|
||||
Immutable().
|
||||
Default(time.Now),
|
||||
field.Time("updated_at").
|
||||
Default(time.Now).
|
||||
UpdateDefault(time.Now),
|
||||
}
|
||||
}
|
||||
|
||||
// DetailsMixin implements the ent.Mixin for sharing
|
||||
// entity details fields with package schemas.
|
||||
type DetailsMixin struct{
|
||||
// We embed the `mixin.Schema` to avoid
|
||||
// implementing the rest of the methods.
|
||||
mixin.Schema
|
||||
}
|
||||
|
||||
func (DetailsMixin) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Int("age").
|
||||
Positive(),
|
||||
field.String("name").
|
||||
NotEmpty(),
|
||||
}
|
||||
}
|
||||
|
||||
// -------------------------------------------------
|
||||
// Schema definition
|
||||
|
||||
// User schema mixed-in the TimeMixin and DetailsMixin fields and therefore
|
||||
// has 5 fields: `created_at`, `updated_at`, `age`, `name` and `nickname`.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (User) Mixin() []ent.Mixin {
|
||||
return []ent.Mixin{
|
||||
TimeMixin{},
|
||||
DetailsMixin{},
|
||||
}
|
||||
}
|
||||
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("nickname").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
|
||||
// Pet schema mixed-in the DetailsMixin fields and therefore
|
||||
// has 3 fields: `age`, `name` and `weight`.
|
||||
type Pet struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (Pet) Mixin() []ent.Mixin {
|
||||
return []ent.Mixin{
|
||||
DetailsMixin{},
|
||||
}
|
||||
}
|
||||
|
||||
func (Pet) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Float("weight"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Builtin Mixin
|
||||
|
||||
Package `mixin` provides a few builtin mixins that can be used
|
||||
for adding the `create_time` and `update_time` fields to the schema.
|
||||
|
||||
In order to use them, add the `mixin.Time` mixin to your schema as follows:
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/mixin"
|
||||
)
|
||||
|
||||
type Pet struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (Pet) Mixin() []ent.Mixin {
|
||||
return []ent.Mixin{
|
||||
mixin.Time{},
|
||||
// Or, mixin.CreateTime only for create_time
|
||||
// and mixin.UpdateTime only for update_time.
|
||||
}
|
||||
}
|
||||
```
|
||||
427
doc/md/schema-view.mdx
Normal file
427
doc/md/schema-view.mdx
Normal file
@@ -0,0 +1,427 @@
|
||||
---
|
||||
id: schema-views
|
||||
title: Views
|
||||
slug: /schema-views
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
Ent supports working with database views. Unlike regular Ent types (schemas), which are usually backed by tables, views
|
||||
act as "virtual tables" and their data results from a query. The following examples demonstrate how to define a `VIEW`
|
||||
in Ent. For more details on the different options, follow the rest of the guide.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="Builder Definition">
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
// CleanUser represents a user without its PII field.
|
||||
type CleanUser struct {
|
||||
ent.View
|
||||
}
|
||||
|
||||
// Annotations of the CleanUser.
|
||||
func (CleanUser) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entsql.ViewFor(dialect.Postgres, func(s *sql.Selector) {
|
||||
s.Select("name", "public_info").From(sql.Table("users"))
|
||||
}),
|
||||
}
|
||||
}
|
||||
|
||||
// Fields of the CleanUser.
|
||||
func (CleanUser) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.String("public_info"),
|
||||
}
|
||||
}
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="Raw Definition">
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
// CleanUser represents a user without its PII field.
|
||||
type CleanUser struct {
|
||||
ent.View
|
||||
}
|
||||
|
||||
// Annotations of the CleanUser.
|
||||
func (CleanUser) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
// Alternatively, you can use raw definitions to define the view.
|
||||
// But note, this definition is skipped if the ViewFor annotation
|
||||
// is defined for the dialect we generated migration to (Postgres).
|
||||
entsql.View(`SELECT name, public_info FROM users`),
|
||||
}
|
||||
}
|
||||
|
||||
// Fields of the CleanUser.
|
||||
func (CleanUser) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.String("public_info"),
|
||||
}
|
||||
}
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="External Definition">
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
// CleanUser represents a user without its PII field.
|
||||
type CleanUser struct {
|
||||
ent.View
|
||||
}
|
||||
|
||||
// View definition is specified in a separate file (`schema.sql`),
|
||||
// and loaded using Atlas' `composite_schema` data-source.
|
||||
|
||||
// Fields of the CleanUser.
|
||||
func (CleanUser) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.String("public_info"),
|
||||
}
|
||||
}
|
||||
```
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
:::info key differences between tables and views
|
||||
- Views are read-only, and therefore, no mutation builders are generated for them. If you want to define insertable/updatable
|
||||
views, define them as regular schemas and follow the guide below to configure their migrations.
|
||||
- Unlike `ent.Schema`, `ent.View` does not have a default `ID` field. If you want to include an `id` field in your view,
|
||||
you can explicitly define it as a field.
|
||||
- Hooks cannot be registered on views, as they are read-only.
|
||||
- Atlas provides built-in support for Ent views, for both versioned migrations and testing. However, if you are not
|
||||
using Atlas and want to use views, you need to manage their migrations manually since Ent does not offer schema
|
||||
migrations for them.
|
||||
:::
|
||||
|
||||
## Introduction
|
||||
|
||||
Views defined in the `ent/schema` package embed the `ent.View` type instead of the `ent.Schema` type. Besides fields,
|
||||
they can have edges, interceptors, and annotations to enable additional integrations. For example:
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
// CleanUser represents a user without its PII field.
|
||||
type CleanUser struct {
|
||||
ent.View
|
||||
}
|
||||
|
||||
// Fields of the CleanUser.
|
||||
func (CleanUser) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
// Note, unlike real schemas (tables, defined with ent.Schema),
|
||||
// the "id" field should be defined manually if needed.
|
||||
field.Int("id"),
|
||||
field.String("name"),
|
||||
field.String("public_info"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Once defined, you can run `go generate ./ent` to create the assets needed to interact with this view. For example:
|
||||
|
||||
```go
|
||||
client.CleanUser.Query().OnlyX(ctx)
|
||||
```
|
||||
|
||||
Note, the `Create`/`Update`/`Delete` builders are not generated for `ent.View`s.
|
||||
|
||||
## Migration and Testing
|
||||
|
||||
After defining the view schema, we need to inform Ent (and Atlas) about the SQL query that defines this view. If not
|
||||
configured, running an Ent query, such as the one defined above, will fail because there is no table named `clean_users`.
|
||||
|
||||
:::note Atlas Guide
|
||||
The rest of the document, assumes you use Ent with [Atlas Pro](https://atlasgo.io/features#pro-plan), as Ent does not have
|
||||
migration support for views or other database objects besides tables and relationships. However, using Atlas or its Pro
|
||||
subscription <u>is not mandatory</u>. Ent does not require a specific migration engine, and as long as the view exists in the
|
||||
database, the client should be able to query it.
|
||||
:::
|
||||
|
||||
To configure our view definition (`AS SELECT ...`), we have two options:
|
||||
1. Define it within the `ent/schema` in Go code.
|
||||
2. Keep the `ent/schema` independent of the view definition and create it externally. Either manually or automatically
|
||||
using Atlas.
|
||||
|
||||
Let's explore both options:
|
||||
|
||||
### Go Definition
|
||||
|
||||
This example demonstrates how to define an `ent.View` with its SQL definition (`AS ...`) specified in the Ent schema.
|
||||
|
||||
The main advantage of this approach is that the `CREATE VIEW` correctness is checked during migration, not during queries.
|
||||
For example, if one of the `ent.Field`s is defined in your `ent/schema` does not exist in your SQL definition, PostgreSQL
|
||||
will return the following error:
|
||||
|
||||
```text
|
||||
// highlight-next-line-error-message
|
||||
create "clean_users" view: pq: CREATE VIEW specifies more column names than columns
|
||||
```
|
||||
|
||||
Here's an example of a view defined along with its fields and its `SELECT` query:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="Builder Definition">
|
||||
|
||||
Using the `entsql.ViewFor` API, you can use a dialect-aware builder to define the view. Note that you can have multiple
|
||||
view definitions for different dialects, and Atlas will use the one that matches the dialect of the migration.
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
// CleanUser represents a user without its PII field.
|
||||
type CleanUser struct {
|
||||
ent.View
|
||||
}
|
||||
|
||||
// Annotations of the CleanUser.
|
||||
func (CleanUser) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entsql.ViewFor(dialect.Postgres, func(s *sql.Selector) {
|
||||
s.Select("id", "name", "public_info").From(sql.Table("users"))
|
||||
}),
|
||||
}
|
||||
}
|
||||
|
||||
// Fields of the CleanUser.
|
||||
func (CleanUser) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
// Note, unlike real schemas (tables, defined with ent.Schema),
|
||||
// the "id" field should be defined manually if needed.
|
||||
field.Int("id"),
|
||||
field.String("name"),
|
||||
field.String("public_info"),
|
||||
}
|
||||
}
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="Raw Definition">
|
||||
|
||||
Alternatively, you can use raw definitions to define the view. But note, this definition is skipped if the `ViewFor`
|
||||
annotation is defined for the dialect we generated migration to (Postgres in this case).
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
// CleanUser represents a user without its PII field.
|
||||
type CleanUser struct {
|
||||
ent.View
|
||||
}
|
||||
|
||||
// Annotations of the CleanUser.
|
||||
func (CleanUser) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entsql.View(`SELECT id, name, public_info FROM users`),
|
||||
}
|
||||
}
|
||||
|
||||
// Fields of the CleanUser.
|
||||
func (CleanUser) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
// Note, unlike real schemas (tables, defined with ent.Schema),
|
||||
// the "id" field should be defined manually if needed.
|
||||
field.Int("id"),
|
||||
field.String("name"),
|
||||
field.String("public_info"),
|
||||
}
|
||||
}
|
||||
```
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
Let's simplify our configuration by creating an `atlas.hcl` file with the necessary parameters. We will use this config
|
||||
file in the [usage](#usage) section below:
|
||||
|
||||
```hcl title="atlas.hcl"
|
||||
env "local" {
|
||||
src = "ent://ent/schema"
|
||||
dev = "docker://postgres/16/dev?search_path=public"
|
||||
}
|
||||
```
|
||||
|
||||
The full example exists in [Ent repository](https://github.com/ent/ent/tree/master/examples/viewschema).
|
||||
|
||||
### External Definition
|
||||
|
||||
This example demonstrates how to define an `ent.View`, but keeps its definition in a separate file (`schema.sql`) or
|
||||
create manually in the database.
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
// CleanUser represents a user without its PII field.
|
||||
type CleanUser struct {
|
||||
ent.View
|
||||
}
|
||||
|
||||
// Fields of the CleanUser.
|
||||
func (CleanUser) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Int("id"),
|
||||
field.String("name"),
|
||||
field.String("public_info"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
After defining the view schema in Ent, the SQL `CREATE VIEW` definition needs to be configured (or created) separately
|
||||
to ensure it exists in the database when queried by the Ent runtime.
|
||||
|
||||
For this example, we will use Atlas' `composite_schema` data source to build a schema graph from our `ent/schema`
|
||||
package and an SQL file describing this view. Let's create a file named `schema.sql` and paste the view definition in it:
|
||||
|
||||
```sql title="schema.sql"
|
||||
-- Create "clean_users" view
|
||||
CREATE VIEW "clean_users" ("id", "name", "public_info") AS SELECT id,
|
||||
name,
|
||||
public_info
|
||||
FROM users;
|
||||
```
|
||||
|
||||
Next, we create an `atlas.hcl` config file with a `composite_schema` that includes both our `ent/schema` and the
|
||||
`schema.sql` file:
|
||||
|
||||
```hcl title="atlas.hcl"
|
||||
data "composite_schema" "app" {
|
||||
# Load the ent schema first with all its tables.
|
||||
schema "public" {
|
||||
url = "ent://ent/schema"
|
||||
}
|
||||
# Then, load the views defined in the schema.sql file.
|
||||
schema "public" {
|
||||
url = "file://schema.sql"
|
||||
}
|
||||
}
|
||||
|
||||
env "local" {
|
||||
src = data.composite_schema.app.url
|
||||
dev = "docker://postgres/15/dev?search_path=public"
|
||||
}
|
||||
```
|
||||
|
||||
The full example exists in [Ent repository](https://github.com/ent/ent/tree/master/examples/viewcomposite).
|
||||
|
||||
## Usage
|
||||
|
||||
After setting up our schema, we can get its representation using the `atlas schema inspect` command, generate migrations for
|
||||
it, apply them to a database, and more. Below are a few commands to get you started with Atlas:
|
||||
|
||||
#### Inspect the Schema
|
||||
|
||||
The `atlas schema inspect` command is commonly used to inspect databases. However, we can also use it to inspect our
|
||||
`ent/schema` and print the SQL representation of it:
|
||||
|
||||
```shell
|
||||
atlas schema inspect \
|
||||
--env local \
|
||||
--url env://src \
|
||||
--format '{{ sql . }}'
|
||||
```
|
||||
|
||||
The command above prints the following SQL. Note, the `clean_users` view is defined in the schema after the `users` table:
|
||||
|
||||
```sql
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "name" character varying NOT NULL, "public_info" character varying NOT NULL, "private_info" character varying NOT NULL, PRIMARY KEY ("id"));
|
||||
-- Create "clean_users" view
|
||||
CREATE VIEW "clean_users" ("id", "name", "public_info") AS SELECT id,
|
||||
name,
|
||||
public_info
|
||||
FROM users;
|
||||
```
|
||||
|
||||
#### Generate Migrations For the Schema
|
||||
|
||||
To generate a migration for the schema, run the following command:
|
||||
|
||||
```shell
|
||||
atlas migrate diff \
|
||||
--env local
|
||||
```
|
||||
|
||||
Note that a new migration file is created with the following content:
|
||||
|
||||
```sql title="migrations/20240712090543.sql"
|
||||
-- Create "users" table
|
||||
CREATE TABLE "users" ("id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY, "name" character varying NOT NULL, "public_info" character varying NOT NULL, "private_info" character varying NOT NULL, PRIMARY KEY ("id"));
|
||||
-- Create "clean_users" view
|
||||
CREATE VIEW "clean_users" ("id", "name", "public_info") AS SELECT id,
|
||||
name,
|
||||
public_info
|
||||
FROM users;
|
||||
```
|
||||
|
||||
#### Apply the Migrations
|
||||
|
||||
To apply the migration generated above to a database, run the following command:
|
||||
|
||||
```
|
||||
atlas migrate apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
:::info Apply the Schema Directly on the Database
|
||||
|
||||
Sometimes, there is a need to apply the schema directly to the database without generating a migration file. For example,
|
||||
when experimenting with schema changes, spinning up a database for testing, etc. In such cases, you can use the command
|
||||
below to apply the schema directly to the database:
|
||||
|
||||
```shell
|
||||
atlas schema apply \
|
||||
--env local \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
Or, when writing tests, you can use the [Atlas Go SDK](https://github.com/ariga/atlas-go-sdk) to align the schema with
|
||||
the database before running assertions:
|
||||
|
||||
```go
|
||||
ac, err := atlasexec.NewClient(".", "atlas")
|
||||
if err != nil {
|
||||
log.Fatalf("failed to initialize client: %w", err)
|
||||
}
|
||||
// Automatically update the database with the desired schema.
|
||||
// Another option, is to use 'migrate apply' or 'schema apply' manually.
|
||||
if _, err := ac.SchemaApply(ctx, &atlasexec.SchemaApplyParams{
|
||||
Env: "local",
|
||||
URL: "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable",
|
||||
AutoApprove: true,
|
||||
}); err != nil {
|
||||
log.Fatalf("failed to apply schema changes: %w", err)
|
||||
}
|
||||
// Run assertions.
|
||||
u1 := client.User.Create().SetName("a8m").SetPrivateInfo("secret").SetPublicInfo("public").SaveX(ctx)
|
||||
v1 := client.CleanUser.Query().OnlyX(ctx)
|
||||
require.Equal(t, u1.ID, v1.ID)
|
||||
require.Equal(t, u1.Name, v1.Name)
|
||||
require.Equal(t, u1.PublicInfo, v1.PublicInfo)
|
||||
```
|
||||
:::
|
||||
|
||||
## Insertable/Updatable Views
|
||||
|
||||
If you want to define an [insertable/updatable view](https://dev.mysql.com/doc/refman/8.4/en/view-updatability.html),
|
||||
set it as regular type (`ent.Schema`) and add the `entsql.Skip()` annotation to it to prevent Ent from generating
|
||||
the `CREATE TABLE` statement for this view. Then, define the view in the database as described in the
|
||||
[external definition](#external-definition) section above.
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
// CleanUser represents a user without its PII field.
|
||||
type CleanUser struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Annotations of the CleanUser.
|
||||
func (CleanUser) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entsql.Skip(),
|
||||
}
|
||||
}
|
||||
|
||||
// Fields of the CleanUser.
|
||||
func (CleanUser) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Int("id"),
|
||||
field.String("name"),
|
||||
field.String("public_info"),
|
||||
}
|
||||
}
|
||||
```
|
||||
152
doc/md/sql-integration.md
Normal file
152
doc/md/sql-integration.md
Normal file
@@ -0,0 +1,152 @@
|
||||
---
|
||||
id: sql-integration
|
||||
title: sql.DB Integration
|
||||
---
|
||||
|
||||
The following examples show how to pass a custom `sql.DB` object to `ent.Client`.
|
||||
|
||||
## Configure `sql.DB`
|
||||
|
||||
First option:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"time"
|
||||
|
||||
"<your_project>/ent"
|
||||
"entgo.io/ent/dialect/sql"
|
||||
)
|
||||
|
||||
func Open() (*ent.Client, error) {
|
||||
drv, err := sql.Open("mysql", "<mysql-dsn>")
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
// Get the underlying sql.DB object of the driver.
|
||||
db := drv.DB()
|
||||
db.SetMaxIdleConns(10)
|
||||
db.SetMaxOpenConns(100)
|
||||
db.SetConnMaxLifetime(time.Hour)
|
||||
return ent.NewClient(ent.Driver(drv)), nil
|
||||
}
|
||||
```
|
||||
|
||||
Second option:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"database/sql"
|
||||
"time"
|
||||
|
||||
"<your_project>/ent"
|
||||
entsql "entgo.io/ent/dialect/sql"
|
||||
)
|
||||
|
||||
func Open() (*ent.Client, error) {
|
||||
db, err := sql.Open("mysql", "<mysql-dsn>")
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
db.SetMaxIdleConns(10)
|
||||
db.SetMaxOpenConns(100)
|
||||
db.SetConnMaxLifetime(time.Hour)
|
||||
// Create an ent.Driver from `db`.
|
||||
drv := entsql.OpenDB("mysql", db)
|
||||
return ent.NewClient(ent.Driver(drv)), nil
|
||||
}
|
||||
```
|
||||
|
||||
## Use Opencensus With MySQL
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"database/sql"
|
||||
"database/sql/driver"
|
||||
|
||||
"<project>/ent"
|
||||
|
||||
"contrib.go.opencensus.io/integrations/ocsql"
|
||||
"entgo.io/ent/dialect"
|
||||
entsql "entgo.io/ent/dialect/sql"
|
||||
"github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
type connector struct {
|
||||
dsn string
|
||||
}
|
||||
|
||||
func (c connector) Connect(context.Context) (driver.Conn, error) {
|
||||
return c.Driver().Open(c.dsn)
|
||||
}
|
||||
|
||||
func (connector) Driver() driver.Driver {
|
||||
return ocsql.Wrap(
|
||||
mysql.MySQLDriver{},
|
||||
ocsql.WithAllTraceOptions(),
|
||||
ocsql.WithRowsClose(false),
|
||||
ocsql.WithRowsNext(false),
|
||||
ocsql.WithDisableErrSkip(true),
|
||||
)
|
||||
}
|
||||
|
||||
// Open new connection and start stats recorder.
|
||||
func Open(dsn string) *ent.Client {
|
||||
db := sql.OpenDB(connector{dsn})
|
||||
// Create an ent.Driver from `db`.
|
||||
drv := entsql.OpenDB(dialect.MySQL, db)
|
||||
return ent.NewClient(ent.Driver(drv))
|
||||
}
|
||||
```
|
||||
|
||||
|
||||
## Use pgx with PostgreSQL
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"database/sql"
|
||||
"log"
|
||||
|
||||
"<project>/ent"
|
||||
|
||||
"entgo.io/ent/dialect"
|
||||
entsql "entgo.io/ent/dialect/sql"
|
||||
_ "github.com/jackc/pgx/v5/stdlib"
|
||||
)
|
||||
|
||||
// Open new connection
|
||||
func Open(databaseUrl string) *ent.Client {
|
||||
db, err := sql.Open("pgx", databaseUrl)
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
|
||||
// Create an ent.Driver from `db`.
|
||||
drv := entsql.OpenDB(dialect.Postgres, db)
|
||||
return ent.NewClient(ent.Driver(drv))
|
||||
}
|
||||
|
||||
func main() {
|
||||
client := Open("postgresql://user:password@127.0.0.1/database")
|
||||
|
||||
// Your code. For example:
|
||||
ctx := context.Background()
|
||||
if err := client.Schema.Create(ctx); err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
users, err := client.User.Query().All(ctx)
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
log.Println(users)
|
||||
}
|
||||
```
|
||||
268
doc/md/templates.md
Normal file
268
doc/md/templates.md
Normal file
@@ -0,0 +1,268 @@
|
||||
---
|
||||
id: templates
|
||||
title: External Templates
|
||||
---
|
||||
|
||||
`ent` accepts external [Go templates](https://golang.org/pkg/text/template) to execute using the `--template` flag.
|
||||
If the template name already defined by `ent`, it will override the existing one. Otherwise, it will write the
|
||||
execution output to a file with the same name as the template. For example:
|
||||
|
||||
`stringer.tmpl` - This template example will be written in a file named: `ent/stringer.go`.
|
||||
|
||||
```gotemplate
|
||||
{{/* The line below tells Intellij/GoLand to enable the autocompletion based on the *gen.Graph type. */}}
|
||||
{{/* gotype: entgo.io/ent/entc/gen.Graph */}}
|
||||
|
||||
{{ define "stringer" }}
|
||||
|
||||
{{/* Add the base header for the generated file */}}
|
||||
{{ $pkg := base $.Config.Package }}
|
||||
{{ template "header" $ }}
|
||||
|
||||
{{/* Loop over all nodes and implement the "GoStringer" interface */}}
|
||||
{{ range $n := $.Nodes }}
|
||||
{{ $receiver := $n.Receiver }}
|
||||
func ({{ $receiver }} *{{ $n.Name }}) GoString() string {
|
||||
if {{ $receiver }} == nil {
|
||||
return fmt.Sprintf("{{ $n.Name }}(nil)")
|
||||
}
|
||||
return {{ $receiver }}.String()
|
||||
}
|
||||
{{ end }}
|
||||
|
||||
{{ end }}
|
||||
```
|
||||
|
||||
`debug.tmpl` - This template example will be written in a file named: `ent/debug.go`.
|
||||
|
||||
```gotemplate
|
||||
{{ define "debug" }}
|
||||
|
||||
{{/* A template that adds the functionality for running each client <T> in debug mode */}}
|
||||
|
||||
{{/* Add the base header for the generated file */}}
|
||||
{{ $pkg := base $.Config.Package }}
|
||||
{{ template "header" $ }}
|
||||
|
||||
{{/* Loop over all nodes and add option the "Debug" method */}}
|
||||
{{ range $n := $.Nodes }}
|
||||
{{ $client := print $n.Name "Client" }}
|
||||
func (c *{{ $client }}) Debug() *{{ $client }} {
|
||||
if c.debug {
|
||||
return c
|
||||
}
|
||||
cfg := config{driver: dialect.Debug(c.driver, c.log), log: c.log, debug: true, hooks: c.hooks}
|
||||
return &{{ $client }}{config: cfg}
|
||||
}
|
||||
{{ end }}
|
||||
|
||||
{{ end }}
|
||||
```
|
||||
|
||||
In order to override an existing template, use its name. For example:
|
||||
```gotemplate
|
||||
{{/* A template for adding additional fields to specific types. */}}
|
||||
{{ define "model/fields/additional" }}
|
||||
{{- /* Add static fields to the "Card" entity. */}}
|
||||
{{- if eq $.Name "Card" }}
|
||||
// StaticField defined by templates.
|
||||
StaticField string `json:"static_field,omitempty"`
|
||||
{{- end }}
|
||||
{{ end }}
|
||||
```
|
||||
|
||||
## Helper Templates
|
||||
|
||||
As mentioned above, `ent` writes each template's execution output to a file named the same as the template.
|
||||
For example, the output from a template defined as `{{ define "stringer" }}` will be written to a file named
|
||||
`ent/stringer.go`.
|
||||
|
||||
By default, `ent` writes each template declared with `{{ define "<name>" }}` to a file. However, it is sometimes
|
||||
desirable to define helper templates - templates that will not be invoked directly but rather be executed by other
|
||||
templates. To facilitate this use case, `ent` supports two naming formats that designate a template as a helper.
|
||||
The formats are:
|
||||
|
||||
1\. `{{ define "helper/.+" }}` for global helper templates. For example:
|
||||
|
||||
```gotemplate
|
||||
{{ define "helper/foo" }}
|
||||
{{/* Logic goes here. */}}
|
||||
{{ end }}
|
||||
|
||||
{{ define "helper/bar/baz" }}
|
||||
{{/* Logic goes here. */}}
|
||||
{{ end }}
|
||||
```
|
||||
|
||||
2\. `{{ define "<root-template>/helper/.+" }}` for local helper templates. A template is considered as "root" if
|
||||
its execution output is written to a file. For example:
|
||||
|
||||
```gotemplate
|
||||
{{/* A root template that is executed on the `gen.Graph` and will be written to a file named: `ent/http.go`.*/}}
|
||||
{{ define "http" }}
|
||||
{{ range $n := $.Nodes }}
|
||||
{{ template "http/helper/get" $n }}
|
||||
{{ template "http/helper/post" $n }}
|
||||
{{ end }}
|
||||
{{ end }}
|
||||
|
||||
{{/* A helper template that is executed on `gen.Type` */}}
|
||||
{{ define "http/helper/get" }}
|
||||
{{/* Logic goes here. */}}
|
||||
{{ end }}
|
||||
|
||||
{{/* A helper template that is executed on `gen.Type` */}}
|
||||
{{ define "http/helper/post" }}
|
||||
{{/* Logic goes here. */}}
|
||||
{{ end }}
|
||||
```
|
||||
|
||||
## Annotations
|
||||
Schema annotations allow attaching metadata to fields and edges and inject them to external templates.
|
||||
An annotation must be a Go type that is serializable to JSON raw value (e.g. struct, map or slice)
|
||||
and implement the [Annotation](https://pkg.go.dev/entgo.io/ent/schema?tab=doc#Annotation) interface.
|
||||
|
||||
Here's an example of an annotation and its usage in schema and template:
|
||||
|
||||
1\. An annotation definition:
|
||||
|
||||
```go
|
||||
package entgql
|
||||
|
||||
// Annotation annotates fields with metadata for templates.
|
||||
type Annotation struct {
|
||||
// OrderField is the ordering field as defined in graphql schema.
|
||||
OrderField string
|
||||
}
|
||||
|
||||
// Name implements ent.Annotation interface.
|
||||
func (Annotation) Name() string {
|
||||
return "EntGQL"
|
||||
}
|
||||
```
|
||||
|
||||
2\. Annotation usage in ent/schema:
|
||||
|
||||
```go
|
||||
// User schema.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the user.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Time("creation_date").
|
||||
Annotations(entgql.Annotation{
|
||||
OrderField: "CREATED_AT",
|
||||
}),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
3\. Annotation usage in external templates:
|
||||
|
||||
```gotemplate
|
||||
{{ range $node := $.Nodes }}
|
||||
{{ range $f := $node.Fields }}
|
||||
{{/* Get the annotation by its name. See: Annotation.Name */}}
|
||||
{{ if $annotation := $f.Annotations.EntGQL }}
|
||||
{{/* Get the field from the annotation. */}}
|
||||
{{ $orderField := $annotation.OrderField }}
|
||||
{{ end }}
|
||||
{{ end }}
|
||||
{{ end }}
|
||||
```
|
||||
|
||||
## Global Annotations
|
||||
|
||||
Global annotation is a type of annotation that is injected into the `gen.Config` object and can be accessed globally
|
||||
in all templates. For example, an annotation that holds a config file information (e.g. `gqlgen.yml` or `swagger.yml`)
|
||||
add can accessed in all templates:
|
||||
|
||||
1\. An annotation definition:
|
||||
|
||||
```go
|
||||
package gqlconfig
|
||||
|
||||
import (
|
||||
"entgo.io/ent/schema"
|
||||
"github.com/99designs/gqlgen/codegen/config"
|
||||
)
|
||||
|
||||
// Annotation defines a custom annotation
|
||||
// to be inject globally to all templates.
|
||||
type Annotation struct {
|
||||
Config *config.Config
|
||||
}
|
||||
|
||||
func (Annotation) Name() string {
|
||||
return "GQL"
|
||||
}
|
||||
|
||||
var _ schema.Annotation = (*Annotation)(nil)
|
||||
```
|
||||
|
||||
2\. Annotation usage in `ent/entc.go`:
|
||||
|
||||
```go
|
||||
func main() {
|
||||
cfg, err := config.LoadConfig("<path to gqlgen.yml>")
|
||||
if err != nil {
|
||||
log.Fatalf("loading gqlgen config: %v", err)
|
||||
}
|
||||
opts := []entc.Option{
|
||||
entc.TemplateDir("./template"),
|
||||
entc.Annotations(gqlconfig.Annotation{Config: cfg}),
|
||||
}
|
||||
err = entc.Generate("./schema", &gen.Config{
|
||||
Templates: entgql.AllTemplates,
|
||||
}, opts...)
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
3\. Annotation usage in external templates:
|
||||
|
||||
```gotemplate
|
||||
{{- with $.Annotations.GQL.Config.StructTag }}
|
||||
{{/* Access the GQL configuration on *gen.Graph */}}
|
||||
{{- end }}
|
||||
|
||||
{{ range $node := $.Nodes }}
|
||||
{{- with $node.Config.Annotations.GQL.Config.StructTag }}
|
||||
{{/* Access the GQL configuration on *gen.Type */}}
|
||||
{{- end }}
|
||||
{{ end }}
|
||||
```
|
||||
|
||||
## Examples
|
||||
- A custom template for implementing the `Node` API for GraphQL -
|
||||
[Github](https://github.com/ent/ent/blob/master/entc/integration/template/ent/template/node.tmpl).
|
||||
|
||||
- An example for executing external templates with custom functions. See [configuration](https://github.com/ent/ent/blob/master/examples/entcpkg/ent/entc.go) and its
|
||||
[README](https://github.com/ent/ent/blob/master/examples/entcpkg) file.
|
||||
|
||||
## Documentation
|
||||
|
||||
Templates are executed on either a specific node type, or the entire schema graph. For API
|
||||
documentation, see the <a target="_blank" href="https://pkg.go.dev/entgo.io/ent/entc/gen?tab=doc">GoDoc</a>.
|
||||
|
||||
## AutoCompletion
|
||||
|
||||
JetBrains users can add the following template annotation to enable the autocompletion in their templates:
|
||||
|
||||
```gotemplate
|
||||
{{/* The line below tells Intellij/GoLand to enable the autocompletion based on the *gen.Graph type. */}}
|
||||
{{/* gotype: entgo.io/ent/entc/gen.Graph */}}
|
||||
|
||||
{{ define "template" }}
|
||||
{{/* ... */}}
|
||||
{{ end }}
|
||||
```
|
||||
|
||||
See it in action:
|
||||
|
||||

|
||||
39
doc/md/testing.md
Normal file
39
doc/md/testing.md
Normal file
@@ -0,0 +1,39 @@
|
||||
---
|
||||
id: testing
|
||||
title: Testing
|
||||
---
|
||||
|
||||
If you're using `ent.Client` in your unit-tests, you can use the generated `enttest`
|
||||
package for creating a client and auto-running the schema migration as follows:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"testing"
|
||||
|
||||
"<project>/ent/enttest"
|
||||
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
)
|
||||
|
||||
func TestXXX(t *testing.T) {
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&_fk=1")
|
||||
defer client.Close()
|
||||
// ...
|
||||
}
|
||||
```
|
||||
|
||||
In order to pass functional options to `Open`, use `enttest.Option`:
|
||||
|
||||
```go
|
||||
func TestXXX(t *testing.T) {
|
||||
opts := []enttest.Option{
|
||||
enttest.WithOptions(ent.Log(t.Log)),
|
||||
enttest.WithMigrateOptions(migrate.WithGlobalUniqueID(true)),
|
||||
}
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&_fk=1", opts...)
|
||||
defer client.Close()
|
||||
// ...
|
||||
}
|
||||
```
|
||||
184
doc/md/transactions.md
Normal file
184
doc/md/transactions.md
Normal file
@@ -0,0 +1,184 @@
|
||||
---
|
||||
id: transactions
|
||||
title: Transactions
|
||||
---
|
||||
|
||||
## Starting A Transaction
|
||||
|
||||
```go
|
||||
// GenTx generates group of entities in a transaction.
|
||||
func GenTx(ctx context.Context, client *ent.Client) error {
|
||||
tx, err := client.Tx(ctx)
|
||||
if err != nil {
|
||||
return fmt.Errorf("starting a transaction: %w", err)
|
||||
}
|
||||
hub, err := tx.Group.
|
||||
Create().
|
||||
SetName("Github").
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return rollback(tx, fmt.Errorf("failed creating the group: %w", err))
|
||||
}
|
||||
// Create the admin of the group.
|
||||
dan, err := tx.User.
|
||||
Create().
|
||||
SetAge(29).
|
||||
SetName("Dan").
|
||||
AddManage(hub).
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return rollback(tx, err)
|
||||
}
|
||||
// Create user "Ariel".
|
||||
a8m, err := tx.User.
|
||||
Create().
|
||||
SetAge(30).
|
||||
SetName("Ariel").
|
||||
AddGroups(hub).
|
||||
AddFriends(dan).
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return rollback(tx, err)
|
||||
}
|
||||
fmt.Println(a8m)
|
||||
// Output:
|
||||
// User(id=2, age=30, name=Ariel)
|
||||
|
||||
// Commit the transaction.
|
||||
return tx.Commit()
|
||||
}
|
||||
|
||||
// rollback calls to tx.Rollback and wraps the given error
|
||||
// with the rollback error if occurred.
|
||||
func rollback(tx *ent.Tx, err error) error {
|
||||
if rerr := tx.Rollback(); rerr != nil {
|
||||
err = fmt.Errorf("%w: %v", err, rerr)
|
||||
}
|
||||
return err
|
||||
}
|
||||
```
|
||||
|
||||
You must call `Unwrap()` if you are querying edges off of a created entity after a successful transaction (example: `a8m.QueryGroups()`). Unwrap restores the state of the underlying client embedded within the entity to a non-transactable version.
|
||||
|
||||
:::warning Note
|
||||
Calling `Unwrap()` on a non-transactional entity (i.e., after a transaction has been committed or rolled back) will
|
||||
cause a panic.
|
||||
:::
|
||||
|
||||
The full example exists in [GitHub](https://github.com/ent/ent/tree/master/examples/traversal).
|
||||
|
||||
## Transactional Client
|
||||
|
||||
Sometimes, you have an existing code that already works with `*ent.Client`, and you want to change it (or wrap it)
|
||||
to interact with transactions. For these use cases, you have a transactional client. An `*ent.Client` that you can
|
||||
get from an existing transaction.
|
||||
|
||||
```go
|
||||
// WrapGen wraps the existing "Gen" function in a transaction.
|
||||
func WrapGen(ctx context.Context, client *ent.Client) error {
|
||||
tx, err := client.Tx(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
txClient := tx.Client()
|
||||
// Use the "Gen" below, but give it the transactional client; no code changes to "Gen".
|
||||
if err := Gen(ctx, txClient); err != nil {
|
||||
return rollback(tx, err)
|
||||
}
|
||||
return tx.Commit()
|
||||
}
|
||||
|
||||
// Gen generates a group of entities.
|
||||
func Gen(ctx context.Context, client *ent.Client) error {
|
||||
// ...
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
The full example exists in [GitHub](https://github.com/ent/ent/tree/master/examples/traversal).
|
||||
|
||||
## Best Practices
|
||||
|
||||
Reusable function that runs callbacks in a transaction:
|
||||
|
||||
```go
|
||||
func WithTx(ctx context.Context, client *ent.Client, fn func(tx *ent.Tx) error) error {
|
||||
tx, err := client.Tx(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
defer func() {
|
||||
if v := recover(); v != nil {
|
||||
tx.Rollback()
|
||||
panic(v)
|
||||
}
|
||||
}()
|
||||
if err := fn(tx); err != nil {
|
||||
if rerr := tx.Rollback(); rerr != nil {
|
||||
err = fmt.Errorf("%w: rolling back transaction: %v", err, rerr)
|
||||
}
|
||||
return err
|
||||
}
|
||||
if err := tx.Commit(); err != nil {
|
||||
return fmt.Errorf("committing transaction: %w", err)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
Its usage:
|
||||
|
||||
```go
|
||||
func Do(ctx context.Context, client *ent.Client) {
|
||||
// WithTx helper.
|
||||
if err := WithTx(ctx, client, func(tx *ent.Tx) error {
|
||||
return Gen(ctx, tx.Client())
|
||||
}); err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Hooks
|
||||
|
||||
Same as [schema hooks](hooks.md#schema-hooks) and [runtime hooks](hooks.md#runtime-hooks), hooks can be registered on
|
||||
active transactions, and will be executed on `Tx.Commit` or `Tx.Rollback`:
|
||||
|
||||
```go
|
||||
func Do(ctx context.Context, client *ent.Client) error {
|
||||
tx, err := client.Tx(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
// Add a hook on Tx.Commit.
|
||||
tx.OnCommit(func(next ent.Committer) ent.Committer {
|
||||
return ent.CommitFunc(func(ctx context.Context, tx *ent.Tx) error {
|
||||
// Code before the actual commit.
|
||||
err := next.Commit(ctx, tx)
|
||||
// Code after the transaction was committed.
|
||||
return err
|
||||
})
|
||||
})
|
||||
// Add a hook on Tx.Rollback.
|
||||
tx.OnRollback(func(next ent.Rollbacker) ent.Rollbacker {
|
||||
return ent.RollbackFunc(func(ctx context.Context, tx *ent.Tx) error {
|
||||
// Code before the actual rollback.
|
||||
err := next.Rollback(ctx, tx)
|
||||
// Code after the transaction was rolled back.
|
||||
return err
|
||||
})
|
||||
})
|
||||
//
|
||||
// <Code goes here>
|
||||
//
|
||||
return err
|
||||
}
|
||||
```
|
||||
|
||||
## Isolation Levels
|
||||
|
||||
Some drivers support tweaking a transaction's isolation level. For example, with the [sql](sql-integration.md) driver, you can do so with the `BeginTx` method.
|
||||
|
||||
```go
|
||||
tx, err := client.BeginTx(ctx, &sql.TxOptions{Isolation: sql.LevelRepeatableRead})
|
||||
```
|
||||
33
doc/md/translations.md
Normal file
33
doc/md/translations.md
Normal file
@@ -0,0 +1,33 @@
|
||||
---
|
||||
id: translations
|
||||
title: Translations
|
||||
---
|
||||
|
||||
## Introduction
|
||||
|
||||
To make Ent more accessible to native speakers of other languages we have started a translation initiative.
|
||||
Our goal is to make all documents in this website available in both Chinese and Japanese. To facilitate the
|
||||
translation, approval and deployment process we have integrated this website with [Crowdin](https://crowdin.com).
|
||||
|
||||
## Contributing
|
||||
|
||||
1. Sign up as a translator on our [Crowdin project](https://crwd.in/ent)
|
||||
2. After registration and sign up, go to our [Project Page](https://crowdin.com/project/ent)
|
||||
3. Pick the language you would like to translate a document into.
|
||||
4. Pick the document you want to translate:
|
||||
* All Docs are under the `md/` folder
|
||||
* Blog Posts are under `website/blog`
|
||||
* Website UI components are under `website/i18n`
|
||||
5. For more information on using the Crowdin UI, please read the [Online Editor documentation](https://support.crowdin.com/online-editor/).
|
||||
6. Your suggestions will be reviewed by a proof-reader, and once approved they will be
|
||||
included in the next website deployment.
|
||||
|
||||
## Joining as a Proof-reader
|
||||
If you would like to contribute in a more permanent way and become a proof-reader
|
||||
for one of the languages, please ping us via the slack channel.
|
||||
|
||||
## Important Guidelines
|
||||
|
||||
- Most documents begin with a line: `id: <document-id>` - this should NEVER be translated and will actually break the website build if it is.
|
||||
- The website build is sensitive to closing of HTML elements, if HTML is needed within the translation it must be closed,
|
||||
or self-closing (i.e. do not leave a dangling `<br>`, make it `<br/>`).
|
||||
216
doc/md/traversals.md
Normal file
216
doc/md/traversals.md
Normal file
@@ -0,0 +1,216 @@
|
||||
---
|
||||
id: traversals
|
||||
title: Graph Traversal
|
||||
---
|
||||
|
||||
For the purpose of the example, we'll generate the following graph:
|
||||
|
||||
|
||||

|
||||
|
||||
The first step is to generate the 3 schemas: `Pet`, `User`, `Group`.
|
||||
|
||||
```console
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new Pet User Group
|
||||
```
|
||||
|
||||
Add the necessary fields and edges for the schemas:
|
||||
|
||||
`ent/schema/pet.go`
|
||||
|
||||
```go
|
||||
// Pet holds the schema definition for the Pet entity.
|
||||
type Pet struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Pet.
|
||||
func (Pet) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Pet.
|
||||
func (Pet) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("friends", Pet.Type),
|
||||
edge.From("owner", User.Type).
|
||||
Ref("pets").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
`ent/schema/user.go`
|
||||
|
||||
```go
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Int("age"),
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the User.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("pets", Pet.Type),
|
||||
edge.To("friends", User.Type),
|
||||
edge.From("groups", Group.Type).
|
||||
Ref("users"),
|
||||
edge.From("manage", Group.Type).
|
||||
Ref("admin"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
`ent/schema/group.go`
|
||||
|
||||
```go
|
||||
// Group holds the schema definition for the Group entity.
|
||||
type Group struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Group.
|
||||
func (Group) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Group.
|
||||
func (Group) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("users", User.Type),
|
||||
edge.To("admin", User.Type).
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Let's write the code for populating the vertices and the edges to the graph:
|
||||
|
||||
```go
|
||||
func Gen(ctx context.Context, client *ent.Client) error {
|
||||
hub, err := client.Group.
|
||||
Create().
|
||||
SetName("Github").
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed creating the group: %w", err)
|
||||
}
|
||||
// Create the admin of the group.
|
||||
// Unlike `Save`, `SaveX` panics if an error occurs.
|
||||
dan := client.User.
|
||||
Create().
|
||||
SetAge(29).
|
||||
SetName("Dan").
|
||||
AddManage(hub).
|
||||
SaveX(ctx)
|
||||
|
||||
// Create "Ariel" and its pets.
|
||||
a8m := client.User.
|
||||
Create().
|
||||
SetAge(30).
|
||||
SetName("Ariel").
|
||||
AddGroups(hub).
|
||||
AddFriends(dan).
|
||||
SaveX(ctx)
|
||||
pedro := client.Pet.
|
||||
Create().
|
||||
SetName("Pedro").
|
||||
SetOwner(a8m).
|
||||
SaveX(ctx)
|
||||
xabi := client.Pet.
|
||||
Create().
|
||||
SetName("Xabi").
|
||||
SetOwner(a8m).
|
||||
SaveX(ctx)
|
||||
|
||||
// Create "Alex" and its pets.
|
||||
alex := client.User.
|
||||
Create().
|
||||
SetAge(37).
|
||||
SetName("Alex").
|
||||
SaveX(ctx)
|
||||
coco := client.Pet.
|
||||
Create().
|
||||
SetName("Coco").
|
||||
SetOwner(alex).
|
||||
AddFriends(pedro).
|
||||
SaveX(ctx)
|
||||
|
||||
fmt.Println("Pets created:", pedro, xabi, coco)
|
||||
// Output:
|
||||
// Pets created: Pet(id=1, name=Pedro) Pet(id=2, name=Xabi) Pet(id=3, name=Coco)
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
Let's go over a few traversals, and show the code for them:
|
||||
|
||||

|
||||
|
||||
The traversal above starts from a `Group` entity, continues to its `admin` (edge),
|
||||
continues to its `friends` (edge), gets their `pets` (edge), gets each pet's `friends` (edge),
|
||||
and requests their owners.
|
||||
|
||||
```go
|
||||
func Traverse(ctx context.Context, client *ent.Client) error {
|
||||
owner, err := client.Group. // GroupClient.
|
||||
Query(). // Query builder.
|
||||
Where(group.Name("Github")). // Filter only Github group (only 1).
|
||||
QueryAdmin(). // Getting Dan.
|
||||
QueryFriends(). // Getting Dan's friends: [Ariel].
|
||||
QueryPets(). // Their pets: [Pedro, Xabi].
|
||||
QueryFriends(). // Pedro's friends: [Coco], Xabi's friends: [].
|
||||
QueryOwner(). // Coco's owner: Alex.
|
||||
Only(ctx) // Expect only one entity to return in the query.
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed querying the owner: %w", err)
|
||||
}
|
||||
fmt.Println(owner)
|
||||
// Output:
|
||||
// User(id=3, age=37, name=Alex)
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
What about the following traversal?
|
||||
|
||||

|
||||
|
||||
We want to get all pets (entities) that have an `owner` (`edge`) that is a `friend`
|
||||
(edge) of some group `admin` (edge).
|
||||
|
||||
```go
|
||||
func Traverse(ctx context.Context, client *ent.Client) error {
|
||||
pets, err := client.Pet.
|
||||
Query().
|
||||
Where(
|
||||
pet.HasOwnerWith(
|
||||
user.HasFriendsWith(
|
||||
user.HasManage(),
|
||||
),
|
||||
),
|
||||
).
|
||||
All(ctx)
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed querying the pets: %w", err)
|
||||
}
|
||||
fmt.Println(pets)
|
||||
// Output:
|
||||
// [Pet(id=1, name=Pedro) Pet(id=2, name=Xabi)]
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
The full example exists in [GitHub](https://github.com/ent/ent/tree/master/examples/traversal).
|
||||
280
doc/md/tutorial-grpc-edges.md
Normal file
280
doc/md/tutorial-grpc-edges.md
Normal file
@@ -0,0 +1,280 @@
|
||||
---
|
||||
id: grpc-edges
|
||||
title: Working with Edges
|
||||
sidebar_label: Working with Edges
|
||||
---
|
||||
Edges enable us to express the relationship between different entities in our ent application. Let's see how they work
|
||||
together with generated gRPC services.
|
||||
|
||||
Let's start by adding a new entity, `Category` and create edges relating our `User` type to it:
|
||||
|
||||
```go title="ent/schema/category.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/contrib/entproto"
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema"
|
||||
"entgo.io/ent/schema/edge"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
type Category struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (Category) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
Annotations(entproto.Field(2)),
|
||||
}
|
||||
}
|
||||
|
||||
func (Category) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entproto.Message(),
|
||||
}
|
||||
}
|
||||
|
||||
func (Category) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("admin", User.Type).
|
||||
Unique().
|
||||
Annotations(entproto.Field(3)),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Creating the inverse relation on the `User`:
|
||||
|
||||
```go title="ent/schema/user.go" {4-6}
|
||||
// Edges of the User.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("administered", Category.Type).
|
||||
Ref("admin").
|
||||
Annotations(entproto.Field(5)),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Notice a few things:
|
||||
|
||||
* Our edges also receive an `entproto.Field` annotation. We will see why in a minute.
|
||||
* We created a one-to-many relationship where a `Category` has a single `admin`, and a `User` can administer multiple
|
||||
categories.
|
||||
|
||||
Re-generating the project with `go generate ./...`, notice the changes to the `.proto` file:
|
||||
|
||||
```protobuf title="ent/proto/entpb/entpb.proto" {1-7,18}
|
||||
message Category {
|
||||
int64 id = 1;
|
||||
|
||||
string name = 2;
|
||||
|
||||
User admin = 3;
|
||||
}
|
||||
|
||||
message User {
|
||||
int64 id = 1;
|
||||
|
||||
string name = 2;
|
||||
|
||||
string email_address = 3;
|
||||
|
||||
google.protobuf.StringValue alias = 4;
|
||||
|
||||
repeated Category administered = 5;
|
||||
}
|
||||
```
|
||||
|
||||
Observe the following changes:
|
||||
|
||||
* A new message, `Category` was created. This message has a field named `admin` corresponding to the `admin` edge on
|
||||
the `Category` schema. It is a non-repeated field because we set the edge to be `.Unique()`. It's field number is `3`,
|
||||
corresponding to the `entproto.Field` annotation on the edge definition.
|
||||
* A new field `administered` was added to the `User` message definition. It is a `repeated` field, corresponding to the
|
||||
fact that we did not mark the edge as `Unique` in this direction. It's field number is `5`, corresponding to the
|
||||
`entproto.Field` annotation on the edge.
|
||||
|
||||
### Creating Entities with their Edges
|
||||
|
||||
Let's demonstrate how to create an entity with its edges by writing a test:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"testing"
|
||||
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
|
||||
"ent-grpc-example/ent/category"
|
||||
"ent-grpc-example/ent/enttest"
|
||||
"ent-grpc-example/ent/proto/entpb"
|
||||
"ent-grpc-example/ent/user"
|
||||
)
|
||||
|
||||
func TestServiceWithEdges(t *testing.T) {
|
||||
// start by initializing an ent client connected to an in memory sqlite instance
|
||||
ctx := context.Background()
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
defer client.Close()
|
||||
|
||||
// next, initialize the UserService. Notice we won't be opening an actual port and
|
||||
// creating a gRPC server and instead we are just calling the library code directly.
|
||||
svc := entpb.NewUserService(client)
|
||||
|
||||
// next, we create a category directly using the ent client.
|
||||
// Notice we are initializing it with no relation to a User.
|
||||
cat := client.Category.Create().SetName("cat_1").SaveX(ctx)
|
||||
|
||||
// next, we invoke the User service's `Create` method. Notice we are
|
||||
// passing a list of entpb.Category instances with only the ID set.
|
||||
create, err := svc.Create(ctx, &entpb.CreateUserRequest{
|
||||
User: &entpb.User{
|
||||
Name: "user",
|
||||
EmailAddress: "user@service.code",
|
||||
Administered: []*entpb.Category{
|
||||
{Id: int64(cat.ID)},
|
||||
},
|
||||
},
|
||||
})
|
||||
if err != nil {
|
||||
t.Fatal("failed creating user using UserService", err)
|
||||
}
|
||||
|
||||
// to verify everything worked correctly, we query the category table to check
|
||||
// we have exactly one category which is administered by the created user.
|
||||
count, err := client.Category.
|
||||
Query().
|
||||
Where(
|
||||
category.HasAdminWith(
|
||||
user.ID(int(create.Id)),
|
||||
),
|
||||
).
|
||||
Count(ctx)
|
||||
if err != nil {
|
||||
t.Fatal("failed counting categories admin by created user", err)
|
||||
}
|
||||
if count != 1 {
|
||||
t.Fatal("expected exactly one group to managed by the created user")
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
|
||||
To create the edge from the created `User` to the existing `Category` we do not need to populate the entire `Category`
|
||||
object. Instead we only populate the `Id` field. This is picked up by the generated service code:
|
||||
|
||||
```go title="ent/proto/entpb/entpb_user_service.go" {3-6}
|
||||
func (svc *UserService) createBuilder(user *User) (*ent.UserCreate, error) {
|
||||
// truncated ...
|
||||
for _, item := range user.GetAdministered() {
|
||||
administered := int(item.GetId())
|
||||
m.AddAdministeredIDs(administered)
|
||||
}
|
||||
return m, nil
|
||||
}
|
||||
```
|
||||
|
||||
### Retrieving Edge IDs for Entities
|
||||
|
||||
We have seen how to create relations between entities, but how do we retrieve that data from the generated gRPC
|
||||
service?
|
||||
|
||||
Consider this example test:
|
||||
|
||||
```go
|
||||
func TestGet(t *testing.T) {
|
||||
// start by initializing an ent client connected to an in memory sqlite instance
|
||||
ctx := context.Background()
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
defer client.Close()
|
||||
|
||||
// next, initialize the UserService. Notice we won't be opening an actual port and
|
||||
// creating a gRPC server and instead we are just calling the library code directly.
|
||||
svc := entpb.NewUserService(client)
|
||||
|
||||
// next, create a user, a category and set that user to be the admin of the category
|
||||
user := client.User.Create().
|
||||
SetName("rotemtam").
|
||||
SetEmailAddress("r@entgo.io").
|
||||
SaveX(ctx)
|
||||
|
||||
client.Category.Create().
|
||||
SetName("category").
|
||||
SetAdmin(user).
|
||||
SaveX(ctx)
|
||||
|
||||
// next, retrieve the user without edge information
|
||||
get, err := svc.Get(ctx, &entpb.GetUserRequest{
|
||||
Id: int64(user.ID),
|
||||
})
|
||||
if err != nil {
|
||||
t.Fatal("failed retrieving the created user", err)
|
||||
}
|
||||
if len(get.Administered) != 0 {
|
||||
t.Fatal("by default edge information is not supposed to be retrieved")
|
||||
}
|
||||
|
||||
// next, retrieve the user *WITH* edge information
|
||||
get, err = svc.Get(ctx, &entpb.GetUserRequest{
|
||||
Id: int64(user.ID),
|
||||
View: entpb.GetUserRequest_WITH_EDGE_IDS,
|
||||
})
|
||||
if err != nil {
|
||||
t.Fatal("failed retrieving the created user", err)
|
||||
}
|
||||
if len(get.Administered) != 1 {
|
||||
t.Fatal("using WITH_EDGE_IDS edges should be returned")
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
As you can see in the test, by default, edge information is not returned by the `Get` method of the service. This is
|
||||
done deliberately because the amount of entities related to an entity is unbound. To allow the caller of to specify
|
||||
whether or not to return the edge information or not, the generated service adheres to [AIP-157](https://google.aip.dev/157)
|
||||
(Partial Responses). In short, the `GetUserRequest` message includes an enum named `View`:
|
||||
|
||||
```protobuf title="ent/proto/entpb/entpb.proto"
|
||||
message GetUserRequest {
|
||||
int64 id = 1;
|
||||
|
||||
View view = 2;
|
||||
|
||||
enum View {
|
||||
VIEW_UNSPECIFIED = 0;
|
||||
|
||||
BASIC = 1;
|
||||
|
||||
WITH_EDGE_IDS = 2;
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Consider the generated code for the `Get` method:
|
||||
|
||||
```go title="ent/proto/entpb/entpb_user_service.go"
|
||||
// Get implements UserServiceServer.Get
|
||||
func (svc *UserService) Get(ctx context.Context, req *GetUserRequest) (*User, error) {
|
||||
// .. truncated ..
|
||||
switch req.GetView() {
|
||||
case GetUserRequest_VIEW_UNSPECIFIED, GetUserRequest_BASIC:
|
||||
get, err = svc.client.User.Get(ctx, int(req.GetId()))
|
||||
case GetUserRequest_WITH_EDGE_IDS:
|
||||
get, err = svc.client.User.Query().
|
||||
Where(user.ID(int(req.GetId()))).
|
||||
WithAdministered(func(query *ent.CategoryQuery) {
|
||||
query.Select(category.FieldID)
|
||||
}).
|
||||
Only(ctx)
|
||||
default:
|
||||
return nil, status.Errorf(codes.InvalidArgument, "invalid argument: unknown view")
|
||||
}
|
||||
// .. truncated ..
|
||||
}
|
||||
```
|
||||
By default, `client.User.Get` is invoked, which does not return any edge ID information, but if `WITH_EDGE_IDS` is passed,
|
||||
the endpoint will retrieve the `ID` field for any `Category` related to the user via the `administered` edge.
|
||||
161
doc/md/tutorial-grpc-ext-service.md
Normal file
161
doc/md/tutorial-grpc-ext-service.md
Normal file
@@ -0,0 +1,161 @@
|
||||
---
|
||||
id: grpc-external-service
|
||||
title: Working with External gRPC Services
|
||||
sidebar_label: External gRPC Services
|
||||
---
|
||||
Oftentimes, you will want to include in your gRPC server, methods that are not automatically generated from
|
||||
your Ent schema. To achieve this result, define the methods in an additional service in an additional `.proto` file
|
||||
in your `entpb` directory.
|
||||
|
||||
:::info
|
||||
|
||||
Find the changes described in this section in [this pull request](https://github.com/rotemtam/ent-grpc-example/pull/7/files).
|
||||
|
||||
:::
|
||||
|
||||
|
||||
For example, suppose you want to add a method named `TopUser` which will return the user with the highest ID number.
|
||||
To do this, create a new `.proto` file in your `entpb` directory, and define a new service:
|
||||
|
||||
```protobuf title="ent/proto/entpb/ext.proto"
|
||||
syntax = "proto3";
|
||||
|
||||
package entpb;
|
||||
|
||||
option go_package = "github.com/rotemtam/ent-grpc-example/ent/proto/entpb";
|
||||
|
||||
import "entpb/entpb.proto";
|
||||
|
||||
import "google/protobuf/empty.proto";
|
||||
|
||||
|
||||
service ExtService {
|
||||
rpc TopUser ( google.protobuf.Empty ) returns ( User );
|
||||
}
|
||||
```
|
||||
|
||||
Next, update `entpb/generate.go` to include the new file in the `protoc` command input:
|
||||
|
||||
```diff title="ent/proto/entpb/generate.go"
|
||||
- //go:generate protoc -I=.. --go_out=.. --go-grpc_out=.. --go_opt=paths=source_relative --go-grpc_opt=paths=source_relative --entgrpc_out=.. --entgrpc_opt=paths=source_relative,schema_path=../../schema entpb/entpb.proto
|
||||
+ //go:generate protoc -I=.. --go_out=.. --go-grpc_out=.. --go_opt=paths=source_relative --go-grpc_opt=paths=source_relative --entgrpc_out=.. --entgrpc_opt=paths=source_relative,schema_path=../../schema entpb/entpb.proto entpb/ext.proto
|
||||
```
|
||||
|
||||
Next, re-run code generation:
|
||||
|
||||
```shell
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Observe some new files were generated in the `ent/proto/entpb` directory:
|
||||
|
||||
```shell
|
||||
tree
|
||||
.
|
||||
|-- entpb.pb.go
|
||||
|-- entpb.proto
|
||||
|-- entpb_grpc.pb.go
|
||||
|-- entpb_user_service.go
|
||||
// highlight-start
|
||||
|-- ext.pb.go
|
||||
|-- ext.proto
|
||||
|-- ext_grpc.pb.go
|
||||
// highlight-end
|
||||
`-- generate.go
|
||||
|
||||
0 directories, 9 files
|
||||
```
|
||||
|
||||
Now, you can implement the `TopUser` method in `ent/proto/entpb/ext.go`:
|
||||
|
||||
```go title="ent/proto/entpb/ext.go"
|
||||
package entpb
|
||||
|
||||
import (
|
||||
"context"
|
||||
|
||||
"github.com/rotemtam/ent-grpc-example/ent"
|
||||
"github.com/rotemtam/ent-grpc-example/ent/user"
|
||||
"google.golang.org/protobuf/types/known/emptypb"
|
||||
)
|
||||
|
||||
// ExtService implements ExtServiceServer.
|
||||
type ExtService struct {
|
||||
client *ent.Client
|
||||
UnimplementedExtServiceServer
|
||||
}
|
||||
|
||||
// TopUser returns the user with the highest ID.
|
||||
func (s *ExtService) TopUser(ctx context.Context, _ *emptypb.Empty) (*User, error) {
|
||||
id := s.client.User.Query().Aggregate(ent.Max(user.FieldID)).IntX(ctx)
|
||||
user := s.client.User.GetX(ctx, id)
|
||||
return toProtoUser(user)
|
||||
}
|
||||
|
||||
// NewExtService returns a new ExtService.
|
||||
func NewExtService(client *ent.Client) *ExtService {
|
||||
return &ExtService{
|
||||
client: client,
|
||||
}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
### Adding the New Service to the gRPC Server
|
||||
|
||||
Finally, update `cmd/server.go` to include the new service:
|
||||
|
||||
```go title="cmd/server.go"
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"net"
|
||||
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
"github.com/rotemtam/ent-grpc-example/ent"
|
||||
"github.com/rotemtam/ent-grpc-example/ent/proto/entpb"
|
||||
"google.golang.org/grpc"
|
||||
)
|
||||
|
||||
func main() {
|
||||
// Initialize an ent client.
|
||||
client, err := ent.Open("sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to sqlite: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
|
||||
// Run the migration tool (creating tables, etc).
|
||||
if err := client.Schema.Create(context.Background()); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
|
||||
// Initialize the generated User service.
|
||||
svc := entpb.NewUserService(client)
|
||||
|
||||
// Create a new gRPC server (you can wire multiple services to a single server).
|
||||
server := grpc.NewServer()
|
||||
|
||||
// highlight-start
|
||||
// Register the User service with the server.
|
||||
entpb.RegisterUserServiceServer(server, svc)
|
||||
// highlight-end
|
||||
|
||||
// Register the external ExtService service with the server.
|
||||
entpb.RegisterExtServiceServer(server, entpb.NewExtService(client))
|
||||
|
||||
// Open port 5000 for listening to traffic.
|
||||
lis, err := net.Listen("tcp", ":5000")
|
||||
if err != nil {
|
||||
log.Fatalf("failed listening: %s", err)
|
||||
}
|
||||
|
||||
// Listen for traffic indefinitely.
|
||||
if err := server.Serve(lis); err != nil {
|
||||
log.Fatalf("server ended: %s", err)
|
||||
}
|
||||
}
|
||||
|
||||
```
|
||||
101
doc/md/tutorial-grpc-generating-a-service.md
Normal file
101
doc/md/tutorial-grpc-generating-a-service.md
Normal file
@@ -0,0 +1,101 @@
|
||||
---
|
||||
id: grpc-generating-a-service
|
||||
title: Generating a gRPC Service
|
||||
sidebar_label: Generating a Service
|
||||
---
|
||||
Generating Protobuf structs generated from our `ent.Schema` can be useful, but what we're really interested in is getting an actual server that can create, read, update, and delete entities from an actual database. To do that, we need to update just one line of code! When we annotate a schema with `entproto.Service`, we tell the `entproto` code-gen that we are interested in generating a gRPC service definition, from the `protoc-gen-entgrpc` will read our definition and generate a service implementation. Edit `ent/schema/user.go` and modify the schema's `Annotations`:
|
||||
|
||||
```go title="ent/schema/user.go" {4}
|
||||
func (User) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entproto.Message(),
|
||||
entproto.Service(), // <-- add this
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Now re-run code-generation:
|
||||
|
||||
```console
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Observe some interesting changes in `ent/proto/entpb`:
|
||||
|
||||
```console
|
||||
ent/proto/entpb
|
||||
├── entpb.pb.go
|
||||
├── entpb.proto
|
||||
├── entpb_grpc.pb.go
|
||||
├── entpb_user_service.go
|
||||
└── generate.go
|
||||
```
|
||||
|
||||
First, `entproto` added a service definition to `entpb.proto`:
|
||||
|
||||
```protobuf title="ent/proto/entpb/entpb.proto"
|
||||
service UserService {
|
||||
rpc Create ( CreateUserRequest ) returns ( User );
|
||||
|
||||
rpc Get ( GetUserRequest ) returns ( User );
|
||||
|
||||
rpc Update ( UpdateUserRequest ) returns ( User );
|
||||
|
||||
rpc Delete ( DeleteUserRequest ) returns ( google.protobuf.Empty );
|
||||
|
||||
rpc List ( ListUserRequest ) returns ( ListUserResponse );
|
||||
|
||||
rpc BatchCreate ( BatchCreateUsersRequest ) returns ( BatchCreateUsersResponse );
|
||||
}
|
||||
```
|
||||
|
||||
In addition, two new files were created. The first, `entpb_grpc.pb.go`, contains the gRPC client stub and the interface definition. If you open the file, you will find in it (among many other things):
|
||||
|
||||
```go title="ent/proto/entpb/entpb_grpc.pb.go"
|
||||
// UserServiceClient is the client API for UserService service.
|
||||
//
|
||||
// For semantics around ctx use and closing/ending streaming RPCs, please
|
||||
// refer to https://pkg.go.dev/google.golang.org/grpc/?tab=doc#ClientConn.NewStream.
|
||||
type UserServiceClient interface {
|
||||
Create(ctx context.Context, in *CreateUserRequest, opts ...grpc.CallOption) (*User, error)
|
||||
Get(ctx context.Context, in *GetUserRequest, opts ...grpc.CallOption) (*User, error)
|
||||
Update(ctx context.Context, in *UpdateUserRequest, opts ...grpc.CallOption) (*User, error)
|
||||
Delete(ctx context.Context, in *DeleteUserRequest, opts ...grpc.CallOption) (*emptypb.Empty, error)
|
||||
List(ctx context.Context, in *ListUserRequest, opts ...grpc.CallOption) (*ListUserResponse, error)
|
||||
BatchCreate(ctx context.Context, in *BatchCreateUsersRequest, opts ...grpc.CallOption) (*BatchCreateUsersResponse, error)
|
||||
}
|
||||
```
|
||||
|
||||
The second file, `entpub_user_service.go` contains a generated implementation for this interface. For example, an implementation for the `Get` method:
|
||||
|
||||
```go title="ent/proto/entpb/entpb_user_service.go"
|
||||
// Get implements UserServiceServer.Get
|
||||
func (svc *UserService) Get(ctx context.Context, req *GetUserRequest) (*User, error) {
|
||||
var (
|
||||
err error
|
||||
get *ent.User
|
||||
)
|
||||
id := int(req.GetId())
|
||||
switch req.GetView() {
|
||||
case GetUserRequest_VIEW_UNSPECIFIED, GetUserRequest_BASIC:
|
||||
get, err = svc.client.User.Get(ctx, id)
|
||||
case GetUserRequest_WITH_EDGE_IDS:
|
||||
get, err = svc.client.User.Query().
|
||||
Where(user.ID(id)).
|
||||
Only(ctx)
|
||||
default:
|
||||
return nil, status.Error(codes.InvalidArgument, "invalid argument: unknown view")
|
||||
}
|
||||
switch {
|
||||
case err == nil:
|
||||
return toProtoUser(get)
|
||||
case ent.IsNotFound(err):
|
||||
return nil, status.Errorf(codes.NotFound, "not found: %s", err)
|
||||
default:
|
||||
return nil, status.Errorf(codes.Internal, "internal error: %s", err)
|
||||
}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
Not bad! Next, let's create a gRPC server that can serve requests to our service.
|
||||
139
doc/md/tutorial-grpc-generating-proto.md
Normal file
139
doc/md/tutorial-grpc-generating-proto.md
Normal file
@@ -0,0 +1,139 @@
|
||||
---
|
||||
id: grpc-generating-proto
|
||||
title: Generating Protobufs with entproto
|
||||
sidebar_label: Generating Protobufs
|
||||
---
|
||||
As Ent and Protobuf schemas are not identical, we must supply some annotations on our schema to help `entproto` figure out exactly how to generate Protobuf definitions (called "Messages" in protobuf terminology).
|
||||
|
||||
The first thing we need to do is to add an `entproto.Message()` annotation. This is our opt-in to Protobuf schema generation, we don't necessarily want to generate proto messages or gRPC service definitions from *all* of our schema entities, and this annotation gives us that control. To add it, append to `ent/schema/user.go`:
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
func (User) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entproto.Message(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Next, we need to annotate each field and assign it a field number. Recall that when [defining a protobuf message type](https://developers.google.com/protocol-buffers/docs/proto3#simple), each field must be assigned a unique number. To do that, we add an `entproto.Field` annotation on each field. Update the `Fields` in `ent/schema/user.go`:
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
Unique().
|
||||
Annotations(
|
||||
entproto.Field(2),
|
||||
),
|
||||
field.String("email_address").
|
||||
Unique().
|
||||
Annotations(
|
||||
entproto.Field(3),
|
||||
),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Notice that we did not start our field numbers from 1, this is because `ent` implicitly creates the `ID` field for the entity, and that field is automatically assigned the number 1. We can now generate our protobuf message type definitions. To do that, we will add to `ent/generate.go` a `go:generate` directive that invokes the `entproto` command-line tool. It should now look like this:
|
||||
|
||||
```go title="ent/generate.go"
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entgo.io/ent/cmd/ent generate ./schema
|
||||
//go:generate go run -mod=mod entgo.io/contrib/entproto/cmd/entproto -path ./schema
|
||||
```
|
||||
|
||||
Let's re-generate our code:
|
||||
|
||||
```console
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Observe that a new directory was created which will contain all protobuf related generated code: `ent/proto`. It now contains:
|
||||
|
||||
```console
|
||||
ent/proto
|
||||
└── entpb
|
||||
├── entpb.proto
|
||||
└── generate.go
|
||||
```
|
||||
|
||||
Two files were created. Let's look at their contents:
|
||||
|
||||
```protobuf title="ent/proto/entpb/entpb.proto"
|
||||
// Code generated by entproto. DO NOT EDIT.
|
||||
syntax = "proto3";
|
||||
|
||||
package entpb;
|
||||
|
||||
option go_package = "ent-grpc-example/ent/proto/entpb";
|
||||
|
||||
message User {
|
||||
int32 id = 1;
|
||||
|
||||
string user_name = 2;
|
||||
|
||||
string email_address = 3;
|
||||
}
|
||||
```
|
||||
|
||||
Nice! A new `.proto` file containing a message type definition that maps to our `User` schema was created!
|
||||
|
||||
```go title="ent/proto/entpb/generate.go"
|
||||
package entpb
|
||||
//go:generate protoc -I=.. --go_out=.. --go-grpc_out=.. --go_opt=paths=source_relative --go-grpc_opt=paths=source_relative --entgrpc_out=.. --entgrpc_opt=paths=source_relative,schema_path=../../schema entpb/entpb.proto
|
||||
```
|
||||
|
||||
A new `generate.go` file was created with an invocation to `protoc`, the protobuf code generator instructing it how to generate Go code from our `.proto` file. For this command to work, we must first install `protoc` as well as 3 protobuf plugins: `protoc-gen-go` (which generates Go Protobuf structs), `protoc-gen-go-grpc` (which generates Go gRPC service interfaces and clients), and `protoc-gen-entgrpc` (which generates an implementation of the service interface). If you do not have these installed, please follow these directions:
|
||||
|
||||
- [protoc installation](https://grpc.io/docs/protoc-installation/)
|
||||
- [protoc-gen-go + protoc-gen-go-grpc installation](https://grpc.io/docs/languages/go/quickstart/)
|
||||
- To install `protoc-gen-entgrpc`, run:
|
||||
|
||||
```
|
||||
go install entgo.io/contrib/entproto/cmd/protoc-gen-entgrpc@master
|
||||
```
|
||||
|
||||
After installing these dependencies, we can re-run code-generation:
|
||||
|
||||
```console
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Observe that a new file named `ent/proto/entpb/entpb.pb.go` was created which contains the generated Go structs for our entities.
|
||||
|
||||
Let's write a test that uses it to make sure everything is wired correctly. Create a new file named `pb_test.go` and write:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"testing"
|
||||
|
||||
"ent-grpc-example/ent/proto/entpb"
|
||||
)
|
||||
|
||||
func TestUserProto(t *testing.T) {
|
||||
user := entpb.User{
|
||||
Name: "rotemtam",
|
||||
EmailAddress: "rotemtam@example.com",
|
||||
}
|
||||
if user.GetName() != "rotemtam" {
|
||||
t.Fatal("expected user name to be rotemtam")
|
||||
}
|
||||
if user.GetEmailAddress() != "rotemtam@example.com" {
|
||||
t.Fatal("expected email address to be rotemtam@example.com")
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
To run it:
|
||||
|
||||
```console
|
||||
go get -u ./... # install deps of the generated package
|
||||
go test ./...
|
||||
```
|
||||
|
||||
Hooray! The test passes. We have successfully generated working Go Protobuf structs from our Ent schema. Next, let's see how to automatically generate a working CRUD gRPC *server* from our schema.
|
||||
|
||||
25
doc/md/tutorial-grpc-intro.md
Normal file
25
doc/md/tutorial-grpc-intro.md
Normal file
@@ -0,0 +1,25 @@
|
||||
---
|
||||
id: grpc-intro
|
||||
title: gRPC Introduction
|
||||
sidebar_label: Introduction
|
||||
---
|
||||
[gRPC](https://grpc.io) is a popular RPC framework open-sourced by Google, and based on an internal system developed
|
||||
there named "Stubby". It is based on [Protocol Buffers](https://developers.google.com/protocol-buffers), Google's
|
||||
language-neutral, platform-neutral extensible mechanism for serializing structured data.
|
||||
|
||||
Ent supports the automatic generation of gRPC services from schemas using a plugin available in [ent/contrib](https://github.com/ent/contrib).
|
||||
|
||||
On a high-level, the integration between Ent and gRPC works like this:
|
||||
* A command-line (or code-gen hook) named `entproto` is used to generate protocol buffer definitions and gRPC service
|
||||
definitions from an ent schema. The schema is annotated using `entproto` annotations to assist the mapping between
|
||||
the domains.
|
||||
* A protoc (protobuf compiler) plugin, `protoc-gen-entgrpc`, is used to generate an implementation of the gRPC service
|
||||
definition generated by `entproto` that uses the project's `ent.Client` to read and write from the database.
|
||||
* A gRPC server that embeds the generated service implementation is written by the developer.
|
||||
|
||||
In this tutorial we will build a fully working gRPC server using the Ent/gRPC integration.
|
||||
|
||||
### Code
|
||||
|
||||
The final code for this tutorial can be found in [rotemtam/ent-grpc-example](https://github.com/rotemtam/ent-grpc-example).
|
||||
|
||||
93
doc/md/tutorial-grpc-optional-fields.md
Normal file
93
doc/md/tutorial-grpc-optional-fields.md
Normal file
@@ -0,0 +1,93 @@
|
||||
---
|
||||
id: grpc-optional-fields
|
||||
title: Optional Fields
|
||||
sidebar_label: Optional Fields
|
||||
---
|
||||
A common issue with Protobufs is that the way that nil values are represented: a zero-valued primitive field isn't
|
||||
encoded into the binary representation, this means that applications cannot distinguish between zero and not-set for
|
||||
primitive fields.
|
||||
|
||||
To support this, the Protobuf project supports some [Well-Known types](https://developers.google.com/protocol-buffers/docs/reference/google.protobuf) called "wrapper types".
|
||||
For example, the wrapper type for a `bool`, is called `google.protobuf.BoolValue` and is [defined as](https://github.com/protocolbuffers/protobuf/blob/991bcada050d7e9919503adef5b52547ec249d35/src/google/protobuf/wrappers.proto#L103-L107):
|
||||
```protobuf title="ent/proto/entpb/entpb.proto"
|
||||
// Wrapper message for `bool`.
|
||||
//
|
||||
// The JSON representation for `BoolValue` is JSON `true` and `false`.
|
||||
message BoolValue {
|
||||
// The bool value.
|
||||
bool value = 1;
|
||||
}
|
||||
```
|
||||
When `entproto` generates a Protobuf message definition, it uses these wrapper types to represent "Optional" ent fields.
|
||||
|
||||
Let's see this in action, modifying our ent schema to include an optional field:
|
||||
|
||||
```go title="ent/schema/user.go" {14-16}
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
Unique().
|
||||
Annotations(
|
||||
entproto.Field(2),
|
||||
),
|
||||
field.String("email_address").
|
||||
Unique().
|
||||
Annotations(
|
||||
entproto.Field(3),
|
||||
),
|
||||
field.String("alias").
|
||||
Optional().
|
||||
Annotations(entproto.Field(4)),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Re-running `go generate ./...`, observe that our Protobuf definition for `User` now looks like:
|
||||
|
||||
```protobuf title="ent/proto/entpb/entpb.proto" {8}
|
||||
message User {
|
||||
int32 id = 1;
|
||||
|
||||
string name = 2;
|
||||
|
||||
string email_address = 3;
|
||||
|
||||
google.protobuf.StringValue alias = 4; // <-- this is new
|
||||
|
||||
repeated Category administered = 5;
|
||||
}
|
||||
```
|
||||
|
||||
The generated service implementation also utilize this field. Observe in `entpb_user_service.go`:
|
||||
|
||||
```go title="ent/proto/entpb/entpb_user_service.go" {3-6}
|
||||
func (svc *UserService) createBuilder(user *User) (*ent.UserCreate, error) {
|
||||
m := svc.client.User.Create()
|
||||
if user.GetAlias() != nil {
|
||||
userAlias := user.GetAlias().GetValue()
|
||||
m.SetAlias(userAlias)
|
||||
}
|
||||
userEmailAddress := user.GetEmailAddress()
|
||||
m.SetEmailAddress(userEmailAddress)
|
||||
userName := user.GetName()
|
||||
m.SetName(userName)
|
||||
for _, item := range user.GetAdministered() {
|
||||
administered := int(item.GetId())
|
||||
m.AddAdministeredIDs(administered)
|
||||
}
|
||||
return m, nil
|
||||
}
|
||||
```
|
||||
|
||||
To use the wrapper types in our client code, we can use helper methods supplied by the [wrapperspb](https://github.com/protocolbuffers/protobuf-go/blob/3f51f05e40d61e930a5416f1ed7092cef14cc058/types/known/wrapperspb/wrappers.pb.go#L458-L460)
|
||||
package to easily build instances of these types. For example in `cmd/client/main.go`:
|
||||
```go {5}
|
||||
func randomUser() *entpb.User {
|
||||
return &entpb.User{
|
||||
Name: fmt.Sprintf("user_%d", rand.Int()),
|
||||
EmailAddress: fmt.Sprintf("user_%d@example.com", rand.Int()),
|
||||
Alias: wrapperspb.String("John Doe"),
|
||||
}
|
||||
}
|
||||
```
|
||||
158
doc/md/tutorial-grpc-server-and-client.md
Normal file
158
doc/md/tutorial-grpc-server-and-client.md
Normal file
@@ -0,0 +1,158 @@
|
||||
---
|
||||
id: grpc-server-and-client
|
||||
title: Creating the Server and Client
|
||||
sidebar_label: Server and Client
|
||||
---
|
||||
|
||||
Getting an automatically generated gRPC service definition is super cool, but we still need to register it to a
|
||||
concrete gRPC server, that listens on some TCP port for traffic and is able to respond to RPC calls.
|
||||
|
||||
We decided not to generate this part automatically because it typically involves some team/org specific
|
||||
behavior such as wiring in different middlewares. This may change in the future. In the meantime, this section
|
||||
describes how to create a simple gRPC server that will serve our service code.
|
||||
|
||||
### Creating the Server
|
||||
|
||||
Create a new file `cmd/server/main.go` and write:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"net"
|
||||
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
"ent-grpc-example/ent"
|
||||
"ent-grpc-example/ent/proto/entpb"
|
||||
"google.golang.org/grpc"
|
||||
)
|
||||
|
||||
func main() {
|
||||
// Initialize an ent client.
|
||||
client, err := ent.Open("sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to sqlite: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
|
||||
// Run the migration tool (creating tables, etc).
|
||||
if err := client.Schema.Create(context.Background()); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
|
||||
// Initialize the generated User service.
|
||||
svc := entpb.NewUserService(client)
|
||||
|
||||
// Create a new gRPC server (you can wire multiple services to a single server).
|
||||
server := grpc.NewServer()
|
||||
|
||||
// Register the User service with the server.
|
||||
entpb.RegisterUserServiceServer(server, svc)
|
||||
|
||||
// Open port 5000 for listening to traffic.
|
||||
lis, err := net.Listen("tcp", ":5000")
|
||||
if err != nil {
|
||||
log.Fatalf("failed listening: %s", err)
|
||||
}
|
||||
|
||||
// Listen for traffic indefinitely.
|
||||
if err := server.Serve(lis); err != nil {
|
||||
log.Fatalf("server ended: %s", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Notice that we added an import of `github.com/mattn/go-sqlite3`, so we need to add it to our module:
|
||||
|
||||
```console
|
||||
go get -u github.com/mattn/go-sqlite3
|
||||
```
|
||||
|
||||
Next, let's run the server, while we write a client that will communicate with it:
|
||||
|
||||
```console
|
||||
go run -mod=mod ./cmd/server
|
||||
```
|
||||
|
||||
### Creating the Client
|
||||
|
||||
Let's create a simple client that makes some calls to our server. Create a new file named `cmd/client/main.go` and write:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"fmt"
|
||||
"log"
|
||||
"math/rand"
|
||||
"time"
|
||||
|
||||
"ent-grpc-example/ent/proto/entpb"
|
||||
"google.golang.org/grpc"
|
||||
"google.golang.org/grpc/status"
|
||||
)
|
||||
|
||||
func main() {
|
||||
rand.Seed(time.Now().UnixNano())
|
||||
|
||||
// Open a connection to the server.
|
||||
conn, err := grpc.Dial(":5000", grpc.WithTransportCredentials(insecure.NewCredentials()))
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to server: %s", err)
|
||||
}
|
||||
defer conn.Close()
|
||||
|
||||
// Create a User service Client on the connection.
|
||||
client := entpb.NewUserServiceClient(conn)
|
||||
|
||||
// Ask the server to create a random User.
|
||||
ctx := context.Background()
|
||||
user := randomUser()
|
||||
created, err := client.Create(ctx, &entpb.CreateUserRequest{
|
||||
User: user,
|
||||
})
|
||||
if err != nil {
|
||||
se, _ := status.FromError(err)
|
||||
log.Fatalf("failed creating user: status=%s message=%s", se.Code(), se.Message())
|
||||
}
|
||||
log.Printf("user created with id: %d", created.Id)
|
||||
|
||||
// On a separate RPC invocation, retrieve the user we saved previously.
|
||||
get, err := client.Get(ctx, &entpb.GetUserRequest{
|
||||
Id: created.Id,
|
||||
})
|
||||
if err != nil {
|
||||
se, _ := status.FromError(err)
|
||||
log.Fatalf("failed retrieving user: status=%s message=%s", se.Code(), se.Message())
|
||||
}
|
||||
log.Printf("retrieved user with id=%d: %v", get.Id, get)
|
||||
}
|
||||
|
||||
func randomUser() *entpb.User {
|
||||
return &entpb.User{
|
||||
Name: fmt.Sprintf("user_%d", rand.Int()),
|
||||
EmailAddress: fmt.Sprintf("user_%d@example.com", rand.Int()),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Our client creates a connection to port 5000, where our server is listening, then issues a `Create`
|
||||
request to create a new user, and then issues a second `Get` request to retrieve it from the database.
|
||||
Let's run our client code:
|
||||
|
||||
```console
|
||||
go run ./cmd/client
|
||||
```
|
||||
|
||||
Observe the output:
|
||||
|
||||
```console
|
||||
2021/03/18 10:42:58 user created with id: 1
|
||||
2021/03/18 10:42:58 retrieved user with id=1: id:1 name:"user_730811260095307266" email_address:"user_7338662242574055998@example.com"
|
||||
```
|
||||
|
||||
Hooray! We have successfully created a real gRPC client to talk to our real gRPC server! In the next sections, we will
|
||||
see how the ent/gRPC integration deals with more advanced ent schema definitions.
|
||||
58
doc/md/tutorial-grpc-service-generation-options.md
Normal file
58
doc/md/tutorial-grpc-service-generation-options.md
Normal file
@@ -0,0 +1,58 @@
|
||||
---
|
||||
id: grpc-service-generation-options
|
||||
title: Configuring Service Method Generation
|
||||
sidebar_label: Service Generation Options
|
||||
---
|
||||
By default, entproto will generate a number of service methods for an `ent.Schema` annotated with `ent.Service()`. Method generation can be customized by including the argument `entproto.Methods()` in the `entproto.Service()` annotation. `entproto.Methods()` accepts bit flags to determine what service methods should be generated. The flags include:
|
||||
```go
|
||||
// Generates a Create gRPC service method for the entproto.Service.
|
||||
entproto.MethodCreate
|
||||
|
||||
// Generates a Get gRPC service method for the entproto.Service.
|
||||
entproto.MethodGet
|
||||
|
||||
// Generates an Update gRPC service method for the entproto.Service.
|
||||
entproto.MethodUpdate
|
||||
|
||||
// Generates a Delete gRPC service method for the entproto.Service.
|
||||
entproto.MethodDelete
|
||||
|
||||
// Generates a List gRPC service method for the entproto.Service.
|
||||
entproto.MethodList
|
||||
|
||||
// Generates a Batch Create gRPC service method for the entproto.Service.
|
||||
entproto.MethodBatchCreate
|
||||
|
||||
// Generates all service methods for the entproto.Service.
|
||||
// This is the same behavior as not including entproto.Methods.
|
||||
entproto.MethodAll
|
||||
```
|
||||
To generate a service with multiple methods, bitwise OR the flags.
|
||||
|
||||
|
||||
To see this in action, we can modify our ent schema. Let's say we wanted to prevent our gRPC client from mutating entries. We can accomplish this by modifying `ent/schema/user.go`:
|
||||
```go title="ent/schema/user.go" {5}
|
||||
func (User) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entproto.Message(),
|
||||
entproto.Service(
|
||||
entproto.Methods(entproto.MethodCreate | entproto.MethodGet | entproto.MethodList | entproto.MethodBatchCreate),
|
||||
),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Re-running `go generate ./...` will give us the following service definition in `entpb.proto`:
|
||||
```protobuf title="ent/proto/entpb/entpb.proto"
|
||||
service UserService {
|
||||
rpc Create ( CreateUserRequest ) returns ( User );
|
||||
|
||||
rpc Get ( GetUserRequest ) returns ( User );
|
||||
|
||||
rpc List ( ListUserRequest ) returns ( ListUserResponse );
|
||||
|
||||
rpc BatchCreate ( BatchCreateUsersRequest ) returns ( BatchCreateUsersResponse );
|
||||
}
|
||||
```
|
||||
|
||||
Notice that the service no longer includes `Update` and `Delete` methods. Perfect!
|
||||
88
doc/md/tutorial-grpc-setting-up.md
Normal file
88
doc/md/tutorial-grpc-setting-up.md
Normal file
@@ -0,0 +1,88 @@
|
||||
---
|
||||
id: grpc-setting-up
|
||||
title: Setting Up
|
||||
sidebar_label: Setting Up
|
||||
---
|
||||
|
||||
Let's start by initializing a new Go module for our project:
|
||||
|
||||
```console
|
||||
mkdir ent-grpc-example
|
||||
cd ent-grpc-example
|
||||
go mod init ent-grpc-example
|
||||
```
|
||||
|
||||
Next, we use `go run` to invoke the ent code generator to initialize a schema:
|
||||
|
||||
```console
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new User
|
||||
```
|
||||
|
||||
Our directory should now look like:
|
||||
|
||||
```console
|
||||
.
|
||||
├── ent
|
||||
│ ├── generate.go
|
||||
│ └── schema
|
||||
│ └── user.go
|
||||
├── go.mod
|
||||
└── go.sum
|
||||
```
|
||||
|
||||
Next, let's add the `entproto` package to our project:
|
||||
|
||||
```console
|
||||
go get -u entgo.io/contrib/entproto
|
||||
```
|
||||
|
||||
Next, we will define the schema for the `User` entity. Open `ent/schema/user.go` and edit:
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
Unique(),
|
||||
field.String("email_address").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
In this step, we added two unique fields to our `User` entity: `name` and `email_address`. The `ent.Schema` is just the definition of the schema. To create usable production code from it we need to run Ent's code generation tool on it. Run:
|
||||
|
||||
```console
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Notice that new files were created from our schema definition:
|
||||
|
||||
```console
|
||||
├── ent
|
||||
│ ├── client.go
|
||||
│ ├── config.go
|
||||
// .... many more
|
||||
│ ├── user
|
||||
│ ├── user.go
|
||||
│ ├── user_create.go
|
||||
│ ├── user_delete.go
|
||||
│ ├── user_query.go
|
||||
│ └── user_update.go
|
||||
├── go.mod
|
||||
└── go.sum
|
||||
```
|
||||
|
||||
At this point, we can open a connection to a database, run a migration to create the `users` table, and start reading and writing data to it. This is covered on the [Setup Tutorial](tutorial-setup.md), so let's cut to the chase and learn about generating Protobuf definitions and gRPC servers from our schema.
|
||||
130
doc/md/tutorial-setup.md
Normal file
130
doc/md/tutorial-setup.md
Normal file
@@ -0,0 +1,130 @@
|
||||
---
|
||||
id: tutorial-setup
|
||||
title: Setting Up
|
||||
sidebar_label: Setting Up
|
||||
---
|
||||
|
||||
This guide is intended for first-time users who want instructions on how to set up an Ent project from scratch.
|
||||
Before we get started, make sure you have the following prerequisites installed on your machine.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
- [Go](https://go.dev/doc/install)
|
||||
- [Docker](https://docs.docker.com/get-docker) (optional)
|
||||
|
||||
After installing these dependencies, create a directory for the project and initialize a Go module:
|
||||
|
||||
```console
|
||||
mkdir todo
|
||||
cd $_
|
||||
go mod init todo
|
||||
```
|
||||
|
||||
## Installation
|
||||
|
||||
Run the following Go commands to install Ent, and tell it to initialize the project structure along with a `Todo` schema.
|
||||
|
||||
```console
|
||||
go get entgo.io/ent/cmd/ent
|
||||
```
|
||||
|
||||
```console
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new Todo
|
||||
```
|
||||
|
||||
After installing Ent and running `ent new`, your project directory should look like this:
|
||||
|
||||
```console
|
||||
.
|
||||
├── ent
|
||||
│ ├── generate.go
|
||||
│ └── schema
|
||||
│ └── todo.go
|
||||
├── go.mod
|
||||
└── go.sum
|
||||
```
|
||||
|
||||
The `ent` directory holds the generated assets (see the next section), and the `ent/schema` directory contains your
|
||||
entity schemas.
|
||||
|
||||
## Code Generation
|
||||
|
||||
When we ran `ent new Todo` above, a schema named `Todo` was created in the `todo.go` file under the`todo/ent/schema/` directory:
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import "entgo.io/ent"
|
||||
|
||||
// Todo holds the schema definition for the Todo entity.
|
||||
type Todo struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Todo.
|
||||
func (Todo) Fields() []ent.Field {
|
||||
return nil
|
||||
}
|
||||
|
||||
// Edges of the Todo.
|
||||
func (Todo) Edges() []ent.Edge {
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
As you can see, initially, the schema has no fields or edges defined. Let's run the command for generating assets to interact with
|
||||
the `Todo` entity:
|
||||
|
||||
```console
|
||||
go generate ./ent
|
||||
```
|
||||
|
||||
## Create a Test Case
|
||||
|
||||
Running `go generate ./ent` invoked Ent's automatic code generation tool, which uses the schemas we define in our `schema` package to generate the actual Go code which we will now use to interact with a database. At this stage, you can find under `./ent/client.go`, client code that is capable of querying and mutating the `Todo` entities. Let's create a
|
||||
[testable example](https://go.dev/blog/examples) to use this. We'll use [SQLite](https://github.com/mattn/go-sqlite3)
|
||||
in this test-case for testing Ent.
|
||||
|
||||
```console
|
||||
go get github.com/mattn/go-sqlite3
|
||||
touch example_test.go
|
||||
```
|
||||
|
||||
Paste the following code in `example_test.go` that instantiates an `ent.Client` and automatically creates all schema resources
|
||||
in the database (tables, columns, etc).
|
||||
|
||||
```go
|
||||
package todo
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"todo/ent"
|
||||
|
||||
"entgo.io/ent/dialect"
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
)
|
||||
|
||||
func Example_Todo() {
|
||||
// Create an ent.Client with in-memory SQLite database.
|
||||
client, err := ent.Open(dialect.SQLite, "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to sqlite: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Run the automatic migration tool to create all schema resources.
|
||||
if err := client.Schema.Create(ctx); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
// Output:
|
||||
}
|
||||
```
|
||||
|
||||
Then, run `go test` to verify that everything works as expected.
|
||||
|
||||
```console
|
||||
go test
|
||||
```
|
||||
|
||||
After setting up our project, we're ready to create our Todo list.
|
||||
217
doc/md/tutorial-todo-crud.md
Normal file
217
doc/md/tutorial-todo-crud.md
Normal file
@@ -0,0 +1,217 @@
|
||||
---
|
||||
id: tutorial-todo-crud
|
||||
title: Query and Mutation
|
||||
sidebar_label: Query and Mutation
|
||||
---
|
||||
|
||||
After setting up our project, we're ready to create our Todo list and query it.
|
||||
|
||||
## Create a Todo
|
||||
|
||||
Let's create a Todo in our testable example. We do it by adding the following code to `example_test.go`:
|
||||
|
||||
```go
|
||||
func Example_Todo() {
|
||||
// ...
|
||||
task1, err := client.Todo.Create().Save(ctx)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating a todo: %v", err)
|
||||
}
|
||||
fmt.Println(task1)
|
||||
// Output:
|
||||
// Todo(id=1)
|
||||
}
|
||||
```
|
||||
|
||||
Running `go test` should pass successfully.
|
||||
|
||||
## Add Fields To The Schema
|
||||
|
||||
As you can see, our Todos are too boring as they contain only the `ID` field. Let's improve this example by adding
|
||||
multiple fields to the schema in `todo/ent/schema/todo.go`:
|
||||
|
||||
```go
|
||||
func (Todo) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Text("text").
|
||||
NotEmpty(),
|
||||
field.Time("created_at").
|
||||
Default(time.Now).
|
||||
Immutable(),
|
||||
field.Enum("status").
|
||||
NamedValues(
|
||||
"InProgress", "IN_PROGRESS",
|
||||
"Completed", "COMPLETED",
|
||||
).
|
||||
Default("IN_PROGRESS"),
|
||||
field.Int("priority").
|
||||
Default(0),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
After adding these fields, we need to run the code-generation as before:
|
||||
|
||||
```console
|
||||
go generate ./ent
|
||||
```
|
||||
|
||||
As you may notice, all fields have a default value on creation except the `text` field, which must be provided by
|
||||
the user. Let's change our `example_test.go` to follow these changes:
|
||||
|
||||
```go
|
||||
func Example_Todo() {
|
||||
// ...
|
||||
task1, err := client.Todo.Create().SetText("Add GraphQL Example").Save(ctx)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating a todo: %v", err)
|
||||
}
|
||||
fmt.Printf("%d: %q\n", task1.ID, task1.Text)
|
||||
task2, err := client.Todo.Create().SetText("Add Tracing Example").Save(ctx)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating a todo: %v", err)
|
||||
}
|
||||
fmt.Printf("%d: %q\n", task2.ID, task2.Text)
|
||||
// Output:
|
||||
// 1: "Add GraphQL Example"
|
||||
// 2: "Add Tracing Example"
|
||||
}
|
||||
```
|
||||
|
||||
Wonderful! We created a schema in the database with 5 columns (`id`, `text`, `created_at`, `status`, `priority`)
|
||||
and created 2 items in our todo list, by inserting 2 rows to the table.
|
||||
|
||||
|
||||
|
||||
## Add Edges To The Schema
|
||||
|
||||
Let’s say we want to design our todo list so that an item can depend on another item. Therefore, we'll add a `parent`
|
||||
edge to each Todo item, to get the item it depends on, and a back-reference edge named `children` in order to get all
|
||||
items that depend on it.
|
||||
|
||||
Let's change our schema again in `todo/ent/schema/todo.go`:
|
||||
|
||||
```go
|
||||
func (Todo) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("parent", Todo.Type).
|
||||
Unique().
|
||||
From("children"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
After adding these edges, we need to run the code-generation as before:
|
||||
|
||||
```console
|
||||
go generate ./ent
|
||||
```
|
||||
|
||||
## Connect 2 Todos
|
||||
|
||||
We continue our edges example, by updating the 2 todo items we just created. We define that item-2 (*"Add Tracing Example"*)
|
||||
depends on item-1 (*"Add GraphQL Example"*).
|
||||
|
||||
|
||||
|
||||
```go
|
||||
func Example_Todo() {
|
||||
// ...
|
||||
if err := task2.Update().SetParent(task1).Exec(ctx); err != nil {
|
||||
log.Fatalf("failed connecting todo2 to its parent: %v", err)
|
||||
}
|
||||
// Output:
|
||||
// 1: "Add GraphQL Example"
|
||||
// 2: "Add Tracing Example"
|
||||
}
|
||||
```
|
||||
|
||||
## Query Todos
|
||||
|
||||
After connecting item-2 to item-1, we're ready to start querying our todo list.
|
||||
|
||||
#### Query all todo items:
|
||||
|
||||
```go
|
||||
func Example_Todo() {
|
||||
// ...
|
||||
|
||||
// Query all todo items.
|
||||
items, err := client.Todo.Query().All(ctx)
|
||||
if err != nil {
|
||||
log.Fatalf("failed querying todos: %v", err)
|
||||
}
|
||||
for _, t := range items {
|
||||
fmt.Printf("%d: %q\n", t.ID, t.Text)
|
||||
}
|
||||
// Output:
|
||||
// 1: "Add GraphQL Example"
|
||||
// 2: "Add Tracing Example"
|
||||
}
|
||||
```
|
||||
|
||||
#### Query all todo items that depend on other items:
|
||||
|
||||
```go
|
||||
func Example_Todo() {
|
||||
// ...
|
||||
|
||||
// Query all todo items that depend on other items.
|
||||
items, err := client.Todo.Query().Where(todo.HasParent()).All(ctx)
|
||||
if err != nil {
|
||||
log.Fatalf("failed querying todos: %v", err)
|
||||
}
|
||||
for _, t := range items {
|
||||
fmt.Printf("%d: %q\n", t.ID, t.Text)
|
||||
}
|
||||
// Output:
|
||||
// 2: "Add Tracing Example"
|
||||
}
|
||||
```
|
||||
|
||||
#### Query all todo items that don't depend on other items and have items that depend on them:
|
||||
|
||||
```go
|
||||
func Example_Todo() {
|
||||
// ...
|
||||
|
||||
// Query all todo items that don't depend on other items and have items that depend them.
|
||||
items, err := client.Todo.Query().
|
||||
Where(
|
||||
todo.Not(
|
||||
todo.HasParent(),
|
||||
),
|
||||
todo.HasChildren(),
|
||||
).
|
||||
All(ctx)
|
||||
if err != nil {
|
||||
log.Fatalf("failed querying todos: %v", err)
|
||||
}
|
||||
for _, t := range items {
|
||||
fmt.Printf("%d: %q\n", t.ID, t.Text)
|
||||
}
|
||||
// Output:
|
||||
// 1: "Add GraphQL Example"
|
||||
}
|
||||
```
|
||||
|
||||
#### Query parent through its children:
|
||||
|
||||
```go
|
||||
func Example_Todo() {
|
||||
// ...
|
||||
|
||||
// Get a parent item through its children and expect the
|
||||
// query to return exactly one item.
|
||||
parent, err := client.Todo.Query(). // Query all todos.
|
||||
Where(todo.HasParent()). // Filter only those with parents.
|
||||
QueryParent(). // Continue traversals to the parents.
|
||||
Only(ctx) // Expect exactly one item.
|
||||
if err != nil {
|
||||
log.Fatalf("failed querying todos: %v", err)
|
||||
}
|
||||
fmt.Printf("%d: %q\n", parent.ID, parent.Text)
|
||||
// Output:
|
||||
// 1: "Add GraphQL Example"
|
||||
}
|
||||
```
|
||||
196
doc/md/tutorial-todo-gql-field-collection.md
Normal file
196
doc/md/tutorial-todo-gql-field-collection.md
Normal file
@@ -0,0 +1,196 @@
|
||||
---
|
||||
id: tutorial-todo-gql-field-collection
|
||||
title: GraphQL Field Collection
|
||||
sidebar_label: Field Collection
|
||||
---
|
||||
|
||||
In this section, we continue our [GraphQL example](tutorial-todo-gql.mdx) by explaining how Ent implements
|
||||
[GraphQL Field Collection](https://spec.graphql.org/June2018/#sec-Field-Collection) for our GraphQL schema and solves the
|
||||
"N+1 Problem" in our resolvers.
|
||||
|
||||
#### Clone the code (optional)
|
||||
|
||||
The code for this tutorial is available under [github.com/a8m/ent-graphql-example](https://github.com/a8m/ent-graphql-example),
|
||||
and tagged (using Git) in each step. If you want to skip the basic setup and start with the initial version of the GraphQL
|
||||
server, you can clone the repository as follows:
|
||||
|
||||
```console
|
||||
git clone git@github.com:a8m/ent-graphql-example.git
|
||||
cd ent-graphql-example
|
||||
go run ./cmd/todo/
|
||||
```
|
||||
|
||||
## Problem
|
||||
|
||||
The *"N+1 problem"* in GraphQL means that a server executes unnecessary database queries to get node associations (i.e. edges)
|
||||
when it can be avoided. The number of queries that will be potentially executed (N+1) is a factor of the number of the
|
||||
nodes returned by the root query, their associations, and so on recursively. Meaning, this can potentially be a very big number (much bigger than N+1).
|
||||
|
||||
Let's try to explain this with the following query:
|
||||
|
||||
```graphql
|
||||
query {
|
||||
users(first: 50) {
|
||||
edges {
|
||||
node {
|
||||
photos {
|
||||
link
|
||||
}
|
||||
posts {
|
||||
content
|
||||
comments {
|
||||
content
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
In the query above, we want to fetch the first 50 users with their photos and their posts, including their comments.
|
||||
|
||||
**In the naive solution** (the problematic case), a server will fetch the first 50 users in one query, then, for each user
|
||||
will execute a query for getting their photos (50 queries), and another query for getting their posts (50). Let's say
|
||||
each user has exactly 10 posts. Therefore, for each post (of each user), the server will execute another query for getting
|
||||
its comments (500). That means we will have `1+50+50+500=601` queries in total.
|
||||
|
||||

|
||||
|
||||
## Ent Solution
|
||||
|
||||
The Ent extension for field collection adds support for automatic [GraphQL field collection](https://spec.graphql.org/June2018/#sec-Field-Collection)
|
||||
for associations (i.e. edges) using [eager loading](eager-load.mdx). Meaning, if a query asks for nodes and their edges,
|
||||
`entgql` will automatically add [`With<E>`](eager-load.mdx) steps to the root query, and as a result, the client will
|
||||
execute a constant number of queries to the database - and it works recursively.
|
||||
|
||||
In the GraphQL query above, the client will execute 1 query for getting the users, 1 for getting the photos,
|
||||
and another 2 for getting the posts and their comments **(4 in total!)**. This logic works both for root queries/resolvers
|
||||
and for the node(s) API.
|
||||
|
||||
## Example
|
||||
|
||||
For the purpose of the example, we **disable the automatic field collection**, change the `ent.Client` to run in
|
||||
debug mode in the `Todos` resolver, and restart our GraphQL server:
|
||||
|
||||
```diff title="ent.resolvers.go"
|
||||
func (r *queryResolver) Todos(ctx context.Context, after *ent.Cursor, first *int, before *ent.Cursor, last *int, orderBy *ent.TodoOrder) (*ent.TodoConnection, error) {
|
||||
- return r.client.Todo.Query().
|
||||
+ return r.client.Debug().Todo.Query().
|
||||
Paginate(ctx, after, first, before, last,
|
||||
ent.WithTodoOrder(orderBy),
|
||||
)
|
||||
}
|
||||
```
|
||||
|
||||
We execute the GraphQL query from the [pagination tutorial](tutorial-todo-gql-paginate.md), and add the
|
||||
`parent` edge to the result:
|
||||
|
||||
```graphql
|
||||
query {
|
||||
todos(last: 10, orderBy: {direction: DESC, field: TEXT}) {
|
||||
edges {
|
||||
node {
|
||||
id
|
||||
text
|
||||
parent {
|
||||
id
|
||||
}
|
||||
}
|
||||
cursor
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Check the process output, and you will see that the server executed 11 queries to the database. 1 for getting the last
|
||||
10 todo items, and another 10 queries for getting the parent of each item:
|
||||
|
||||
```sql
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` ORDER BY `id` ASC LIMIT 11
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` JOIN (SELECT `todo_parent` FROM `todos` WHERE `id` = ?) AS `t1` ON `todos`.`id` = `t1`.`todo_parent` LIMIT 2
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` JOIN (SELECT `todo_parent` FROM `todos` WHERE `id` = ?) AS `t1` ON `todos`.`id` = `t1`.`todo_parent` LIMIT 2
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` JOIN (SELECT `todo_parent` FROM `todos` WHERE `id` = ?) AS `t1` ON `todos`.`id` = `t1`.`todo_parent` LIMIT 2
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` JOIN (SELECT `todo_parent` FROM `todos` WHERE `id` = ?) AS `t1` ON `todos`.`id` = `t1`.`todo_parent` LIMIT 2
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` JOIN (SELECT `todo_parent` FROM `todos` WHERE `id` = ?) AS `t1` ON `todos`.`id` = `t1`.`todo_parent` LIMIT 2
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` JOIN (SELECT `todo_parent` FROM `todos` WHERE `id` = ?) AS `t1` ON `todos`.`id` = `t1`.`todo_parent` LIMIT 2
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` JOIN (SELECT `todo_parent` FROM `todos` WHERE `id` = ?) AS `t1` ON `todos`.`id` = `t1`.`todo_parent` LIMIT 2
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` JOIN (SELECT `todo_parent` FROM `todos` WHERE `id` = ?) AS `t1` ON `todos`.`id` = `t1`.`todo_parent` LIMIT 2
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` JOIN (SELECT `todo_parent` FROM `todos` WHERE `id` = ?) AS `t1` ON `todos`.`id` = `t1`.`todo_parent` LIMIT 2
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` JOIN (SELECT `todo_parent` FROM `todos` WHERE `id` = ?) AS `t1` ON `todos`.`id` = `t1`.`todo_parent` LIMIT 2
|
||||
```
|
||||
|
||||
Let's see how Ent can automatically solve our problem: when defining an Ent edge, `entgql` auto binds it to its usage in
|
||||
GraphQL and generates edge-resolvers for the nodes under the `gql_edge.go` file:
|
||||
|
||||
```go title="ent/gql_edge.go"
|
||||
func (t *Todo) Children(ctx context.Context) ([]*Todo, error) {
|
||||
if fc := graphql.GetFieldContext(ctx); fc != nil && fc.Field.Alias != "" {
|
||||
result, err = t.NamedChildren(graphql.GetFieldContext(ctx).Field.Alias)
|
||||
} else {
|
||||
result, err = t.Edges.ChildrenOrErr()
|
||||
}
|
||||
if IsNotLoaded(err) {
|
||||
result, err = t.QueryChildren().All(ctx)
|
||||
}
|
||||
return result, err
|
||||
}
|
||||
```
|
||||
|
||||
If we check the process' output again without **disabling fields collection**, we will see that this time the server
|
||||
executed only two queries to the database. One to get the last 10 todo items, and a second for getting
|
||||
the parent-item of each todo-item that was returned to the first query.
|
||||
|
||||
```sql
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority`, `todos`.`todo_parent` FROM `todos` ORDER BY `id` DESC LIMIT 11
|
||||
SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` WHERE `todos`.`id` IN (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
|
||||
```
|
||||
|
||||
If you're having trouble running this example, go to the [first section](#clone-the-code-optional), clone the code
|
||||
and run the example.
|
||||
|
||||
## Field Mappings
|
||||
|
||||
The [`entgql.MapsTo`](https://pkg.go.dev/entgo.io/contrib/entgql#MapsTo) allows you to add a custom field/edge mapping
|
||||
between the Ent schema and the GraphQL schema. This is useful when you want to expose a field or edge with a different
|
||||
name(s) in the GraphQL schema. For example:
|
||||
|
||||
```go
|
||||
// One to one mapping.
|
||||
field.Int("priority").
|
||||
Annotations(
|
||||
entgql.OrderField("PRIORITY_ORDER"),
|
||||
entgql.MapsTo("priorityOrder"),
|
||||
)
|
||||
|
||||
// Multiple GraphQL fields can map to the same Ent field.
|
||||
field.Int("category_id").
|
||||
Annotations(
|
||||
entgql.MapsTo("categoryID", "category_id", "categoryX"),
|
||||
)
|
||||
```
|
||||
|
||||
#### Collected For Resolver Fields
|
||||
|
||||
The `entgql.CollectedFor` annotation allows you to specify that a field should be automatically collected when certain
|
||||
GraphQL resolver fields (extended fields) are queried. This is useful when you have resolver fields that depend on
|
||||
underlying Ent field values.
|
||||
|
||||
```go
|
||||
field.String("name").
|
||||
Optional().
|
||||
Annotations(
|
||||
entgql.CollectedFor("uppercaseName"),
|
||||
)
|
||||
```
|
||||
|
||||
:::note
|
||||
If Ent does not know about the mapping between a resolver field and its underlying Ent field, and it encounters an unknown
|
||||
field in the query, it will query all fields from the database to ensure the resolver has the data it needs.
|
||||
:::
|
||||
|
||||
---
|
||||
|
||||
Well done! By using automatic field collection for our Ent schema definition, we were able to greatly improve the
|
||||
GraphQL query efficiency in our application. In the next section, we will learn how to make our GraphQL mutations
|
||||
transactional.
|
||||
343
doc/md/tutorial-todo-gql-filter-input.md
Normal file
343
doc/md/tutorial-todo-gql-filter-input.md
Normal file
@@ -0,0 +1,343 @@
|
||||
---
|
||||
id: tutorial-todo-gql-filter-input
|
||||
title: Filter Inputs
|
||||
sidebar_label: Filter Inputs
|
||||
---
|
||||
|
||||
In this section, we continue the [GraphQL example](tutorial-todo-gql.mdx) by explaining how to generate
|
||||
type-safe GraphQL filters (i.e. `Where` predicates) from our `ent/schema`, and allow users to seamlessly
|
||||
map GraphQL queries to Ent queries. For example, the following GraphQL query, maps to the Ent query below:
|
||||
|
||||
**GraphQL**
|
||||
|
||||
```graphql
|
||||
{
|
||||
hasParent: true,
|
||||
hasChildrenWith: {
|
||||
status: IN_PROGRESS,
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Ent**
|
||||
|
||||
```go
|
||||
client.Todo.
|
||||
Query().
|
||||
Where(
|
||||
todo.HasParent(),
|
||||
todo.HasChildrenWith(
|
||||
todo.StatusEQ(todo.StatusInProgress),
|
||||
),
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
#### Clone the code (optional)
|
||||
|
||||
The code for this tutorial is available under [github.com/a8m/ent-graphql-example](https://github.com/a8m/ent-graphql-example),
|
||||
and tagged (using Git) in each step. If you want to skip the basic setup and start with the initial version of the GraphQL
|
||||
server, you can clone the repository and run the program as follows:
|
||||
|
||||
```console
|
||||
git clone git@github.com:a8m/ent-graphql-example.git
|
||||
cd ent-graphql-example
|
||||
go run ./cmd/todo/
|
||||
```
|
||||
|
||||
### Configure Ent
|
||||
|
||||
Go to your `ent/entc.go` file, and add the 4 highlighted lines (extension options):
|
||||
|
||||
```go {3-6} title="ent/entc.go"
|
||||
func main() {
|
||||
ex, err := entgql.NewExtension(
|
||||
entgql.WithSchemaGenerator(),
|
||||
entgql.WithWhereInputs(true),
|
||||
entgql.WithConfigPath("gqlgen.yml"),
|
||||
entgql.WithSchemaPath("ent.graphql"),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("creating entgql extension: %v", err)
|
||||
}
|
||||
opts := []entc.Option{
|
||||
entc.Extensions(ex),
|
||||
entc.TemplateDir("./template"),
|
||||
}
|
||||
if err := entc.Generate("./schema", &gen.Config{}, opts...); err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The `WithWhereInputs` option enables the filter generation, the `WithConfigPath` configures the path to the `gqlgen`
|
||||
config file, which allows the extension to more accurately map GraphQL to Ent types. The last option `WithSchemaPath`,
|
||||
configures a path to a new, or an existing GraphQL schema to write the generated filters to.
|
||||
|
||||
After changing the `entc.go` configuration, we're ready to execute the code generation as follows:
|
||||
|
||||
```console
|
||||
go generate .
|
||||
```
|
||||
|
||||
Observe that Ent has generated `<T>WhereInput` for each type in your schema in a file named `ent/gql_where_input.go`. Ent
|
||||
also generates a GraphQL schema as well (`ent.graphql`), so you don't need to `autobind` them to `gqlgen` manually.
|
||||
For example:
|
||||
|
||||
```go title="ent/gql_where_input.go"
|
||||
// TodoWhereInput represents a where input for filtering Todo queries.
|
||||
type TodoWhereInput struct {
|
||||
Not *TodoWhereInput `json:"not,omitempty"`
|
||||
Or []*TodoWhereInput `json:"or,omitempty"`
|
||||
And []*TodoWhereInput `json:"and,omitempty"`
|
||||
|
||||
// "created_at" field predicates.
|
||||
CreatedAt *time.Time `json:"createdAt,omitempty"`
|
||||
CreatedAtNEQ *time.Time `json:"createdAtNEQ,omitempty"`
|
||||
CreatedAtIn []time.Time `json:"createdAtIn,omitempty"`
|
||||
CreatedAtNotIn []time.Time `json:"createdAtNotIn,omitempty"`
|
||||
CreatedAtGT *time.Time `json:"createdAtGT,omitempty"`
|
||||
CreatedAtGTE *time.Time `json:"createdAtGTE,omitempty"`
|
||||
CreatedAtLT *time.Time `json:"createdAtLT,omitempty"`
|
||||
CreatedAtLTE *time.Time `json:"createdAtLTE,omitempty"`
|
||||
|
||||
// "status" field predicates.
|
||||
Status *todo.Status `json:"status,omitempty"`
|
||||
StatusNEQ *todo.Status `json:"statusNEQ,omitempty"`
|
||||
StatusIn []todo.Status `json:"statusIn,omitempty"`
|
||||
StatusNotIn []todo.Status `json:"statusNotIn,omitempty"`
|
||||
|
||||
// .. truncated ..
|
||||
}
|
||||
```
|
||||
|
||||
```graphql title="ent.graphql"
|
||||
"""
|
||||
TodoWhereInput is used for filtering Todo objects.
|
||||
Input was generated by ent.
|
||||
"""
|
||||
input TodoWhereInput {
|
||||
not: TodoWhereInput
|
||||
and: [TodoWhereInput!]
|
||||
or: [TodoWhereInput!]
|
||||
|
||||
"""created_at field predicates"""
|
||||
createdAt: Time
|
||||
createdAtNEQ: Time
|
||||
createdAtIn: [Time!]
|
||||
createdAtNotIn: [Time!]
|
||||
createdAtGT: Time
|
||||
createdAtGTE: Time
|
||||
createdAtLT: Time
|
||||
createdAtLTE: Time
|
||||
|
||||
"""status field predicates"""
|
||||
status: Status
|
||||
statusNEQ: Status
|
||||
statusIn: [Status!]
|
||||
statusNotIn: [Status!]
|
||||
|
||||
# .. truncated ..
|
||||
}
|
||||
```
|
||||
|
||||
:::info
|
||||
If your project contains more than 1 GraphQL schema (e.g. `todo.graphql` and `ent.graphql`), you should configure
|
||||
`gqlgen.yml` file as follows:
|
||||
|
||||
```yaml
|
||||
schema:
|
||||
- todo.graphql
|
||||
# The ent.graphql schema was generated by Ent.
|
||||
- ent.graphql
|
||||
```
|
||||
:::
|
||||
|
||||
### Configure GQL
|
||||
|
||||
After running the code generation, we're ready to complete the integration and expose the filtering capabilities in GraphQL:
|
||||
|
||||
1\. Edit the GraphQL schema to accept the new filter types:
|
||||
```graphql {8} title="ent.graphql"
|
||||
type Query {
|
||||
todos(
|
||||
after: Cursor,
|
||||
first: Int,
|
||||
before: Cursor,
|
||||
last: Int,
|
||||
orderBy: TodoOrder,
|
||||
where: TodoWhereInput,
|
||||
): TodoConnection!
|
||||
}
|
||||
```
|
||||
|
||||
2\. Use the new filter types in GraphQL resolvers:
|
||||
```go {5} title="ent.resolvers.go"
|
||||
func (r *queryResolver) Todos(ctx context.Context, after *ent.Cursor, first *int, before *ent.Cursor, last *int, orderBy *ent.TodoOrder, where *ent.TodoWhereInput) (*ent.TodoConnection, error) {
|
||||
return r.client.Todo.Query().
|
||||
Paginate(ctx, after, first, before, last,
|
||||
ent.WithTodoOrder(orderBy),
|
||||
ent.WithTodoFilter(where.Filter),
|
||||
)
|
||||
}
|
||||
```
|
||||
|
||||
### Execute Queries
|
||||
|
||||
As mentioned above, with the new GraphQL filter types, you can express the same Ent filters you use in your
|
||||
Go code.
|
||||
|
||||
#### Conjunction, disjunction and negation
|
||||
|
||||
The `Not`, `And` and `Or` operators can be added to the `where` clause using the `not`, `and` and `or` fields. For example:
|
||||
|
||||
```graphql {3-15}
|
||||
query {
|
||||
todos(
|
||||
where: {
|
||||
or: [
|
||||
{
|
||||
status: COMPLETED
|
||||
},
|
||||
{
|
||||
not: {
|
||||
hasParent: true,
|
||||
status: IN_PROGRESS
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
) {
|
||||
edges {
|
||||
node {
|
||||
id
|
||||
text
|
||||
}
|
||||
cursor
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
When multiple filter fields are provided, Ent implicitly adds the `And` operator.
|
||||
|
||||
```graphql
|
||||
{
|
||||
status: COMPLETED,
|
||||
textHasPrefix: "GraphQL",
|
||||
}
|
||||
```
|
||||
The above query will produce the following Ent query:
|
||||
|
||||
```go
|
||||
client.Todo.
|
||||
Query().
|
||||
Where(
|
||||
todo.And(
|
||||
todo.StatusEQ(todo.StatusCompleted),
|
||||
todo.TextHasPrefix("GraphQL"),
|
||||
)
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
#### Edge/Relation filters
|
||||
|
||||
[Edge (relation) predicates](https://entgo.io/docs/predicates#edge-predicates) can be expressed in the same Ent syntax:
|
||||
|
||||
```graphql
|
||||
{
|
||||
hasParent: true,
|
||||
hasChildrenWith: {
|
||||
status: IN_PROGRESS,
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The above query will produce the following Ent query:
|
||||
|
||||
```go
|
||||
client.Todo.
|
||||
Query().
|
||||
Where(
|
||||
todo.HasParent(),
|
||||
todo.HasChildrenWith(
|
||||
todo.StatusEQ(todo.StatusInProgress),
|
||||
),
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
### Custom filters
|
||||
|
||||
Sometimes we need to add custom conditions to our filters, while it is always possible to use [Templates](https://pkg.go.dev/entgo.io/contrib@master/entgql#WithTemplates) and [SchemaHooks](https://pkg.go.dev/entgo.io/contrib@master/entgql#WithSchemaHook)
|
||||
it's not always the easiest solution, specially if we only want to add simple conditions.
|
||||
|
||||
Luckily by using a combination of the [GraphQL object type extensions](https://spec.graphql.org/October2021/#sec-Object-Extensions) and custom resolvers, we can achieve this functionality.
|
||||
|
||||
Let's see an example of adding a custom `isCompleted` filter that will receive a boolean value and filter
|
||||
all the TODO's that have the `completed` status.
|
||||
|
||||
Let's start by extending the `TodoWhereInput`:
|
||||
|
||||
```graphql title="todo.graphql"
|
||||
extend input TodoWhereInput {
|
||||
isCompleted: Boolean
|
||||
}
|
||||
```
|
||||
|
||||
After running the code generation, we should see a new field resolver inside the `todo.resolvers.go` file:
|
||||
|
||||
```go title="todo.resolvers.go"
|
||||
func (r *todoWhereInputResolver) IsCompleted(ctx context.Context, obj *ent.TodoWhereInput, data *bool) error {
|
||||
panic(fmt.Errorf("not implemented"))
|
||||
}
|
||||
```
|
||||
|
||||
We can now use the `AddPredicates` method inside the `ent.TodoWhereInput` struct to implement our custom filtering:
|
||||
|
||||
```go title="todo.resolvers.go"
|
||||
func (r *todoWhereInputResolver) IsCompleted(ctx context.Context, obj *ent.TodoWhereInput, data *bool) error {
|
||||
if obj == nil || data == nil {
|
||||
return nil
|
||||
}
|
||||
if *data {
|
||||
obj.AddPredicates(todo.StatusEQ(todo.StatusCompleted))
|
||||
} else {
|
||||
obj.AddPredicates(todo.StatusNEQ(todo.StatusCompleted))
|
||||
}
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
We can use this new filtering as any other predicate:
|
||||
|
||||
```graphql
|
||||
{
|
||||
isCompleted: true,
|
||||
}
|
||||
# including the not, and and or fields
|
||||
{
|
||||
not: {
|
||||
isCompleted: true,
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Usage as predicates
|
||||
|
||||
The `Filter` option lets use the generated `WhereInput`s as regular predicates on any type of query:
|
||||
|
||||
```go
|
||||
query := ent.Todo.Query()
|
||||
query, err := input.Filter(query)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
return query.All(ctx)
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
Well done! As you can see, by changing a few lines of code our application now exposes a type-safe GraphQL filters
|
||||
that automatically map to Ent queries. Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack).
|
||||
304
doc/md/tutorial-todo-gql-mutation-input.md
Normal file
304
doc/md/tutorial-todo-gql-mutation-input.md
Normal file
@@ -0,0 +1,304 @@
|
||||
---
|
||||
id: tutorial-todo-gql-mutation-input
|
||||
title: Mutation Inputs
|
||||
sidebar_label: Mutation Inputs
|
||||
---
|
||||
|
||||
In this section, we continue the [GraphQL example](tutorial-todo-gql.mdx) by explaining how to extend the Ent code
|
||||
generator using Go templates and generate [input type](https://graphql.org/graphql-js/mutations-and-input-types/)
|
||||
objects for our GraphQL mutations that can be applied directly on Ent mutations.
|
||||
|
||||
#### Clone the code (optional)
|
||||
|
||||
The code for this tutorial is available under [github.com/a8m/ent-graphql-example](https://github.com/a8m/ent-graphql-example),
|
||||
and tagged (using Git) in each step. If you want to skip the basic setup and start with the initial version of the GraphQL
|
||||
server, you can clone the repository and run the program as follows:
|
||||
|
||||
```console
|
||||
git clone git@github.com:a8m/ent-graphql-example.git
|
||||
cd ent-graphql-example
|
||||
go run ./cmd/todo/
|
||||
```
|
||||
|
||||
## Mutation Types
|
||||
|
||||
Ent supports generating mutation types. A mutation type can be accepted as an input for GraphQL mutations, and it is
|
||||
handled and verified by Ent. Let's tell Ent that our GraphQL `Todo` type supports create and update operations:
|
||||
|
||||
```go title="ent/schema/todo.go"
|
||||
func (Todo) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entgql.QueryField(),
|
||||
//highlight-next-line
|
||||
entgql.Mutations(entgql.MutationCreate(), entgql.MutationUpdate()),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Then, run code generation:
|
||||
|
||||
```go
|
||||
go generate .
|
||||
```
|
||||
|
||||
You'll notice that Ent generated for you 2 types: `ent.CreateTodoInput` and `ent.UpdateTodoInput`.
|
||||
|
||||
## Mutations
|
||||
|
||||
After generating our mutation inputs, we can connect them to the GraphQL mutations:
|
||||
|
||||
```graphql title="todo.graphql"
|
||||
type Mutation {
|
||||
createTodo(input: CreateTodoInput!): Todo!
|
||||
updateTodo(id: ID!, input: UpdateTodoInput!): Todo!
|
||||
}
|
||||
```
|
||||
|
||||
Running code generation we'll generate the actual mutations and the only thing left after that is to bind the resolvers
|
||||
to Ent.
|
||||
```go
|
||||
go generate .
|
||||
```
|
||||
|
||||
```go title="todo.resolvers.go"
|
||||
// CreateTodo is the resolver for the createTodo field.
|
||||
func (r *mutationResolver) CreateTodo(ctx context.Context, input ent.CreateTodoInput) (*ent.Todo, error) {
|
||||
return r.client.Todo.Create().SetInput(input).Save(ctx)
|
||||
}
|
||||
|
||||
// UpdateTodo is the resolver for the updateTodo field.
|
||||
func (r *mutationResolver) UpdateTodo(ctx context.Context, id int, input ent.UpdateTodoInput) (*ent.Todo, error) {
|
||||
return r.client.Todo.UpdateOneID(id).SetInput(input).Save(ctx)
|
||||
}
|
||||
```
|
||||
|
||||
## Test the `CreateTodo` Resolver
|
||||
|
||||
Let's start with creating 2 todo items by executing the `createTodo` mutations twice.
|
||||
|
||||
#### Mutation
|
||||
|
||||
```graphql
|
||||
mutation CreateTodo {
|
||||
createTodo(input: {text: "Create GraphQL Example", status: IN_PROGRESS, priority: 2}) {
|
||||
id
|
||||
text
|
||||
createdAt
|
||||
priority
|
||||
parent {
|
||||
id
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
#### Output
|
||||
|
||||
```json
|
||||
{
|
||||
"data": {
|
||||
"createTodo": {
|
||||
"id": "1",
|
||||
"text": "Create GraphQL Example",
|
||||
"createdAt": "2021-04-19T10:49:52+03:00",
|
||||
"priority": 2,
|
||||
"parent": null
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
#### Mutation
|
||||
|
||||
```graphql
|
||||
mutation CreateTodo {
|
||||
createTodo(input: {text: "Create Tracing Example", status: IN_PROGRESS, priority: 2}) {
|
||||
id
|
||||
text
|
||||
createdAt
|
||||
priority
|
||||
parent {
|
||||
id
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
#### Output
|
||||
|
||||
```json
|
||||
{
|
||||
"data": {
|
||||
"createTodo": {
|
||||
"id": "2",
|
||||
"text": "Create Tracing Example",
|
||||
"createdAt": "2021-04-19T10:50:01+03:00",
|
||||
"priority": 2,
|
||||
"parent": null
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Test the `UpdateTodo` Resolver
|
||||
|
||||
The only thing left is to test the `UpdateTodo` resolver. Let's use it to update the `parent` of the 2nd todo item to `1`.
|
||||
|
||||
```graphql
|
||||
mutation UpdateTodo {
|
||||
updateTodo(id: 2, input: {parentID: 1}) {
|
||||
id
|
||||
text
|
||||
createdAt
|
||||
priority
|
||||
parent {
|
||||
id
|
||||
text
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
#### Output
|
||||
|
||||
```json
|
||||
{
|
||||
"data": {
|
||||
"updateTodo": {
|
||||
"id": "2",
|
||||
"text": "Create Tracing Example",
|
||||
"createdAt": "2021-04-19T10:50:01+03:00",
|
||||
"priority": 1,
|
||||
"parent": {
|
||||
"id": "1",
|
||||
"text": "Create GraphQL Example"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Create edges with mutations
|
||||
|
||||
To create the edges of a node in the same mutation, you can extend the GQL mutation input with the edge fields:
|
||||
|
||||
```graphql title="extended.graphql"
|
||||
extend input CreateTodoInput {
|
||||
createChildren: [CreateTodoInput!]
|
||||
}
|
||||
```
|
||||
|
||||
Next, run code generation again:
|
||||
```go
|
||||
go generate .
|
||||
```
|
||||
|
||||
GQLGen will generate the resolver for the `createChildren` field, allowing you to use it in your resolver:
|
||||
|
||||
```go title="extended.resolvers.go"
|
||||
// CreateChildren is the resolver for the createChildren field.
|
||||
func (r *createTodoInputResolver) CreateChildren(ctx context.Context, obj *ent.CreateTodoInput, data []*ent.CreateTodoInput) error {
|
||||
panic(fmt.Errorf("not implemented: CreateChildren - createChildren"))
|
||||
}
|
||||
```
|
||||
|
||||
Now, we need to implement the logic to create the children:
|
||||
|
||||
```go title="extended.resolvers.go"
|
||||
// CreateChildren is the resolver for the createChildren field.
|
||||
func (r *createTodoInputResolver) CreateChildren(ctx context.Context, obj *ent.CreateTodoInput, data []*ent.CreateTodoInput) error {
|
||||
// highlight-start
|
||||
// NOTE: We need to use the Ent client from the context.
|
||||
// To ensure we create all of the children in the same transaction.
|
||||
// See: Transactional Mutations for more information.
|
||||
c := ent.FromContext(ctx)
|
||||
// highlight-end
|
||||
builders := make([]*ent.TodoCreate, len(data))
|
||||
for i := range data {
|
||||
builders[i] = c.Todo.Create().SetInput(*data[i])
|
||||
}
|
||||
todos, err := c.Todo.CreateBulk(builders...).Save(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
ids := make([]int, len(todos))
|
||||
for i := range todos {
|
||||
ids[i] = todos[i].ID
|
||||
}
|
||||
obj.ChildIDs = append(obj.ChildIDs, ids...)
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
Change the following lines to use the transactional client:
|
||||
|
||||
```go title="todo.resolvers.go"
|
||||
// CreateTodo is the resolver for the createTodo field.
|
||||
func (r *mutationResolver) CreateTodo(ctx context.Context, input ent.CreateTodoInput) (*ent.Todo, error) {
|
||||
// highlight-next-line
|
||||
return ent.FromContext(ctx).Todo.Create().SetInput(input).Save(ctx)
|
||||
}
|
||||
|
||||
// UpdateTodo is the resolver for the updateTodo field.
|
||||
func (r *mutationResolver) UpdateTodo(ctx context.Context, id int, input ent.UpdateTodoInput) (*ent.Todo, error) {
|
||||
// highlight-next-line
|
||||
return ent.FromContext(ctx).Todo.UpdateOneID(id).SetInput(input).Save(ctx)
|
||||
}
|
||||
```
|
||||
|
||||
Test the mutation with the children:
|
||||
|
||||
**Mutation**
|
||||
```graphql
|
||||
mutation {
|
||||
createTodo(input: {
|
||||
text: "parent", status:IN_PROGRESS,
|
||||
createChildren: [
|
||||
{ text: "children1", status: IN_PROGRESS },
|
||||
{ text: "children2", status: COMPLETED }
|
||||
]
|
||||
}) {
|
||||
id
|
||||
text
|
||||
children {
|
||||
id
|
||||
text
|
||||
status
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Output**
|
||||
```json
|
||||
{
|
||||
"data": {
|
||||
"createTodo": {
|
||||
"id": "3",
|
||||
"text": "parent",
|
||||
"children": [
|
||||
{
|
||||
"id": "1",
|
||||
"text": "children1",
|
||||
"status": "IN_PROGRESS"
|
||||
},
|
||||
{
|
||||
"id": "2",
|
||||
"text": "children2",
|
||||
"status": "COMPLETED"
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
If you enable the debug Client, you'll see that the children are created in the same transaction:
|
||||
```log
|
||||
2022/12/14 00:27:41 driver.Tx(7e04b00b-7941-41c5-9aee-41c8c2d85312): started
|
||||
2022/12/14 00:27:41 Tx(7e04b00b-7941-41c5-9aee-41c8c2d85312).Query: query=INSERT INTO `todos` (`created_at`, `priority`, `status`, `text`) VALUES (?, ?, ?, ?), (?, ?, ?, ?) RETURNING `id` args=[2022-12-14 00:27:41.046344 +0700 +07 m=+5.283557793 0 IN_PROGRESS children1 2022-12-14 00:27:41.046345 +0700 +07 m=+5.283558626 0 COMPLETED children2]
|
||||
2022/12/14 00:27:41 Tx(7e04b00b-7941-41c5-9aee-41c8c2d85312).Query: query=INSERT INTO `todos` (`text`, `created_at`, `status`, `priority`) VALUES (?, ?, ?, ?) RETURNING `id` args=[parent 2022-12-14 00:27:41.047455 +0700 +07 m=+5.284669251 IN_PROGRESS 0]
|
||||
2022/12/14 00:27:41 Tx(7e04b00b-7941-41c5-9aee-41c8c2d85312).Exec: query=UPDATE `todos` SET `todo_parent` = ? WHERE `id` IN (?, ?) AND `todo_parent` IS NULL args=[3 1 2]
|
||||
2022/12/14 00:27:41 Tx(7e04b00b-7941-41c5-9aee-41c8c2d85312).Query: query=SELECT DISTINCT `todos`.`id`, `todos`.`text`, `todos`.`created_at`, `todos`.`status`, `todos`.`priority` FROM `todos` WHERE `todo_parent` = ? args=[3]
|
||||
2022/12/14 00:27:41 Tx(7e04b00b-7941-41c5-9aee-41c8c2d85312): committed
|
||||
```
|
||||
133
doc/md/tutorial-todo-gql-node.md
Normal file
133
doc/md/tutorial-todo-gql-node.md
Normal file
@@ -0,0 +1,133 @@
|
||||
---
|
||||
id: tutorial-todo-gql-node
|
||||
title: Relay Node Interface
|
||||
sidebar_label: Relay Node Interface
|
||||
---
|
||||
|
||||
In this section, we continue the [GraphQL example](tutorial-todo-gql.mdx) by explaining how to implement the
|
||||
[Relay Node Interface](https://relay.dev/graphql/objectidentification.htm). If you're not familiar with the
|
||||
Node interface, read the following paragraphs that were taken from [relay.dev](https://relay.dev/graphql/objectidentification.htm#sel-DABDDBAADLA0Cl0c):
|
||||
|
||||
> To provide options for GraphQL clients to elegantly handle for caching and data refetching GraphQL servers need to expose object identifiers in a standardized way. In the query, the schema should provide a standard mechanism for asking for an object by ID. In the response, the schema provides a standard way of providing these IDs.
|
||||
>
|
||||
> We refer to objects with identifiers as “nodes”. An example of both of those is the following query:
|
||||
>
|
||||
> ```graphql
|
||||
> {
|
||||
> node(id: "4") {
|
||||
> id
|
||||
> ... on User {
|
||||
> name
|
||||
> }
|
||||
> }
|
||||
> }
|
||||
> ```
|
||||
|
||||
#### Clone the code (optional)
|
||||
|
||||
The code for this tutorial is available under [github.com/a8m/ent-graphql-example](https://github.com/a8m/ent-graphql-example),
|
||||
and tagged (using Git) in each step. If you want to skip the basic setup and start with the initial version of the GraphQL
|
||||
server, you can clone the repository as follows:
|
||||
|
||||
```console
|
||||
git clone git@github.com:a8m/ent-graphql-example.git
|
||||
cd ent-graphql-example
|
||||
go run ./cmd/todo/
|
||||
```
|
||||
|
||||
## Implementation
|
||||
|
||||
Ent supports the Node interface through its GraphQL integration. By following a few simple steps you can add support
|
||||
for it in your application. We start by telling `gqlgen` that Ent provides the `Node` interface by editing the
|
||||
`gqlgen.yaml` file as follows:
|
||||
|
||||
```diff title="gqlgen.yml" {7-9}
|
||||
# This section declares type mapping between the GraphQL and Go type systems.
|
||||
models:
|
||||
# Defines the ID field as Go 'int'.
|
||||
ID:
|
||||
model:
|
||||
- github.com/99designs/gqlgen/graphql.IntID
|
||||
Node:
|
||||
model:
|
||||
- todo/ent.Noder
|
||||
```
|
||||
|
||||
To apply these changes, we rerun the code generation:
|
||||
|
||||
```console
|
||||
go generate .
|
||||
```
|
||||
|
||||
Like before, we need to implement the GraphQL resolvers in `ent.resolvers.go`. With a one-liner change, we can
|
||||
implement those by replacing the generated `gqlgen` code with the following:
|
||||
|
||||
```diff title="ent.resolvers.go"
|
||||
func (r *queryResolver) Node(ctx context.Context, id int) (ent.Noder, error) {
|
||||
- panic(fmt.Errorf("not implemented: Node - node"))
|
||||
+ return r.client.Noder(ctx, id)
|
||||
}
|
||||
|
||||
func (r *queryResolver) Nodes(ctx context.Context, ids []int) ([]ent.Noder, error) {
|
||||
- panic(fmt.Errorf("not implemented: Nodes - nodes"))
|
||||
+ return r.client.Noders(ctx, ids)
|
||||
}
|
||||
```
|
||||
|
||||
## Query Nodes
|
||||
|
||||
Now, we're ready to test our new GraphQL resolvers. Let's start with creating a few todo items by running this
|
||||
query multiple times (changing variables is optional):
|
||||
|
||||
```graphql
|
||||
mutation CreateTodo($input: CreateTodoInput!) {
|
||||
createTodo(input: $input) {
|
||||
id
|
||||
text
|
||||
createdAt
|
||||
priority
|
||||
parent {
|
||||
id
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
# Query Variables: { "input": { "text":"Create GraphQL Example", "status": "IN_PROGRESS", "priority": 1 } }
|
||||
# Output: { "data": { "createTodo": { "id": "2", "text": "Create GraphQL Example", "createdAt": "2021-03-10T15:02:18+02:00", "priority": 1, "parent": null } } }
|
||||
```
|
||||
|
||||
Running the **Node** API on one of the todo items will return:
|
||||
|
||||
````graphql
|
||||
query {
|
||||
node(id: 1) {
|
||||
id
|
||||
... on Todo {
|
||||
text
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
# Output: { "data": { "node": { "id": "1", "text": "Create GraphQL Example" } } }
|
||||
````
|
||||
|
||||
Running the **Nodes** API on one of the todo items will return:
|
||||
|
||||
```graphql
|
||||
query {
|
||||
nodes(ids: [1, 2]) {
|
||||
id
|
||||
... on Todo {
|
||||
text
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
# Output: { "data": { "nodes": [ { "id": "1", "text": "Create GraphQL Example" }, { "id": "2", "text": "Create Tracing Example" } ] } }
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
Well done! As you can see, by changing a few lines of code our application now implements the Relay Node Interface.
|
||||
In the next section, we will show how to implement the Relay Cursor Connections spec using Ent, which is very useful
|
||||
if we want our application to support slicing and pagination of query results.
|
||||
298
doc/md/tutorial-todo-gql-paginate.md
Normal file
298
doc/md/tutorial-todo-gql-paginate.md
Normal file
@@ -0,0 +1,298 @@
|
||||
---
|
||||
id: tutorial-todo-gql-paginate
|
||||
title: Relay Cursor Connections (Pagination)
|
||||
sidebar_label: Relay Cursor Connections
|
||||
---
|
||||
|
||||
In this section, we continue the [GraphQL example](tutorial-todo-gql.mdx) by explaining how to implement the
|
||||
[Relay Cursor Connections Spec](https://relay.dev/graphql/connections.htm). If you're not familiar with the
|
||||
Cursor Connections interface, read the following paragraphs that were taken from [relay.dev](https://relay.dev/graphql/connections.htm#sel-DABDDDAADFA0E3kM):
|
||||
|
||||
> In the query, the connection model provides a standard mechanism for slicing and paginating the result set.
|
||||
>
|
||||
> In the response, the connection model provides a standard way of providing cursors, and a way of telling the client
|
||||
> when more results are available.
|
||||
>
|
||||
> An example of all four of those is the following query:
|
||||
> ```graphql
|
||||
> {
|
||||
> user {
|
||||
> id
|
||||
> name
|
||||
> friends(first: 10, after: "opaqueCursor") {
|
||||
> edges {
|
||||
> cursor
|
||||
> node {
|
||||
> id
|
||||
> name
|
||||
> }
|
||||
> }
|
||||
> pageInfo {
|
||||
> hasNextPage
|
||||
> }
|
||||
> }
|
||||
> }
|
||||
> }
|
||||
> ```
|
||||
|
||||
#### Clone the code (optional)
|
||||
|
||||
The code for this tutorial is available under [github.com/a8m/ent-graphql-example](https://github.com/a8m/ent-graphql-example),
|
||||
and tagged (using Git) in each step. If you want to skip the basic setup and start with the initial version of the GraphQL
|
||||
server, you can clone the repository as follows:
|
||||
|
||||
```console
|
||||
git clone git@github.com:a8m/ent-graphql-example.git
|
||||
cd ent-graphql-example
|
||||
go run ./cmd/todo/
|
||||
```
|
||||
|
||||
|
||||
## Add Annotations To Schema
|
||||
|
||||
Ordering can be defined on any comparable field of Ent by annotating it with `entgql.Annotation`.
|
||||
Note that the given `OrderField` name must be uppercase and match its enum value in the GraphQL schema.
|
||||
|
||||
```go title="ent/schema/todo.go"
|
||||
func (Todo) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Text("text").
|
||||
NotEmpty().
|
||||
Annotations(
|
||||
entgql.OrderField("TEXT"),
|
||||
),
|
||||
field.Time("created_at").
|
||||
Default(time.Now).
|
||||
Immutable().
|
||||
Annotations(
|
||||
entgql.OrderField("CREATED_AT"),
|
||||
),
|
||||
field.Enum("status").
|
||||
NamedValues(
|
||||
"InProgress", "IN_PROGRESS",
|
||||
"Completed", "COMPLETED",
|
||||
).
|
||||
Default("IN_PROGRESS").
|
||||
Annotations(
|
||||
entgql.OrderField("STATUS"),
|
||||
),
|
||||
field.Int("priority").
|
||||
Default(0).
|
||||
Annotations(
|
||||
entgql.OrderField("PRIORITY"),
|
||||
),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Order By Multiple Fields
|
||||
|
||||
By default, the `orderBy` argument only accepts a single `<T>Order` value. To enable sorting by multiple fields, simply
|
||||
add the `entgql.MultiOrder()` annotation to desired schema.
|
||||
|
||||
```go title="ent/schema/todo.go"
|
||||
func (Todo) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
//highlight-next-line
|
||||
entgql.MultiOrder(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
By adding this annotation to the `Todo` schema, the `orderBy` argument will be changed from `TodoOrder` to `[TodoOrder!]`.
|
||||
|
||||
## Order By Edge Count
|
||||
|
||||
Non-unique edges can be annotated with the `OrderField` annotation to enable sorting nodes based on the count of specific
|
||||
edge types.
|
||||
|
||||
```go title="ent/schema/todo/go"
|
||||
func (Todo) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("children", Todo.Type).
|
||||
Annotations(
|
||||
entgql.RelayConnection(),
|
||||
// highlight-next-line
|
||||
entgql.OrderField("CHILDREN_COUNT"),
|
||||
).
|
||||
From("parent").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
:::info
|
||||
The naming convention for this ordering term is: `UPPER(<edge-name>)_COUNT`. For example, `CHILDREN_COUNT`
|
||||
or `POSTS_COUNT`.
|
||||
:::
|
||||
|
||||
## Order By Edge Field
|
||||
|
||||
Unique edges can be annotated with the `OrderField` annotation to allow sorting nodes by their associated edge fields.
|
||||
For example, _sorting posts by their author's name_, or _ordering todos based on their parent's priority_. Note that
|
||||
in order to sort by an edge field, the field must be annotated with `OrderField` within the referenced type.
|
||||
|
||||
The naming convention for this ordering term is: `UPPER(<edge-name>)_<edge-field>`. For example, `PARENT_PRIORITY`.
|
||||
|
||||
```go title="ent/schema/todo.go"
|
||||
// Fields returns todo fields.
|
||||
func (Todo) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
// ...
|
||||
field.Int("priority").
|
||||
Default(0).
|
||||
Annotations(
|
||||
// highlight-next-line
|
||||
entgql.OrderField("PRIORITY"),
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges returns todo edges.
|
||||
func (Todo) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("children", Todo.Type).
|
||||
From("parent").
|
||||
Annotations(
|
||||
// highlight-next-line
|
||||
entgql.OrderField("PARENT_PRIORITY"),
|
||||
).
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
:::info
|
||||
The naming convention for this ordering term is: `UPPER(<edge-name>)_<edge-field>`. For example, `PARENT_PRIORITY` or
|
||||
`AUTHOR_NAME`.
|
||||
:::
|
||||
|
||||
## Add Pagination Support For Query
|
||||
|
||||
1\. The next step for enabling pagination is to tell Ent that the `Todo` type is a Relay Connection.
|
||||
|
||||
```go title="ent/schema/todo.go"
|
||||
func (Todo) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
//highlight-next-line
|
||||
entgql.RelayConnection(),
|
||||
entgql.QueryField(),
|
||||
entgql.Mutations(entgql.MutationCreate()),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
2\. Then, run `go generate .` and you'll notice that `ent.resolvers.go` was changed. Head over to the `Todos` resolver
|
||||
and update it to pass pagination arguments to `.Paginate()`:
|
||||
|
||||
```go title="ent.resolvers.go" {2-5}
|
||||
func (r *queryResolver) Todos(ctx context.Context, after *ent.Cursor, first *int, before *ent.Cursor, last *int, orderBy *ent.TodoOrder) (*ent.TodoConnection, error) {
|
||||
return r.client.Todo.Query().
|
||||
Paginate(ctx, after, first, before, last,
|
||||
ent.WithTodoOrder(orderBy),
|
||||
)
|
||||
}
|
||||
```
|
||||
|
||||
:::info Relay Connection Configuration
|
||||
|
||||
The `entgql.RelayConnection()` function indicates that the node or edge should support pagination.
|
||||
Hence,the returned result is a Relay connection rather than a list of nodes (`[T!]!` => `<T>Connection!`).
|
||||
|
||||
Setting this annotation on schema `T` (reside in ent/schema), enables pagination for this node and therefore, Ent will
|
||||
generate all Relay types for this schema, such as: `<T>Edge`, `<T>Connection`, and `PageInfo`. For example:
|
||||
|
||||
```go
|
||||
func (Todo) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entgql.RelayConnection(),
|
||||
entgql.QueryField(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Setting this annotation on an edge indicates that the GraphQL field for this edge should support nested pagination
|
||||
and the returned type is a Relay connection. For example:
|
||||
|
||||
```go
|
||||
func (Todo) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("parent", Todo.Type).
|
||||
Unique().
|
||||
From("children").
|
||||
Annotations(entgql.RelayConnection()),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The generated GraphQL schema will be:
|
||||
|
||||
```diff
|
||||
-children: [Todo!]!
|
||||
+children(first: Int, last: Int, after: Cursor, before: Cursor): TodoConnection!
|
||||
```
|
||||
|
||||
:::
|
||||
|
||||
## Pagination Usage
|
||||
|
||||
Now, we're ready to test our new GraphQL resolvers. Let's start with creating a few todo items by running this
|
||||
query multiple times (changing variables is optional):
|
||||
|
||||
```graphql
|
||||
mutation CreateTodo($input: CreateTodoInput!) {
|
||||
createTodo(input: $input) {
|
||||
id
|
||||
text
|
||||
createdAt
|
||||
priority
|
||||
parent {
|
||||
id
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
# Query Variables: { "input": { "text": "Create GraphQL Example", "status": "IN_PROGRESS", "priority": 1 } }
|
||||
# Output: { "data": { "createTodo": { "id": "2", "text": "Create GraphQL Example", "createdAt": "2021-03-10T15:02:18+02:00", "priority": 1, "parent": null } } }
|
||||
```
|
||||
|
||||
Then, we can query our todo list using the pagination API:
|
||||
|
||||
```graphql
|
||||
query {
|
||||
todos(first: 3, orderBy: {direction: DESC, field: TEXT}) {
|
||||
edges {
|
||||
node {
|
||||
id
|
||||
text
|
||||
}
|
||||
cursor
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
# Output: { "data": { "todos": { "edges": [ { "node": { "id": "16", "text": "Create GraphQL Example" }, "cursor": "gqFpEKF2tkNyZWF0ZSBHcmFwaFFMIEV4YW1wbGU" }, { "node": { "id": "15", "text": "Create GraphQL Example" }, "cursor": "gqFpD6F2tkNyZWF0ZSBHcmFwaFFMIEV4YW1wbGU" }, { "node": { "id": "14", "text": "Create GraphQL Example" }, "cursor": "gqFpDqF2tkNyZWF0ZSBHcmFwaFFMIEV4YW1wbGU" } ] } } }
|
||||
```
|
||||
|
||||
We can also use the cursor we got in the query above to get all items that come after it.
|
||||
|
||||
```graphql
|
||||
query {
|
||||
todos(first: 3, after:"gqFpEKF2tkNyZWF0ZSBHcmFwaFFMIEV4YW1wbGU", orderBy: {direction: DESC, field: TEXT}) {
|
||||
edges {
|
||||
node {
|
||||
id
|
||||
text
|
||||
}
|
||||
cursor
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
# Output: { "data": { "todos": { "edges": [ { "node": { "id": "15", "text": "Create GraphQL Example" }, "cursor": "gqFpD6F2tkNyZWF0ZSBHcmFwaFFMIEV4YW1wbGU" }, { "node": { "id": "14", "text": "Create GraphQL Example" }, "cursor": "gqFpDqF2tkNyZWF0ZSBHcmFwaFFMIEV4YW1wbGU" }, { "node": { "id": "13", "text": "Create GraphQL Example" }, "cursor": "gqFpDaF2tkNyZWF0ZSBHcmFwaFFMIEV4YW1wbGU" } ] } } }
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
Great! With a few simple changes, our application now supports pagination. Please continue to the next section where we
|
||||
explain how to implement GraphQL field collections and learn how Ent solves the *"N+1 problem"* in GraphQL resolvers.
|
||||
298
doc/md/tutorial-todo-gql-schema-generator.md
Normal file
298
doc/md/tutorial-todo-gql-schema-generator.md
Normal file
@@ -0,0 +1,298 @@
|
||||
---
|
||||
id: tutorial-todo-gql-schema-generator
|
||||
title: Schema Generator
|
||||
sidebar_label: Schema Generator
|
||||
---
|
||||
|
||||
In this section, we will continue the [GraphQL example](tutorial-todo-gql.mdx) by explaining how to generate a
|
||||
type-safe GraphQL schema from our `ent/schema`.
|
||||
|
||||
### Configure Ent
|
||||
|
||||
Go to your `ent/entc.go` file, and add the highlighted line (extension options):
|
||||
|
||||
```go {5} title="ent/entc.go"
|
||||
func main() {
|
||||
ex, err := entgql.NewExtension(
|
||||
entgql.WithWhereInputs(true),
|
||||
entgql.WithConfigPath("../gqlgen.yml"),
|
||||
entgql.WithSchemaGenerator(),
|
||||
entgql.WithSchemaPath("../ent.graphql"),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("creating entgql extension: %v", err)
|
||||
}
|
||||
opts := []entc.Option{
|
||||
entc.Extensions(ex),
|
||||
entc.TemplateDir("./template"),
|
||||
}
|
||||
if err := entc.Generate("./schema", &gen.Config{}, opts...); err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The `WithSchemaGenerator` option enables the GraphQL schema generation.
|
||||
|
||||
### Add Annotations To `Todo` Schema
|
||||
|
||||
The `entgql.RelayConnection()` annotation is used to generate the Relay `<T>Edge`, `<T>Connection`, and `PageInfo` types for the `Todo` type.
|
||||
|
||||
The `entgql.QueryField()` annotation is used to generate the `todos` field in the `Query` type.
|
||||
|
||||
```go {13,14} title="ent/schema/todo.go"
|
||||
// Edges of the Todo.
|
||||
func (Todo) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("parent", Todo.Type).
|
||||
Unique().
|
||||
From("children").
|
||||
}
|
||||
}
|
||||
|
||||
// Annotations of the Todo.
|
||||
func (Todo) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entgql.RelayConnection(),
|
||||
entgql.QueryField(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The `entgql.RelayConnection()` annotation can also be used on the edge fields, to generate first, last, after, before... arguments and change the field type to `<T>Connection!`. For example to change the `children` field from `children: [Todo!]!` to `children(first: Int, last: Int, after: Cursor, before: Cursor): TodoConnection!`. You can add the `entgql.RelayConnection()` annotation to the edge field:
|
||||
|
||||
```go {7} title="ent/schema/todo.go"
|
||||
// Edges of the Todo.
|
||||
func (Todo) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("parent", Todo.Type).
|
||||
Unique().
|
||||
From("children").
|
||||
Annotations(entgql.RelayConnection()),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Cleanup the handwritten schema
|
||||
|
||||
Please remove the types below from the `todo.graphql` to avoid conflict with the types that are generated by EntGQL in the `ent.graphql` file.
|
||||
|
||||
```diff title="todo.graphql"
|
||||
-interface Node {
|
||||
- id: ID!
|
||||
-}
|
||||
|
||||
"""Maps a Time GraphQL scalar to a Go time.Time struct."""
|
||||
scalar Time
|
||||
|
||||
-"""
|
||||
-Define a Relay Cursor type:
|
||||
-https://relay.dev/graphql/connections.htm#sec-Cursor
|
||||
-"""
|
||||
-scalar Cursor
|
||||
|
||||
-"""
|
||||
-Define an enumeration type and map it later to Ent enum (Go type).
|
||||
-https://graphql.org/learn/schema/#enumeration-types
|
||||
-"""
|
||||
-enum Status {
|
||||
- IN_PROGRESS
|
||||
- COMPLETED
|
||||
-}
|
||||
-
|
||||
-type PageInfo {
|
||||
- hasNextPage: Boolean!
|
||||
- hasPreviousPage: Boolean!
|
||||
- startCursor: Cursor
|
||||
- endCursor: Cursor
|
||||
-}
|
||||
|
||||
-type TodoConnection {
|
||||
- totalCount: Int!
|
||||
- pageInfo: PageInfo!
|
||||
- edges: [TodoEdge]
|
||||
-}
|
||||
|
||||
-type TodoEdge {
|
||||
- node: Todo
|
||||
- cursor: Cursor!
|
||||
-}
|
||||
|
||||
-"""The following enums match the entgql annotations in the ent/schema."""
|
||||
-enum TodoOrderField {
|
||||
- CREATED_AT
|
||||
- PRIORITY
|
||||
- STATUS
|
||||
- TEXT
|
||||
-}
|
||||
|
||||
-enum OrderDirection {
|
||||
- ASC
|
||||
- DESC
|
||||
-}
|
||||
|
||||
input TodoOrder {
|
||||
direction: OrderDirection!
|
||||
field: TodoOrderField
|
||||
}
|
||||
|
||||
-"""
|
||||
-Define an object type and map it later to the generated Ent model.
|
||||
-https://graphql.org/learn/schema/#object-types-and-fields
|
||||
-"""
|
||||
-type Todo implements Node {
|
||||
- id: ID!
|
||||
- createdAt: Time
|
||||
- status: Status!
|
||||
- priority: Int!
|
||||
- text: String!
|
||||
- parent: Todo
|
||||
- children: [Todo!]
|
||||
-}
|
||||
|
||||
"""
|
||||
Define an input type for the mutation below.
|
||||
https://graphql.org/learn/schema/#input-types
|
||||
Note that this type is mapped to the generated
|
||||
input type in mutation_input.go.
|
||||
"""
|
||||
input CreateTodoInput {
|
||||
status: Status! = IN_PROGRESS
|
||||
priority: Int
|
||||
text: String
|
||||
parentID: ID
|
||||
ChildIDs: [ID!]
|
||||
}
|
||||
|
||||
"""
|
||||
Define an input type for the mutation below.
|
||||
https://graphql.org/learn/schema/#input-types
|
||||
Note that this type is mapped to the generated
|
||||
input type in mutation_input.go.
|
||||
"""
|
||||
input UpdateTodoInput {
|
||||
status: Status
|
||||
priority: Int
|
||||
text: String
|
||||
parentID: ID
|
||||
clearParent: Boolean
|
||||
addChildIDs: [ID!]
|
||||
removeChildIDs: [ID!]
|
||||
}
|
||||
|
||||
"""
|
||||
Define a mutation for creating todos.
|
||||
https://graphql.org/learn/queries/#mutations
|
||||
"""
|
||||
type Mutation {
|
||||
createTodo(input: CreateTodoInput!): Todo!
|
||||
updateTodo(id: ID!, input: UpdateTodoInput!): Todo!
|
||||
updateTodos(ids: [ID!]!, input: UpdateTodoInput!): [Todo!]!
|
||||
}
|
||||
|
||||
-"""Define a query for getting all todos and support the Node interface."""
|
||||
-type Query {
|
||||
- todos(after: Cursor, first: Int, before: Cursor, last: Int, orderBy: TodoOrder, where: TodoWhereInput): TodoConnection
|
||||
- node(id: ID!): Node
|
||||
- nodes(ids: [ID!]!): [Node]!
|
||||
-}
|
||||
```
|
||||
|
||||
### Ensure the execution order of Ent and GQLGen
|
||||
|
||||
We also need to do some changes to our `generate.go` files to ensure the execution order of Ent and GQLGen. The reason for this is to ensure that GQLGen sees the objects created by Ent and executes the code generator properly.
|
||||
|
||||
First, remove the `ent/generate.go` file. Then, update the `ent/entc.go` file with the correct path, because the Ent codegen will be run from the project root directory.
|
||||
|
||||
```diff title="ent/entc.go"
|
||||
func main() {
|
||||
ex, err := entgql.NewExtension(
|
||||
entgql.WithWhereInputs(true),
|
||||
- entgql.WithConfigPath("../gqlgen.yml"),
|
||||
+ entgql.WithConfigPath("./gqlgen.yml"),
|
||||
entgql.WithSchemaGenerator(),
|
||||
- entgql.WithSchemaPath("../ent.graphql"),
|
||||
+ entgql.WithSchemaPath("./ent.graphql"),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("creating entgql extension: %v", err)
|
||||
}
|
||||
opts := []entc.Option{
|
||||
entc.Extensions(ex),
|
||||
- entc.TemplateDir("./template"),
|
||||
+ entc.TemplateDir("./ent/template"),
|
||||
}
|
||||
- if err := entc.Generate("./schema", &gen.Config{}, opts...); err != nil {
|
||||
+ if err := entc.Generate("./ent/schema", &gen.Config{}, opts...); err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Update the `generate.go` to include the ent codegen.
|
||||
```go {3} title="generate.go"
|
||||
package todo
|
||||
|
||||
//go:generate go run -mod=mod ./ent/entc.go
|
||||
//go:generate go run -mod=mod github.com/99designs/gqlgen
|
||||
```
|
||||
|
||||
After changing the `generate.go` file, we're ready to execute the code generation as follows:
|
||||
|
||||
```console
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
You will see that the `ent.graphql` file will be updated with the new content from EntGQL's Schema Generator.
|
||||
|
||||
### Extending the type that generated by Ent
|
||||
|
||||
You may note that the type generated will include the `Query` type object with some fields that are already defined:
|
||||
|
||||
```graphql
|
||||
type Query {
|
||||
"""Fetches an object given its ID."""
|
||||
node(
|
||||
"""ID of the object."""
|
||||
id: ID!
|
||||
): Node
|
||||
"""Lookup nodes by a list of IDs."""
|
||||
nodes(
|
||||
"""The list of node IDs."""
|
||||
ids: [ID!]!
|
||||
): [Node]!
|
||||
todos(
|
||||
"""Returns the elements in the list that come after the specified cursor."""
|
||||
after: Cursor
|
||||
|
||||
"""Returns the first _n_ elements from the list."""
|
||||
first: Int
|
||||
|
||||
"""Returns the elements in the list that come before the specified cursor."""
|
||||
before: Cursor
|
||||
|
||||
"""Returns the last _n_ elements from the list."""
|
||||
last: Int
|
||||
|
||||
"""Ordering options for Todos returned from the connection."""
|
||||
orderBy: TodoOrder
|
||||
|
||||
"""Filtering options for Todos returned from the connection."""
|
||||
where: TodoWhereInput
|
||||
): TodoConnection!
|
||||
}
|
||||
```
|
||||
|
||||
To add new fields to the `Query` type, you can do the following:
|
||||
```graphql title="todo.graphql"
|
||||
extend type Query {
|
||||
"""Returns the literal string 'pong'."""
|
||||
ping: String!
|
||||
}
|
||||
```
|
||||
|
||||
You can extend any type that is generated by Ent. To skip a field from the type, you can use the `entgql.Skip()` on that field or edge.
|
||||
|
||||
---
|
||||
|
||||
Well done! As you can see, after adapting the Schema Generator feature we don't have to write GQL schemas by hand anymore. Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack).
|
||||
99
doc/md/tutorial-todo-gql-tx-mutation.md
Normal file
99
doc/md/tutorial-todo-gql-tx-mutation.md
Normal file
@@ -0,0 +1,99 @@
|
||||
---
|
||||
id: tutorial-todo-gql-tx-mutation
|
||||
title: Transactional Mutations
|
||||
sidebar_label: Transactional Mutations
|
||||
---
|
||||
|
||||
In this section, we continue the [GraphQL example](tutorial-todo-gql.mdx) by explaining how to set our GraphQL mutations
|
||||
to be transactional. That means, to automatically wrap our GraphQL mutations with a database transaction and either
|
||||
commit at the end, or rollback the transaction in case of a GraphQL error.
|
||||
|
||||
#### Clone the code (optional)
|
||||
|
||||
The code for this tutorial is available under [github.com/a8m/ent-graphql-example](https://github.com/a8m/ent-graphql-example),
|
||||
and tagged (using Git) in each step. If you want to skip the basic setup and start with the initial version of the GraphQL
|
||||
server, you can clone the repository and checkout `v0.1.0` as follows:
|
||||
|
||||
```console
|
||||
git clone git@github.com:a8m/ent-graphql-example.git
|
||||
cd ent-graphql-example
|
||||
go run ./cmd/todo/
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
The GraphQL extensions provides a handler named `entgql.Transactioner` that executes each GraphQL mutation in a
|
||||
transaction. The injected client for the resolver is a [transactional `ent.Client`](transactions.md#transactional-client).
|
||||
Hence, GraphQL resolvers that uses `ent.Client` won't need to be changed. In order to add it to our todo list application
|
||||
we follow these steps:
|
||||
|
||||
1\. Edit the `cmd/todo/main.go` and add to the GraphQL server initialization the `entgql.Transactioner` handler as
|
||||
follows:
|
||||
|
||||
```diff title="cmd/todo/main.go"
|
||||
srv := handler.NewDefaultServer(todo.NewSchema(client))
|
||||
+srv.Use(entgql.Transactioner{TxOpener: client})
|
||||
```
|
||||
|
||||
2\. Then, in the GraphQL mutations, use the client from context as follows:
|
||||
```diff title="todo.resolvers.go"
|
||||
}
|
||||
+func (mutationResolver) CreateTodo(ctx context.Context, input ent.CreateTodoInput) (*ent.Todo, error) {
|
||||
+ client := ent.FromContext(ctx)
|
||||
+ return client.Todo.Create().SetInput(input).Save(ctx)
|
||||
-func (r *mutationResolver) CreateTodo(ctx context.Context, input ent.CreateTodoInput) (*ent.Todo, error) {
|
||||
- return r.client.Todo.Create().SetInput(input).Save(ctx)
|
||||
}
|
||||
```
|
||||
|
||||
## Isolation Levels
|
||||
|
||||
If you'd like to tweak the transaction's isolation level, you can do so by implementing your own `TxOpener`. For example:
|
||||
|
||||
```go title="cmd/todo/main.go"
|
||||
srv.Use(entgql.Transactioner{
|
||||
TxOpener: entgql.TxOpenerFunc(func(ctx context.Context) (context.Context, driver.Tx, error) {
|
||||
tx, err := client.BeginTx(ctx, &sql.TxOptions{Isolation: sql.LevelRepeatableRead})
|
||||
if err != nil {
|
||||
return nil, nil, err
|
||||
}
|
||||
ctx = ent.NewTxContext(ctx, tx)
|
||||
ctx = ent.NewContext(ctx, tx.Client())
|
||||
return ctx, tx, nil
|
||||
}),
|
||||
})
|
||||
```
|
||||
|
||||
## Skip Operations
|
||||
|
||||
By default, `entgql.Transactioner` wraps all mutations within a transaction. However, there are mutations or operations
|
||||
that don't require database access or need special handling. In these cases, you can instruct `entgql.Transactioner` to
|
||||
skip the transaction by setting a custom `SkipTxFunc` function or using one of the built-in ones.
|
||||
|
||||
```go title="cmd/todo/main.go" {4,10,16-18}
|
||||
srv.Use(entgql.Transactioner{
|
||||
TxOpener: client,
|
||||
// Skip the given operation names from running under a transaction.
|
||||
SkipTxFunc: entgql.SkipOperations("operation1", "operation2"),
|
||||
})
|
||||
|
||||
srv.Use(entgql.Transactioner{
|
||||
TxOpener: client,
|
||||
// Skip if the operation has a mutation field with the given names.
|
||||
SkipTxFunc: entgql.SkipIfHasFields("field1", "field2"),
|
||||
})
|
||||
|
||||
srv.Use(entgql.Transactioner{
|
||||
TxOpener: client,
|
||||
// Custom skip function.
|
||||
SkipTxFunc: func(*ast.OperationDefinition) bool {
|
||||
// ...
|
||||
},
|
||||
})
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
Great! With a few lines of code, our application now supports automatic transactional mutations. Please continue to the
|
||||
next section where we explain how to extend the Ent code generator and generate [GraphQL input types](https://graphql.org/graphql-js/mutations-and-input-types/)
|
||||
for our GraphQL mutations.
|
||||
507
doc/md/tutorial-todo-gql.mdx
Normal file
507
doc/md/tutorial-todo-gql.mdx
Normal file
@@ -0,0 +1,507 @@
|
||||
---
|
||||
id: tutorial-todo-gql
|
||||
title: Introduction
|
||||
sidebar_label: Introduction
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
In this tutorial, we will learn how to connect Ent to [GraphQL](https://graphql.org) and set up the various integrations
|
||||
Ent provides, such as:
|
||||
1. Generating a GraphQL schema for nodes and edges defined in an Ent schema.
|
||||
2. Auto-generated `Query` and `Mutation` resolvers and provide seamless integration with the [Relay framework](https://relay.dev/).
|
||||
3. Filtering, pagination (including nested) and compliant support with the [Relay Cursor Connections Spec](https://relay.dev/graphql/connections.htm).
|
||||
4. Efficient [field collection](tutorial-todo-gql-field-collection.md) to overcome the N+1 problem without requiring data
|
||||
loaders.
|
||||
5. [Transactional mutations](tutorial-todo-gql-tx-mutation.md) to ensure consistency in case of failures.
|
||||
|
||||
If you're not familiar with GraphQL, it's recommended to go over its [introduction guide](https://graphql.org/learn/)
|
||||
before going over this tutorial.
|
||||
|
||||
#### Clone the code (optional)
|
||||
|
||||
The code for this tutorial is available under [github.com/a8m/ent-graphql-example](https://github.com/a8m/ent-graphql-example),
|
||||
and tagged (using Git) in each step. If you want to skip the basic setup and start with the initial version of the GraphQL
|
||||
server, you can clone the repository as follows:
|
||||
|
||||
```shell
|
||||
git clone git@github.com:a8m/ent-graphql-example.git
|
||||
cd ent-graphql-example
|
||||
go run ./cmd/todo
|
||||
```
|
||||
|
||||
## Basic Setup
|
||||
|
||||
This tutorial begins where the previous one ended (with a working Todo-list schema). We start by installing the
|
||||
[contrib/entgql](https://pkg.go.dev/entgo.io/contrib/entgql) Ent extension and use it for generating our first schema. Then,
|
||||
install and configure the [99designs/gqlgen](https://github.com/99designs/gqlgen) framework for building our GraphQL
|
||||
server and explore the official integration Ent provides to it.
|
||||
|
||||
#### Install and configure `entgql`
|
||||
|
||||
1\. Install `entgql`:
|
||||
|
||||
```shell
|
||||
go get entgo.io/contrib/entgql@master
|
||||
```
|
||||
|
||||
2\. Add the following annotations to the `Todo` schema to enable `Query` and `Mutation` (creation) capabilities:
|
||||
|
||||
```go title="ent/schema/todo.go" {3-4}
|
||||
func (Todo) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entgql.QueryField(),
|
||||
entgql.Mutations(entgql.MutationCreate()),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
3\. Create a new Go file named `ent/entc.go`, and paste the following content:
|
||||
|
||||
```go title="ent/entc.go"
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
"entgo.io/contrib/entgql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ex, err := entgql.NewExtension(
|
||||
// Tell Ent to generate a GraphQL schema for
|
||||
// the Ent schema in a file named ent.graphql.
|
||||
entgql.WithSchemaGenerator(),
|
||||
entgql.WithSchemaPath("ent.graphql"),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("creating entgql extension: %v", err)
|
||||
}
|
||||
opts := []entc.Option{
|
||||
entc.Extensions(ex),
|
||||
}
|
||||
if err := entc.Generate("./ent/schema", &gen.Config{}, opts...); err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
:::note
|
||||
The `ent/entc.go` is ignored using a build tag, and it is executed by the `go generate` command through the `generate.go`
|
||||
file.
|
||||
:::
|
||||
|
||||
**4\.** Remove the `ent/generate.go` file and create a new one in the **root of the project** with the following
|
||||
contents. In next steps, `gqlgen` commands will be added to this file as well.
|
||||
|
||||
```go title="generate.go"
|
||||
package todo
|
||||
|
||||
//go:generate go run -mod=mod ./ent/entc.go
|
||||
```
|
||||
|
||||
#### Running schema generation
|
||||
|
||||
After installing and configuring `entgql`, it is time to execute the codegen:
|
||||
|
||||
```shell
|
||||
go generate .
|
||||
```
|
||||
|
||||
You'll notice a new file was created named `ent.graphql`:
|
||||
|
||||
```graphql title="ent.graphql"
|
||||
directive @goField(forceResolver: Boolean, name: String) on FIELD_DEFINITION | INPUT_FIELD_DEFINITION
|
||||
directive @goModel(model: String, models: [String!]) on OBJECT | INPUT_OBJECT | SCALAR | ENUM | INTERFACE | UNION
|
||||
"""
|
||||
Define a Relay Cursor type:
|
||||
https://relay.dev/graphql/connections.htm#sec-Cursor
|
||||
"""
|
||||
scalar Cursor
|
||||
"""
|
||||
An object with an ID.
|
||||
Follows the [Relay Global Object Identification Specification](https://relay.dev/graphql/objectidentification.htm)
|
||||
"""
|
||||
interface Node @goModel(model: "todo/ent.Noder") {
|
||||
"""The id of the object."""
|
||||
id: ID!
|
||||
}
|
||||
|
||||
# ...
|
||||
```
|
||||
|
||||
#### Install and configure `gqlgen`
|
||||
|
||||
1\. Install `99designs/gqlgen`:
|
||||
|
||||
```shell
|
||||
go get github.com/99designs/gqlgen
|
||||
```
|
||||
|
||||
2\. The gqlgen package can be configured using a `gqlgen.yml` file that is automatically loaded from the current directory.
|
||||
Let's add this file to the root of the project. Follow the comments in this file to understand what each config directive
|
||||
means:
|
||||
|
||||
```yaml title="gqlgen.yml"
|
||||
# schema tells gqlgen where the GraphQL schema is located.
|
||||
schema:
|
||||
- ent.graphql
|
||||
|
||||
# resolver reports where the resolver implementations go.
|
||||
resolver:
|
||||
layout: follow-schema
|
||||
dir: .
|
||||
|
||||
# gqlgen will search for any type names in the schema in these go packages
|
||||
# if they match it will use them, otherwise it will generate them.
|
||||
|
||||
# autobind tells gqngen to search for any type names in the GraphQL schema in the
|
||||
# provided package. If they match it will use them, otherwise it will generate new.
|
||||
autobind:
|
||||
- todo/ent
|
||||
- todo/ent/todo
|
||||
|
||||
# This section declares type mapping between the GraphQL and Go type systems.
|
||||
models:
|
||||
# Defines the ID field as Go 'int'.
|
||||
ID:
|
||||
model:
|
||||
- github.com/99designs/gqlgen/graphql.IntID
|
||||
Node:
|
||||
model:
|
||||
- todo/ent.Noder
|
||||
```
|
||||
|
||||
3\. Edit the `ent/entc.go` to let Ent know about the `gqlgen` configuration:
|
||||
|
||||
```go
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
"entgo.io/contrib/entgql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ex, err := entgql.NewExtension(
|
||||
// Tell Ent to generate a GraphQL schema for
|
||||
// the Ent schema in a file named ent.graphql.
|
||||
entgql.WithSchemaGenerator(),
|
||||
entgql.WithSchemaPath("ent.graphql"),
|
||||
//highlight-next-line
|
||||
entgql.WithConfigPath("gqlgen.yml"),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("creating entgql extension: %v", err)
|
||||
}
|
||||
opts := []entc.Option{
|
||||
entc.Extensions(ex),
|
||||
}
|
||||
if err := entc.Generate("./ent/schema", &gen.Config{}, opts...); err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
4\. Add the `gqlgen` generate command to the `generate.go` file:
|
||||
|
||||
```go title="generate.go"
|
||||
package todo
|
||||
|
||||
//go:generate go run -mod=mod ./ent/entc.go
|
||||
//highlight-next-line
|
||||
//go:generate go run -mod=mod github.com/99designs/gqlgen
|
||||
```
|
||||
|
||||
Now, we're ready to run `go generate` to trigger `ent` and `gqlgen` code generation. Execute the following command from
|
||||
the root of the project:
|
||||
|
||||
```shell
|
||||
go generate .
|
||||
```
|
||||
|
||||
You may have noticed that some files were generated by `gqlgen`:
|
||||
|
||||
```console
|
||||
tree -L 1
|
||||
.
|
||||
├── ent/
|
||||
├── ent.graphql
|
||||
//highlight-next-line
|
||||
├── ent.resolvers.go
|
||||
├── example_test.go
|
||||
├── generate.go
|
||||
//highlight-next-line
|
||||
├── generated.go
|
||||
├── go.mod
|
||||
├── go.sum
|
||||
├── gqlgen.yml
|
||||
//highlight-next-line
|
||||
└── resolver.go
|
||||
```
|
||||
|
||||
## Basic Server
|
||||
|
||||
Before building the GraphQL server we need to set up the main schema `Resolver` defined in `resolver.go`.
|
||||
`gqlgen` allows changing the generated `Resolver` and adding dependencies to it. Let's use `ent.Client` as
|
||||
a dependency by pasting the following in `resolver.go`:
|
||||
|
||||
```go title="resolver.go"
|
||||
package todo
|
||||
|
||||
import (
|
||||
"todo/ent"
|
||||
|
||||
"github.com/99designs/gqlgen/graphql"
|
||||
)
|
||||
|
||||
// Resolver is the resolver root.
|
||||
type Resolver struct{ client *ent.Client }
|
||||
|
||||
// NewSchema creates a graphql executable schema.
|
||||
func NewSchema(client *ent.Client) graphql.ExecutableSchema {
|
||||
return NewExecutableSchema(Config{
|
||||
Resolvers: &Resolver{client},
|
||||
})
|
||||
}
|
||||
```
|
||||
|
||||
After setting up the main resolver, we create a new directory `cmd/todo` and a `main.go` file with the following code
|
||||
to set up a GraphQL server:
|
||||
|
||||
```go title="cmd/todo/main.go"
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"net/http"
|
||||
|
||||
"todo"
|
||||
"todo/ent"
|
||||
"todo/ent/migrate"
|
||||
|
||||
"entgo.io/ent/dialect"
|
||||
"github.com/99designs/gqlgen/graphql/handler"
|
||||
"github.com/99designs/gqlgen/graphql/playground"
|
||||
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
)
|
||||
|
||||
func main() {
|
||||
// Create ent.Client and run the schema migration.
|
||||
client, err := ent.Open(dialect.SQLite, "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatal("opening ent client", err)
|
||||
}
|
||||
if err := client.Schema.Create(
|
||||
context.Background(),
|
||||
migrate.WithGlobalUniqueID(true),
|
||||
); err != nil {
|
||||
log.Fatal("opening ent client", err)
|
||||
}
|
||||
|
||||
// Configure the server and start listening on :8081.
|
||||
srv := handler.NewDefaultServer(todo.NewSchema(client))
|
||||
http.Handle("/",
|
||||
playground.Handler("Todo", "/query"),
|
||||
)
|
||||
http.Handle("/query", srv)
|
||||
log.Println("listening on :8081")
|
||||
if err := http.ListenAndServe(":8081", nil); err != nil {
|
||||
log.Fatal("http server terminated", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Run the server using the command below, and open [localhost:8081](http://localhost:8081):
|
||||
|
||||
```console
|
||||
go run ./cmd/todo
|
||||
```
|
||||
|
||||
You should see the interactive playground:
|
||||
|
||||

|
||||
|
||||
If you are having trouble with getting the playground to run, go to [first section](#clone-the-code-optional) and
|
||||
clone the example repository.
|
||||
|
||||
## Query Todos
|
||||
|
||||
If we try to query our todo list, we'll get an error as the resolver method is not yet implemented.
|
||||
Let's implement the resolver by replacing the `Todos` implementation in the query resolver:
|
||||
|
||||
```diff title="ent.resolvers.go"
|
||||
func (r *queryResolver) Todos(ctx context.Context) ([]*ent.Todo, error) {
|
||||
- panic(fmt.Errorf("not implemented"))
|
||||
+ return r.client.Todo.Query().All(ctx)
|
||||
}
|
||||
```
|
||||
|
||||
Then, running this GraphQL query should return an empty todo list:
|
||||
|
||||
<Tabs
|
||||
defaultValue="graphql"
|
||||
values={[
|
||||
{label: 'GraphQL', value: 'graphql'},
|
||||
{label: 'Output', value: 'output'},
|
||||
]}>
|
||||
<TabItem value="graphql">
|
||||
|
||||
```graphql
|
||||
query AllTodos {
|
||||
todos {
|
||||
id
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="output">
|
||||
|
||||
```json
|
||||
{
|
||||
"data": {
|
||||
"todos": []
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Mutating Todos
|
||||
|
||||
As you can see above, our GraphQL schema returns an empty list of todo items. Let's create a few todo items, but this time
|
||||
we'll do it from GraphQL. Luckily, Ent provides auto generated mutations for creating and updating nodes and edges.
|
||||
|
||||
1\. We start by extending our GraphQL schema with custom mutations. Let's create a new file named `todo.graphql`
|
||||
and add our `Mutation` type:
|
||||
|
||||
```graphql title="todo.graphql"
|
||||
type Mutation {
|
||||
# The input and the output are types generated by Ent.
|
||||
createTodo(input: CreateTodoInput!): Todo
|
||||
}
|
||||
```
|
||||
|
||||
2\. Add the custom GraphQL schema to `gqlgen.yml` configuration:
|
||||
|
||||
```yaml title="gqlgen.yml"
|
||||
schema:
|
||||
- ent.graphql
|
||||
//highlight-next-line
|
||||
- todo.graphql
|
||||
# ...
|
||||
```
|
||||
|
||||
3\. Run code generation:
|
||||
|
||||
```shell
|
||||
go generate .
|
||||
```
|
||||
|
||||
As you can see, `gqlgen` generated for us a new file named `todo.resolvers.go` with the `createTodo` resolver. Let's
|
||||
connect it to Ent generated code, and ask Ent to handle this mutation:
|
||||
|
||||
```diff title="todo.resolvers.go"
|
||||
func (r *mutationResolver) CreateTodo(ctx context.Context, input ent.CreateTodoInput) (*ent.Todo, error) {
|
||||
- panic(fmt.Errorf("not implemented: CreateTodo - createTodo"))
|
||||
+ return r.client.Todo.Create().SetInput(input).Save(ctx)
|
||||
}
|
||||
```
|
||||
|
||||
4\. Re-run `go run ./cmd/todo` again and go to the playground:
|
||||
|
||||
## Demo
|
||||
|
||||
At this stage, we are ready to create a todo item and query it:
|
||||
|
||||
<Tabs
|
||||
defaultValue="mutation"
|
||||
values={[
|
||||
{label: 'Mutation', value: 'mutation'},
|
||||
{label: 'Mutation Output', value: 'mutation_output'},
|
||||
{label: 'Query', value: 'query'},
|
||||
{label: 'Query Output', value: 'query_output'},
|
||||
]}>
|
||||
<TabItem value="mutation">
|
||||
|
||||
```graphql
|
||||
mutation CreateTodo {
|
||||
createTodo(input: {text: "Create GraphQL Example", status: IN_PROGRESS, priority: 1}) {
|
||||
id
|
||||
text
|
||||
createdAt
|
||||
priority
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="mutation_output">
|
||||
|
||||
```json
|
||||
{
|
||||
"data": {
|
||||
"createTodo": {
|
||||
"id": "1",
|
||||
"text": "Create GraphQL Example",
|
||||
"createdAt": "2022-09-08T15:20:58.696576+03:00",
|
||||
"priority": 1,
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="query">
|
||||
|
||||
```graphql
|
||||
query {
|
||||
todos {
|
||||
id
|
||||
text
|
||||
status
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="query_output">
|
||||
|
||||
```json
|
||||
{
|
||||
"data": {
|
||||
"todos": [
|
||||
{
|
||||
"id": "1",
|
||||
"text": "Create GraphQL Example",
|
||||
"status": "IN_PROGRESS"
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
If you're having trouble with getting this example to work, go to [first section](#clone-the-code-optional) and clone the
|
||||
example repository.
|
||||
|
||||
---
|
||||
|
||||
Please continue to the next section where we explain how to implement the
|
||||
[Relay Node Interface](https://relay.dev/graphql/objectidentification.htm) and learn how Ent automatically supports this.
|
||||
904
doc/md/versioned-migrations.mdx
Normal file
904
doc/md/versioned-migrations.mdx
Normal file
@@ -0,0 +1,904 @@
|
||||
---
|
||||
id: versioned-migrations
|
||||
title: Versioned Migrations
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import InstallationInstructions from './components/_installation_instructions.mdx';
|
||||
import AtlasMigrateDiff from './components/_atlas_migrate_diff.mdx';
|
||||
import AtlasMigrateApply from './components/_atlas_migrate_apply.mdx';
|
||||
|
||||
## Quick Guide
|
||||
|
||||
Here are a few quick steps that explain how to auto-generate and execute migration files against a database. For
|
||||
a more in-depth explanation, continue reading the [next section](#in-depth-guide).
|
||||
|
||||
### Generating migrations
|
||||
|
||||
<InstallationInstructions />
|
||||
|
||||
Then, run the following command to automatically generate migration files for your Ent schema:
|
||||
|
||||
<AtlasMigrateDiff/>
|
||||
|
||||
:::info The role of the [dev database](https://atlasgo.io/concepts/dev-database)
|
||||
Atlas loads the **current state** by executing the SQL files stored in the migration directory onto the provided
|
||||
[dev database](https://atlasgo.io/concepts/dev-database). It then compares this state against the **desired state**
|
||||
defined by the `ent/schema` package and writes a migration plan for moving from the current state to the desired state.
|
||||
:::
|
||||
|
||||
### Applying migrations
|
||||
|
||||
|
||||
To apply the pending migration files onto the database, run the following command:
|
||||
|
||||
<AtlasMigrateApply/>
|
||||
|
||||
For more information head over to the [Atlas documentation](https://atlasgo.io/versioned/apply).
|
||||
|
||||
### Migration status
|
||||
|
||||
Use the following command to get detailed information about the migration status of the connected database:
|
||||
|
||||
<Tabs
|
||||
defaultValue="mysql"
|
||||
values={[
|
||||
{label: 'MySQL', value: 'mysql'},
|
||||
{label: 'MariaDB', value: 'maria'},
|
||||
{label: 'PostgreSQL', value: 'postgres'},
|
||||
{label: 'SQLite', value: 'sqlite'},
|
||||
]}>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```shell
|
||||
atlas migrate status \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--url "mysql://root:pass@localhost:3306/example"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="maria">
|
||||
|
||||
```shell
|
||||
atlas migrate status \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--url "maria://root:pass@localhost:3306/example"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="postgres">
|
||||
|
||||
```shell
|
||||
atlas migrate status \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--url "postgres://postgres:pass@localhost:5432/database?search_path=public&sslmode=disable"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sqlite">
|
||||
|
||||
```shell
|
||||
atlas migrate status \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--url "sqlite://file.db?_fk=1"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## In Depth Guide
|
||||
|
||||
If you are using the [Atlas](https://github.com/ariga/atlas) migration engine, you are able to use the versioned
|
||||
migration workflow. Instead of applying the computed changes directly to the database, Atlas generates a set
|
||||
of migration files containing the necessary SQL statements to migrate the database. These files can then be edited to
|
||||
your needs and be applied by many existing migration tools, such as golang-migrate, Flyway, and Liquibase.
|
||||
|
||||
### Generating Versioned Migration Files
|
||||
|
||||
Migration files are generated by computing the difference between two **states**. We call the state reflected by
|
||||
your Ent schema the **desired** state, and the **current** state is the last state of your schema before your most
|
||||
recent changes. There are two ways for Ent to determine the current state:
|
||||
|
||||
1. Replay the existing migration directory and inspect the schema (default)
|
||||
2. Connect to an existing database and inspect the schema
|
||||
|
||||
We emphasize to use the first option, as it has the advantage of not having to connect to a production database to
|
||||
create a diff. In addition, this approach also works if you have multiple deployments in different migration states.
|
||||
|
||||

|
||||
|
||||
In order to automatically generate migration files, you can use one of the two approaches:
|
||||
1. Use [Atlas](https://atlasgo.io) `migrate diff` command against your `ent/schema` package.
|
||||
2. Enable the `sql/versioned-migration` feature flag and write a small migration generation script that uses Atlas as
|
||||
a package to generate the migration files.
|
||||
|
||||
#### Option 1: Use the `atlas migrate diff` command
|
||||
|
||||
<AtlasMigrateDiff/>
|
||||
|
||||
:::note
|
||||
To enable the [`GlobalUniqueID`](migrate.md#universal-ids) option in versioned migration, append the query parameter
|
||||
`globalid=1` to the desired state. For example: `--to "ent://ent/schema?globalid=1"`.
|
||||
:::
|
||||
|
||||
Run `ls ent/migrate/migrations` after the command above was passed successfully, and you will notice Atlas created 2
|
||||
files:
|
||||
|
||||
<Tabs
|
||||
defaultValue="migration_file"
|
||||
values={[
|
||||
{label: '20220811114629_create_users.sql', value: 'migration_file'},
|
||||
{label: 'atlas.sum', value: 'sum_file'},
|
||||
]}>
|
||||
<TabItem value="migration_file">
|
||||
|
||||
```sql
|
||||
-- create "users" table
|
||||
CREATE TABLE `users` (`id` bigint NOT NULL AUTO_INCREMENT, PRIMARY KEY (`id`)) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sum_file">
|
||||
|
||||
In addition to the migration directory, Atlas maintains a file name `atlas.sum` which is used
|
||||
to ensure the integrity of the migration directory and force developers to deal with situations
|
||||
where migration order or contents were modified after the fact.
|
||||
|
||||
```text
|
||||
h1:vj6fBSDiLEwe+jGdHQvM2NU8G70lAfXwmI+zkyrxMnk=
|
||||
20220811114629_create_users.sql h1:wrm4K8GSucW6uMJX7XfmfoVPhyzz3vN5CnU1mam2Y4c=
|
||||
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
Head over to the [Applying Migration Files](#apply-migration-files) section to learn how to execute the generated
|
||||
migration files onto the database.
|
||||
|
||||
#### Option 2: Create a migration generation script
|
||||
|
||||
The first step is to enable the versioned migration feature by passing in the `sql/versioned-migration` feature flag.
|
||||
Depending on how you execute the Ent code generator, you have to use one of the two options:
|
||||
|
||||
<Tabs
|
||||
defaultValue="ent"
|
||||
values={[
|
||||
{label: 'Using Ent CLI', value: 'ent'},
|
||||
{label: 'Using the entc package', value: 'entc'},
|
||||
]}>
|
||||
<TabItem value="ent">
|
||||
|
||||
If you are using the default go generate configuration, simply add the `--feature sql/versioned-migration` to
|
||||
the `ent/generate.go` file as follows:
|
||||
|
||||
```go
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entgo.io/ent/cmd/ent generate --feature sql/versioned-migration ./schema
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="entc">
|
||||
|
||||
If you are using the code generation package (e.g. if you are using an Ent extension like `entgql`),
|
||||
add the feature flag as follows:
|
||||
|
||||
```go
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
)
|
||||
|
||||
func main() {
|
||||
err := entc.Generate("./schema", &gen.Config{
|
||||
//highlight-next-line
|
||||
Features: []gen.Feature{gen.FeatureVersionedMigration},
|
||||
})
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
After running code generation using `go generate`, the new methods for creating migration files were added to your
|
||||
`ent/migrate` package. The next steps are:
|
||||
|
||||
1\. Provide a URL to an Atlas [dev database](https://atlasgo.io/concepts/dev-database) to replay the migration directory
|
||||
and compute the **current** state. Let's use `docker` for running a local database container:
|
||||
|
||||
<Tabs
|
||||
defaultValue="mysql"
|
||||
values={[
|
||||
{label: 'MySQL', value: 'mysql'},
|
||||
{label: 'MariaDB', value: 'mariadb'},
|
||||
{label: 'PostgreSQL', value: 'postgres'},
|
||||
]}>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```bash
|
||||
docker run --name migration --rm -p 3306:3306 -e MYSQL_ROOT_PASSWORD=pass -e MYSQL_DATABASE=test -d mysql
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="mariadb">
|
||||
|
||||
```bash
|
||||
docker run --name migration --rm -p 3306:3306 -e MYSQL_ROOT_PASSWORD=pass -e MYSQL_DATABASE=test -d mariadb
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="postgres">
|
||||
|
||||
```bash
|
||||
docker run --name migration --rm -p 5432:5432 -e POSTGRES_PASSWORD=pass -e POSTGRES_DB=test -d postgres
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
2\. Create a file named `main.go` and a directory named `migrations` under the `ent/migrate` package and customize the migration generation for your project.
|
||||
|
||||
<Tabs
|
||||
defaultValue="atlas"
|
||||
values={[
|
||||
{label: 'Atlas', value: 'atlas'},
|
||||
{label: 'golang-migrate/migrate', value: 'golang_migrate'},
|
||||
{label: 'pressly/goose', value: 'goose'},
|
||||
{label: 'amacneil/dbmate', value: 'dbmate'},
|
||||
{label: 'Flyway', value: 'flyway'},
|
||||
{label: 'Liquibase', value: 'liquibase'},
|
||||
]}>
|
||||
<TabItem value="atlas">
|
||||
|
||||
```go title="ent/migrate/main.go"
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"os"
|
||||
|
||||
"<project>/ent/migrate"
|
||||
|
||||
atlas "ariga.io/atlas/sql/migrate"
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ctx := context.Background()
|
||||
// Create a local migration directory able to understand Atlas migration file format for replay.
|
||||
dir, err := atlas.NewLocalDir("ent/migrate/migrations")
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating atlas migration directory: %v", err)
|
||||
}
|
||||
// Migrate diff options.
|
||||
opts := []schema.MigrateOption{
|
||||
schema.WithDir(dir), // provide migration directory
|
||||
schema.WithMigrationMode(schema.ModeReplay), // provide migration mode
|
||||
schema.WithDialect(dialect.MySQL), // Ent dialect to use
|
||||
schema.WithFormatter(atlas.DefaultFormatter),
|
||||
}
|
||||
if len(os.Args) != 2 {
|
||||
log.Fatalln("migration name is required. Use: 'go run -mod=mod ent/migrate/main.go <name>'")
|
||||
}
|
||||
// Generate migrations using Atlas support for MySQL (note the Ent dialect option passed above).
|
||||
err = migrate.NamedDiff(ctx, "mysql://root:pass@localhost:3306/test", os.Args[1], opts...)
|
||||
if err != nil {
|
||||
log.Fatalf("failed generating migration file: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="golang_migrate">
|
||||
|
||||
```go title="ent/migrate/main.go"
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"os"
|
||||
|
||||
"<project>/ent/migrate"
|
||||
|
||||
"ariga.io/atlas/sql/sqltool"
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ctx := context.Background()
|
||||
// Create a local migration directory able to understand golang-migrate migration file format for replay.
|
||||
dir, err := sqltool.NewGolangMigrateDir("ent/migrate/migrations")
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating atlas migration directory: %v", err)
|
||||
}
|
||||
// Migrate diff options.
|
||||
opts := []schema.MigrateOption{
|
||||
schema.WithDir(dir), // provide migration directory
|
||||
schema.WithMigrationMode(schema.ModeReplay), // provide migration mode
|
||||
schema.WithDialect(dialect.MySQL), // Ent dialect to use
|
||||
}
|
||||
if len(os.Args) != 2 {
|
||||
log.Fatalln("migration name is required. Use: 'go run -mod=mod ent/migrate/main.go <name>'")
|
||||
}
|
||||
// Generate migrations using Atlas support for MySQL (note the Ent dialect option passed above).
|
||||
err = migrate.NamedDiff(ctx, "mysql://root:pass@localhost:3306/test", os.Args[1], opts...)
|
||||
if err != nil {
|
||||
log.Fatalf("failed generating migration file: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="goose">
|
||||
|
||||
```go title="ent/migrate/main.go"
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"os"
|
||||
|
||||
"<project>/ent/migrate"
|
||||
|
||||
"ariga.io/atlas/sql/sqltool"
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ctx := context.Background()
|
||||
// Create a local migration directory able to understand goose migration file format for replay.
|
||||
dir, err := sqltool.NewGooseDir("ent/migrate/migrations")
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating atlas migration directory: %v", err)
|
||||
}
|
||||
// Migrate diff options.
|
||||
opts := []schema.MigrateOption{
|
||||
schema.WithDir(dir), // provide migration directory
|
||||
schema.WithMigrationMode(schema.ModeReplay), // provide migration mode
|
||||
schema.WithDialect(dialect.MySQL), // Ent dialect to use
|
||||
}
|
||||
if len(os.Args) != 2 {
|
||||
log.Fatalln("migration name is required. Use: 'go run -mod=mod ent/migrate/main.go <name>'")
|
||||
}
|
||||
// Generate migrations using Atlas support for MySQL (note the Ent dialect option passed above).
|
||||
err = migrate.NamedDiff(ctx, "mysql://root:pass@localhost:3306/test", os.Args[1], opts...)
|
||||
if err != nil {
|
||||
log.Fatalf("failed generating migration file: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="dbmate">
|
||||
|
||||
```go title="ent/migrate/main.go"
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"os"
|
||||
|
||||
"<project>/ent/migrate"
|
||||
|
||||
"ariga.io/atlas/sql/sqltool"
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ctx := context.Background()
|
||||
// Create a local migration directory able to understand dbmate migration file format for replay.
|
||||
dir, err := sqltool.NewDBMateDir("ent/migrate/migrations")
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating atlas migration directory: %v", err)
|
||||
}
|
||||
// Migrate diff options.
|
||||
opts := []schema.MigrateOption{
|
||||
schema.WithDir(dir), // provide migration directory
|
||||
schema.WithMigrationMode(schema.ModeReplay), // provide migration mode
|
||||
schema.WithDialect(dialect.MySQL), // Ent dialect to use
|
||||
}
|
||||
if len(os.Args) != 2 {
|
||||
log.Fatalln("migration name is required. Use: 'go run -mod=mod ent/migrate/main.go <name>'")
|
||||
}
|
||||
// Generate migrations using Atlas support for MySQL (note the Ent dialect option passed above).
|
||||
err = migrate.NamedDiff(ctx, "mysql://root:pass@localhost:3306/test", os.Args[1], opts...)
|
||||
if err != nil {
|
||||
log.Fatalf("failed generating migration file: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="flyway">
|
||||
|
||||
```go title="ent/migrate/main.go"
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"os"
|
||||
|
||||
"<project>/ent/migrate"
|
||||
|
||||
"ariga.io/atlas/sql/sqltool"
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ctx := context.Background()
|
||||
// Create a local migration directory able to understand Flyway migration file format for replay.
|
||||
dir, err := sqltool.NewFlywayDir("ent/migrate/migrations")
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating atlas migration directory: %v", err)
|
||||
}
|
||||
// Migrate diff options.
|
||||
opts := []schema.MigrateOption{
|
||||
schema.WithDir(dir), // provide migration directory
|
||||
schema.WithMigrationMode(schema.ModeReplay), // provide migration mode
|
||||
schema.WithDialect(dialect.MySQL), // Ent dialect to use
|
||||
}
|
||||
if len(os.Args) != 2 {
|
||||
log.Fatalln("migration name is required. Use: 'go run -mod=mod ent/migrate/main.go <name>'")
|
||||
}
|
||||
// Generate migrations using Atlas support for MySQL (note the Ent dialect option passed above).
|
||||
err = migrate.NamedDiff(ctx, "mysql://root:pass@localhost:3306/test", os.Args[1], opts...)
|
||||
if err != nil {
|
||||
log.Fatalf("failed generating migration file: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="liquibase">
|
||||
|
||||
```go title="ent/migrate/main.go"
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"os"
|
||||
|
||||
"<project>/ent/migrate"
|
||||
|
||||
"ariga.io/atlas/sql/sqltool"
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ctx := context.Background()
|
||||
// Create a local migration directory able to understand Liquibase migration file format for replay.
|
||||
dir, err := sqltool.NewLiquibaseDir("ent/migrate/migrations")
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating atlas migration directory: %v", err)
|
||||
}
|
||||
// Migrate diff options.
|
||||
opts := []schema.MigrateOption{
|
||||
schema.WithDir(dir), // provide migration directory
|
||||
schema.WithMigrationMode(schema.ModeReplay), // provide migration mode
|
||||
schema.WithDialect(dialect.MySQL), // Ent dialect to use
|
||||
}
|
||||
if len(os.Args) != 2 {
|
||||
log.Fatalln("migration name is required. Use: 'go run -mod=mod ent/migrate/main.go <name>'")
|
||||
}
|
||||
// Generate migrations using Atlas support for MySQL (note the Ent dialect option passed above).
|
||||
err = migrate.NamedDiff(ctx, "mysql://root:pass@localhost:3306/test", os.Args[1], opts...)
|
||||
if err != nil {
|
||||
log.Fatalf("failed generating migration file: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
3\. Trigger migration generation by executing `go run -mod=mod ent/migrate/main.go <name>` from the root of the project.
|
||||
For example:
|
||||
|
||||
```bash
|
||||
go run -mod=mod ent/migrate/main.go create_users
|
||||
```
|
||||
|
||||
Run `ls ent/migrate/migrations` after the command above was passed successfully, and you will notice Atlas created 2
|
||||
files:
|
||||
|
||||
<Tabs
|
||||
defaultValue="migration_file"
|
||||
values={[
|
||||
{label: '20220811114629_create_users.sql', value: 'migration_file'},
|
||||
{label: 'atlas.sum', value: 'sum_file'},
|
||||
]}>
|
||||
<TabItem value="migration_file">
|
||||
|
||||
```sql
|
||||
-- create "users" table
|
||||
CREATE TABLE `users` (`id` bigint NOT NULL AUTO_INCREMENT, PRIMARY KEY (`id`)) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sum_file">
|
||||
|
||||
In addition to the migration directory, Atlas maintains a file name `atlas.sum` which is used
|
||||
to ensure the integrity of the migration directory and force developers to deal with situations
|
||||
where migration order or contents were modified after the fact.
|
||||
|
||||
```text
|
||||
h1:vj6fBSDiLEwe+jGdHQvM2NU8G70lAfXwmI+zkyrxMnk=
|
||||
20220811114629_create_users.sql h1:wrm4K8GSucW6uMJX7XfmfoVPhyzz3vN5CnU1mam2Y4c=
|
||||
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
The full reference example exists in [GitHub repository](https://github.com/ent/ent/tree/master/examples/migration).
|
||||
|
||||
### Verifying and linting migrations
|
||||
|
||||
After generating our migration files with Atlas, we can run the [`atlas migrate lint`](https://atlasgo.io/versioned/lint)
|
||||
command that validates and analyzes the contents of the migration directory and generate insights and diagnostics on the
|
||||
selected changes:
|
||||
|
||||
1. Ensure the migration history can be replayed from any point at time.
|
||||
2. Protect from unexpected history changes when concurrent migrations are written to the migration directory by multiple
|
||||
team members. Read more about the consistency checks in the [section below](#atlas-migration-directory-integrity-file).
|
||||
3. Detect whether [destructive](https://atlasgo.io/lint/analyzers#destructive-changes) or irreversible changes have been
|
||||
made or whether they are dependent on tables' contents and can cause a migration failure.
|
||||
|
||||
Let's run `atlas migrate lint` with the necessary parameters to run migration linting:
|
||||
|
||||
- `--dev-url` a URL to a [Dev Database](https://atlasgo.io/concepts/dev-database) that will be used to replay changes.
|
||||
- `--dir` the URL to the migration directory, by default it is `file://migrations`.
|
||||
- `--dir-format` custom directory format, by default it is `atlas`.
|
||||
- (optional) `--log` custom logging using a Go template.
|
||||
- (optional) `--latest` run analysis on the latest `N` migration files.
|
||||
- (optional) `--git-base` run analysis against the base Git branch.
|
||||
|
||||
#### Install Atlas:
|
||||
|
||||
<InstallationInstructions />
|
||||
|
||||
#### Run the `atlas migrate lint` command:
|
||||
|
||||
<Tabs
|
||||
defaultValue="mysql"
|
||||
values={[
|
||||
{label: 'MySQL', value: 'mysql'},
|
||||
{label: 'MariaDB', value: 'maria'},
|
||||
{label: 'PostgreSQL', value: 'postgres'},
|
||||
{label: 'SQLite', value: 'sqlite'},
|
||||
]}>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```shell
|
||||
atlas migrate lint \
|
||||
--dev-url="docker://mysql/8/test" \
|
||||
--dir="file://ent/migrate/migrations" \
|
||||
--latest=1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="maria">
|
||||
|
||||
```shell
|
||||
atlas migrate lint \
|
||||
--dev-url="docker://mariadb/latest/test" \
|
||||
--dir="file://ent/migrate/migrations" \
|
||||
--latest=1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="postgres">
|
||||
|
||||
```shell
|
||||
atlas migrate lint \
|
||||
--dev-url="docker://postgres/15/test?search_path=public" \
|
||||
--dir="file://ent/migrate/migrations" \
|
||||
--latest=1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sqlite">
|
||||
|
||||
```shell
|
||||
atlas migrate lint \
|
||||
--dev-url="sqlite://file?mode=memory" \
|
||||
--dir="file://ent/migrate/migrations" \
|
||||
--latest=1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
An output of such a run might look as follows:
|
||||
|
||||
```text {3,7}
|
||||
20221114090322_add_age.sql: data dependent changes detected:
|
||||
|
||||
L2: Adding a non-nullable "double" column "age" on table "users" without a default value implicitly sets existing rows with 0
|
||||
|
||||
20221114101516_add_name.sql: data dependent changes detected:
|
||||
|
||||
L2: Adding a non-nullable "varchar" column "name" on table "users" without a default value implicitly sets existing rows with ""
|
||||
```
|
||||
|
||||
|
||||
#### A Word on Global Unique IDs
|
||||
|
||||
**This section only applies to MySQL users using the [global unique id](migrate.md/#universal-ids) feature.**
|
||||
|
||||
When using the global unique ids, Ent allocates a range of `1<<32` integer values for each table. This is done by giving
|
||||
the first table an autoincrement starting value of `1`, the second one the starting value `4294967296`, the third one
|
||||
`8589934592`, and so on. The order in which the tables receive the starting value is saved in an extra table
|
||||
called `ent_types`. With MySQL 5.6 and 5.7, the autoincrement starting value is only saved in
|
||||
memory ([docs](https://dev.mysql.com/doc/refman/8.0/en/innodb-auto-increment-handling.html), **InnoDB AUTO_INCREMENT
|
||||
Counter Initialization** header) and re-calculated on startup by looking at the last inserted id for any table. Now, if
|
||||
you happen to have a table with no rows yet, the autoincrement starting value is set to 0 for every table without any
|
||||
entries. With the online migration feature this wasn't an issue, because the migration engine looked at the `ent_types`
|
||||
tables and made sure to update the counter, if it wasn't set correctly. However, with versioned migration, this is no
|
||||
longer the case. In order to ensure, that everything is set up correctly after a server restart, make sure to call
|
||||
the `VerifyTableRange` method on the Atlas struct:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"<project>/ent"
|
||||
"<project>/ent/migrate"
|
||||
"entgo.io/ent/dialect/sql"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
drv, err := sql.Open("mysql", "user:pass@tcp(localhost:3306)/ent")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to mysql: %v", err)
|
||||
}
|
||||
defer drv.Close()
|
||||
// Verify the type allocation range.
|
||||
m, err := schema.NewMigrate(drv, nil)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating migrate: %v", err)
|
||||
}
|
||||
if err := m.VerifyTableRange(context.Background(), migrate.Tables); err != nil {
|
||||
log.Fatalf("failed verifyint range allocations: %v", err)
|
||||
}
|
||||
client := ent.NewClient(ent.Driver(drv))
|
||||
// ... do stuff with the client
|
||||
}
|
||||
```
|
||||
|
||||
:::caution Important
|
||||
After an upgrade to MySQL 8 from a previous version, you still have to run the method once to update the starting
|
||||
values. Since MySQL 8 the counter is no longer only stored in memory, meaning subsequent calls to the method are no
|
||||
longer needed after the first one.
|
||||
:::
|
||||
|
||||
### Apply Migration Files
|
||||
|
||||
Ent recommends to use the Atlas CLI to apply the generated migration files onto the database. If you want to use any
|
||||
other migration management tool, Ent has support for generating migrations for several of them out of the box.
|
||||
|
||||
<AtlasMigrateApply/>
|
||||
|
||||
For more information head over to the [Atlas documentation](https://atlasgo.io/versioned/apply).
|
||||
|
||||
:::info
|
||||
|
||||
In previous versions of Ent [`golang-migrate/migrate`](https://github.com/golang-migrate/migrate) has been the default
|
||||
migration execution engine. For an easy transition, Atlas can import the migrations format of golang-migrate for you.
|
||||
You can learn more about it in the [Atlas documentation](https://atlasgo.io/versioned/import).
|
||||
|
||||
:::
|
||||
|
||||
## Moving from Auto-Migration to Versioned Migrations
|
||||
|
||||
In case you already have an Ent application in production and want to switch over from auto migration to the new
|
||||
versioned migration, you need to take some extra steps.
|
||||
|
||||
### Create an initial migration file reflecting the currently deployed state
|
||||
|
||||
To do this make sure your schema definition is in sync with your deployed version(s). Then spin up an empty database and
|
||||
run the diff command once as described above. This will create the statements needed to create the current state of
|
||||
your schema graph. If you happened to have [universal IDs](migrate.md#universal-ids) enabled before, any deployment will
|
||||
have a special database table named `ent_types`. The above command will create the necessary SQL statements to create
|
||||
that table as well as its contents (similar to the following):
|
||||
|
||||
```sql
|
||||
CREATE TABLE `users` (`id` integer NOT NULL PRIMARY KEY AUTOINCREMENT);
|
||||
CREATE TABLE `groups` (`id` integer NOT NULL PRIMARY KEY AUTOINCREMENT);
|
||||
INSERT INTO sqlite_sequence (name, seq) VALUES ("groups", 4294967296);
|
||||
CREATE TABLE `ent_types` (`id` integer NOT NULL PRIMARY KEY AUTOINCREMENT, `type` text NOT NULL);
|
||||
CREATE UNIQUE INDEX `ent_types_type_key` ON `ent_types` (`type`);
|
||||
INSERT INTO `ent_types` (`type`) VALUES ('users'), ('groups');
|
||||
```
|
||||
|
||||
In order to ensure to not break existing code, make sure the contents of that file are equal to the contents in the
|
||||
table present in the database you created the diff from. For example, if you consider the migration file from
|
||||
above (`users,groups`) but your deployed table looks like the one below (`groups,users`):
|
||||
|
||||
| id | type |
|
||||
|-----|--------|
|
||||
| 1 | groups |
|
||||
| 2 | users |
|
||||
|
||||
You can see, that the order differs. In that case, you have to manually change both the entries in the generated
|
||||
migration file.
|
||||
|
||||
### Use an Atlas Baseline Migration
|
||||
|
||||
If you are using Atlas as migration execution engine, you can then simply use the `--baseline` flag. For other tools,
|
||||
please take a look at their respective documentation.
|
||||
|
||||
```shell
|
||||
atlas migrate apply \
|
||||
--dir "file://migrations"
|
||||
--url mysql://root:pass@localhost:3306/ent
|
||||
--baseline "<version>"
|
||||
```
|
||||
|
||||
## Atlas migration directory integrity file
|
||||
|
||||
### The Problem
|
||||
|
||||
Suppose you have multiple teams develop a feature in parallel and both of them need a migration. If Team A and Team B do
|
||||
not check in with each other, they might end up with a broken set of migration files (like adding the same table or
|
||||
column twice) since new files do not raise a merge conflict in a version control system like git. The following example
|
||||
demonstrates such behavior:
|
||||
|
||||

|
||||
|
||||
Assume both Team A and Team B add a new schema called User and generate a versioned migration file on their respective
|
||||
branch.
|
||||
|
||||
```sql title="20220318104614_team_A.sql"
|
||||
-- create "users" table
|
||||
CREATE TABLE `users` (
|
||||
`id` bigint NOT NULL AUTO_INCREMENT,
|
||||
// highlight-start
|
||||
`team_a_col` INTEGER NOT NULL,
|
||||
// highlight-end
|
||||
PRIMARY KEY (`id`)
|
||||
) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
```
|
||||
|
||||
```sql title="20220318104615_team_B.sql"
|
||||
-- create "users" table
|
||||
CREATE TABLE `users` (
|
||||
`id` bigint NOT NULL AUTO_INCREMENT,
|
||||
// highlight-start
|
||||
`team_b_col` INTEGER NOT NULL,
|
||||
// highlight-end
|
||||
PRIMARY KEY (`id`)
|
||||
) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
```
|
||||
|
||||
If they both merge their branch into master, git will not raise a conflict and everything seems fine. But attempting to
|
||||
apply the pending migrations will result in migration failure:
|
||||
|
||||
```shell
|
||||
mysql> CREATE TABLE `users` (`id` bigint NOT NULL AUTO_INCREMENT, `team_a_col` INTEGER NOT NULL, PRIMARY KEY (`id`)) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
[2022-04-14 10:00:38] completed in 31 ms
|
||||
|
||||
mysql> CREATE TABLE `users` (`id` bigint NOT NULL AUTO_INCREMENT, `team_b_col` INTEGER NOT NULL, PRIMARY KEY (`id`)) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
[2022-04-14 10:00:48] [42S01][1050] Table 'users' already exists
|
||||
```
|
||||
|
||||
Depending on the SQL this can potentially leave your database in a crippled state.
|
||||
|
||||
### The Solution
|
||||
|
||||
Luckily, the Atlas migration engine offers a way to prevent concurrent creation of new migration files and guard against
|
||||
accidental changes in the migration history we call **Migration Directory Integrity File**, which simply is another file
|
||||
in your migration directory called `atlas.sum`. For the migration directory of team A it would look similar to this:
|
||||
|
||||
```text
|
||||
h1:KRFsSi68ZOarsQAJZ1mfSiMSkIOZlMq4RzyF//Pwf8A=
|
||||
20220318104614_team_A.sql h1:EGknG5Y6GQYrc4W8e/r3S61Aqx2p+NmQyVz/2m8ZNwA=
|
||||
|
||||
```
|
||||
|
||||
The `atlas.sum` file contains the checksum of each migration file (implemented by a reverse, one branch merkle hash
|
||||
tree), and a sum of all files. Adding new files results in a change to the sum file, which will raise merge conflicts in
|
||||
most version controls systems. Let's see how we can use the **Migration Directory Integrity File** to detect the case
|
||||
from above automatically.
|
||||
|
||||
:::note
|
||||
Please note, that you need to have the Atlas CLI installed in your system for this to work, so make sure to follow
|
||||
the [installation instructions](https://atlasgo.io/cli/getting-started/setting-up#install-the-cli) before proceeding.
|
||||
:::
|
||||
|
||||
In previous versions of Ent, the integrity file was opt-in. But we think this is a very important feature that provides
|
||||
great value and safety to migrations. Therefore, generation of the sum file is now the default behavior and in the
|
||||
future we might even remove the option to disable this feature. For now, if you really want to remove integrity file
|
||||
generation, use the `schema.DisableChecksum()` option.
|
||||
|
||||
In addition to the usual `.sql` migration files the migration directory will contain the `atlas.sum` file. Every time
|
||||
you let Ent generate a new migration file, this file is updated for you. However, every manual change made to the
|
||||
migration directory will render the migration directory and the `atlas.sum` file out-of-sync. With the Atlas CLI you can
|
||||
both check if the file and migration directory are in-sync, and fix it if not:
|
||||
|
||||
```shell
|
||||
# If there is no output, the migration directory is in-sync.
|
||||
atlas migrate validate --dir file://<path-to-your-migration-directory>
|
||||
```
|
||||
|
||||
```shell
|
||||
# If the migration directory and sum file are out-of-sync the Atlas CLI will tell you.
|
||||
atlas migrate validate --dir file://<path-to-your-migration-directory>
|
||||
Error: checksum mismatch
|
||||
|
||||
You have a checksum error in your migration directory.
|
||||
This happens if you manually create or edit a migration file.
|
||||
Please check your migration files and run
|
||||
|
||||
'atlas migrate hash'
|
||||
|
||||
to re-hash the contents and resolve the error.
|
||||
|
||||
exit status 1
|
||||
```
|
||||
|
||||
If you are sure, that the contents in your migration files are correct, you can re-compute the hashes in the `atlas.sum`
|
||||
file:
|
||||
|
||||
```shell
|
||||
# Recompute the sum file.
|
||||
atlas migrate hash --dir file://<path-to-your-migration-directory>
|
||||
```
|
||||
|
||||
Back to the problem above, if team A would land their changes on master first and team B would now attempt to land
|
||||
theirs, they'd get a merge conflict, as you can see in the example below:
|
||||
|
||||

|
||||
|
||||
You can add the `atlas migrate validate` call to your CI to have the migration directory checked continuously. Even if
|
||||
any team member would now forget to update the `atlas.sum` file after a manual edit, the CI would not go green,
|
||||
indicating a problem.
|
||||
58
doc/md/versioned/01-intro.md
Normal file
58
doc/md/versioned/01-intro.md
Normal file
@@ -0,0 +1,58 @@
|
||||
---
|
||||
id: intro
|
||||
title: Introduction
|
||||
---
|
||||
## Schema Migration Flows
|
||||
|
||||
Ent supports two different workflows for managing schema changes:
|
||||
* Automatic Migrations - a declarative style of schema migrations which happen entirely at runtime.
|
||||
With this flow, Ent calculates the difference between the connected database and the database
|
||||
schema needed to satisfy the `ent.Schema` definitions, and then applies the changes to the database.
|
||||
* Versioned Migrations - a workflow where schema migrations are written as SQL files ahead of time
|
||||
and then are applied to the database by a specialized tool such as [Atlas](https://atlasgo.io) or
|
||||
[golang-migrate](https://github.com/golang-migrate/migrate).
|
||||
|
||||
Many users start with the automatic migration flow as it is the easiest to get started with, but
|
||||
as their project grows, they may find that they need more control over the migration process, and
|
||||
they switch to the versioned migration flow.
|
||||
|
||||
This tutorial will walk you through the process of upgrading an existing project from automatic migrations
|
||||
to versioned migrations.
|
||||
|
||||
## Supporting repository
|
||||
|
||||
All of the steps demonstrated in this tutorial can be found in the
|
||||
[rotemtam/ent-versioned-migrations-demo](https://github.com/rotemtam/ent-versioned-migrations-demo)
|
||||
repository on GitHub. In each section we will link to the relevant commit in the repository.
|
||||
|
||||
The initial Ent project which we will be upgrading can be found
|
||||
[here](https://github.com/rotemtam/ent-versioned-migrations-demo/tree/start).
|
||||
|
||||
## Automatic Migration
|
||||
|
||||
In this tutorial, we assume you have an existing Ent project and that you are using automatic migrations.
|
||||
Many simpler projects have a block of code similar to this in their `main.go` file:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
func main() {
|
||||
// Connect to the database (MySQL for example).
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Run migration.
|
||||
// highlight-next-line
|
||||
if err := client.Schema.Create(ctx); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
// ... Continue with server start.
|
||||
}
|
||||
```
|
||||
|
||||
This code connects to the database, and then runs the automatic migration tool to create all schema resources.
|
||||
|
||||
Next, let's see how to set up our project for versioned migrations.
|
||||
43
doc/md/versioned/02-auto-plan.mdx
Normal file
43
doc/md/versioned/02-auto-plan.mdx
Normal file
@@ -0,0 +1,43 @@
|
||||
---
|
||||
title: Automatic migration planning
|
||||
id: auto-plan
|
||||
---
|
||||
|
||||
import InstallationInstructions from '../components/_installation_instructions.mdx';
|
||||
import AtlasMigrateDiff from '../components/_atlas_migrate_diff.mdx';
|
||||
|
||||
## Automatic migration planning
|
||||
|
||||
One of the convenient features of Automatic Migrations is that developers do not
|
||||
need to write the SQL statements to create or modify the database schema. To
|
||||
achieve similar benefits, we will now add a script to our project that will
|
||||
automatically plan migration files for us based on the changes to our schema.
|
||||
|
||||
To do this, Ent uses [Atlas](https://atlasgo.io), an open-source tool for managing database
|
||||
schemas, created by the same people behind Ent.
|
||||
|
||||
If you have been following our example repo, we have been using SQLite as our database
|
||||
until this point. To demonstrate a more realistic use case, we will now switch to MySQL.
|
||||
See this change in [PR #3](https://github.com/rotemtam/ent-versioned-migrations-demo/pull/3/files).
|
||||
|
||||
## Using the Atlas CLI to plan migrations
|
||||
|
||||
In this section, we will demonstrate how to use the Atlas CLI to automatically plan
|
||||
schema migrations for us. In the past, users had to create a custom Go program to
|
||||
do this (as described [here](07-programmatically.mdx)). With recent versions of Atlas,
|
||||
this is no longer necessary: Atlas can natively load the desired database schema from an Ent schema.
|
||||
|
||||
<InstallationInstructions />
|
||||
|
||||
Then, run the following command to automatically generate migration files for your Ent schema:
|
||||
|
||||
<AtlasMigrateDiff/>
|
||||
|
||||
:::info The role of the [dev database](https://atlasgo.io/concepts/dev-database)
|
||||
Atlas loads the **current state** by executing the SQL files stored in the migration directory onto the provided
|
||||
[dev database](https://atlasgo.io/concepts/dev-database). It then compares this state against the **desired state**
|
||||
defined by the `ent/schema` package and writes a migration plan for moving from the current state to the desired state.
|
||||
:::
|
||||
|
||||
|
||||
Next, let's see how to upgrade an existing production database to be managed with versioned migrations.
|
||||
78
doc/md/versioned/03-upgrade-prod.mdx
Normal file
78
doc/md/versioned/03-upgrade-prod.mdx
Normal file
@@ -0,0 +1,78 @@
|
||||
---
|
||||
id: upgrade-prod
|
||||
title: Upgrading Production
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
:::info Supporting repository
|
||||
|
||||
The change described in this section can be found in
|
||||
[PR #5](https://github.com/rotemtam/ent-versioned-migrations-demo/pull/5/files)
|
||||
in the supporting repository.
|
||||
|
||||
:::
|
||||
|
||||
## Upgrading our production database to use versioned migrations
|
||||
|
||||
If you have been following our tutorial to this point, you may be asking yourself how do we
|
||||
upgrade the production instance of our database to be managed by the versioned migraions workflow?
|
||||
With local development, we can just delete the database and start over, but that is not an option
|
||||
for production for obvious reasons.
|
||||
|
||||
Like many other database schema management tools, [Atlas](https://atlasgo.io) uses a metadata table
|
||||
on the target database to keep track of which migrations were already applied.
|
||||
In the case where we start using Atlas on an existing database, we must somehow
|
||||
inform Atlas that all migrations up to a certain version were already applied.
|
||||
|
||||
To illustrate this, let's try to run Atlas's `migrate apply` command on a database
|
||||
that is currently managed by an auto-migration workflow using the migration directory that we just
|
||||
created. Notice that we use a connection string to a database that _already has_ the application schema
|
||||
instantiated (we use the `/db` suffix to indicate that we want to connect to the `db` database).
|
||||
|
||||
```text
|
||||
atlas migrate apply --dir file://ent/migrate/migrations --url mysql://root:pass@localhost:3306/db
|
||||
```
|
||||
|
||||
Atlas returns an error:
|
||||
|
||||
```text
|
||||
Error: sql/migrate: connected database is not clean: found table "atlas_schema_revisions" in schema "db". baseline version or allow-dirty is required
|
||||
```
|
||||
|
||||
This error is expected, as this is the first time we are running Atlas on this database, but as the error said
|
||||
we need to "baseline" the database. This means that we tell Atlas that the database is already at a certain state
|
||||
that correlates with one of the versions in the migration directory.
|
||||
|
||||
To fix this, we use the `--baseline` flag to tell Atlas that the database is already at
|
||||
a certain version:
|
||||
|
||||
```text
|
||||
atlas migrate apply --dir file://ent/migrate/migrations --url mysql://root:pass@localhost:3306/db --baseline 20221114165732
|
||||
```
|
||||
|
||||
Atlas reports that there's nothing new to run:
|
||||
|
||||
```text
|
||||
No migration files to execute
|
||||
```
|
||||
|
||||
That's better! Next, let's verify that Atlas is aware of what migrations
|
||||
were already applied by using the `migrate status` command:
|
||||
|
||||
```text
|
||||
atlas migrate status --dir file://ent/migrate/migrations --url mysql://root:pass@localhost:3306/db
|
||||
```
|
||||
Atlas reports:
|
||||
```text
|
||||
Migration Status: OK
|
||||
-- Current Version: 20221114165732
|
||||
-- Next Version: Already at latest version
|
||||
-- Executed Files: 1
|
||||
-- Pending Files: 0
|
||||
```
|
||||
Great! We have successfully upgraded our project to use versioned migrations with Atlas.
|
||||
|
||||
Next, let's see how we add a new migration to our project when we make a change to our
|
||||
Ent schema.
|
||||
129
doc/md/versioned/04-new-migration.mdx
Normal file
129
doc/md/versioned/04-new-migration.mdx
Normal file
@@ -0,0 +1,129 @@
|
||||
---
|
||||
title: Planning a Migration
|
||||
id: new-migration
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
:::info Supporting repository
|
||||
|
||||
The change described in this section can be found in
|
||||
[PR #6](https://github.com/rotemtam/ent-versioned-migrations-demo/pull/6/files)
|
||||
in the supporting repository.
|
||||
|
||||
:::
|
||||
|
||||
|
||||
## Planning a migration
|
||||
|
||||
In this section, we will discuss how to plan a new schema migration when we
|
||||
make a change to our project's Ent schema. Consider we want to add a new field
|
||||
to our `User` entity, adding a new optional field named `title`:
|
||||
|
||||
```go title=ent/schema/user.go
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.String("email"). // <-- Our new field
|
||||
Unique(),
|
||||
// highlight-start
|
||||
field.String("title").
|
||||
Optional(),
|
||||
// highlight-end
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
After adding the new field, we need to rerun code-gen for our project:
|
||||
|
||||
```shell
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Next, we need to create a new migration file for our change using the Atlas CLI:
|
||||
|
||||
|
||||
<Tabs
|
||||
defaultValue="mysql"
|
||||
values={[
|
||||
{label: 'MySQL', value: 'mysql'},
|
||||
{label: 'MariaDB', value: 'maria'},
|
||||
{label: 'PostgreSQL', value: 'postgres'},
|
||||
{label: 'SQLite', value: 'sqlite'},
|
||||
]}>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```shell
|
||||
atlas migrate diff add_user_title \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://mysql/8/ent"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="maria">
|
||||
|
||||
```shell
|
||||
atlas migrate diff add_user_title \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://mariadb/latest/test"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="postgres">
|
||||
|
||||
```shell
|
||||
atlas migrate diff add_user_title \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://postgres/15/test?search_path=public"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sqlite">
|
||||
|
||||
```shell
|
||||
atlas migrate diff add_user_title \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "sqlite://file?mode=memory&_fk=1"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
Observe a new file named `20221115101649_add_user_title.sql` was created under
|
||||
the `ent/migrate/migrations/` directory. This file contains the SQL statements
|
||||
to create the newly added `title` field in the `users` table:
|
||||
|
||||
```sql title=ent/migrate/migrations/20221115101649_add_user_title.sql
|
||||
-- modify "users" table
|
||||
ALTER TABLE `users` ADD COLUMN `title` varchar(255) NULL;
|
||||
```
|
||||
|
||||
Great! We've successfully used the Atlas CLI to automatically
|
||||
generate a new migration file for our change.
|
||||
|
||||
To apply the migration, we can run the following command:
|
||||
|
||||
```shell
|
||||
atlas migrate apply --dir file://ent/migrate/migrations --url mysql://root:pass@localhost:3306/db
|
||||
```
|
||||
Atlas reports:
|
||||
```shell
|
||||
Migrating to version 20221115101649 from 20221114165732 (1 migrations in total):
|
||||
|
||||
-- migrating version 20221115101649
|
||||
-> ALTER TABLE `users` ADD COLUMN `title` varchar(255) NULL;
|
||||
-- ok (36.152277ms)
|
||||
|
||||
-------------------------
|
||||
-- 44.1116ms
|
||||
-- 1 migrations
|
||||
-- 1 sql statements
|
||||
```
|
||||
|
||||
In the next section, we will discuss how to plan custom schema migrations for our project.
|
||||
91
doc/md/versioned/05-custom-migrations.md
Normal file
91
doc/md/versioned/05-custom-migrations.md
Normal file
@@ -0,0 +1,91 @@
|
||||
---
|
||||
title: Custom migrations
|
||||
id: custom-migrations
|
||||
---
|
||||
:::info Supporting repository
|
||||
|
||||
The change described in this section can be found in
|
||||
[PR #7](https://github.com/rotemtam/ent-versioned-migrations-demo/pull/7/files)
|
||||
in the supporting repository.
|
||||
|
||||
:::
|
||||
|
||||
## Custom migrations
|
||||
In some cases, you may want to write custom migrations that are not automatically
|
||||
generated by Atlas. This can be useful in cases where you want to perform changes
|
||||
to your database that aren't currently supported by Ent, or if you want to seed
|
||||
the database with data.
|
||||
|
||||
In this section, we will learn how to add custom migrations to our project. For the
|
||||
purpose of this guide, let's assume we want to seed the users table with some data.
|
||||
|
||||
## Create a custom migration
|
||||
|
||||
Let's start by adding a new migration file to our project:
|
||||
|
||||
```shell
|
||||
atlas migrate new seed_users --dir file://ent/migrate/migrations
|
||||
```
|
||||
|
||||
Observe that a new file named `20221115102552_seed_users.sql` was created in the
|
||||
`ent/migrate/migrations` directory.
|
||||
|
||||
Continue by opening the file and adding the following SQL statements:
|
||||
|
||||
```sql
|
||||
INSERT INTO `users` (`name`, `email`, `title`)
|
||||
VALUES ('Jerry Seinfeld', 'jerry@seinfeld.io', 'Mr.'),
|
||||
('George Costanza', 'george@costanza.io', 'Mr.')
|
||||
```
|
||||
|
||||
## Recalculating the checksum file
|
||||
|
||||
Let's try to run our new custom migration:
|
||||
|
||||
```shell
|
||||
atlas migrate apply --dir file://ent/migrate/migrations --url mysql://root:pass@localhost:3306/db
|
||||
```
|
||||
Atlas fails with an error:
|
||||
```text
|
||||
You have a checksum error in your migration directory.
|
||||
This happens if you manually create or edit a migration file.
|
||||
Please check your migration files and run
|
||||
|
||||
'atlas migrate hash'
|
||||
|
||||
to re-hash the contents and resolve the error
|
||||
|
||||
Error: checksum mismatch
|
||||
```
|
||||
Atlas introduces the concept of [migration directory integrity](https://atlasgo.io/concepts/migration-directory-integrity)
|
||||
as a means to enforce a linear migration history. This way, if multiple developers work on the
|
||||
same project in parallel, they can be sure that their merged migration history is correct.
|
||||
|
||||
Let's re-hash the contents of our migration directory to resolve the error:
|
||||
|
||||
```shell
|
||||
atlas migrate hash --dir file://ent/migrate/migrations
|
||||
```
|
||||
|
||||
If we run `atlas migrate apply` again, we will see that the migration was successfully applied:
|
||||
```text
|
||||
atlas migrate apply --dir file://ent/migrate/migrations --url mysql://root:pass@localhost:3306/db
|
||||
```
|
||||
Atlas reports:
|
||||
```text
|
||||
Migrating to version 20221115102552 from 20221115101649 (1 migrations in total):
|
||||
|
||||
-- migrating version 20221115102552
|
||||
-> INSERT INTO `users` (`name`, `email`, `title`)
|
||||
VALUES ('Jerry Seinfeld', 'jerry@seinfeld.io', 'Mr.'),
|
||||
('George Costanza', 'george@costanza.io', 'Mr.')
|
||||
-- ok (9.077102ms)
|
||||
|
||||
-------------------------
|
||||
-- 19.857555ms
|
||||
-- 1 migrations
|
||||
-- 1 sql statements
|
||||
```
|
||||
|
||||
In the next section, we will learn how to automatically verify the safety of our
|
||||
schema migrations using Atlas's [Linting](https://atlasgo.io/versioned/lint) feature.
|
||||
264
doc/md/versioned/06-verifying-safety.mdx
Normal file
264
doc/md/versioned/06-verifying-safety.mdx
Normal file
@@ -0,0 +1,264 @@
|
||||
---
|
||||
title: Verifying migration safety
|
||||
id: verifying-safety
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
:::info Supporting repository
|
||||
|
||||
The change described in this section can be found in
|
||||
[PR #8](https://github.com/rotemtam/ent-versioned-migrations-demo/pull/8/files)
|
||||
in the supporting repository.
|
||||
|
||||
:::
|
||||
|
||||
## Verifying migration safety
|
||||
|
||||
As the database is a critical component of our application, we want to make sure that when we
|
||||
make changes to it, we don't break anything. Ill-planned migrations can cause data loss, application
|
||||
downtime and other issues. Atlas provides a mechanism to verify that a migration is safe to run.
|
||||
This mechanism is called [migration linting](https://atlasgo.io/versioned/lint) and in this section
|
||||
we will show how to use it to verify that our migration is safe to run.
|
||||
|
||||
## Linting the migration directory
|
||||
|
||||
To lint our migration directory we can use the `atlas migrate lint` command.
|
||||
To demonstrate this, let's see what happens if we decide to change the `Title` field in the `User`
|
||||
model from optional to required:
|
||||
|
||||
```diff
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.String("email").
|
||||
Unique(),
|
||||
-- field.String("title").
|
||||
-- Optional(),
|
||||
++ field.String("title"),
|
||||
}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
Let's re-run codegen:
|
||||
|
||||
```shell
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Next, let's automatically generate a new migration:
|
||||
|
||||
|
||||
<Tabs
|
||||
defaultValue="mysql"
|
||||
values={[
|
||||
{label: 'MySQL', value: 'mysql'},
|
||||
{label: 'MariaDB', value: 'maria'},
|
||||
{label: 'PostgreSQL', value: 'postgres'},
|
||||
{label: 'SQLite', value: 'sqlite'},
|
||||
]}>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```shell
|
||||
atlas migrate diff user_title_required \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://mysql/8/ent"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="maria">
|
||||
|
||||
```shell
|
||||
atlas migrate diff user_title_required \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://mariadb/latest/test"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="postgres">
|
||||
|
||||
```shell
|
||||
atlas migrate diff user_title_required \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://postgres/15/test?search_path=public"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sqlite">
|
||||
|
||||
```shell
|
||||
atlas migrate diff user_title_required \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "sqlite://file?mode=memory&_fk=1"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
A new migration file was created in the `ent/migrate/migrations` directory:
|
||||
|
||||
```sql title="ent/migrate/migrations/20221116051710_user_title_required.sql"
|
||||
-- modify "users" table
|
||||
ALTER TABLE `users` MODIFY COLUMN `title` varchar(255) NOT NULL;
|
||||
```
|
||||
|
||||
Now, let's lint the migration directory:
|
||||
|
||||
```shell
|
||||
atlas migrate lint --dev-url mysql://root:pass@localhost:3306/dev --dir file://ent/migrate/migrations --latest 1
|
||||
```
|
||||
|
||||
Atlas reports that the migration may be unsafe to run:
|
||||
|
||||
```text
|
||||
20221116051710_user_title_required.sql: data dependent changes detected:
|
||||
|
||||
L2: Modifying nullable column "title" to non-nullable might fail in case it contains NULL values
|
||||
```
|
||||
|
||||
Atlas detected that the migration is unsafe to run and prevented us from running it.
|
||||
In this case, Atlas classified this change as a data dependent change. This means that the change
|
||||
might fail, depending on the concrete data in the database.
|
||||
|
||||
Atlas can detect many more types of issues, for a full list, see the [Atlas documentation](https://atlasgo.io/lint/analyzers).
|
||||
|
||||
## Linting our migration directory in CI
|
||||
|
||||
In the previous section, we saw how to lint our migration directory locally. In this section,
|
||||
we will see how to lint our migration directory in CI. This way, we can make sure that our migration
|
||||
history is safe to run before we merge it to the main branch.
|
||||
|
||||
[GitHub Actions](https://github.com/features/actions) is a popular CI/CD
|
||||
product from GitHub. With GitHub Actions, users can easily define workflows
|
||||
that are triggered in various lifecycle events related to a Git repository.
|
||||
For example, many teams configure GitHub actions to run all unit tests in
|
||||
a repository on each change that is committed to a repository.
|
||||
|
||||
One of the powerful features of GitHub Actions is its extensibility: it is
|
||||
very easy to package a piece of functionality as a module (called an "action")
|
||||
that can later be reused by many projects.
|
||||
|
||||
Teams using GitHub that wish to ensure all changes to their database schema are safe
|
||||
can use the [`atlas-action`](https://github.com/ariga/atlas-action) GitHub Action.
|
||||
|
||||
This action is used for [linting migration directories](/versioned/lint)
|
||||
using the `atlas migrate lint` command. This command validates and analyzes the contents
|
||||
of migration directories and generates insights and diagnostics on the selected changes:
|
||||
|
||||
* Ensure the migration history can be replayed from any point in time.
|
||||
* Protect from unexpected history changes when concurrent migrations are written to the migration directory by
|
||||
multiple team members.
|
||||
* Detect whether destructive or irreversible changes have been made or whether they are dependent on tables'
|
||||
contents and can cause a migration failure.
|
||||
|
||||
## Usage
|
||||
|
||||
Add `.github/workflows/atlas-ci.yaml` to your repo with the following contents:
|
||||
|
||||
```yaml
|
||||
name: Atlas CI
|
||||
on:
|
||||
# Run whenever code is changed in the master branch,
|
||||
# change this to your root branch.
|
||||
push:
|
||||
branches:
|
||||
- master
|
||||
pull_request:
|
||||
paths:
|
||||
- 'ent/migrate/migrations/*'
|
||||
jobs:
|
||||
lint:
|
||||
services:
|
||||
# Spin up a mysql:8.0.29 container to be used as the dev-database for analysis.
|
||||
mysql:
|
||||
image: mysql:8.0.29
|
||||
env:
|
||||
MYSQL_ROOT_PASSWORD: pass
|
||||
MYSQL_DATABASE: dev
|
||||
ports:
|
||||
- "3306:3306"
|
||||
options: >-
|
||||
--health-cmd "mysqladmin ping -ppass"
|
||||
--health-interval 10s
|
||||
--health-start-period 10s
|
||||
--health-timeout 5s
|
||||
--health-retries 10
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3.0.1
|
||||
with:
|
||||
fetch-depth: 0 # Mandatory unless "latest" is set below.
|
||||
- uses: ariga/atlas-action@v0
|
||||
with:
|
||||
dir: ent/migrate/migrations
|
||||
dev-url: mysql://root:pass@localhost:3306/dev
|
||||
```
|
||||
Now, whenever we make a pull request with a potentially unsafe migration, the Atlas
|
||||
GitHub action will run and report the linting results. For example, for our data-dependent change:
|
||||
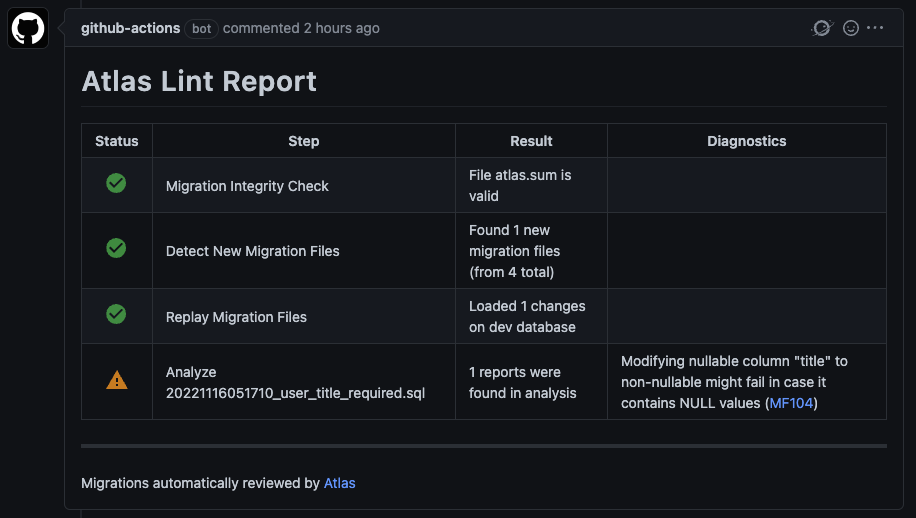
|
||||
|
||||
For more in depth documentation, see the [atlas-action](https://atlasgo.io/integrations/github-actions)
|
||||
docs on the Atlas website.
|
||||
|
||||
Let's fix the issue by back-filling the `title` column. Add the following
|
||||
statement to the migration file:
|
||||
|
||||
```sql title="ent/migrate/migrations/20221116051710_user_title_required.sql"
|
||||
-- modify "users" table
|
||||
UPDATE `users` SET `title` = "" WHERE `title` IS NULL;
|
||||
|
||||
ALTER TABLE `users` MODIFY COLUMN `title` varchar(255) NOT NULL;
|
||||
```
|
||||
|
||||
Re-hash the migration directory:
|
||||
|
||||
```shell
|
||||
atlas migrate hash --dir file://ent/migrate/migrations
|
||||
```
|
||||
|
||||
Re-running `atlas migrate lint`, we can see that the migration directory doesn't
|
||||
contain any unsafe changes:
|
||||
|
||||
```text
|
||||
atlas migrate lint --dev-url mysql://root:pass@localhost:3306/dev --dir file://ent/migrate/migrations --latest 1
|
||||
```
|
||||
|
||||
Because no issues are found, the command will exit with a zero exit code and no output.
|
||||
|
||||
When we commit this change to GitHub, the Atlas GitHub action will run and report that
|
||||
the issue is resolved:
|
||||
|
||||

|
||||
|
||||
## Conclusion
|
||||
|
||||
In this section, we saw how to use Atlas to verify that our migration is safe to run both
|
||||
locally and in CI.
|
||||
|
||||
This wraps up our tutorial on how to upgrade your Ent project from
|
||||
automatic migration to versioned migrations. To recap, we learned how to:
|
||||
|
||||
* Enable the versioned migrations feature-flag
|
||||
* Create a script to automatically plan migrations based on our desired Ent schema
|
||||
* Upgrade our production database to use versioned migrations with Atlas
|
||||
* Plan custom migrations for our project
|
||||
* Verify migrations safely using `atlas migrate lint`
|
||||
|
||||
In the next steps
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
|
||||
220
doc/md/versioned/07-programmatically.mdx
Normal file
220
doc/md/versioned/07-programmatically.mdx
Normal file
@@ -0,0 +1,220 @@
|
||||
---
|
||||
id: programmatically
|
||||
title: "Appendix: programmatic planning"
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
In the previous sections, we saw how to use the Atlas CLI to generate migration files. However, we can also
|
||||
generate these files programmatically. In this section we will review how to write Go code that can be used for
|
||||
automatically planning migration files.
|
||||
|
||||
## 1. Enable the versioned migration feature flag
|
||||
|
||||
:::info Supporting repository
|
||||
|
||||
The change described in this section can be found in PR [#2](https://github.com/rotemtam/ent-versioned-migrations-demo/pull/2/files)
|
||||
in the supporting repository.
|
||||
|
||||
:::
|
||||
|
||||
The first step is to enable the versioned migration feature by passing in the `sql/versioned-migration` feature flag.
|
||||
Depending on how you execute the Ent code generator, you have to use one of the two options:
|
||||
|
||||
<Tabs
|
||||
defaultValue="ent"
|
||||
values={[
|
||||
{label: 'Using Ent CLI', value: 'ent'},
|
||||
{label: 'Using the entc package', value: 'entc'},
|
||||
]}>
|
||||
<TabItem value="ent">
|
||||
|
||||
If you are using the default go generate configuration, simply add the `--feature sql/versioned-migration` to
|
||||
the `ent/generate.go` file as follows:
|
||||
|
||||
```go
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entgo.io/ent/cmd/ent generate --feature sql/versioned-migration ./schema
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="entc">
|
||||
|
||||
If you are using the code generation package (e.g. if you are using an Ent extension like `entgql`),
|
||||
add the feature flag as follows:
|
||||
|
||||
```go
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
)
|
||||
|
||||
func main() {
|
||||
err := entc.Generate("./schema", &gen.Config{
|
||||
//highlight-next-line
|
||||
Features: []gen.Feature{gen.FeatureVersionedMigration},
|
||||
})
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
Next, re-run code-generation:
|
||||
|
||||
```shell
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
After running the code-generation, you should see the following
|
||||
[methods added](https://github.com/rotemtam/ent-versioned-migrations-demo/commit/e724fa32330d920fd405b9785fcfece2a46ea56c#diff-370235e5107bbdd35861063f3beff1507723ebdda6e29a39cdde1f1a944594d8)
|
||||
to `ent/migrate/migrate.go`:
|
||||
* `Diff`
|
||||
* `NamedDiff`
|
||||
|
||||
These methods are used to compare the state read from a database connection or a migration directory with the state defined
|
||||
by the Ent schema.
|
||||
|
||||
## 2. Automatic Migration planning script
|
||||
|
||||
:::info Supporting repository
|
||||
|
||||
The change described in this section can be found in PR [#4](https://github.com/rotemtam/ent-versioned-migrations-demo/pull/4/files)
|
||||
in the supporting repository.
|
||||
|
||||
:::
|
||||
|
||||
### Dev database
|
||||
|
||||
To be able to plan accurate and consistent migration files, Atlas introduces the
|
||||
concept of a [Dev database](https://atlasgo.io/concepts/dev-database), a temporary
|
||||
database which is used to simulate the state of the database after different changes.
|
||||
Therefore, to use Atlas to automatically plan migrations, we need to supply a connection
|
||||
string to such a database to our migration planning script. Such a database is most commonly
|
||||
spun up using a local Docker container. Let's do this now by running the following command:
|
||||
|
||||
```shell
|
||||
docker run --rm --name atlas-db-dev -d -p 3306:3306 -e MYSQL_DATABASE=dev -e MYSQL_ROOT_PASSWORD=pass mysql:8
|
||||
```
|
||||
|
||||
Using the Dev database we have just configured, we can write a script that will use Atlas to plan
|
||||
migration files for us. Let's create a new file called `main.go` in the `ent/migrate` directory
|
||||
of our project:
|
||||
|
||||
```go title=ent/migrate/main.go
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"os"
|
||||
|
||||
// highlight-next-line
|
||||
"<project>/ent/migrate"
|
||||
|
||||
atlas "ariga.io/atlas/sql/migrate"
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
const (
|
||||
dir = "ent/migrate/migrations"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ctx := context.Background()
|
||||
// Create a local migration directory able to understand Atlas migration file format for replay.
|
||||
if err := os.MkdirAll(dir, 0755); err != nil {
|
||||
log.Fatalf("creating migration directory: %v", err)
|
||||
}
|
||||
dir, err := atlas.NewLocalDir(dir)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating atlas migration directory: %v", err)
|
||||
}
|
||||
// Migrate diff options.
|
||||
opts := []schema.MigrateOption{
|
||||
schema.WithDir(dir), // provide migration directory
|
||||
schema.WithMigrationMode(schema.ModeReplay), // provide migration mode
|
||||
schema.WithDialect(dialect.MySQL), // Ent dialect to use
|
||||
schema.WithFormatter(atlas.DefaultFormatter),
|
||||
}
|
||||
if len(os.Args) != 2 {
|
||||
log.Fatalln("migration name is required. Use: 'go run -mod=mod ent/migrate/main.go <name>'")
|
||||
}
|
||||
// Generate migrations using Atlas support for MySQL (note the Ent dialect option passed above).
|
||||
//highlight-next-line
|
||||
err = migrate.NamedDiff(ctx, "mysql://root:pass@localhost:3306/dev", os.Args[1], opts...)
|
||||
if err != nil {
|
||||
log.Fatalf("failed generating migration file: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
:::info
|
||||
|
||||
Notice that you need to make some modifications to the script above in the highlighted lines.
|
||||
Edit the import path of the `migrate` package to match your project and to supply the connection
|
||||
string to your Dev database.
|
||||
|
||||
:::
|
||||
|
||||
To run the script, first create a `migrations` directory in the `ent/migrate` directory of your
|
||||
project:
|
||||
|
||||
```text
|
||||
mkdir ent/migrate/migrations
|
||||
```
|
||||
|
||||
Then, run the script to create the initial migration file for your project:
|
||||
|
||||
```shell
|
||||
go run -mod=mod ent/migrate/main.go initial
|
||||
```
|
||||
Notice that `initial` here is just a label for the migration file. You can use any name you want.
|
||||
|
||||
Observe that after running the script, two new files were created in the `ent/migrate/migrations`
|
||||
directory. The first file is named `atlas.sum`, which is a checksum file used by Atlas to enforce
|
||||
a linear history of migrations:
|
||||
|
||||
```text title=ent/migrate/migrations/atlas.sum
|
||||
h1:Dt6N5dIebSto365ZEyIqiBKDqp4INvd7xijLIokqWqA=
|
||||
20221114165732_initialize.sql h1:/33+7ubMlxuTkW6Ry55HeGEZQ58JqrzaAl2x1TmUTdE=
|
||||
```
|
||||
|
||||
The second file is the actual migration file, which is named after the label we passed to the
|
||||
script:
|
||||
|
||||
```sql title=ent/migrate/migrations/20221114165732_initial.sql
|
||||
-- create "users" table
|
||||
CREATE TABLE `users` (`id` bigint NOT NULL AUTO_INCREMENT, `name` varchar(255) NOT NULL, `email` varchar(255) NOT NULL, PRIMARY KEY (`id`), UNIQUE INDEX `email` (`email`)) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
-- create "blogs" table
|
||||
CREATE TABLE `blogs` (`id` bigint NOT NULL AUTO_INCREMENT, `title` varchar(255) NOT NULL, `body` longtext NOT NULL, `created_at` timestamp NOT NULL, `user_blog_posts` bigint NULL, PRIMARY KEY (`id`), CONSTRAINT `blogs_users_blog_posts` FOREIGN KEY (`user_blog_posts`) REFERENCES `users` (`id`) ON DELETE SET NULL) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
```
|
||||
|
||||
## Other migration tools
|
||||
|
||||
Atlas integrates very well with Ent, but it is not the only migration tool that can be used
|
||||
to manage database schemas in Ent projects. The following is a list of other migration tools
|
||||
that are supported:
|
||||
|
||||
* [Goose](https://github.com/pressly/goose)
|
||||
* [Golang Migrate](https://github.com/golang-migrate/migrate)
|
||||
* [Flyway](https://flywaydb.org)
|
||||
* [Liquibase](https://www.liquibase.org)
|
||||
* [dbmate](https://github.com/amacneil/dbmate)
|
||||
|
||||
To learn more about how to use these tools with Ent, see the [docs](https://entgo.io/docs/versioned-migrations#create-a-migration-files-generator) on this subject.
|
||||
79
doc/md/writing-docs.md
Normal file
79
doc/md/writing-docs.md
Normal file
@@ -0,0 +1,79 @@
|
||||
---
|
||||
id: writing-docs
|
||||
title: Writing Docs
|
||||
---
|
||||
|
||||
This document contains guidelines for contributing changes to the Ent documentation website.
|
||||
|
||||
The Ent documentation website is generated from the project's main [GitHub repo](https://github.com/ent/ent).
|
||||
|
||||
Follow this short guide to contribute documentation improvements and additions:
|
||||
|
||||
### Setting Up
|
||||
|
||||
1\. [Fork and clone locally](https://docs.github.com/en/github/getting-started-with-github/quickstart/fork-a-repo) the
|
||||
[main repository](https://github.com/ent/ent).
|
||||
|
||||
2\. The documentation site uses [Docusaurus](https://docusaurus.io/). To run it you will need [Node.js installed](https://nodejs.org/en/).
|
||||
|
||||
3\. Install the dependencies:
|
||||
```shell
|
||||
cd doc/website && npm install
|
||||
```
|
||||
|
||||
4\. Run the website in development mode:
|
||||
|
||||
```shell
|
||||
cd doc/website && npm start
|
||||
```
|
||||
|
||||
5\. Open you browser at [http://localhost:3000](http://localhost:3000).
|
||||
|
||||
### General Guidelines
|
||||
|
||||
* Documentation files are located in `doc/md`, they are [Markdown-formatted](https://en.wikipedia.org/wiki/Markdown)
|
||||
with "front-matter" style annotations at the top. [Read more](https://docusaurus.io/docs/docs-introduction) about
|
||||
Docusaurus's document format.
|
||||
* Ent uses [Golang CommitMessage](https://github.com/golang/go/wiki/CommitMessage) formats to keep the repository's
|
||||
history nice and readable. As such, please use a commit message such as:
|
||||
```text
|
||||
doc/md: adding a guide on contribution of docs to ent
|
||||
```
|
||||
|
||||
### Adding New Documents
|
||||
|
||||
1\. Add a new Markdown file in the `doc/md` directory, for example `doc/md/writing-docs.md`.
|
||||
|
||||
2\. The file should be formatted as such:
|
||||
|
||||
```markdown
|
||||
---
|
||||
id: writing-docs
|
||||
title: Writing Docs
|
||||
---
|
||||
...
|
||||
```
|
||||
Where `id` should be a unique identifier for the document, should be the same as the filename without the `.md` suffix,
|
||||
and `title` is the title of the document as it will appear in the page itself and any navigation element on the site.
|
||||
|
||||
3\. If you want the page to appear in the documentation website's sidebar, add its `id` to `website/sidebars.js`, for example:
|
||||
```diff
|
||||
{
|
||||
type: 'category',
|
||||
label: 'Misc',
|
||||
items: [
|
||||
'templates',
|
||||
'graphql',
|
||||
'sql-integration',
|
||||
'testing',
|
||||
'faq',
|
||||
'generating-ent-schemas',
|
||||
'feature-flags',
|
||||
'translations',
|
||||
'contributors',
|
||||
+ 'writing-docs',
|
||||
'slack'
|
||||
],
|
||||
collapsed: false,
|
||||
},
|
||||
```
|
||||
Reference in New Issue
Block a user