snapshot of https://github.com/ent/ent.git (master, 2026-09-15; blobs > 131072B omitted)
This commit is contained in:
 upstream-mirror
20
doc/website/.gitignore
vendored
Normal file
20
doc/website/.gitignore
vendored
Normal file
@@ -0,0 +1,20 @@
|
||||
# dependencies
|
||||
/node_modules
|
||||
|
||||
# production
|
||||
/build
|
||||
|
||||
# generated files
|
||||
.docusaurus
|
||||
.cache-loader
|
||||
|
||||
# misc
|
||||
.DS_Store
|
||||
.env.local
|
||||
.env.development.local
|
||||
.env.test.local
|
||||
.env.production.local
|
||||
|
||||
npm-debug.log*
|
||||
yarn-debug.log*
|
||||
yarn-error.log*
|
||||
50
doc/website/blog/2019-10-03-introducing-ent.md
Normal file
50
doc/website/blog/2019-10-03-introducing-ent.md
Normal file
@@ -0,0 +1,50 @@
|
||||
---
|
||||
title: Introducing ent
|
||||
author: Ariel Mashraki
|
||||
authorURL: "https://github.com/a8m"
|
||||
authorImageURL: "https://avatars0.githubusercontent.com/u/7413593"
|
||||
authorTwitter: arielmashraki
|
||||
---
|
||||
## The state of Go in Facebook Connectivity Tel Aviv
|
||||
20 months ago, I joined Facebook Connectivity (FBC) team in Tel Aviv after ~5 years
|
||||
of programming in Go and embedding it in a few companies.
|
||||
I joined a team that was working on a new project and we needed to choose a language
|
||||
for this mission. We compared a few languages and decided to go with Go.
|
||||
|
||||
Since then, Go continued to spread across other FBC projects and became a big success
|
||||
with around 15 Go engineers in Tel Aviv alone. **New services are now written in Go**.
|
||||
|
||||
## The motivation for writing a new ORM in Go
|
||||
|
||||
Most of my work in my 5 years before Facebook was on infra tooling and micro-services without
|
||||
too much data-model work. A service that was needed to do a little amount of work with an SQL
|
||||
database used one of the existing open-source solutions, but one that had worked with a
|
||||
complicated data model was written in a different language with a robust ORM. For example,
|
||||
Python with SQLAlchemy.
|
||||
|
||||
At Facebook we like to think about our data-model in graph concepts. We've had a good experience
|
||||
with this model internally.
|
||||
The lack of a proper Graph-based ORM for Go, led us to write one here with the following principles:
|
||||
|
||||
- **Schema As Code** - defining types, relations and constraints should be in Go code (not struct
|
||||
tags), and should be validated using a CLI tool. We have good experience with a similar tool
|
||||
internally at Facebook.
|
||||
- **Statically typed and explicit API** using codegen - API with `interface{}`s everywhere affects
|
||||
developers efficiency; especially project newbies.
|
||||
- **Queries, aggregations and graph traversals** should be simple - developers don’t want to deal
|
||||
with raw SQL queries nor SQL terms.
|
||||
- **Predicates should be statically typed**. No strings everywhere.
|
||||
- Full support for `context.Context` - This helps us to get full visibility in our traces and logs
|
||||
systems, and it’s important for other features like cancellation.
|
||||
- **Storage agnostic** - we tried to keep the storage layer dynamic using codegen templates,
|
||||
since the development initially started on Gremlin (AWS Neptune) and switched later to MySQL.
|
||||
|
||||
## Open-sourcing ent
|
||||
|
||||
**ent** is an entity framework (ORM) for Go, built with the principles described above.
|
||||
**ent** makes it possible to define any data model or graph-structure in Go code easily; The
|
||||
schema configuration is verified by **entc** (the ent codegen) that generates an idiomatic and
|
||||
statically-typed API that keeps Go developers productive and happy.
|
||||
It supports MySQL, MariaDB, PostgreSQL, SQLite, and Gremlin-based graph databases.
|
||||
|
||||
We’re open-sourcing **ent** today, and invite you to get started → [entgo.io/docs/getting-started](/docs/getting-started).
|
||||
215
doc/website/blog/2021-03-12-announcing-edge-field-support.md
Normal file
215
doc/website/blog/2021-03-12-announcing-edge-field-support.md
Normal file
@@ -0,0 +1,215 @@
|
||||
---
|
||||
title: Announcing Edge-field Support in v0.7.0
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
---
|
||||
Over the past few months, there has been much discussion in the Ent project [issues](https://github.com/ent/ent/issues) about adding support for the retrieval of the foreign key field when retrieving entities with One-to-One or One-to-Many edges. We are happy to announce that as of [v0.7.0](https://github.com/ent/ent/releases/tag/v0.7.0) ent supports this feature.
|
||||
|
||||
### Before Edge-field Support
|
||||
|
||||
Prior to merging this branch, a user that wanted to retrieve the foreign-key field for an entity needed to use eager-loading. Suppose our schema looked like this:
|
||||
|
||||
```go
|
||||
// ent/schema/user.go:
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
Unique().
|
||||
NotEmpty(),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the User.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("pets", Pet.Type).
|
||||
Ref("owner"),
|
||||
}
|
||||
}
|
||||
|
||||
// ent/schema/pet.go
|
||||
|
||||
// Pet holds the schema definition for the Pet entity.
|
||||
type Pet struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Pet.
|
||||
func (Pet) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
NotEmpty(),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Pet.
|
||||
func (Pet) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("owner", User.Type).
|
||||
Unique().
|
||||
Required(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The schema describes two related entities: `User` and `Pet`, with a One-to-Many edge between them: a user can own many pets and a pet can have one owner.
|
||||
|
||||
When retrieving pets from the data storage, it is common for developers to want to access the foreign-key field on the pet. However, because this field is created implicitly from the `owner` edge it was automatically accessible when retrieving an entity. To retrieve this from the storage a developer needed to do something like:
|
||||
|
||||
```go
|
||||
func Test(t *testing.T) {
|
||||
ctx := context.Background()
|
||||
c := enttest.Open(t, dialect.SQLite, "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
defer c.Close()
|
||||
|
||||
// Create the User
|
||||
u := c.User.Create().
|
||||
SetUserName("rotem").
|
||||
SaveX(ctx)
|
||||
|
||||
// Create the Pet
|
||||
p := c.Pet.
|
||||
Create().
|
||||
SetOwner(u). // Associate with the user
|
||||
SetName("donut").
|
||||
SaveX(ctx)
|
||||
|
||||
petWithOwnerId := c.Pet.Query().
|
||||
Where(pet.ID(p.ID)).
|
||||
WithOwner(func(query *ent.UserQuery) {
|
||||
query.Select(user.FieldID)
|
||||
}).
|
||||
OnlyX(ctx)
|
||||
fmt.Println(petWithOwnerId.Edges.Owner.ID)
|
||||
// Output: 1
|
||||
}
|
||||
```
|
||||
|
||||
Aside from being very verbose, retrieving the pet with the owner this way was inefficient in-terms of database queries. If we execute the query with the `.Debug()` we can see the DB queries ent generates to satisfy this call:
|
||||
|
||||
```sql
|
||||
SELECT DISTINCT `pets`.`id`, `pets`.`name`, `pets`.`pet_owner` FROM `pets` WHERE `pets`.`id` = ? LIMIT 2
|
||||
SELECT DISTINCT `users`.`id` FROM `users` WHERE `users`.`id` IN (?)
|
||||
```
|
||||
|
||||
In this example, Ent first retrieves the Pet with an ID of `1`, then redundantly fetches the `id` field from the `users` table for users with an ID of `1`.
|
||||
|
||||
### With Edge-field Support
|
||||
|
||||
[Edge-field support](https://entgo.io/docs/schema-edges/#edge-field) greatly simplifies and improves the efficiency of this flow. With this feature, developers can define the foreign key field as part of the schemas `Fields()`, and by using the `.Field(..)` modifier on the edge definition instruct Ent to expose and map the foreign column to this field. So, in our example schema, we would modify it to be:
|
||||
|
||||
```go
|
||||
// user.go stays the same
|
||||
|
||||
// pet.go
|
||||
// Fields of the Pet.
|
||||
func (Pet) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
NotEmpty(),
|
||||
field.Int("owner_id"), // <-- explicitly add the field we want to contain the FK
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Pet.
|
||||
func (Pet) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("owner", User.Type).
|
||||
Field("owner_id"). // <-- tell ent which field holds the reference to the owner
|
||||
Unique().
|
||||
Required(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
In order to update our client code we need to re-run code generation:
|
||||
|
||||
```sql
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
We can now modify our query to be much simpler:
|
||||
|
||||
```go
|
||||
func Test(t *testing.T) {
|
||||
ctx := context.Background()
|
||||
c := enttest.Open(t, dialect.SQLite, "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
defer c.Close()
|
||||
|
||||
u := c.User.Create().
|
||||
SetUserName("rotem").
|
||||
SaveX(ctx)
|
||||
|
||||
p := c.Pet.Create().
|
||||
SetOwner(u).
|
||||
SetName("donut").
|
||||
SaveX(ctx)
|
||||
|
||||
petWithOwnerId := c.Pet.GetX(ctx, p.ID) // <-- Simply retrieve the Pet
|
||||
|
||||
fmt.Println(petWithOwnerId.OwnerID)
|
||||
// Output: 1
|
||||
}
|
||||
```
|
||||
|
||||
Running with the `.Debug()` modifier we can see that the DB queries make more sense now:
|
||||
|
||||
```sql
|
||||
SELECT DISTINCT `pets`.`id`, `pets`.`name`, `pets`.`owner_id` FROM `pets` WHERE `pets`.`id` = ? LIMIT 2
|
||||
```
|
||||
|
||||
Hooray 🎉!
|
||||
|
||||
### Migrating Existing Schemas to Edge Fields
|
||||
|
||||
If you are already using Ent with an existing schema, you may already have O2M relations whose foreign-key columns already exist in your database. Depending on how you configured your schema, chances are that they may be stored in a column by a different name than the field you are now adding. For instance, you want to create an `owner_id` field, but Ent auto-created the column foreign-key column as `pet_owner`.
|
||||
|
||||
To check what column name Ent is using for this field you can look in the `./ent/migrate/schema.go` file:
|
||||
|
||||
```go
|
||||
PetsColumns = []*schema.Column{
|
||||
{Name: "id", Type: field.TypeInt, Increment: true},
|
||||
{Name: "name", Type: field.TypeString},
|
||||
{Name: "pet_owner", Type: field.TypeInt, Nullable: true}, // <-- this is our FK
|
||||
}
|
||||
```
|
||||
|
||||
To allow for a smooth migration, you must explicitly tell Ent to keep using the existing column name. You can do this by using the `StorageKey` modifier (either on the field or on the edge). For example:
|
||||
|
||||
```go
|
||||
// In schema/pet.go:
|
||||
|
||||
// Fields of the Pet.
|
||||
func (Pet) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
NotEmpty(),
|
||||
field.Int("owner_id").
|
||||
StorageKey("pet_owner"), // <-- explicitly set the column name
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
In the near future we plan to implement Schema Versioning, which will store the history of schema changes alongside the code. Having this information will allow ent to support such migrations in an automatic and predictable way.
|
||||
|
||||
### Wrapping Up
|
||||
|
||||
Edge-field support is readily available and can be installed by `go get -u entgo.io/ent@v0.7.0`.
|
||||
|
||||
Many thanks 🙏 to all the good people who took the time to give feedback and helped design this feature properly: [Alex Snast](https://github.com/alexsn), [Ruben de Vries](https://github.com/rubensayshi), [Marwan Sulaiman](https://github.com/marwan-at-work), [Andy Day](https://github.com/adayNU), [Sebastian Fekete](https://github.com/aight8) and [Joe Harvey](https://github.com/errorhandler).
|
||||
|
||||
### For more Ent news and updates:
|
||||
|
||||
- Follow us on [twitter.com/entgo_io](https://twitter.com/entgo_io)
|
||||
- Subscribe to our [newsletter](https://entgo.substack.com/)
|
||||
- Join us on #ent on the [Gophers slack](https://app.slack.com/client/T029RQSE6/C01FMSQDT53)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
475
doc/website/blog/2021-03-18-generating-a-grpc-server-with-ent.md
Normal file
475
doc/website/blog/2021-03-18-generating-a-grpc-server-with-ent.md
Normal file
@@ -0,0 +1,475 @@
|
||||
---
|
||||
title: Generate a fully-working Go gRPC server in two minutes with Ent
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
---
|
||||

|
||||
## Introduction
|
||||
Having entity schemas defined in a central, language-neutral format
|
||||
has [many benefits](https://rotemtam.com/2019/06/28/the-statically-typed-org/) as the scale of software engineering organizations increase. To do this, many organizations use [Protocol Buffers](https://developers.google.com/protocol-buffers) as their [interface definition language](https://en.wikipedia.org/wiki/Interface_description_language) (IDL). In addition, gRPC,
|
||||
a Protobuf-based RPC framework modeled after Google's internal [Stubby](https://grpc.io/blog/principles/#motivation) is becoming increasingly popular due to its efficiency and code-generation capabilities.
|
||||
|
||||
Being an IDL, gRPC does not prescribe any specific guidelines on implementing the data access layer so implementations vary greatly. Ent is a natural candidate for building the data access layer in any Go application and so there is great potential in integrating the two technologies together.
|
||||
|
||||
Today we announce an experimental version of `entproto`, a Go package, and a command-line tool to add Protobuf and gRPC support for ent users. With `entproto`, developers can set up a fully working CRUD gRPC server in a few minutes. In this post, we will show exactly how to do just that.
|
||||
|
||||
## Setting Up
|
||||
The final version of this tutorial is available on [GitHub](https://github.com/rotemtam/ent-grpc-example), you can clone it if you prefer following along that way.
|
||||
|
||||
Let's start by initializing a new Go module for our project:
|
||||
|
||||
```console
|
||||
mkdir ent-grpc-example
|
||||
cd ent-grpc-example
|
||||
go mod init ent-grpc-example
|
||||
```
|
||||
|
||||
Next we use `go run` to invoke the ent code generator to initialize a schema:
|
||||
|
||||
```console
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new User
|
||||
```
|
||||
|
||||
Our directory should now look like:
|
||||
|
||||
```console
|
||||
.
|
||||
├── ent
|
||||
│ ├── generate.go
|
||||
│ └── schema
|
||||
│ └── user.go
|
||||
├── go.mod
|
||||
└── go.sum
|
||||
```
|
||||
|
||||
Next, let's add the `entproto` package to our project:
|
||||
|
||||
```console
|
||||
go get -u entgo.io/contrib/entproto
|
||||
```
|
||||
|
||||
Next, we will define the schema for the `User` entity. Open `ent/schema/user.go` and edit:
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema"
|
||||
)
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
Unique(),
|
||||
field.String("email_address").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
In this step, we added two unique fields to our `User` entity: `name` and `email_address`. The `ent.Schema` is just the definition of the schema, to create usable production code from it we need to run Ent's code generation tool on it. Run:
|
||||
|
||||
```console
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Notice the a bunch of new files were created from our schema definition now:
|
||||
|
||||
```console
|
||||
├── ent
|
||||
│ ├── client.go
|
||||
│ ├── config.go
|
||||
// .... many more
|
||||
│ ├── user
|
||||
│ ├── user.go
|
||||
│ ├── user_create.go
|
||||
│ ├── user_delete.go
|
||||
│ ├── user_query.go
|
||||
│ └── user_update.go
|
||||
├── go.mod
|
||||
└── go.sum
|
||||
```
|
||||
|
||||
At this point, we can open a connection to a database, run a migration to create the `users` table, and start reading and writing data to it. This is covered on the [Setup Tutorial](https://entgo.io/docs/tutorial-setup/), so let's cut to the chase and learn about generating Protobuf definitions and gRPC servers from our schema.
|
||||
|
||||
## Generating Go Protobufs with `entproto`
|
||||
|
||||
As ent and Protobuf schemas are not identical, we must supply some annotations on our schema to help `entproto` figure out exactly how to generate Protobuf definitions (called "Messages" in protobuf lingo).
|
||||
|
||||
The first thing we need to do is to add an `entproto.Message()` annotation. This is our opt-in to Protobuf schema generation, we don't necessarily want to generate proto messages or gRPC service definitions from *all* of our schema entities, and this annotation gives us that control. To add it, append to `ent/schema/user.go`:
|
||||
|
||||
```go
|
||||
func (User) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entproto.Message(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Next, we need to annotate each field and assign it a field number. Recall that when [defining a protobuf message type](https://developers.google.com/protocol-buffers/docs/proto3#simple), each field must be assigned a unique number. To do that, we add an `entproto.Field` annotation on each field. Update the `Fields` in `ent/schema/user.go`:
|
||||
|
||||
```go
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
Unique().
|
||||
Annotations(
|
||||
entproto.Field(2),
|
||||
),
|
||||
field.String("email_address").
|
||||
Unique().
|
||||
Annotations(
|
||||
entproto.Field(3),
|
||||
),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Notice that we did not start our field numbers from 1, this is because `ent` implicitly creates the `ID` field for the entity, and that field is automatically assigned the number 1. We can now generate our protobuf message type definitions. To do that, we will add to `ent/generate.go` a `go:generate` directive that invokes the `entproto` command-line tool. It should now look like this:
|
||||
|
||||
```go
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entgo.io/ent/cmd/ent generate ./schema
|
||||
//go:generate go run -mod=mod entgo.io/contrib/entproto/cmd/entproto -path ./schema
|
||||
```
|
||||
|
||||
Let's re-generate our code:
|
||||
|
||||
```console
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Observe that a new directory was created which will contain all protobuf related generated code: `ent/proto`. It now contains:
|
||||
|
||||
```console
|
||||
ent/proto
|
||||
└── entpb
|
||||
├── entpb.proto
|
||||
└── generate.go
|
||||
```
|
||||
|
||||
Two files were created. Let's look at their contents:
|
||||
|
||||
```protobuf
|
||||
// Code generated by entproto. DO NOT EDIT.
|
||||
syntax = "proto3";
|
||||
|
||||
package entpb;
|
||||
|
||||
option go_package = "ent-grpc-example/ent/proto/entpb";
|
||||
|
||||
message User {
|
||||
int32 id = 1;
|
||||
|
||||
string user_name = 2;
|
||||
|
||||
string email_address = 3;
|
||||
}
|
||||
```
|
||||
|
||||
Nice! A new `.proto` file containing a message type definition that maps to our `User` schema was created!
|
||||
|
||||
```go
|
||||
package entpb
|
||||
//go:generate protoc -I=.. --go_out=.. --go-grpc_out=.. --go_opt=paths=source_relative --go-grpc_opt=paths=source_relative --entgrpc_out=.. --entgrpc_opt=paths=source_relative,schema_path=../../schema entpb/entpb.proto
|
||||
```
|
||||
|
||||
A new `generate.go` file was created with an invocation to `protoc`, the protobuf code generator instructing it how to generate Go code from our `.proto` file. For this command to work, we must first install `protoc` as well as 3 protobuf plugins: `protoc-gen-go` (which generates Go Protobuf structs), `protoc-gen-go-grpc` (which generates Go gRPC service interfaces and clients), and `protoc-gen-entgrpc` (which generates an implementation of the service interface). If you do not have these installed, please follow these directions:
|
||||
|
||||
- [protoc installation](https://grpc.io/docs/protoc-installation/)
|
||||
- [protoc-gen-go + protoc-gen-go-grpc installation](https://grpc.io/docs/languages/go/quickstart/)
|
||||
- Run `go get -u entgo.io/contrib/entproto/cmd/protoc-gen-entgrpc` to install `protoc-gen-entgrpc`
|
||||
|
||||
After installing these dependencies, we can re-run code-generation:
|
||||
|
||||
```console
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Observe that a new file named `ent/proto/entpb/entpb.pb.go` was created which contains the generated Go structs for our entities.
|
||||
|
||||
Let's write a test that uses it to make sure everything is wired correctly. Create a new file named `pb_test.go` and write:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"testing"
|
||||
|
||||
"ent-grpc-example/ent/proto/entpb"
|
||||
)
|
||||
|
||||
func TestUserProto(t *testing.T) {
|
||||
user := entpb.User{
|
||||
Name: "rotemtam",
|
||||
EmailAddress: "rotemtam@example.com",
|
||||
}
|
||||
if user.GetName() != "rotemtam" {
|
||||
t.Fatal("expected user name to be rotemtam")
|
||||
}
|
||||
if user.GetEmailAddress() != "rotemtam@example.com" {
|
||||
t.Fatal("expected email address to be rotemtam@example.com")
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
To run it:
|
||||
|
||||
```console
|
||||
go get -u./... # install deps of the generated package
|
||||
go test ./...
|
||||
```
|
||||
|
||||
Hooray! The test passes. We have successfully generated working Go Protobuf structs from our Ent schema. Next, let's see how to automatically generate a working CRUD gRPC *server* from our schema.
|
||||
|
||||
## Generating a Fully Working gRPC Server from our Schema
|
||||
|
||||
Having Protobuf structs generated from our `ent.Schema` can be useful, but what we're really interested in is getting an actual server that can create, read, update, and delete entities from an actual database. To do that, we need to update just one line of code! When we annotate a schema with `entproto.Service`, we tell the `entproto` code-gen that we are interested in generating a gRPC service definition, from the `protoc-gen-entgrpc` will read our definition and generate a service implementation. Edit `ent/schema/user.go` and modify the schema's `Annotations`:
|
||||
|
||||
```diff
|
||||
func (User) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entproto.Message(),
|
||||
+ entproto.Service(), // <-- add this
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Now re-run code-generation:
|
||||
|
||||
```console
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Observe some interesting changes in `ent/proto/entpb`:
|
||||
|
||||
```console
|
||||
ent/proto/entpb
|
||||
├── entpb.pb.go
|
||||
├── entpb.proto
|
||||
├── entpb_grpc.pb.go
|
||||
├── entpb_user_service.go
|
||||
└── generate.go
|
||||
```
|
||||
|
||||
First, `entproto` added a service definition to `entpb.proto`:
|
||||
|
||||
```protobuf
|
||||
service UserService {
|
||||
rpc Create ( CreateUserRequest ) returns ( User );
|
||||
|
||||
rpc Get ( GetUserRequest ) returns ( User );
|
||||
|
||||
rpc Update ( UpdateUserRequest ) returns ( User );
|
||||
|
||||
rpc Delete ( DeleteUserRequest ) returns ( google.protobuf.Empty );
|
||||
}
|
||||
```
|
||||
|
||||
In addition, two new files were created. The first, `ent_grpc.pb.go`, contains the gRPC client stub and the interface definition. If you open the file, you will find in it (among many other things):
|
||||
|
||||
```go
|
||||
// UserServiceClient is the client API for UserService service.
|
||||
//
|
||||
// For semantics around ctx use and closing/ending streaming RPCs, please refer to https://pkg.go.dev/google.golang.org/grpc/?tab=doc#ClientConn.NewStream.
|
||||
type UserServiceClient interface {
|
||||
Create(ctx context.Context, in *CreateUserRequest, opts ...grpc.CallOption) (*User, error)
|
||||
Get(ctx context.Context, in *GetUserRequest, opts ...grpc.CallOption) (*User, error)
|
||||
Update(ctx context.Context, in *UpdateUserRequest, opts ...grpc.CallOption) (*User, error)
|
||||
Delete(ctx context.Context, in *DeleteUserRequest, opts ...grpc.CallOption) (*emptypb.Empty, error)
|
||||
}
|
||||
```
|
||||
|
||||
The second file, `entpub_user_service.go` contains a generated implementation for this interface. For example, an implementation for the `Get` method:
|
||||
|
||||
```go
|
||||
// Get implements UserServiceServer.Get
|
||||
func (svc *UserService) Get(ctx context.Context, req *GetUserRequest) (*User, error) {
|
||||
get, err := svc.client.User.Get(ctx, int(req.GetId()))
|
||||
switch {
|
||||
case err == nil:
|
||||
return toProtoUser(get), nil
|
||||
case ent.IsNotFound(err):
|
||||
return nil, status.Errorf(codes.NotFound, "not found: %s", err)
|
||||
default:
|
||||
return nil, status.Errorf(codes.Internal, "internal error: %s", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Not bad! Next, let's create a gRPC server that can serve requests to our service.
|
||||
|
||||
### Creating the Server
|
||||
|
||||
Create a new file `cmd/server/main.go` and write:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"net"
|
||||
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
"ent-grpc-example/ent"
|
||||
"ent-grpc-example/ent/proto/entpb"
|
||||
"google.golang.org/grpc"
|
||||
)
|
||||
|
||||
func main() {
|
||||
// Initialize an ent client.
|
||||
client, err := ent.Open("sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to sqlite: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
|
||||
// Run the migration tool (creating tables, etc).
|
||||
if err := client.Schema.Create(context.Background()); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
|
||||
// Initialize the generated User service.
|
||||
svc := entpb.NewUserService(client)
|
||||
|
||||
// Create a new gRPC server (you can wire multiple services to a single server).
|
||||
server := grpc.NewServer()
|
||||
|
||||
// Register the User service with the server.
|
||||
entpb.RegisterUserServiceServer(server, svc)
|
||||
|
||||
// Open port 5000 for listening to traffic.
|
||||
lis, err := net.Listen("tcp", ":5000")
|
||||
if err != nil {
|
||||
log.Fatalf("failed listening: %s", err)
|
||||
}
|
||||
|
||||
// Listen for traffic indefinitely.
|
||||
if err := server.Serve(lis); err != nil {
|
||||
log.Fatalf("server ended: %s", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Notice that we added an import of `github.com/mattn/go-sqlite3`, so we need to add it to our module:
|
||||
|
||||
```console
|
||||
go get -u github.com/mattn/go-sqlite3
|
||||
```
|
||||
|
||||
Next, let's run the server, while we write a client that will communicate with it:
|
||||
|
||||
```console
|
||||
go run -mod=mod ./cmd/server
|
||||
```
|
||||
|
||||
### Creating the Client
|
||||
|
||||
Let's create a simple client that will make some calls to our server. Create a new file named `cmd/client/main.go` and write:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"fmt"
|
||||
"log"
|
||||
"math/rand"
|
||||
"time"
|
||||
|
||||
"ent-grpc-example/ent/proto/entpb"
|
||||
"google.golang.org/grpc"
|
||||
"google.golang.org/grpc/status"
|
||||
)
|
||||
|
||||
func main() {
|
||||
rand.Seed(time.Now().UnixNano())
|
||||
|
||||
// Open a connection to the server.
|
||||
conn, err := grpc.Dial(":5000", grpc.WithInsecure())
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to server: %s", err)
|
||||
}
|
||||
defer conn.Close()
|
||||
|
||||
// Create a User service Client on the connection.
|
||||
client := entpb.NewUserServiceClient(conn)
|
||||
|
||||
// Ask the server to create a random User.
|
||||
ctx := context.Background()
|
||||
user := randomUser()
|
||||
created, err := client.Create(ctx, &entpb.CreateUserRequest{
|
||||
User: user,
|
||||
})
|
||||
if err != nil {
|
||||
se, _ := status.FromError(err)
|
||||
log.Fatalf("failed creating user: status=%s message=%s", se.Code(), se.Message())
|
||||
}
|
||||
log.Printf("user created with id: %d", created.Id)
|
||||
|
||||
// On a separate RPC invocation, retrieve the user we saved previously.
|
||||
get, err := client.Get(ctx, &entpb.GetUserRequest{
|
||||
Id: created.Id,
|
||||
})
|
||||
if err != nil {
|
||||
se, _ := status.FromError(err)
|
||||
log.Fatalf("failed retrieving user: status=%s message=%s", se.Code(), se.Message())
|
||||
}
|
||||
log.Printf("retrieved user with id=%d: %v", get.Id, get)
|
||||
}
|
||||
|
||||
func randomUser() *entpb.User {
|
||||
return &entpb.User{
|
||||
Name: fmt.Sprintf("user_%d", rand.Int()),
|
||||
EmailAddress: fmt.Sprintf("user_%d@example.com", rand.Int()),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Our client creates a connection to port 5000, where our server is listening, then issues a `Create` request to create a new user, and then issues a second `Get` request to retrieve it from the database. Let's run our client code:
|
||||
|
||||
```console
|
||||
go run ./cmd/client
|
||||
```
|
||||
|
||||
Observe the output:
|
||||
|
||||
```console
|
||||
2021/03/18 10:42:58 user created with id: 1
|
||||
2021/03/18 10:42:58 retrieved user with id=1: id:1 name:"user_730811260095307266" email_address:"user_7338662242574055998@example.com"
|
||||
```
|
||||
|
||||
Amazing! With a few annotations on our schema, we used the super-powers of code generation to create a working gRPC server in no time!
|
||||
|
||||
## Caveats and Limitations
|
||||
|
||||
`entproto` is still experimental stage and lacks some basic functionality. For example, many applications will probably want a `List` or `Find` method on their service, but these are not yet supported. In addition, some other issues we plan to tackle in the near future:
|
||||
|
||||
- Currently only "unique" edges are supported (O2O, O2M).
|
||||
- The generated "mutating" methods (Create/Update) currently set all fields, disregarding zero/null values and field nullability.
|
||||
- All fields are copied from the gRPC request to the ent client, support for configuring some fields to be unsettable via the service by adding a field/edge annotation is also planned.
|
||||
|
||||
## Next Steps
|
||||
|
||||
We believe that `ent` + gRPC can be a great way to build server applications in Go. For example, to set granular access control to the entities managed by our application, developers can already use [Privacy Policies](https://entgo.io/docs/privacy/) that work out-of-the-box with the gRPC integration. To run any arbitrary Go code on the different lifecycle events of entities, developers can utilize custom [Hooks](https://entgo.io/docs/hooks/).
|
||||
|
||||
Do you want to build gRPC servers with `ent`? If you want some help setting up or want the integration to support your use case, please reach out to us via our [Discussions Page on GitHub](https://github.com/ent/ent/discussions) or in the #ent channel on the [Gophers Slack](https://app.slack.com/client/T029RQSE6/C01FMSQDT53) or our [Discord server](https://discord.gg/qZmPgTE6RX).
|
||||
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://app.slack.com/client/T029RQSE6/C01FMSQDT53)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
103
doc/website/blog/2021-05-04-announcing-schema-imports.md
Normal file
103
doc/website/blog/2021-05-04-announcing-schema-imports.md
Normal file
@@ -0,0 +1,103 @@
|
||||
---
|
||||
title: Announcing the "Schema Import Initiative" and protoc-gen-ent
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
---
|
||||
|
||||
Migrating to a new ORM is not an easy process, and the transition cost can be prohibitive to many organizations. As much
|
||||
as we developers are enamoured by "Shiny New Things", the truth is that we rarely get a chance to work on a
|
||||
truly "green-field" project. Most of our careers, we operate in contexts where many technical and business constraints
|
||||
(a.k.a legacy systems) dictate and limit our options for moving forward. Developers of new technologies that want to
|
||||
succeed must offer interoperability capability and integration paths to help organizations seamlessly transition to a
|
||||
new way of solving an existing problem.
|
||||
|
||||
To help lower the cost of transitioning to Ent (or simply experimenting with it), we have started the
|
||||
"**Schema Import Initiative**" to help support many use cases for generating Ent schemas from external resources.
|
||||
The centrepiece of this effort is the `schemast` package ([source code](https://github.com/ent/contrib/tree/master/schemast),
|
||||
[docs](https://entgo.io/docs/generating-ent-schemas)) which enables developers to easily write programs that generate
|
||||
and manipulate Ent schemas. Using this package, developers can program in a high-level API, relieving them from worrying
|
||||
about code parsing and AST manipulations.
|
||||
|
||||
### Protobuf Import Support
|
||||
|
||||
The first project to use this new API, is `protoc-gen-ent`, a `protoc` plugin to generate Ent schemas from `.proto`
|
||||
files ([docs](https://github.com/ent/contrib/tree/master/entproto/cmd/protoc-gen-ent)). Organizations that have existing
|
||||
schemas defined in Protobuf can use this tool to generate Ent code automatically. For example, taking a simple
|
||||
message definition:
|
||||
|
||||
```protobuf
|
||||
syntax = "proto3";
|
||||
|
||||
package entpb;
|
||||
|
||||
option go_package = "github.com/yourorg/project/ent/proto/entpb";
|
||||
|
||||
message User {
|
||||
string name = 1;
|
||||
string email_address = 2;
|
||||
}
|
||||
```
|
||||
|
||||
And setting the `ent.schema.gen` option to true:
|
||||
|
||||
```diff
|
||||
syntax = "proto3";
|
||||
|
||||
package entpb;
|
||||
|
||||
+import "options/opts.proto";
|
||||
|
||||
option go_package = "github.com/yourorg/project/ent/proto/entpb";
|
||||
|
||||
message User {
|
||||
+ option (ent.schema).gen = true; // <-- tell protoc-gen-ent you want to generate a schema from this message
|
||||
string name = 1;
|
||||
string email_address = 2;
|
||||
}
|
||||
```
|
||||
|
||||
Developers can invoke the standard `protoc` (protobuf compiler) command to use this plugin:
|
||||
|
||||
```shell
|
||||
protoc -I=proto/ --ent_out=. --ent_opt=schemadir=./schema proto/entpb/user.proto
|
||||
```
|
||||
|
||||
To generate Ent schemas from these definitions:
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{field.String("name"), field.String("email_address")}
|
||||
}
|
||||
func (User) Edges() []ent.Edge {
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
To start using `protoc-gen-ent` today, and read about all of the different configuration options, head over to
|
||||
the [documentation](https://github.com/ent/contrib/tree/master/entproto/cmd/protoc-gen-ent)!
|
||||
|
||||
### Join the Schema Import Initiative
|
||||
|
||||
Do you have schemas defined elsewhere that you would like to automatically import in to Ent? With the `schemast`
|
||||
package, it is easier than ever to write the tool that you need to do that. Not sure how to start? Want to collaborate
|
||||
with the community in planning and building out your idea? Reach out to our great community via our
|
||||
[Discord server](https://discord.gg/qZmPgTE6RX), [Slack channel](https://app.slack.com/client/T029RQSE6/C01FMSQDT53) or start a [discussion on GitHub](https://github.com/ent/ent/discussions)!
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://app.slack.com/client/T029RQSE6/C01FMSQDT53)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
85
doc/website/blog/2021-06-28-gprc-ready-for-use.md
Normal file
85
doc/website/blog/2021-06-28-gprc-ready-for-use.md
Normal file
@@ -0,0 +1,85 @@
|
||||
---
|
||||
title: Ent + gRPC is Ready for Usage
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
---
|
||||
A few months ago, we announced the experimental support for
|
||||
[generating gRPC services from Ent Schema definitions](https://entgo.io/blog/2021/03/18/generating-a-grpc-server-with-ent). The
|
||||
implementation was not complete yet but we wanted to get it out the door for the community to experiment with and provide
|
||||
us with feedback.
|
||||
|
||||
Today, after much feedback from the community, we are happy to announce that the [Ent](https://entgo.io) +
|
||||
[gRPC](https://grpc.io) integration is "Ready for Usage", this means all of the basic features are complete
|
||||
and we anticipate that most Ent applications can utilize this integration.
|
||||
|
||||
What have we added since our initial announcement?
|
||||
- [Support for "Optional Fields"](https://entgo.io/docs/grpc-optional-fields) - A common issue with Protobufs
|
||||
is that the way that nil values are represented: a zero-valued primitive field isn't encoded into the binary
|
||||
representation. This means that applications cannot distinguish between zero and not-set for primitive fields.
|
||||
To support this, the Protobuf project supports some
|
||||
"[Well-Known-Types](https://developers.google.com/protocol-buffers/docs/reference/google.protobuf)"
|
||||
called "wrapper types" that wrap the primitive value with a struct. This wasn't previously supported
|
||||
but now when `entproto` generates a Protobuf message definition, it uses these wrapper types to represent
|
||||
"Optional" ent fields:
|
||||
```protobuf {15}
|
||||
// Code generated by entproto. DO NOT EDIT.
|
||||
syntax = "proto3";
|
||||
|
||||
package entpb;
|
||||
|
||||
import "google/protobuf/wrappers.proto";
|
||||
|
||||
message User {
|
||||
int32 id = 1;
|
||||
|
||||
string name = 2;
|
||||
|
||||
string email_address = 3;
|
||||
|
||||
google.protobuf.StringValue alias = 4;
|
||||
}
|
||||
```
|
||||
|
||||
- [Multi-edge support](https://entgo.io/docs/grpc-edges) - when we released the initial version of
|
||||
`protoc-gen-entgrpc`, we only supported generating gRPC service implementations for "Unique" edges
|
||||
(i.e reference at most one entity). Since a [recent version](https://github.com/ent/contrib/commit/bf9430fbba45a808bc054144f9711833c76bf05c),
|
||||
the plugin supports the generation of gRPC methods to read and write entities with O2M and M2M relationships.
|
||||
- [Partial responses](https://entgo.io/docs/grpc-edges#retrieving-edge-ids-for-entities) - By default, edge information
|
||||
is not returned by the `Get` method of the service. This is done deliberately because the amount of entities related
|
||||
to an entity is unbound.
|
||||
|
||||
To allow the caller of to specify whether or not to return the edge information or not, the generated service adheres
|
||||
to [Google AIP-157](https://google.aip.dev/157) (Partial Responses). In short, the `Get<T>Request` message
|
||||
includes an enum named View, this enum allows the caller to control whether or not this information should be retrieved from the database or not.
|
||||
|
||||
```protobuf {6-12}
|
||||
message GetUserRequest {
|
||||
int32 id = 1;
|
||||
|
||||
View view = 2;
|
||||
|
||||
enum View {
|
||||
VIEW_UNSPECIFIED = 0;
|
||||
|
||||
BASIC = 1;
|
||||
|
||||
WITH_EDGE_IDS = 2;
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Getting Started
|
||||
|
||||
- To help everyone get started with the Ent + gRPC integration, we have published an official [Ent + gRPC Tutorial](https://entgo.io/docs/grpc-intro) (and a complimentary [GitHub repo](https://github.com/rotemtam/ent-grpc-example)).
|
||||
- Do you need help getting started with the integration or have some other question? [Join us on Slack](https://entgo.io/docs/slack) or our [Discord server](https://discord.gg/qZmPgTE6RX).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
@@ -0,0 +1,349 @@
|
||||
---
|
||||
title: Automatic GraphQL Filter Generation
|
||||
author: Ariel Mashraki
|
||||
authorURL: "https://github.com/a8m"
|
||||
authorImageURL: "https://avatars0.githubusercontent.com/u/7413593"
|
||||
authorTwitter: arielmashraki
|
||||
---
|
||||
|
||||
#### TL;DR
|
||||
|
||||
We added a new integration to the Ent GraphQL extension that generates type-safe GraphQL filters (i.e. `Where` predicates)
|
||||
from an `ent/schema`, and allows users to seamlessly map GraphQL queries to Ent queries.
|
||||
|
||||
For example, to get all `COMPLETED` todo items, we can execute the following:
|
||||
|
||||
````graphql
|
||||
query QueryAllCompletedTodos {
|
||||
todos(
|
||||
where: {
|
||||
status: COMPLETED,
|
||||
},
|
||||
) {
|
||||
edges {
|
||||
node {
|
||||
id
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
````
|
||||
|
||||
The generated GraphQL filters follow the Ent syntax. This means, the following query is also valid:
|
||||
|
||||
```graphql
|
||||
query FilterTodos {
|
||||
todos(
|
||||
where: {
|
||||
or: [
|
||||
{
|
||||
hasParent: false,
|
||||
status: COMPLETED,
|
||||
},
|
||||
{
|
||||
status: IN_PROGRESS,
|
||||
hasParentWith: {
|
||||
priorityLT: 1,
|
||||
statusNEQ: COMPLETED,
|
||||
},
|
||||
}
|
||||
]
|
||||
},
|
||||
) {
|
||||
edges {
|
||||
node {
|
||||
id
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Background
|
||||
|
||||
Many libraries that deal with data in Go choose the path of passing around empty interface instances
|
||||
(`interface{}`) and use reflection at runtime to figure out how to map data to struct fields. Aside from the
|
||||
performance penalty of using reflection everywhere, the big negative impact on teams is the
|
||||
loss of type-safety.
|
||||
|
||||
When APIs are explicit, known at compile-time (or even as we type), the feedback a developer receives around a
|
||||
large class of errors is almost immediate. Many defects are found early, and development is also much more fun!
|
||||
|
||||
Ent was designed to provide an excellent developer experience for teams working on applications with
|
||||
large data-models. To facilitate this, we decided early on that one of the core design principles
|
||||
of Ent is "statically typed and explicit API using code generation". This means, that for every
|
||||
entity a developer defines in their `ent/schema`, explicit, type-safe code is generated for the
|
||||
developer to efficiently interact with their data. For example, In the
|
||||
[Filesystem Example in the ent repository](https://github.com/ent/ent/blob/master/examples/fs/), you will
|
||||
find a schema named `File`:
|
||||
|
||||
```go
|
||||
// File holds the schema definition for the File entity.
|
||||
type File struct {
|
||||
ent.Schema
|
||||
}
|
||||
// Fields of the File.
|
||||
func (File) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.Bool("deleted").
|
||||
Default(false),
|
||||
field.Int("parent_id").
|
||||
Optional(),
|
||||
}
|
||||
}
|
||||
```
|
||||
When the Ent code-gen runs, it will generate many predicate functions. For example, the following function which
|
||||
can be used to filter `File`s by their `name` field:
|
||||
|
||||
```go
|
||||
package file
|
||||
// .. truncated ..
|
||||
|
||||
// Name applies the EQ predicate on the "name" field.
|
||||
func Name(v string) predicate.File {
|
||||
return predicate.File(func(s *sql.Selector) {
|
||||
s.Where(sql.EQ(s.C(FieldName), v))
|
||||
})
|
||||
}
|
||||
```
|
||||
|
||||
[GraphQL](https://graphql.org) is a query language for APIs originally created at Facebook. Similar to Ent,
|
||||
GraphQL models data in graph concepts and facilitates type-safe queries. Around a year ago, we
|
||||
released an integration between Ent and GraphQL. Similar to the [gRPC Integration](2021-06-28-gprc-ready-for-use.md),
|
||||
the goal for this integration is to allow developers to easily create API servers that map to Ent, to mutate
|
||||
and query data in their databases.
|
||||
|
||||
### Automatic GraphQL Filters Generation
|
||||
|
||||
In a recent community survey, the Ent + GraphQL integration was mentioned as one of the most
|
||||
loved features of the Ent project. Until today, the integration allowed users to perform useful, albeit
|
||||
basic queries against their data. Today, we announce the release of a feature that we think will
|
||||
open up many interesting new use cases for Ent users: "Automatic GraphQL Filters Generation".
|
||||
|
||||
As we have seen above, the Ent code-gen maintains for us a suite of predicate functions in our Go codebase
|
||||
that allow us to easily and explicitly filter data from our database tables. This power was,
|
||||
until recently, not available (at least not automatically) to users of the Ent + GraphQL integration.
|
||||
With automatic GraphQL filter generation, by making a single-line configuration change, developers
|
||||
can now add to their GraphQL schema a complete set of "Filter Input Types" that can be used as predicates in their
|
||||
GraphQL queries. In addition, the implementation provides runtime code that parses these predicates and maps them into
|
||||
Ent queries. Let's see this in action:
|
||||
|
||||
### Generating Filter Input Types
|
||||
|
||||
In order to generate input filters (e.g. `TodoWhereInput`) for each type in your `ent/schema` package,
|
||||
edit the `ent/entc.go` configuration file as follows:
|
||||
|
||||
```go
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/contrib/entgql"
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ex, err := entgql.NewExtension(
|
||||
entgql.WithWhereFilters(true),
|
||||
entgql.WithConfigPath("../gqlgen.yml"),
|
||||
entgql.WithSchemaPath("<PATH-TO-GRAPHQL-SCHEMA>"),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("creating entgql extension: %v", err)
|
||||
}
|
||||
err = entc.Generate("./schema", &gen.Config{}, entc.Extensions(ex))
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
If you're new to Ent and GraphQL, please follow the [Getting Started Tutorial](https://entgo.io/docs/tutorial-todo-gql).
|
||||
|
||||
Next, run `go generate ./ent/...`. Observe that Ent has generated `<T>WhereInput` for each type in your schema. Ent
|
||||
will update the GraphQL schema as well, so you don't need to `autobind` them to `gqlgen` manually. For example:
|
||||
|
||||
```go title="ent/where_input.go"
|
||||
// TodoWhereInput represents a where input for filtering Todo queries.
|
||||
type TodoWhereInput struct {
|
||||
Not *TodoWhereInput `json:"not,omitempty"`
|
||||
Or []*TodoWhereInput `json:"or,omitempty"`
|
||||
And []*TodoWhereInput `json:"and,omitempty"`
|
||||
|
||||
// "created_at" field predicates.
|
||||
CreatedAt *time.Time `json:"createdAt,omitempty"`
|
||||
CreatedAtNEQ *time.Time `json:"createdAtNEQ,omitempty"`
|
||||
CreatedAtIn []time.Time `json:"createdAtIn,omitempty"`
|
||||
CreatedAtNotIn []time.Time `json:"createdAtNotIn,omitempty"`
|
||||
CreatedAtGT *time.Time `json:"createdAtGT,omitempty"`
|
||||
CreatedAtGTE *time.Time `json:"createdAtGTE,omitempty"`
|
||||
CreatedAtLT *time.Time `json:"createdAtLT,omitempty"`
|
||||
CreatedAtLTE *time.Time `json:"createdAtLTE,omitempty"`
|
||||
|
||||
// "status" field predicates.
|
||||
Status *todo.Status `json:"status,omitempty"`
|
||||
StatusNEQ *todo.Status `json:"statusNEQ,omitempty"`
|
||||
StatusIn []todo.Status `json:"statusIn,omitempty"`
|
||||
StatusNotIn []todo.Status `json:"statusNotIn,omitempty"`
|
||||
|
||||
// .. truncated ..
|
||||
}
|
||||
```
|
||||
|
||||
```graphql title="todo.graphql"
|
||||
"""
|
||||
TodoWhereInput is used for filtering Todo objects.
|
||||
Input was generated by ent.
|
||||
"""
|
||||
input TodoWhereInput {
|
||||
not: TodoWhereInput
|
||||
and: [TodoWhereInput!]
|
||||
or: [TodoWhereInput!]
|
||||
|
||||
"""created_at field predicates"""
|
||||
createdAt: Time
|
||||
createdAtNEQ: Time
|
||||
createdAtIn: [Time!]
|
||||
createdAtNotIn: [Time!]
|
||||
createdAtGT: Time
|
||||
createdAtGTE: Time
|
||||
createdAtLT: Time
|
||||
createdAtLTE: Time
|
||||
|
||||
"""status field predicates"""
|
||||
status: Status
|
||||
statusNEQ: Status
|
||||
statusIn: [Status!]
|
||||
statusNotIn: [Status!]
|
||||
|
||||
# .. truncated ..
|
||||
}
|
||||
```
|
||||
|
||||
Next, to complete the integration we need to make two more changes:
|
||||
|
||||
1\. Edit the GraphQL schema to accept the new filter types:
|
||||
```graphql {8}
|
||||
type Query {
|
||||
todos(
|
||||
after: Cursor,
|
||||
first: Int,
|
||||
before: Cursor,
|
||||
last: Int,
|
||||
orderBy: TodoOrder,
|
||||
where: TodoWhereInput,
|
||||
): TodoConnection!
|
||||
}
|
||||
```
|
||||
|
||||
2\. Use the new filter types in GraphQL resolvers:
|
||||
```go {5}
|
||||
func (r *queryResolver) Todos(ctx context.Context, after *ent.Cursor, first *int, before *ent.Cursor, last *int, orderBy *ent.TodoOrder, where *ent.TodoWhereInput) (*ent.TodoConnection, error) {
|
||||
return r.client.Todo.Query().
|
||||
Paginate(ctx, after, first, before, last,
|
||||
ent.WithTodoOrder(orderBy),
|
||||
ent.WithTodoFilter(where.Filter),
|
||||
)
|
||||
}
|
||||
```
|
||||
|
||||
### Filter Specification
|
||||
|
||||
As mentioned above, with the new GraphQL filter types, you can express the same Ent filters you use in your
|
||||
Go code.
|
||||
|
||||
#### Conjunction, disjunction and negation
|
||||
|
||||
The `Not`, `And` and `Or` operators can be added using the `not`, `and` and `or` fields. For example:
|
||||
|
||||
```graphql
|
||||
{
|
||||
or: [
|
||||
{
|
||||
status: COMPLETED,
|
||||
},
|
||||
{
|
||||
not: {
|
||||
hasParent: true,
|
||||
status: IN_PROGRESS,
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
When multiple filter fields are provided, Ent implicitly adds the `And` operator.
|
||||
|
||||
```graphql
|
||||
{
|
||||
status: COMPLETED,
|
||||
textHasPrefix: "GraphQL",
|
||||
}
|
||||
```
|
||||
The above query will produce the following Ent query:
|
||||
|
||||
```go
|
||||
client.Todo.
|
||||
Query().
|
||||
Where(
|
||||
todo.And(
|
||||
todo.StatusEQ(todo.StatusCompleted),
|
||||
todo.TextHasPrefix("GraphQL"),
|
||||
)
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
#### Edge/Relation filters
|
||||
|
||||
[Edge (relation) predicates](https://entgo.io/docs/predicates#edge-predicates) can be expressed in the same Ent syntax:
|
||||
|
||||
```graphql
|
||||
{
|
||||
hasParent: true,
|
||||
hasChildrenWith: {
|
||||
status: IN_PROGRESS,
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The above query will produce the following Ent query:
|
||||
|
||||
```go
|
||||
client.Todo.
|
||||
Query().
|
||||
Where(
|
||||
todo.HasParent(),
|
||||
todo.HasChildrenWith(
|
||||
todo.StatusEQ(todo.StatusInProgress),
|
||||
),
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
### Implementation Example
|
||||
|
||||
A working example exists in [github.com/a8m/ent-graphql-example](https://github.com/a8m/ent-graphql-example).
|
||||
|
||||
### Wrapping Up
|
||||
|
||||
As we've discussed earlier, Ent has set creating a "statically typed and explicit API using code generation"
|
||||
as a core design principle. With automatic GraphQL filter generation, we are doubling down on this
|
||||
idea to provide developers with the same explicit, type-safe development experience on the RPC layer as well.
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
|
||||
@@ -0,0 +1,323 @@
|
||||
---
|
||||
title: Database Locking Techniques with Ent
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
---
|
||||
|
||||
Locks are one of the fundamental building blocks of any concurrent
|
||||
computer program. When many things are happening simultaneously,
|
||||
programmers reach out to locks to guarantee the mutual exclusion of
|
||||
concurrent access to a resource. Locks (and other mutual exclusion
|
||||
primitives) exist in many different layers of the stack from low-level
|
||||
CPU instructions to application-level APIs (such as `sync.Mutex` in Go).
|
||||
|
||||
When working with relational databases, one of the common needs of
|
||||
application developers is the ability to acquire a lock on records.
|
||||
Imagine an `inventory` table, listing items available for sale on
|
||||
an e-commerce website. This table might have a column named `state`
|
||||
that could either be set to `available` or `purchased`. avoid the
|
||||
scenario where two users think they have successfully purchased the
|
||||
same inventory item, the application must prevent two operations
|
||||
from mutating the item from an available to a purchased state.
|
||||
|
||||
How can the application guarantee this? Having the server check
|
||||
if the desired item is `available` before setting it to `purchased`
|
||||
would not be good enough. Imagine a scenario where two users
|
||||
simultaneously try to purchase the same item. Two requests would
|
||||
travel from their browsers to the application server and arrive
|
||||
roughly at the same time. Both would query the database for the
|
||||
item's state, and see the item is `available`. Seeing this, both
|
||||
request handlers would issue an `UPDATE` query setting the state
|
||||
to `purchased` and the `buyer_id` to the id of the requesting user.
|
||||
Both queries will succeed, but the final state of the record will
|
||||
be that the user who issued the `UPDATE` query last will be
|
||||
considered the buyer of the item.
|
||||
|
||||
Over the years, different techniques have evolved to allow developers
|
||||
to write applications that provide these guarantees to users. Some
|
||||
of them involve explicit locking mechanisms provided by databases,
|
||||
while others rely on more general ACID properties of databases to
|
||||
achieve mutual exclusion. In this post we will explore the
|
||||
implementation of two of these techniques using Ent.
|
||||
|
||||
### Optimistic Locking
|
||||
|
||||
Optimistic locking (sometimes also called Optimistic Concurrency
|
||||
Control) is a technique that can be used to achieve locking
|
||||
behavior without explicitly acquiring a lock on any record.
|
||||
|
||||
On a high-level, this is how optimistic locking works:
|
||||
|
||||
- Each record is assigned a numeric version number. This value
|
||||
must be monotonically increasing. Often Unix timestamps of the latest row update are used.
|
||||
- A transaction reads a record, noting its version number from the
|
||||
database.
|
||||
- An `UPDATE` statement is issued to modify the record:
|
||||
- The statement must include a predicate requiring that the
|
||||
version number has not changed from its previous value. For example: `WHERE id=<id> AND version=<previous version>`.
|
||||
- The statement must increase the version. Some applications
|
||||
will increase the current value by 1, and some will set it
|
||||
to the current timestamp.
|
||||
- The database returns the amount of rows modified by
|
||||
the `UPDATE` statement. If the number is 0, this means someone
|
||||
else has modified the record between the time we read it, and
|
||||
the time we wanted to update it. The transaction is considered
|
||||
failed, rolled back and can be retried.
|
||||
|
||||
Optimistic locking is commonly used in "low contention"
|
||||
environments (situations where the likelihood of two transactions
|
||||
interfering with one another is relatively low) and where the
|
||||
locking logic can be trusted to happen in the application layer.
|
||||
If there are writers to the database that we cannot ensure to
|
||||
obey the required logic, this technique is rendered useless.
|
||||
|
||||
Let’s see how this technique can be employed using Ent.
|
||||
|
||||
We start by defining our `ent.Schema` for a `User`. The user has an
|
||||
`online` boolean field to specify whether they are currently
|
||||
online and an `int64` field for the current version number.
|
||||
|
||||
```go
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Bool("online"),
|
||||
field.Int64("version").
|
||||
DefaultFunc(func() int64 {
|
||||
return time.Now().UnixNano()
|
||||
}).
|
||||
Comment("Unix time of when the latest update occurred")
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Next, let's implement a simple optimistically locked update to our
|
||||
`online` field:
|
||||
|
||||
```go
|
||||
func optimisticUpdate(tx *ent.Tx, prev *ent.User, online bool) error {
|
||||
// The next version number for the record must monotonically increase
|
||||
// using the current timestamp is a common technique to achieve this.
|
||||
nextVer := time.Now().UnixNano()
|
||||
|
||||
// We begin the update operation:
|
||||
n := tx.User.Update().
|
||||
|
||||
// We limit our update to only work on the correct record and version:
|
||||
Where(user.ID(prev.ID), user.Version(prev.Version)).
|
||||
|
||||
// We set the next version:
|
||||
SetVersion(nextVer).
|
||||
|
||||
// We set the value we were passed by the user:
|
||||
SetOnline(online).
|
||||
SaveX(context.Background())
|
||||
|
||||
// SaveX returns the number of affected records. If this value is
|
||||
// different from 1 the record must have been changed by another
|
||||
// process.
|
||||
if n != 1 {
|
||||
return fmt.Errorf("update failed: user id=%d updated by another process", prev.ID)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
Next, let's write a test to verify that if two processes try to
|
||||
edit the same record, only one will succeed:
|
||||
|
||||
```go
|
||||
func TestOCC(t *testing.T) {
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
ctx := context.Background()
|
||||
|
||||
// Create the user for the first time.
|
||||
orig := client.User.Create().SetOnline(true).SaveX(ctx)
|
||||
|
||||
// Read another copy of the same user.
|
||||
userCopy := client.User.GetX(ctx, orig.ID)
|
||||
|
||||
// Open a new transaction:
|
||||
tx, err := client.Tx(ctx)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating transaction: %v", err)
|
||||
}
|
||||
|
||||
// Try to update the record once. This should succeed.
|
||||
if err := optimisticUpdate(tx, userCopy, false); err != nil {
|
||||
tx.Rollback()
|
||||
log.Fatal("unexpected failure:", err)
|
||||
}
|
||||
|
||||
// Try to update the record a second time. This should fail.
|
||||
err = optimisticUpdate(tx, orig, false)
|
||||
if err == nil {
|
||||
log.Fatal("expected second update to fail")
|
||||
}
|
||||
fmt.Println(err)
|
||||
}
|
||||
```
|
||||
|
||||
Running our test:
|
||||
|
||||
```go
|
||||
=== RUN TestOCC
|
||||
update failed: user id=1 updated by another process
|
||||
--- PASS: Test (0.00s)
|
||||
```
|
||||
|
||||
Great! Using optimistic locking we can prevent two processes from
|
||||
stepping on each other's toes!
|
||||
|
||||
### Pessimistic Locking
|
||||
|
||||
As we've mentioned above, optimistic locking isn't always
|
||||
appropriate. For use cases where we prefer to delegate the
|
||||
responsibility for maintaining the integrity of the lock to
|
||||
the databases, some database engines (such as MySQL, Postgres,
|
||||
and MariaDB, but not SQLite) offer pessimistic locking
|
||||
capabilities. These databases support a modifier to `SELECT`
|
||||
statements that is called `SELECT ... FOR UPDATE`. The MySQL
|
||||
documentation [explains](https://dev.mysql.com/doc/refman/8.0/en/innodb-locking-reads.html):
|
||||
|
||||
> A SELECT ... FOR UPDATE reads the latest available data, setting
|
||||
> exclusive locks on each row it reads. Thus, it sets the same locks
|
||||
> a searched SQL UPDATE would set on the rows.
|
||||
|
||||
Alternatively, users can use `SELECT ... FOR SHARE` statements, as
|
||||
explained by the docs, `SELECT ... FOR SHARE`:
|
||||
|
||||
> Sets a shared mode lock on any rows that are read. Other sessions
|
||||
> can read the rows, but cannot modify them until your transaction
|
||||
> commits. If any of these rows were changed by another transaction
|
||||
> that has not yet committed, your query waits until that
|
||||
> transaction ends and then uses the latest values.
|
||||
|
||||
Ent has recently added support for `FOR SHARE`/ `FOR UPDATE`
|
||||
statements via a feature-flag called `sql/lock`. To use it,
|
||||
modify your `generate.go` file to include `--feature sql/lock`:
|
||||
|
||||
```go
|
||||
//go:generate go run -mod=mod entgo.io/ent/cmd/ent generate --feature sql/lock ./schema
|
||||
```
|
||||
|
||||
Next, let's implement a function that will use pessimistic
|
||||
locking to make sure only a single process can update our `User`
|
||||
object's `online` field:
|
||||
|
||||
```go
|
||||
func pessimisticUpdate(tx *ent.Tx, id int, online bool) (*ent.User, error) {
|
||||
ctx := context.Background()
|
||||
|
||||
// On our active transaction, we begin a query against the user table
|
||||
u, err := tx.User.Query().
|
||||
|
||||
// We add a predicate limiting the lock to the user we want to update.
|
||||
Where(user.ID(id)).
|
||||
|
||||
// We use the ForUpdate method to tell ent to ask our DB to lock
|
||||
// the returned records for update.
|
||||
ForUpdate(
|
||||
// We specify that the query should not wait for the lock to be
|
||||
// released and instead fail immediately if the record is locked.
|
||||
sql.WithLockAction(sql.NoWait),
|
||||
).
|
||||
Only(ctx)
|
||||
|
||||
// If we failed to acquire the lock we do not proceed to update the record.
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
// Finally, we set the online field to the desired value.
|
||||
return u.Update().SetOnline(online).Save(ctx)
|
||||
}
|
||||
```
|
||||
|
||||
Now, let's write a test that verifies that if two processes try to
|
||||
edit the same record, only one will succeed:
|
||||
|
||||
```go
|
||||
func TestPessimistic(t *testing.T) {
|
||||
ctx := context.Background()
|
||||
client := enttest.Open(t, dialect.MySQL, "root:pass@tcp(localhost:3306)/test?parseTime=True")
|
||||
|
||||
// Create the user for the first time.
|
||||
orig := client.User.Create().SetOnline(true).SaveX(ctx)
|
||||
|
||||
// Open a new transaction. This transaction will acquire the lock on our user record.
|
||||
tx, err := client.Tx(ctx)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating transaction: %v", err)
|
||||
}
|
||||
defer tx.Commit()
|
||||
|
||||
// Open a second transaction. This transaction is expected to fail at
|
||||
// acquiring the lock on our user record.
|
||||
tx2, err := client.Tx(ctx)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating transaction: %v", err)
|
||||
}
|
||||
defer tx.Commit()
|
||||
|
||||
// The first update is expected to succeed.
|
||||
if _, err := pessimisticUpdate(tx, orig.ID, true); err != nil {
|
||||
log.Fatalf("unexpected error: %s", err)
|
||||
}
|
||||
|
||||
// Because we did not run tx.Commit yet, the row is still locked when
|
||||
// we try to update it a second time. This operation is expected to
|
||||
// fail.
|
||||
_, err = pessimisticUpdate(tx2, orig.ID, true)
|
||||
if err == nil {
|
||||
log.Fatal("expected second update to fail")
|
||||
}
|
||||
fmt.Println(err)
|
||||
}
|
||||
```
|
||||
|
||||
A few things are worth mentioning in this example:
|
||||
|
||||
- Notice that we use a real MySQL instance to run this test
|
||||
against, as SQLite does not support `SELECT .. FOR UPDATE`.
|
||||
- For the simplicity of the example, we used the `sql.NoWait`
|
||||
option to tell the database to return an error if the lock cannot be acquired. This means that the calling application needs to retry the write after receiving the error. If we don't specify this option, we can create flows where our application blocks until the lock is released and then proceeds without retrying. This is not always desirable but it opens up some interesting design options.
|
||||
- We must always commit our transaction. Forgetting to do so can
|
||||
result in some serious issues. Remember that while the lock
|
||||
is maintained, no one can read or update this record.
|
||||
|
||||
Running our test:
|
||||
|
||||
```go
|
||||
=== RUN TestPessimistic
|
||||
Error 3572: Statement aborted because lock(s) could not be acquired immediately and NOWAIT is set.
|
||||
--- PASS: TestPessimistic (0.08s)
|
||||
```
|
||||
|
||||
Great! We have used MySQL's "locking reads" capabilities and Ent's
|
||||
new support for it to implement a locking mechanism that provides
|
||||
real mutual exclusion guarantees.
|
||||
|
||||
### Conclusion
|
||||
|
||||
We began this post by presenting the type of business requirements
|
||||
that lead application developers to reach out for locking techniques when working with databases. We continued by presenting two different approaches to achieving mutual exclusion when updating database records and demonstrated how to employ these techniques using Ent.
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join
|
||||
our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
@@ -0,0 +1,533 @@
|
||||
---
|
||||
title: Generate a fully-working Go CRUD HTTP API with Ent
|
||||
author: MasseElch
|
||||
authorURL: "https://github.com/masseelch"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/12862103?v=4"
|
||||
---
|
||||
|
||||
When we say that one of the core principles of Ent is "Schema as Code", we mean by that more than "Ent's DSL for
|
||||
defining entities and their edges is done using regular Go code". Ent's unique approach, compared to many other ORMs, is
|
||||
to express all of the logic related to an entity, as code, directly in the schema definition.
|
||||
|
||||
With Ent, developers can write all authorization logic (called "[Privacy](https://entgo.io/docs/privacy)" within Ent),
|
||||
and all of the mutation side-effects (called "[Hooks](https://entgo.io/docs/hooks)" within Ent) directly on the schema.
|
||||
Having everything in the same place can be very convenient, but its true power is revealed when paired with code
|
||||
generation.
|
||||
|
||||
If schemas are defined this way, it becomes possible to generate code for fully-working production-grade servers
|
||||
automatically. If we move the responsibility for authorization decisions and custom side effects from the RPC layer to
|
||||
the data layer, the implementation of the basic CRUD (Create, Read, Update and Delete) endpoints becomes generic to the
|
||||
extent that it can be machine-generated. This is exactly the idea behind the popular GraphQL and gRPC Ent extensions.
|
||||
|
||||
Today, we would like to present a new Ent extension named `elk` that can automatically generate fully-working, RESTful
|
||||
API endpoints from your Ent schemas. `elk` strives to automate all of the tedious work of setting up the basic CRUD
|
||||
endpoints for every entity you add to your graph, including logging, validation of the request body, eager loading
|
||||
relations and serializing, all while leaving reflection out of sight and maintaining type-safety.
|
||||
|
||||
Let’s get started!
|
||||
|
||||
### Getting Started
|
||||
|
||||
The final version of the code below can be found on [GitHub](https://github.com/masseelch/elk-example).
|
||||
|
||||
Start by creating a new Go project:
|
||||
|
||||
```shell
|
||||
mkdir elk-example
|
||||
cd elk-example
|
||||
go mod init elk-example
|
||||
```
|
||||
|
||||
Invoke the ent code generator and create two schemas: User, Pet:
|
||||
|
||||
```shell
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new Pet User
|
||||
```
|
||||
|
||||
Your project should now look like this:
|
||||
|
||||
```
|
||||
.
|
||||
├── ent
|
||||
│ ├── generate.go
|
||||
│ └── schema
|
||||
│ ├── pet.go
|
||||
│ └── user.go
|
||||
├── go.mod
|
||||
└── go.sum
|
||||
```
|
||||
|
||||
Next, add the `elk` package to our project:
|
||||
|
||||
```shell
|
||||
go get -u github.com/masseelch/elk
|
||||
```
|
||||
|
||||
`elk` uses the
|
||||
Ent [extension API](https://github.com/ent/ent/blob/a19a89a141cf1a5e1b38c93d7898f218a1f86c94/entc/entc.go#L197) to
|
||||
integrate with Ent’s code-generation. This requires that we use the `entc` (ent codegen) package as
|
||||
described [here](https://entgo.io/docs/code-gen#use-entc-as-a-package). Follow the next three steps to enable it and to
|
||||
configure Ent to work with the `elk` extension:
|
||||
|
||||
1\. Create a new Go file named `ent/entc.go` and paste the following content:
|
||||
|
||||
```go
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
"github.com/masseelch/elk"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ex, err := elk.NewExtension(
|
||||
elk.GenerateSpec("openapi.json"),
|
||||
elk.GenerateHandlers(),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("creating elk extension: %v", err)
|
||||
}
|
||||
err = entc.Generate("./schema", &gen.Config{}, entc.Extensions(ex))
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
2\. Edit the `ent/generate.go` file to execute the `ent/entc.go` file:
|
||||
|
||||
```go
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entc.go
|
||||
|
||||
```
|
||||
|
||||
3/. `elk` uses some external packages in its generated code. Currently, you have to get those packages manually once
|
||||
when setting up `elk`:
|
||||
|
||||
```shell
|
||||
go get github.com/mailru/easyjson github.com/masseelch/render github.com/go-chi/chi/v5 go.uber.org/zap
|
||||
```
|
||||
|
||||
With these steps complete, all is set up for using our `elk`-powered ent! To learn more about Ent, how to connect to
|
||||
different types of databases, run migrations or work with entities head over to
|
||||
the [Setup Tutorial](https://entgo.io/docs/tutorial-setup/).
|
||||
|
||||
### Generating HTTP CRUD Handlers with `elk`
|
||||
|
||||
To generate the fully-working HTTP handlers we need first create an Ent schema definition. Open and
|
||||
edit `ent/schema/pet.go`:
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// Pet holds the schema definition for the Pet entity.
|
||||
type Pet struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Pet.
|
||||
func (Pet) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.Int("age"),
|
||||
}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
We added two fields to our `Pet` entity: `name` and `age`. The `ent.Schema` just defines the fields of our entity. To
|
||||
generate runnable code from our schema, run:
|
||||
|
||||
```shell
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Observe that in addition to the files Ent would normally generate, another directory named `ent/http` was created. These
|
||||
files were generated by the `elk` extension and contain the code for the generated HTTP handlers. For example, here
|
||||
is some of the generated code for a read-operation on the Pet entity:
|
||||
|
||||
```go
|
||||
const (
|
||||
PetCreate Routes = 1 << iota
|
||||
PetRead
|
||||
PetUpdate
|
||||
PetDelete
|
||||
PetList
|
||||
PetRoutes = 1<<iota - 1
|
||||
)
|
||||
|
||||
// PetHandler handles http crud operations on ent.Pet.
|
||||
type PetHandler struct {
|
||||
handler
|
||||
|
||||
client *ent.Client
|
||||
log *zap.Logger
|
||||
}
|
||||
|
||||
func NewPetHandler(c *ent.Client, l *zap.Logger) *PetHandler {
|
||||
return &PetHandler{
|
||||
client: c,
|
||||
log: l.With(zap.String("handler", "PetHandler")),
|
||||
}
|
||||
}
|
||||
|
||||
// Read fetches the ent.Pet identified by a given url-parameter from the
|
||||
// database and renders it to the client.
|
||||
func (h *PetHandler) Read(w http.ResponseWriter, r *http.Request) {
|
||||
l := h.log.With(zap.String("method", "Read"))
|
||||
// ID is URL parameter.
|
||||
id, err := strconv.Atoi(chi.URLParam(r, "id"))
|
||||
if err != nil {
|
||||
l.Error("error getting id from url parameter", zap.String("id", chi.URLParam(r, "id")), zap.Error(err))
|
||||
render.BadRequest(w, r, "id must be an integer greater zero")
|
||||
return
|
||||
}
|
||||
// Create the query to fetch the Pet
|
||||
q := h.client.Pet.Query().Where(pet.ID(id))
|
||||
e, err := q.Only(r.Context())
|
||||
if err != nil {
|
||||
switch {
|
||||
case ent.IsNotFound(err):
|
||||
msg := stripEntError(err)
|
||||
l.Info(msg, zap.Error(err), zap.Int("id", id))
|
||||
render.NotFound(w, r, msg)
|
||||
case ent.IsNotSingular(err):
|
||||
msg := stripEntError(err)
|
||||
l.Error(msg, zap.Error(err), zap.Int("id", id))
|
||||
render.BadRequest(w, r, msg)
|
||||
default:
|
||||
l.Error("could not read pet", zap.Error(err), zap.Int("id", id))
|
||||
render.InternalServerError(w, r, nil)
|
||||
}
|
||||
return
|
||||
}
|
||||
l.Info("pet rendered", zap.Int("id", id))
|
||||
easyjson.MarshalToHTTPResponseWriter(NewPet2657988899View(e), w)
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
Next, let’s see how to create an actual RESTful HTTP server that can manage your Pet entities. Create a file
|
||||
named `main.go` and add the following content:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"fmt"
|
||||
"log"
|
||||
"net/http"
|
||||
|
||||
"elk-example/ent"
|
||||
elk "elk-example/ent/http"
|
||||
|
||||
"github.com/go-chi/chi/v5"
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
"go.uber.org/zap"
|
||||
)
|
||||
|
||||
func main() {
|
||||
// Create the ent client.
|
||||
c, err := ent.Open("sqlite3", "./ent.db?_fk=1")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to sqlite: %v", err)
|
||||
}
|
||||
defer c.Close()
|
||||
// Run the auto migration tool.
|
||||
if err := c.Schema.Create(context.Background()); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
// Router and Logger.
|
||||
r, l := chi.NewRouter(), zap.NewExample()
|
||||
// Create the pet handler.
|
||||
r.Route("/pets", func(r chi.Router) {
|
||||
elk.NewPetHandler(c, l).Mount(r, elk.PetRoutes)
|
||||
})
|
||||
// Start listen to incoming requests.
|
||||
fmt.Println("Server running")
|
||||
defer fmt.Println("Server stopped")
|
||||
if err := http.ListenAndServe(":8080", r); err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
Next, start the server:
|
||||
|
||||
```shell
|
||||
go run -mod=mod main.go
|
||||
```
|
||||
|
||||
Congratulations! We now have a running server serving the Pets API. We could ask the server for a list of all pets in
|
||||
the database, but there are none yet. Let’s create one first:
|
||||
|
||||
```shell
|
||||
curl -X 'POST' -H 'Content-Type: application/json' -d '{"name":"Kuro","age":3}' 'localhost:8080/pets'
|
||||
```
|
||||
|
||||
You should get this response:
|
||||
|
||||
```json
|
||||
{
|
||||
"age": 3,
|
||||
"id": 1,
|
||||
"name": "Kuro"
|
||||
}
|
||||
```
|
||||
|
||||
If you head over to the terminal where the server is running you can also see `elk`s built in logging:
|
||||
|
||||
```json
|
||||
{
|
||||
"level": "info",
|
||||
"msg": "pet rendered",
|
||||
"handler": "PetHandler",
|
||||
"method": "Create",
|
||||
"id": 1
|
||||
}
|
||||
```
|
||||
|
||||
`elk` uses [zap](https://github.com/uber-go/zap) for logging. To learn more about it, have a look at its documentation.
|
||||
|
||||
### Relations
|
||||
|
||||
To illustrate more of `elk`s features, let’s extend our graph. Edit `ent/schema/user.go` and `ent/schema/pet.go`:
|
||||
|
||||
```go title="ent/schema/pet.go"
|
||||
// Edges of the Pet.
|
||||
func (Pet) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("owner", User.Type).
|
||||
Ref("pets").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/edge"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.Int("age"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the User.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("pets", Pet.Type),
|
||||
}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
We have now created a One-To-Many relation between the Pet and User schemas: A pet belongs to a user, and a user can
|
||||
have multiple pets.
|
||||
|
||||
Rerun the code generator:
|
||||
|
||||
```shell
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Do not forget to register the `UserHandler` on our router. Just add the following lines to `main.go`:
|
||||
|
||||
```diff
|
||||
[...]
|
||||
r.Route("/pets", func(r chi.Router) {
|
||||
elk.NewPetHandler(c, l, v).Mount(r, elk.PetRoutes)
|
||||
})
|
||||
+ // Create the user handler.
|
||||
+ r.Route("/users", func(r chi.Router) {
|
||||
+ elk.NewUserHandler(c, l, v).Mount(r, elk.UserRoutes)
|
||||
+ })
|
||||
// Start listen to incoming requests.
|
||||
fmt.Println("Server running")
|
||||
[...]
|
||||
```
|
||||
|
||||
After restarting the server we can create a `User` that owns the previously created Pet named Kuro:
|
||||
|
||||
```shell
|
||||
curl -X 'POST' -H 'Content-Type: application/json' -d '{"name":"Elk","age":30,"owner":1}' 'localhost:8080/users'
|
||||
```
|
||||
|
||||
The server returns the following response:
|
||||
|
||||
```json
|
||||
{
|
||||
"age": 30,
|
||||
"edges": {},
|
||||
"id": 1,
|
||||
"name": "Elk"
|
||||
}
|
||||
```
|
||||
|
||||
From the output we can see that the user has been created, but the edges are empty. `elk` does not include edges in its
|
||||
output by default. You can configure `elk` to render edges using a feature called "serialization groups". Annotate your
|
||||
schemas with the `elk.SchemaAnnotation`
|
||||
and `elk.Annotation` structs. Edit `ent/schema/user.go` and add those:
|
||||
|
||||
```go
|
||||
// Edges of the User.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("pets", Pet.Type).
|
||||
Annotations(elk.Groups("user")),
|
||||
}
|
||||
}
|
||||
|
||||
// Annotations of the User.
|
||||
func (User) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{elk.ReadGroups("user")}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
The `elk.Annotation`s added to the fields and edges tell elk to eager-load them and add them to the payload if the "
|
||||
user" group is requested. The `elk.SchemaAnnotation` is used to make the read-operation of the `UserHandler` request "
|
||||
user". Note, that any fields that do not have a serialization group attached are included by default. Edges, however,
|
||||
are excluded, unless configured otherwise.
|
||||
|
||||
Next, let’s regenerate the code once again, and restart the server. You should now see the pets of a user rendered if
|
||||
you read a resource:
|
||||
|
||||
```shell
|
||||
curl 'localhost:8080/users/1'
|
||||
```
|
||||
|
||||
```json
|
||||
{
|
||||
"age": 30,
|
||||
"edges": {
|
||||
"pets": [
|
||||
{
|
||||
"id": 1,
|
||||
"name": "Kuro",
|
||||
"age": 3,
|
||||
"edges": {}
|
||||
}
|
||||
]
|
||||
},
|
||||
"id": 1,
|
||||
"name": "Elk"
|
||||
}
|
||||
```
|
||||
|
||||
### Request validation
|
||||
|
||||
Our current schemas allow to set a negative age for pets or users and we can create pets without an owner (as we did
|
||||
with Kuro). Ent has built-in support for basic [validation](https://entgo.io/docs/schema-fields#validators). In some
|
||||
cases you may want to validate requests made against your API before passing their payload to Ent. `elk`
|
||||
uses [this](https://github.com/go-playground/validator) package to define validation rules and validate data. We can
|
||||
create separate validation rules for Create and Update operations using `elk.Annotation`. In our example, let’s assume
|
||||
that we want our Pet schema to only allow ages greater than zero and to disallow creating a pet without an owner.
|
||||
Edit `ent/schema/pet.go`:
|
||||
|
||||
```go
|
||||
// Fields of the Pet.
|
||||
func (Pet) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.Int("age").
|
||||
Positive().
|
||||
Annotations(
|
||||
elk.CreateValidation("required,gt=0"),
|
||||
elk.UpdateValidation("gt=0"),
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Pet.
|
||||
func (Pet) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("owner", User.Type).
|
||||
Ref("pets").
|
||||
Unique().
|
||||
Required().
|
||||
Annotations(elk.Validation("required")),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Next, regenerate the code and restart the server. To test our new validation rules, let’s try to create a pet with
|
||||
invalid age and without an owner:
|
||||
|
||||
```shell
|
||||
curl -X 'POST' -H 'Content-Type: application/json' -d '{"name":"Bob","age":-2}' 'localhost:8080/pets'
|
||||
```
|
||||
|
||||
`elk` returns a detailed response that includes information about which validations failed:
|
||||
|
||||
```json
|
||||
{
|
||||
"code": 400,
|
||||
"status": "Bad Request",
|
||||
"errors": {
|
||||
"Age": "This value failed validation on 'gt:0'.",
|
||||
"Owner": "This value is required."
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Note the uppercase field names. The validator package uses the structs field name to generate its validation errors, but
|
||||
you can simply override this, as stated in
|
||||
the [example](https://github.com/go-playground/validator/blob/9a5bce32538f319bf69aebb3aca90d394bc6d0cb/_examples/struct-level/main.go#L37)
|
||||
.
|
||||
|
||||
If you do not define any validation rules, `elk` will not include the validation-code in its generated output. `elk`s`
|
||||
request validation is especially useful if you'd wanted to do cross-field-validation.
|
||||
|
||||
### Upcoming Features
|
||||
|
||||
We hope you agree that `elk` has some useful features already, but there are still many exciting things to come. The
|
||||
next version of `elk` will include::
|
||||
|
||||
- Fully working flutter frontend to administrate your nodes
|
||||
- Integration of Ent’s validation in the current request validator
|
||||
- More transport formats (currently only JSON)
|
||||
|
||||
### Conclusion
|
||||
|
||||
This post has shown just a small part of what `elk` can do. To see some more examples of what you can do with it, head
|
||||
over to the project’s README on GitHub. I hope that with `elk`-powered Ent, you and your fellow developers can automate
|
||||
some repetitive tasks that go into building RESTful APIs and focus on more meaningful work.
|
||||
|
||||
`elk` is in an early stage of development, we welcome any suggestion or feedback and if you are willing to help we'd be
|
||||
very glad. The [GitHub Issues](https://github.com/masseelch/elk/issues) is a wonderful place for you to reach out for
|
||||
help, feedback, suggestions and contribution.
|
||||
|
||||
#### About the Author
|
||||
|
||||
_MasseElch is a software engineer from the windy, flat, north of Germany. When not hiking with his dog Kuro (who has his
|
||||
own Instagram channel :scream:) or playing hide-and-seek with his son, he drinks coffee and enjoys coding._
|
||||
283
doc/website/blog/2021-08-05-announcing-upsert-api.md
Normal file
283
doc/website/blog/2021-08-05-announcing-upsert-api.md
Normal file
@@ -0,0 +1,283 @@
|
||||
---
|
||||
title: Announcing the Upsert API in v0.9.0
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
---
|
||||
|
||||
|
||||
It has been almost 4 months since our [last release](https://github.com/ent/ent/releases/tag/v0.8.0), and for a good reason.
|
||||
Version [0.9.0](https://github.com/ent/ent/releases/tag/v0.9.0) which was released today is packed with some highly-anticipated
|
||||
features. Perhaps at the top of the list, is a feature that has been in discussion for [more than a year in a half](https://github.com/ent/ent/issues/139)
|
||||
and was one of the most commonly requested features in the [Ent User Survey](https://forms.gle/7VZSPVc7D1iu75GV9): the Upsert API!
|
||||
|
||||
Version 0.9.0 adds support for "Upsert" style statements using [a new feature flag](https://entgo.io/docs/feature-flags#upsert): `sql/upsert`.
|
||||
Ent has a [collection of feature flags](https://entgo.io/docs/feature-flags) that can be switched on to add more features
|
||||
to the code generated by Ent. This is used as both a mechanism to allow opt-in to some features that are not necessarily
|
||||
desired in every project and as a way to run experiments of features that may one day become part of Ent's core.
|
||||
|
||||
In this post, we will introduce the new feature, the places where it is useful, and demonstrate how to use it.
|
||||
|
||||
### Upsert
|
||||
|
||||
"Upsert" is a commonly-used term in data systems that is a portmanteau of "update" and "insert" which usually refers to
|
||||
a statement that attempts to insert a record to a table, and if a uniqueness constraint is violated (e.g. a record by
|
||||
that ID already exists) that record is updated instead. While none of the popular relational databases have a specific
|
||||
`UPSERT` statement, most of them support ways of achieving this type of behavior.
|
||||
|
||||
For example, assume we have a table with this definition in an SQLite database:
|
||||
|
||||
```sql
|
||||
CREATE TABLE users (
|
||||
id integer PRIMARY KEY AUTOINCREMENT,
|
||||
email varchar(255) UNIQUE,
|
||||
name varchar(255)
|
||||
)
|
||||
```
|
||||
|
||||
If we try to execute the same insert twice:
|
||||
|
||||
```sql
|
||||
INSERT INTO users (email, name) VALUES ('rotem@entgo.io', 'Rotem Tamir');
|
||||
INSERT INTO users (email, name) VALUES ('rotem@entgo.io', 'Rotem Tamir');
|
||||
```
|
||||
|
||||
We get this error:
|
||||
|
||||
```
|
||||
[2021-08-05 06:49:22] UNIQUE constraint failed: users.email
|
||||
```
|
||||
|
||||
In many cases, it is useful to have write operations be [idempotent](https://en.wikipedia.org/wiki/Idempotence),
|
||||
meaning we can run them many times in a row while leaving the system in the same state.
|
||||
|
||||
In other cases, it is not desirable to query if a record exists before trying to create it. For these kinds of situations,
|
||||
SQLite supports the [`ON CONFLICT` clause](https://www.sqlite.org/lang_upsert.html) in `INSERT`
|
||||
statements. To instruct SQLite to override an existing value with the new one we can execute:
|
||||
|
||||
```sql
|
||||
INSERT INTO users (email, name) values ('rotem@entgo.io', 'Tamir, Rotem')
|
||||
ON CONFLICT (email) DO UPDATE SET email=excluded.email, name=excluded.name;
|
||||
```
|
||||
|
||||
If we prefer to keep the existing values, we can use the `DO NOTHING` conflict action:
|
||||
|
||||
```sql
|
||||
INSERT INTO users (email, name) values ('rotem@entgo.io', 'Tamir, Rotem')
|
||||
ON CONFLICT DO NOTHING;
|
||||
```
|
||||
|
||||
Sometimes we want to merge the two versions in some way, we can use the `DO UPDATE` action a little differently to
|
||||
achieve do something like:
|
||||
|
||||
```sql
|
||||
INSERT INTO users (email, full_name) values ('rotem@entgo.io', 'Tamir, Rotem')
|
||||
ON CONFLICT (email) DO UPDATE SET name=excluded.name || ' (formerly: ' || users.name || ')'
|
||||
```
|
||||
|
||||
In this case, after our second `INSERT` the value for the `name` column would be: `Tamir, Rotem (formerly: Rotem Tamir)`.
|
||||
Not very useful, but hopefully you can see that you can do cool things this way.
|
||||
|
||||
### Upsert with Ent
|
||||
|
||||
Assume we have an existing Ent project with an entity similar to the `users` table described above:
|
||||
|
||||
```go
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("email").
|
||||
Unique(),
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
As the Upsert API is a newly released feature, make sure to update your `ent` version using:
|
||||
|
||||
```bash
|
||||
go get -u entgo.io/ent@v0.9.0
|
||||
```
|
||||
|
||||
Next, add the `sql/upsert` feature flag to your code-generation flags, in `ent/generate.go`:
|
||||
|
||||
```go
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entgo.io/ent/cmd/ent generate --feature sql/upsert ./schema
|
||||
```
|
||||
|
||||
Next, re-run code generation for your project:
|
||||
|
||||
```go
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Observe that a new method named `OnConflict` was added to the `ent/user_create.go` file:
|
||||
|
||||
```go
|
||||
// OnConflict allows configuring the `ON CONFLICT` / `ON DUPLICATE KEY` clause
|
||||
// of the `INSERT` statement. For example:
|
||||
//
|
||||
// client.User.Create().
|
||||
// SetEmailAddress(v).
|
||||
// OnConflict(
|
||||
// // Update the row with the new values
|
||||
// // the was proposed for insertion.
|
||||
// sql.ResolveWithNewValues(),
|
||||
// ).
|
||||
// // Override some of the fields with custom
|
||||
// // update values.
|
||||
// Update(func(u *ent.UserUpsert) {
|
||||
// SetEmailAddress(v+v)
|
||||
// }).
|
||||
// Exec(ctx)
|
||||
//
|
||||
func (uc *UserCreate) OnConflict(opts ...sql.ConflictOption) *UserUpsertOne {
|
||||
uc.conflict = opts
|
||||
return &UserUpsertOne{
|
||||
create: uc,
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
This (along with more new generated code) will serve us in achieving upsert behavior for our `User` entity.
|
||||
To explore this, let's first start by writing a test to reproduce the uniqueness constraint error:
|
||||
|
||||
```go
|
||||
func TestUniqueConstraintFails(t *testing.T) {
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
ctx := context.TODO()
|
||||
|
||||
// Create the user for the first time.
|
||||
client.User.
|
||||
Create().
|
||||
SetEmail("rotem@entgo.io").
|
||||
SetName("Rotem Tamir").
|
||||
SaveX(ctx)
|
||||
|
||||
// Try to create a user with the same email the second time.
|
||||
_, err := client.User.
|
||||
Create().
|
||||
SetEmail("rotem@entgo.io").
|
||||
SetName("Rotem Tamir").
|
||||
Save(ctx)
|
||||
|
||||
if !ent.IsConstraintError(err) {
|
||||
log.Fatalf("expected second created to fail with constraint error")
|
||||
}
|
||||
log.Printf("second query failed with: %v", err)
|
||||
}
|
||||
```
|
||||
|
||||
The test passes:
|
||||
|
||||
```bash
|
||||
=== RUN TestUniqueConstraintFails
|
||||
2021/08/05 07:12:11 second query failed with: ent: constraint failed: insert node to table "users": UNIQUE constraint failed: users.email
|
||||
--- PASS: TestUniqueConstraintFails (0.00s)
|
||||
```
|
||||
|
||||
Next, let's see how to instruct Ent to override the existing values with the new in case a conflict occurs:
|
||||
|
||||
```go
|
||||
func TestUpsertReplace(t *testing.T) {
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
ctx := context.TODO()
|
||||
|
||||
// Create the user for the first time.
|
||||
orig := client.User.
|
||||
Create().
|
||||
SetEmail("rotem@entgo.io").
|
||||
SetName("Rotem Tamir").
|
||||
SaveX(ctx)
|
||||
|
||||
// Try to create a user with the same email the second time.
|
||||
// This time we set ON CONFLICT behavior, and use the `UpdateNewValues`
|
||||
// modifier.
|
||||
newID := client.User.Create().
|
||||
SetEmail("rotem@entgo.io").
|
||||
SetName("Tamir, Rotem").
|
||||
OnConflict().
|
||||
UpdateNewValues().
|
||||
// we use the IDX method to receive the ID
|
||||
// of the created/updated entity
|
||||
IDX(ctx)
|
||||
|
||||
// We expect the ID of the originally created user to be the same as
|
||||
// the one that was just updated.
|
||||
if orig.ID != newID {
|
||||
log.Fatalf("expected upsert to update an existing record")
|
||||
}
|
||||
|
||||
current := client.User.GetX(ctx, orig.ID)
|
||||
if current.Name != "Tamir, Rotem" {
|
||||
log.Fatalf("expected upsert to replace with the new values")
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Running our test:
|
||||
|
||||
```bash
|
||||
=== RUN TestUpsertReplace
|
||||
--- PASS: TestUpsertReplace (0.00s)
|
||||
```
|
||||
|
||||
Alternatively, we can use the `Ignore` modifier to instruct Ent to keep the old version when resolving the conflict.
|
||||
Let's write a test that shows this:
|
||||
|
||||
```go
|
||||
func TestUpsertIgnore(t *testing.T) {
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
ctx := context.TODO()
|
||||
|
||||
// Create the user for the first time.
|
||||
orig := client.User.
|
||||
Create().
|
||||
SetEmail("rotem@entgo.io").
|
||||
SetName("Rotem Tamir").
|
||||
SaveX(ctx)
|
||||
|
||||
// Try to create a user with the same email the second time.
|
||||
// This time we set ON CONFLICT behavior, and use the `Ignore`
|
||||
// modifier.
|
||||
client.User.
|
||||
Create().
|
||||
SetEmail("rotem@entgo.io").
|
||||
SetName("Tamir, Rotem").
|
||||
OnConflict().
|
||||
Ignore().
|
||||
ExecX(ctx)
|
||||
|
||||
current := client.User.GetX(ctx, orig.ID)
|
||||
if current.FullName != orig.FullName {
|
||||
log.Fatalf("expected upsert to keep the original version")
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
You can read more about the feature in the [Feature Flag](https://entgo.io/docs/feature-flags#upsert) or [Upsert API](https://entgo.io/docs/crud#upsert-one) documentation.
|
||||
|
||||
### Wrapping Up
|
||||
|
||||
In this post, we presented the Upsert API, a long-anticipated capability, that is available by feature-flag in Ent v0.9.0.
|
||||
We discussed where upserts are commonly used in applications and the way they are implemented using common relational databases.
|
||||
Finally, we showed a simple example of how to get started with the Upsert API using Ent.
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack/).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
@@ -0,0 +1,371 @@
|
||||
---
|
||||
title: Building Observable Ent Applications with Prometheus
|
||||
author: Yoni Davidson
|
||||
authorURL: "https://github.com/yonidavidson"
|
||||
authorImageURL: "https://avatars0.githubusercontent.com/u/5472778"
|
||||
authorTwitter: yonidavidson
|
||||
---
|
||||
|
||||
Observability is a quality of a system that refers to how well its internal state can be measured externally.
|
||||
As a computer program evolves into a full-blown production system this quality becomes increasingly important.
|
||||
One of the ways to make a software system more observable is to export metrics, that is, to report in some externally
|
||||
visible way a quantitative description of the running system's state. For instance, to expose an HTTP endpoint where we
|
||||
can see how many errors occurred since the process has started. In this post, we will explore how to build more
|
||||
observable Ent applications using Prometheus.
|
||||
|
||||
### What is Ent?
|
||||
|
||||
[Ent](https://entgo.io/docs/getting-started/), is a simple, yet powerful entity framework for Go, that makes it easy
|
||||
to build and maintain applications with large data models.
|
||||
|
||||
### What is Prometheus?
|
||||
|
||||
[Prometheus](https://prometheus.io/) is an open source monitoring system developed by engineering at SoundCloud in 2012.
|
||||
It includes an embedded time series database and many integrations to third-party systems.
|
||||
The Prometheus client exposes the process's metrics via an HTTP endpoint (usually `/metrics`), this endpoint is
|
||||
discovered by the Prometheus scraper which polls the endpoint every interval (typically 30s) and writes it
|
||||
into a time-series database.
|
||||
|
||||
Prometheus is just an example of a class of metric collection backends. Many others, such as AWS CloudWatch, InfluxDB
|
||||
and others exist and are in wide use in the industry. Towards the end of this post, we will discuss a possible path to
|
||||
a unified, standards-based integration with any such backend.
|
||||
|
||||
### Working with Prometheus
|
||||
|
||||
To expose an application's metrics using Prometheus, we need to create a
|
||||
Prometheus [Collector](https://prometheus.io/docs/introduction/glossary/#collector), a collector collects
|
||||
a set of metrics from your server.
|
||||
|
||||
In our example, we will be using [two types of metrics](https://prometheus.io/docs/concepts/metric_types/)
|
||||
that can be stored in a collector: Counters and Histograms. Counters are monotonically increasing cumulative metrics
|
||||
that represent how many times something has happened, commonly used to count the number of requests a server has
|
||||
processed or errors that have occurred. Histograms sample observations into buckets of configurable sizes and are
|
||||
commonly used to represent latency distributions (i.e how many requests returned in under 5ms, 10ms, 100ms, 1s, etc.)
|
||||
In addition, Prometheus allows metrics to be broken down into labels. This is useful for example for counting requests
|
||||
but breaking down the counter by endpoint name.
|
||||
|
||||
Let’s see how to create such a collector using the [official Go client](https://github.com/prometheus/client_golang).
|
||||
To do so, we will use a package in the client called [promauto](https://pkg.go.dev/github.com/prometheus/client_golang@v1.11.0/prometheus/promauto) that simplifies the processes of creating collectors.
|
||||
A simple example of a collector that counts (for example, total request or number or request error):
|
||||
|
||||
```go
|
||||
package example
|
||||
|
||||
import (
|
||||
"github.com/prometheus/client_golang/prometheus"
|
||||
"github.com/prometheus/client_golang/prometheus/promauto"
|
||||
)
|
||||
|
||||
var (
|
||||
// List of dynamic labels
|
||||
labelNames = []string{"endpoint", "error_code"}
|
||||
|
||||
// Create a counter collector
|
||||
exampleCollector = promauto.NewCounterVec(
|
||||
prometheus.CounterOpts{
|
||||
Name: "endpoint_errors",
|
||||
Help: "Number of errors in endpoints",
|
||||
},
|
||||
labelNames,
|
||||
)
|
||||
)
|
||||
|
||||
// When using you set the values of the dynamic labels and then increment the counter
|
||||
func incrementError() {
|
||||
exampleCollector.WithLabelValues("/create-user", "400").Inc()
|
||||
}
|
||||
```
|
||||
|
||||
### Ent Hooks
|
||||
|
||||
[Hooks](https://entgo.io/docs/hooks) are a feature of Ent that allows adding custom logic before and after operations that change the data entities.
|
||||
|
||||
A mutation is an operation that changes something in the database.
|
||||
There are 5 types of mutations:
|
||||
1. Create.
|
||||
2. UpdateOne.
|
||||
3. Update.
|
||||
4. DeleteOne.
|
||||
5. Delete.
|
||||
|
||||
Hooks are functions that get an [ent.Mutator](https://pkg.go.dev/entgo.io/ent#Mutator) and return a mutator back.
|
||||
They function similar to the popular [HTTP middleware pattern](https://github.com/go-chi/chi#middleware-handlers).
|
||||
|
||||
```go
|
||||
package example
|
||||
|
||||
import (
|
||||
"context"
|
||||
|
||||
"entgo.io/ent"
|
||||
)
|
||||
|
||||
func exampleHook() ent.Hook {
|
||||
//use this to init your hook
|
||||
return func(next ent.Mutator) ent.Mutator {
|
||||
return ent.MutateFunc(func(ctx context.Context, m ent.Mutation) (ent.Value, error) {
|
||||
// Do something before mutation.
|
||||
v, err := next.Mutate(ctx, m)
|
||||
if err != nil {
|
||||
// Do something if error after mutation.
|
||||
}
|
||||
// Do something after mutation.
|
||||
return v, err
|
||||
})
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
In Ent, there are two types of mutation hooks - schema hooks and runtime hooks. Schema hooks are mainly used for defining
|
||||
custom mutation logic on a specific entity type, for example, syncing entity creation to another system. Runtime hooks, on the other hand, are used
|
||||
to define more global logic for adding things like logging, metrics, tracing, etc.
|
||||
|
||||
For our use case, we should definitely use runtime hooks, because to be valuable we want to export metrics on all
|
||||
operations on all entity types:
|
||||
|
||||
```go
|
||||
package example
|
||||
|
||||
import (
|
||||
"entprom/ent"
|
||||
"entprom/ent/hook"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, _ := ent.Open("sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
|
||||
// Add a hook only on user mutations.
|
||||
client.User.Use(exampleHook())
|
||||
|
||||
// Add a hook only on update operations.
|
||||
client.Use(hook.On(exampleHook(), ent.OpUpdate|ent.OpUpdateOne))
|
||||
}
|
||||
```
|
||||
|
||||
### Exporting Prometheus Metrics for an Ent Application
|
||||
|
||||
With all of the introductions complete, let’s cut to the chase and show how to use Prometheus and Ent hooks together to
|
||||
create an observable application. Our goal with this example is to export these metrics using a hook:
|
||||
|
||||
| Metric Name | Description |
|
||||
|--------------------------------|------------------------------------------|
|
||||
| ent_operation_total | Number of ent mutation operations |
|
||||
| ent_operation_error | Number of failed ent mutation operations |
|
||||
| ent_operation_duration_seconds | Time in seconds per operation |
|
||||
|
||||
|
||||
Each of these metrics will be broken down by labels into two dimensions:
|
||||
* `mutation_type`: Entity type that is being mutated (User, BlogPost, Account etc.).
|
||||
* `mutation_op`: The operation that is being performed (Create, Delete etc.).
|
||||
|
||||
Let’s start by defining our collectors:
|
||||
|
||||
```go
|
||||
//Ent dynamic dimensions
|
||||
const (
|
||||
mutationType = "mutation_type"
|
||||
mutationOp = "mutation_op"
|
||||
)
|
||||
|
||||
var entLabels = []string{mutationType, mutationOp}
|
||||
|
||||
// Create a collector for total operations counter
|
||||
func initOpsProcessedTotal() *prometheus.CounterVec {
|
||||
return promauto.NewCounterVec(
|
||||
prometheus.CounterOpts{
|
||||
Name: "ent_operation_total",
|
||||
Help: "Number of ent mutation operations",
|
||||
},
|
||||
entLabels,
|
||||
)
|
||||
}
|
||||
|
||||
// Create a collector for error counter
|
||||
func initOpsProcessedError() *prometheus.CounterVec {
|
||||
return promauto.NewCounterVec(
|
||||
prometheus.CounterOpts{
|
||||
Name: "ent_operation_error",
|
||||
Help: "Number of failed ent mutation operations",
|
||||
},
|
||||
entLabels,
|
||||
)
|
||||
}
|
||||
|
||||
// Create a collector for duration histogram collector
|
||||
func initOpsDuration() *prometheus.HistogramVec {
|
||||
return promauto.NewHistogramVec(
|
||||
prometheus.HistogramOpts{
|
||||
Name: "ent_operation_duration_seconds",
|
||||
Help: "Time in seconds per operation",
|
||||
},
|
||||
entLabels,
|
||||
)
|
||||
}
|
||||
```
|
||||
Next, let’s define our new hook:
|
||||
|
||||
```go
|
||||
// Hook init collectors, count total at beginning error on mutation error and duration also after.
|
||||
func Hook() ent.Hook {
|
||||
opsProcessedTotal := initOpsProcessedTotal()
|
||||
opsProcessedError := initOpsProcessedError()
|
||||
opsDuration := initOpsDuration()
|
||||
return func(next ent.Mutator) ent.Mutator {
|
||||
return ent.MutateFunc(func(ctx context.Context, m ent.Mutation) (ent.Value, error) {
|
||||
// Before mutation, start measuring time.
|
||||
start := time.Now()
|
||||
// Extract dynamic labels from mutation.
|
||||
labels := prometheus.Labels{mutationType: m.Type(), mutationOp: m.Op().String()}
|
||||
// Increment total ops counter.
|
||||
opsProcessedTotal.With(labels).Inc()
|
||||
// Execute mutation.
|
||||
v, err := next.Mutate(ctx, m)
|
||||
if err != nil {
|
||||
// In case of error increment error counter.
|
||||
opsProcessedError.With(labels).Inc()
|
||||
}
|
||||
// Stop time measure.
|
||||
duration := time.Since(start)
|
||||
// Record duration in seconds.
|
||||
opsDuration.With(labels).Observe(duration.Seconds())
|
||||
return v, err
|
||||
})
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Connecting the Prometheus Collector to our Service
|
||||
|
||||
After defining our hook, let’s see next how to connect it to our application and how to use Prometheus to serve
|
||||
an endpoint that exposes the metrics in our collectors:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"net/http"
|
||||
|
||||
"entprom"
|
||||
"entprom/ent"
|
||||
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
"github.com/prometheus/client_golang/prometheus/promhttp"
|
||||
)
|
||||
|
||||
func createClient() *ent.Client {
|
||||
c, err := ent.Open("sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to sqlite: %v", err)
|
||||
}
|
||||
ctx := context.Background()
|
||||
// Run the auto migration tool.
|
||||
if err := c.Schema.Create(ctx); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
return c
|
||||
}
|
||||
|
||||
func handler(client *ent.Client) func(w http.ResponseWriter, r *http.Request) {
|
||||
return func(w http.ResponseWriter, r *http.Request) {
|
||||
ctx := context.Background()
|
||||
// Run operations.
|
||||
_, err := client.User.Create().SetName("a8m").Save(ctx)
|
||||
if err != nil {
|
||||
http.Error(w, err.Error(), http.StatusBadRequest)
|
||||
return
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
func main() {
|
||||
// Create Ent client and migrate
|
||||
client := createClient()
|
||||
// Use the hook
|
||||
client.Use(entprom.Hook())
|
||||
// Simple handler to run actions on our DB.
|
||||
http.HandleFunc("/", handler(client))
|
||||
// This endpoint sends metrics to the prometheus to collect
|
||||
http.Handle("/metrics", promhttp.Handler())
|
||||
log.Println("server starting on port 8080")
|
||||
// Run the server
|
||||
log.Fatal(http.ListenAndServe(":8080", nil))
|
||||
}
|
||||
```
|
||||
|
||||
After a few times of accessing `/` on our server (using `curl` or a browser), go to `/metrics`. There you will see the output from the Prometheus client:
|
||||
|
||||
```
|
||||
# HELP ent_operation_duration_seconds Time in seconds per operation
|
||||
# TYPE ent_operation_duration_seconds histogram
|
||||
ent_operation_duration_seconds_bucket{mutation_op="OpCreate",mutation_type="User",le="0.005"} 2
|
||||
ent_operation_duration_seconds_bucket{mutation_op="OpCreate",mutation_type="User",le="0.01"} 2
|
||||
ent_operation_duration_seconds_bucket{mutation_op="OpCreate",mutation_type="User",le="0.025"} 2
|
||||
ent_operation_duration_seconds_bucket{mutation_op="OpCreate",mutation_type="User",le="0.05"} 2
|
||||
ent_operation_duration_seconds_bucket{mutation_op="OpCreate",mutation_type="User",le="0.1"} 2
|
||||
ent_operation_duration_seconds_bucket{mutation_op="OpCreate",mutation_type="User",le="0.25"} 2
|
||||
ent_operation_duration_seconds_bucket{mutation_op="OpCreate",mutation_type="User",le="0.5"} 2
|
||||
ent_operation_duration_seconds_bucket{mutation_op="OpCreate",mutation_type="User",le="1"} 2
|
||||
ent_operation_duration_seconds_bucket{mutation_op="OpCreate",mutation_type="User",le="2.5"} 2
|
||||
ent_operation_duration_seconds_bucket{mutation_op="OpCreate",mutation_type="User",le="5"} 2
|
||||
ent_operation_duration_seconds_bucket{mutation_op="OpCreate",mutation_type="User",le="10"} 2
|
||||
ent_operation_duration_seconds_bucket{mutation_op="OpCreate",mutation_type="User",le="+Inf"} 2
|
||||
ent_operation_duration_seconds_sum{mutation_op="OpCreate",mutation_type="User"} 0.000265669
|
||||
ent_operation_duration_seconds_count{mutation_op="OpCreate",mutation_type="User"} 2
|
||||
# HELP ent_operation_error Number of failed ent mutation operations
|
||||
# TYPE ent_operation_error counter
|
||||
ent_operation_error{mutation_op="OpCreate",mutation_type="User"} 1
|
||||
# HELP ent_operation_total Number of ent mutation operations
|
||||
# TYPE ent_operation_total counter
|
||||
ent_operation_total{mutation_op="OpCreate",mutation_type="User"} 2
|
||||
```
|
||||
|
||||
In the top part, we can see the histogram calculated, it calculates the number of operations in each “bucket”.
|
||||
After that, we can see the number of total operations and the number of errors.
|
||||
Each metric is followed by its description that can be seen when querying with Prometheus dashboard.
|
||||
|
||||
The Prometheus client is only one component of the Prometheus architecture.
|
||||
To run a complete system including a scraper that will poll your endpoint, a Prometheus that will store your
|
||||
metrics and can answer queries, and a simple UI to interact with it, I recommend reading the official
|
||||
documentation or use the docker-compose.yaml in this example [repo](https://github.com/yonidavidson/ent-prometheus-example).
|
||||
|
||||
### Future Work on Observability in Ent
|
||||
|
||||
As we’ve mentioned above, there is an abundance of metric collections backends available today,
|
||||
Prometheus being just one of many successful projects. While these solutions differ in many dimensions
|
||||
(self-hosted vs SaaS, different storage engines with different query languages, and more) - from the metric
|
||||
reporting client perspective, they are virtually identical.
|
||||
|
||||
In cases like these, good software engineering principles suggest that the concrete backend should be abstracted away
|
||||
from the client using an interface. This interface can then be implemented by backends so client applications can easily
|
||||
switch between the different implementations. Such changes are happening in recent years in our industry. Consider,
|
||||
for example, the [Open Container Initiative](https://opencontainers.org/) or the
|
||||
[Service Mesh Interface](https://smi-spec.io/): both are initiatives that strive to define a standard interface
|
||||
for a problem space. This interface is supposed to create an ecosystem of implementations of
|
||||
the standard. In the observability space, the exact same convergence is occurring with [OpenCensus](https://opencensus.io/) and
|
||||
[OpenTracing](https://opentracing.io/) currently merging into [OpenTelemetry](https://opentelemetry.io/).
|
||||
|
||||
As nice as it would be to publish an Ent + Prometheus extension similar to the one presented in this post, we are firm
|
||||
believers that observability should be solved with a standards-based approach.
|
||||
We invite everyone to [join the discussion](https://github.com/ent/ent/discussions/1819) on what is the right way to do this for Ent.
|
||||
|
||||
|
||||
### Wrap-Up
|
||||
|
||||
We started this post by presenting Prometheus, a popular open-source monitoring solution. Next, we reviewed “Hooks”, a feature
|
||||
of Ent that allows adding custom logic before and after operations that change the data entities. We then showed how
|
||||
to integrate the two to create observable applications using Ent. Finally, we discussed the future of observability in Ent
|
||||
and invited everyone to join the discussion [to shape it](https://github.com/ent/ent/discussions/1819).
|
||||
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack/).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
@@ -0,0 +1,180 @@
|
||||
---
|
||||
title: Visualizing your Data Graph Using entviz
|
||||
author: Amit Shani
|
||||
authorURL: "https://github.com/hedwigz"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/8277210?v=4"
|
||||
authorTwitter: itsamitush
|
||||
---
|
||||
|
||||
Joining an existing project with a large codebase can be a daunting task.
|
||||
|
||||
Understanding the data model of an application is key for developers to start working on an existing project. One commonly used tool to help overcome this challenge, and enable developers to grasp an application's data model is an [ER (Entity Relation) diagram](https://en.wikipedia.org/wiki/Entity%E2%80%93relationship_model).
|
||||
|
||||
ER diagrams provide a visual representation of your data model, and details each field of the entities. Many tools can help create these, where one example is Jetbrains DataGrip, that can generate an ER diagram by connecting to and inspecting an existing database:
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Datagrip ER diagram" src="https://entgo.io/images/assets/entviz/datagrip_er_diagram.png" />
|
||||
<p style={{fontSize: 12}}>DataGrip ER diagram example</p>
|
||||
</div>
|
||||
|
||||
[Ent](https://entgo.io/docs/getting-started/), a simple, yet powerful entity framework for Go, was originally developed inside Facebook specifically for dealing with projects with large and complex data models.
|
||||
This is why Ent uses code generation - it gives type-safety and code-completion out-of-the-box which helps explain the data model and improves developer velocity.
|
||||
On top of all of this, wouldn't it be great to automatically generate ER diagrams that maintain a high-level view of the data model in a visually appealing representation? (I mean, who doesn't love visualizations?)
|
||||
|
||||
### Introducing entviz
|
||||
[entviz](https://github.com/hedwigz/entviz) is an ent extension that automatically generates a static HTML page that visualizes your data graph.
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img width="600px" alt="Entviz example output" src="https://entgo.io/images/assets/entviz/entviz-example-visualization.png" />
|
||||
<p style={{fontSize: 12}}>Entviz example output</p>
|
||||
</div>
|
||||
Most ER diagram generation tools need to connect to your database and introspect it, which makes it harder to maintain an up-to-date diagram of the database schema. Since entviz integrates directly to your Ent schema, it does not need to connect to your database, and it automatically generates fresh visualization every time you modify your schema.
|
||||
|
||||
If you want to know more about how entviz was implemented, checkout the [implementation section](#implementation).
|
||||
|
||||
|
||||
### See it in action
|
||||
First, let's add the entviz extension to our entc.go file:
|
||||
```bash
|
||||
go get github.com/hedwigz/entviz
|
||||
```
|
||||
:::info
|
||||
If you are not familiar with `entc` you're welcome to read [entc documentation](https://entgo.io/docs/code-gen#use-entc-as-a-package) to learn more about it.
|
||||
:::
|
||||
```go title="ent/entc.go"
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
"github.com/hedwigz/entviz"
|
||||
)
|
||||
|
||||
func main() {
|
||||
err := entc.Generate("./schema", &gen.Config{}, entc.Extensions(entviz.Extension{}))
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
Let's say we have a simple schema with a user entity and some fields:
|
||||
```go title="ent/schema/user.go"
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.String("email"),
|
||||
field.Time("created").
|
||||
Default(time.Now),
|
||||
}
|
||||
}
|
||||
```
|
||||
Now, entviz will automatically generate a visualization of our graph everytime we run:
|
||||
```bash
|
||||
go generate ./...
|
||||
```
|
||||
You should now see a new file called `schema-viz.html` in your ent directory:
|
||||
```bash
|
||||
$ ll ./ent/schema-viz.html
|
||||
-rw-r--r-- 1 hedwigz hedwigz 7.3K Aug 27 09:00 schema-viz.html
|
||||
```
|
||||
Open the html file with your favorite browser to see the visualization
|
||||
|
||||

|
||||
|
||||
Next, let's add another entity named Post, and see how our visualization changes:
|
||||
```bash
|
||||
ent new Post
|
||||
```
|
||||
```go title="ent/schema/post.go"
|
||||
// Fields of the Post.
|
||||
func (Post) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("content"),
|
||||
field.Time("created").
|
||||
Default(time.Now),
|
||||
}
|
||||
}
|
||||
```
|
||||
Now we add an ([O2M](https://entgo.io/docs/schema-edges/#o2m-two-types)) edge from User to Post:
|
||||
```go title="ent/schema/post.go"
|
||||
// Edges of the User.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("posts", Post.Type),
|
||||
}
|
||||
}
|
||||
```
|
||||
Finally, regenerate the code:
|
||||
```bash
|
||||
go generate ./...
|
||||
```
|
||||
Refresh your browser to see the updated result!
|
||||
|
||||

|
||||
|
||||
|
||||
### Implementation
|
||||
Entviz was implemented by extending ent via its [extension API](https://github.com/ent/ent/blob/1304dc3d795b3ea2de7101c7ca745918def668ef/entc/entc.go#L197).
|
||||
The Ent extension API lets you aggregate multiple [templates](https://entgo.io/docs/templates/), [hooks](https://entgo.io/docs/hooks/), [options](https://entgo.io/docs/code-gen/#code-generation-options) and [annotations](https://entgo.io/docs/templates/#annotations).
|
||||
For instance, entviz uses templates to add another go file, `entviz.go`, which exposes the `ServeEntviz` method that can be used as an http handler, like so:
|
||||
```go
|
||||
func main() {
|
||||
http.ListenAndServe("localhost:3002", ent.ServeEntviz())
|
||||
}
|
||||
```
|
||||
We define an extension struct which embeds the default extension, and we export our template via the `Templates` method:
|
||||
```go
|
||||
//go:embed entviz.go.tmpl
|
||||
var tmplfile string
|
||||
|
||||
type Extension struct {
|
||||
entc.DefaultExtension
|
||||
}
|
||||
|
||||
func (Extension) Templates() []*gen.Template {
|
||||
return []*gen.Template{
|
||||
gen.MustParse(gen.NewTemplate("entviz").Parse(tmplfile)),
|
||||
}
|
||||
}
|
||||
```
|
||||
The template file is the code that we want to generate:
|
||||
```gotemplate
|
||||
{{ define "entviz"}}
|
||||
|
||||
{{ $pkg := base $.Config.Package }}
|
||||
{{ template "header" $ }}
|
||||
import (
|
||||
_ "embed"
|
||||
"net/http"
|
||||
"strings"
|
||||
"time"
|
||||
)
|
||||
|
||||
//go:embed schema-viz.html
|
||||
var html string
|
||||
|
||||
func ServeEntviz() http.Handler {
|
||||
generateTime := time.Now()
|
||||
return http.HandlerFunc(func(w http.ResponseWriter, req *http.Request) {
|
||||
http.ServeContent(w, req, "schema-viz.html", generateTime, strings.NewReader(html))
|
||||
})
|
||||
}
|
||||
{{ end }}
|
||||
```
|
||||
That's it! now we have a new method in ent package.
|
||||
|
||||
### Wrapping-Up
|
||||
|
||||
We saw how ER diagrams help developers keep track of their data model. Next, we introduced entviz - an Ent extension that automatically generates an ER diagram for Ent schemas. We saw how entviz utilizes Ent's extension API to extend the code generation and add extra functionality. Finally, you got to see it in action by installing and use entviz in your own project. If you like the code and/or want to contribute - feel free to checkout the [project on github](https://github.com/hedwigz/entviz).
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack/).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
@@ -0,0 +1,45 @@
|
||||
---
|
||||
title: Ent Joins the Linux Foundation
|
||||
author: Ariel Mashraki
|
||||
authorURL: https://github.com/a8m
|
||||
authorImageURL: https://avatars0.githubusercontent.com/u/7413593
|
||||
authorTwitter: arielmashraki
|
||||
---
|
||||
|
||||
|
||||
Dear community,
|
||||
|
||||
I’m really happy to share something that has been in the works for quite some time.
|
||||
Yesterday (August 31st), a [press release](https://www.linuxfoundation.org/press-release/ent-joins-the-linux-foundation/)
|
||||
was issued announcing that Ent is joining the Linux Foundation.
|
||||
|
||||
|
||||
Ent was open-sourced while I was working on it with my peers at Facebook in 2019. Since then, our community has
|
||||
grown, and we’ve seen the adoption of Ent explode across many organizations of different sizes and sectors.
|
||||
|
||||
Our goal with moving under the governance of the Linux Foundation is to provide a corporate-neutral environment in
|
||||
which organizations can more easily contribute code, as we’ve seen with other successful OSS projects such as Kubernetes
|
||||
and GraphQL. In addition, the move under the governance of the Linux Foundation positions Ent where we would like it to
|
||||
be, a core, infrastructure technology that organizations can trust because it is guaranteed to be here for a long time.
|
||||
|
||||
In terms of our community, nothing in particular changes, the repository has already moved to [github.com/ent/ent](https://github.com/ent/ent)
|
||||
a few months ago, the license remains Apache 2.0, and we are all 100% committed to the success of the project. We’re sure
|
||||
that the Linux Foundation’s strong brand and organizational capabilities will help to build even more confidence in Ent
|
||||
and further foster its adoption in the industry.
|
||||
|
||||
I wanted to express my deep gratitude to the amazing folks at Facebook and the Linux Foundation that have worked hard on
|
||||
making this change possible and showing trust in our community to keep pushing the state-of-the-art in data access
|
||||
frameworks. This is a big achievement for our community, and so I want to take a moment to thank all of you for your
|
||||
contributions, support, and trust in this project.
|
||||
|
||||
On a personal note, I wanted to share that [Rotem](https://github.com/rotemtam) (a core contributor to Ent)
|
||||
and I have founded a new company, [Ariga](https://ariga.io).
|
||||
We’re on a mission to build something that we call an “operational data graph” that is heavily built using Ent, we will
|
||||
be sharing more details on that in the near future. You can expect to see many new exciting features contributed to the
|
||||
framework by our team. In addition, Ariga employees will dedicate time and resources to support and foster this wonderful
|
||||
community.
|
||||
|
||||
If you have any questions about this change or have any ideas on how to make it even better, please don’t hesitate to
|
||||
reach out to me on our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack/).
|
||||
|
||||
Ariel :heart:
|
||||
281
doc/website/blog/2021-09-02-ent-extension-api.md
Normal file
281
doc/website/blog/2021-09-02-ent-extension-api.md
Normal file
@@ -0,0 +1,281 @@
|
||||
---
|
||||
title: Extending Ent with the Extension API
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
---
|
||||
|
||||
A few months ago, [Ariel](https://github.com/a8m) made a silent but highly-impactful contribution
|
||||
to Ent's core, the [Extension API](https://entgo.io/docs/extensions). While Ent has had extension capabilities (such as [Code-gen Hooks](https://entgo.io/docs/code-gen/#code-generation-hooks),
|
||||
[External Templates](https://entgo.io/docs/templates/), and [Annotations](https://entgo.io/docs/templates/#annotations))
|
||||
for a long time, there wasn't a convenient way to bundle together all of these moving parts into a
|
||||
coherent, self-contained component. The [Extension API](https://entgo.io/docs/extensions) which we
|
||||
discuss in the post does exactly that.
|
||||
|
||||
Many open-source ecosystems thrive specifically because they excel at providing developers an
|
||||
easy and structured way to extend a small, core system. Much criticism has been made of the
|
||||
Node.js ecosystem (even by its [original creator Ryan Dahl](https://www.youtube.com/watch?v=M3BM9TB-8yA))
|
||||
but it is very hard to argue that the ease of publishing and consuming new `npm` modules
|
||||
facilitated the explosion in its popularity. I've discussed on my personal blog how
|
||||
[protoc's plugin system works](https://rotemtam.com/2021/03/22/creating-a-protoc-plugin-to-gen-go-code/)
|
||||
and how that made the Protobuf ecosystem thrive. In short, ecosystems are only created under
|
||||
modular designs.
|
||||
|
||||
In our post today, we will explore Ent's `Extension` API by building a toy example.
|
||||
|
||||
### Getting Started
|
||||
|
||||
The Extension API only works for projects use Ent's code-generation [as a Go package](https://entgo.io/docs/code-gen/#use-entc-as-a-package).
|
||||
To set that up, after initializing your project, create a new file named `ent/entc.go`:
|
||||
```go title=ent/entc.go
|
||||
//+build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
func main() {
|
||||
err := entc.Generate("./schema", &gen.Config{})
|
||||
if err != nil {
|
||||
log.Fatal("running ent codegen:", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
Next, modify `ent/generate.go` to invoke our `entc` file:
|
||||
```go title=ent/generate.go
|
||||
package ent
|
||||
|
||||
//go:generate go run entc.go
|
||||
```
|
||||
|
||||
### Creating our Extension
|
||||
|
||||
All extension's must implement the [Extension](https://pkg.go.dev/entgo.io/ent/entc#Extension) interface:
|
||||
|
||||
```go
|
||||
type Extension interface {
|
||||
// Hooks holds an optional list of Hooks to apply
|
||||
// on the graph before/after the code-generation.
|
||||
Hooks() []gen.Hook
|
||||
// Annotations injects global annotations to the gen.Config object that
|
||||
// can be accessed globally in all templates. Unlike schema annotations,
|
||||
// being serializable to JSON raw value is not mandatory.
|
||||
//
|
||||
// {{- with $.Config.Annotations.GQL }}
|
||||
// {{/* Annotation usage goes here. */}}
|
||||
// {{- end }}
|
||||
//
|
||||
Annotations() []Annotation
|
||||
// Templates specifies a list of alternative templates
|
||||
// to execute or to override the default.
|
||||
Templates() []*gen.Template
|
||||
// Options specifies a list of entc.Options to evaluate on
|
||||
// the gen.Config before executing the code generation.
|
||||
Options() []Option
|
||||
}
|
||||
```
|
||||
To simplify the development of new extensions, developers can embed [entc.DefaultExtension](https://pkg.go.dev/entgo.io/ent/entc#DefaultExtension)
|
||||
to create extensions without implementing all methods. In `entc.go`, add:
|
||||
```go title=ent/entc.go
|
||||
// ...
|
||||
|
||||
// GreetExtension implements entc.Extension.
|
||||
type GreetExtension {
|
||||
entc.DefaultExtension
|
||||
}
|
||||
```
|
||||
|
||||
Currently, our extension doesn't do anything. Next, let's connect it to our code-generation config.
|
||||
In `entc.go`, add our new extension to the `entc.Generate` invocation:
|
||||
|
||||
```go
|
||||
err := entc.Generate("./schema", &gen.Config{}, entc.Extensions(&GreetExtension{})
|
||||
```
|
||||
|
||||
### Adding Templates
|
||||
|
||||
External templates can be bundled into extensions to enhance Ent's core code-generation
|
||||
functionality. With our toy example, our goal is to add to each entity a generated method
|
||||
name `Greet` that returns a greeting with the type's name when invoked. We're aiming for something
|
||||
like:
|
||||
|
||||
```go
|
||||
func (u *User) Greet() string {
|
||||
return "Greetings, User"
|
||||
}
|
||||
```
|
||||
|
||||
To do this, let's add a new external template file and place it in `ent/templates/greet.tmpl`:
|
||||
```gotemplate title="ent/templates/greet.tmpl"
|
||||
{{ define "greet" }}
|
||||
|
||||
{{/* Add the base header for the generated file */}}
|
||||
{{ $pkg := base $.Config.Package }}
|
||||
{{ template "header" $ }}
|
||||
|
||||
{{/* Loop over all nodes and add the Greet method */}}
|
||||
{{ range $n := $.Nodes }}
|
||||
{{ $receiver := $n.Receiver }}
|
||||
func ({{ $receiver }} *{{ $n.Name }}) Greet() string {
|
||||
return "Greetings, {{ $n.Name }}"
|
||||
}
|
||||
{{ end }}
|
||||
{{ end }}
|
||||
```
|
||||
|
||||
Next, let's implement the `Templates` method:
|
||||
|
||||
```go title="ent/entc.go"
|
||||
func (*GreetExtension) Templates() []*gen.Template {
|
||||
return []*gen.Template{
|
||||
gen.MustParse(gen.NewTemplate("greet").ParseFiles("templates/greet.tmpl")),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Next, let's kick the tires on our extension. Add a new schema for the `User` type in a file
|
||||
named `ent/schema/user.go`:
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("email_address").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Next, run:
|
||||
```shell
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Observe that a new file, `ent/greet.go`, was created, it contains:
|
||||
|
||||
```go title="ent/greet.go"
|
||||
// Code generated by ent, DO NOT EDIT.
|
||||
|
||||
package ent
|
||||
|
||||
func (u *User) Greet() string {
|
||||
return "Greetings, User"
|
||||
}
|
||||
```
|
||||
|
||||
Great! Our extension was invoked from Ent's code-generation and produced the code
|
||||
we wanted for our schema!
|
||||
|
||||
### Adding Annotations
|
||||
|
||||
Annotations provide a way to supply users of our extension with an API
|
||||
to modify the behavior of code generation logic. To add annotations to our extension,
|
||||
implement the `Annotations` method. Suppose that for our `GreetExtension` we want
|
||||
to provide users with the ability to configure the greeting word in the generated
|
||||
code:
|
||||
|
||||
```go
|
||||
// GreetingWord implements entc.Annotation
|
||||
type GreetingWord string
|
||||
|
||||
func (GreetingWord) Name() string {
|
||||
return "GreetingWord"
|
||||
}
|
||||
```
|
||||
Next, we add a `word` field to our `GreetExtension` struct:
|
||||
```go
|
||||
type GreetExtension struct {
|
||||
entc.DefaultExtension
|
||||
Word GreetingWord
|
||||
}
|
||||
```
|
||||
Next, implement the `Annotations` method:
|
||||
```go
|
||||
func (s *GreetExtension) Annotations() []entc.Annotation {
|
||||
return []entc.Annotation{
|
||||
s.Word,
|
||||
}
|
||||
}
|
||||
```
|
||||
Now, from within your templates you can access the `GreetingWord` annotation. Modify
|
||||
`ent/templates/greet.tmpl` to use our new annotation:
|
||||
|
||||
```gotemplate
|
||||
func ({{ $receiver }} *{{ $n.Name }}) Greet() string {
|
||||
return "{{ $.Annotations.GreetingWord }}, {{ $n.Name }}"
|
||||
}
|
||||
```
|
||||
Next, modify the code-generation configuration to set the GreetingWord annotation:
|
||||
```go title="ent/entc.go
|
||||
err := entc.Generate("./schema",
|
||||
&gen.Config{},
|
||||
entc.Extensions(&GreetExtension{
|
||||
Word: GreetingWord("Shalom"),
|
||||
}),
|
||||
)
|
||||
```
|
||||
To see our annotation control the generated code, re-run:
|
||||
```shell
|
||||
go generate ./...
|
||||
```
|
||||
Finally, observe that the generated `ent/greet.go` was updated:
|
||||
|
||||
```go
|
||||
func (u *User) Greet() string {
|
||||
return "Shalom, User"
|
||||
}
|
||||
```
|
||||
|
||||
Hooray! We added an option to use an annotation to control the greeting word in the
|
||||
generated `Greet` method!
|
||||
|
||||
### More Possibilities
|
||||
|
||||
In addition to templates and annotations, the Extension API allows developers to bundle
|
||||
`gen.Hook`s and `entc.Option`s in extensions to further control the behavior of your code-generation.
|
||||
In this post we will not discuss these possibilities, but if you are interested in using them
|
||||
head over to the [documentation](https://entgo.io/docs/extensions).
|
||||
|
||||
### Wrapping Up
|
||||
|
||||
In this post we explored via a toy example how to use the `Extension` API to create new
|
||||
Ent code-generation extensions. As we've mentioned above, modular design that allows anyone
|
||||
to extend the core functionality of software is critical to the success of any ecosystem.
|
||||
We're seeing this claim start to realize with the Ent community, here's a list of some
|
||||
interesting projects that use the Extension API:
|
||||
* [elk](https://github.com/masseelch/elk) - an extension to generate REST endpoints from Ent schemas.
|
||||
* [entgql](https://github.com/ent/contrib/tree/master/entgql) - generate GraphQL servers from Ent schemas.
|
||||
* [entviz](https://github.com/hedwigz/entviz) - generate ER diagrams from Ent schemas.
|
||||
|
||||
And what about you? Do you have an idea for a useful Ent extension? I hope this post
|
||||
demonstrated that with the new Extension API, it is not a difficult task.
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack/).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
387
doc/website/blog/2021-09-10-openapi-generator.md
Normal file
387
doc/website/blog/2021-09-10-openapi-generator.md
Normal file
@@ -0,0 +1,387 @@
|
||||
---
|
||||
title: Generating OpenAPI Specification with Ent
|
||||
author: MasseElch
|
||||
authorURL: "https://github.com/masseelch"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/12862103?v=4"
|
||||
---
|
||||
|
||||
In a [previous blogpost](https://entgo.io/blog/2021/07/29/generate-a-fully-working-go-crud-http-api-with-ent), we
|
||||
presented to you [`elk`](https://github.com/masseelch/elk) - an [extension](https://entgo.io/docs/extensions) to Ent
|
||||
enabling you to generate a fully-working Go CRUD HTTP API from your schema. In the today's post I'd like to introduce to
|
||||
you a shiny new feature that recently made it into `elk`:
|
||||
a fully compliant [OpenAPI Specification (OAS)](https://swagger.io/resources/open-api/) generator.
|
||||
|
||||
OAS (formerly known as Swagger Specification) is a technical specification defining a standard, language-agnostic
|
||||
interface description for REST APIs. This allows both humans and automated tools to understand the described service
|
||||
without the actual source code or additional documentation. Combined with the [Swagger Tooling](https://swagger.io/) you
|
||||
can generate both server and client boilerplate code for more than 20 languages, just by passing in the OAS file.
|
||||
|
||||
### Getting Started
|
||||
|
||||
The first step is to add the `elk` package to your project:
|
||||
|
||||
```shell
|
||||
go get github.com/masseelch/elk@latest
|
||||
```
|
||||
|
||||
`elk` uses the Ent [Extension API](https://entgo.io/docs/extensions) to integrate with Ent’s code-generation. This
|
||||
requires that we use the `entc` (ent codegen) package as
|
||||
described [here](https://entgo.io/docs/code-gen#use-entc-as-a-package) to generate code for our project. Follow the next
|
||||
two steps to enable it and to configure Ent to work with the `elk` extension:
|
||||
|
||||
1\. Create a new Go file named `ent/entc.go` and paste the following content:
|
||||
|
||||
```go
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
"github.com/masseelch/elk"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ex, err := elk.NewExtension(
|
||||
elk.GenerateSpec("openapi.json"),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("creating elk extension: %v", err)
|
||||
}
|
||||
err = entc.Generate("./schema", &gen.Config{}, entc.Extensions(ex))
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
2\. Edit the `ent/generate.go` file to execute the `ent/entc.go` file:
|
||||
|
||||
```go
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entc.go
|
||||
```
|
||||
|
||||
With these steps complete, all is set up for generating an OAS file from your schema! If you are new to Ent and want to
|
||||
learn more about it, how to connect to different types of databases, run migrations or work with entities, then head
|
||||
over to the [Setup Tutorial](https://entgo.io/docs/tutorial-setup/).
|
||||
|
||||
### Generate an OAS file
|
||||
|
||||
The first step on our way to the OAS file is to create an Ent schema graph:
|
||||
|
||||
```shell
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new Fridge Compartment Item
|
||||
```
|
||||
|
||||
To demonstrate `elk`'s OAS generation capabilities, we will build together an example application. Suppose I have
|
||||
multiple fridges with multiple compartments, and my significant-other and I want to know its contents at all times. To
|
||||
supply ourselves with this incredibly useful information we will create a Go server with a RESTful API. To ease the
|
||||
creation of client applications that can communicate with our server, we will create an OpenAPI Specification file
|
||||
describing its API. Once we have that, we can build a frontend to manage fridges and contents in a language of our
|
||||
choice by using the Swagger Codegen! You can find an example that uses docker to generate a
|
||||
client [here](https://github.com/masseelch/elk/blob/master/internal/openapi/ent/generate.go).
|
||||
|
||||
Let's create our schema:
|
||||
|
||||
```go title="ent/fridge.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/edge"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// Fridge holds the schema definition for the Fridge entity.
|
||||
type Fridge struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Fridge.
|
||||
func (Fridge) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("title"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Fridge.
|
||||
func (Fridge) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("compartments", Compartment.Type),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```go title="ent/compartment.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/edge"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// Compartment holds the schema definition for the Compartment entity.
|
||||
type Compartment struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Compartment.
|
||||
func (Compartment) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Compartment.
|
||||
func (Compartment) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("fridge", Fridge.Type).
|
||||
Ref("compartments").
|
||||
Unique(),
|
||||
edge.To("contents", Item.Type),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```go title="ent/item.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/edge"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// Item holds the schema definition for the Item entity.
|
||||
type Item struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Item.
|
||||
func (Item) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Item.
|
||||
func (Item) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("compartment", Compartment.Type).
|
||||
Ref("contents").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Now, let's generate the Ent code and the OAS file.
|
||||
|
||||
```shell
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
In addition to the files Ent normally generates, another file named `openapi.json` has been created. Copy its contents
|
||||
and paste them into the [Swagger Editor](https://editor.swagger.io/). You should see three groups: **Compartment**, **
|
||||
Item** and **Fridge**.
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Swagger Editor Example" src="https://entgo.io/images/assets/elkopa/1.png" />
|
||||
<p style={{fontSize: 12}}>Swagger Editor Example</p>
|
||||
</div>
|
||||
|
||||
If you happen to open up the POST operation tab in the Fridge group, you see a description of
|
||||
the expected request data and all the possible responses. Great!
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="POST operation on Fridge" src="https://entgo.io/images/assets/elkopa/2.png" />
|
||||
<p style={{fontSize: 12}}>POST operation on Fridge</p>
|
||||
</div>
|
||||
|
||||
### Basic Configuration
|
||||
|
||||
The description of our API does not yet reflect what it does, let's change that! `elk` provides easy-to-use
|
||||
configuration builders to manipulate the generated OAS file. Open up `ent/entc.go` and pass in the updated title and
|
||||
description of our Fridge API:
|
||||
|
||||
```go title="ent/entc.go"
|
||||
//go:build ignore
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
"github.com/masseelch/elk"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ex, err := elk.NewExtension(
|
||||
elk.GenerateSpec(
|
||||
"openapi.json",
|
||||
// It is a Content-Management-System ...
|
||||
elk.SpecTitle("Fridge CMS"),
|
||||
// You can use CommonMark syntax (https://commonmark.org/).
|
||||
elk.SpecDescription("API to manage fridges and their cooled contents. **ICY!**"),
|
||||
elk.SpecVersion("0.0.1"),
|
||||
),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("creating elk extension: %v", err)
|
||||
}
|
||||
err = entc.Generate("./schema", &gen.Config{}, entc.Extensions(ex))
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Rerunning the code generator will create an updated OAS file you can copy-paste into the Swagger Editor.
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Updated API Info" src="https://entgo.io/images/assets/elkopa/3.png" />
|
||||
<p style={{fontSize: 12}}>Updated API Info</p>
|
||||
</div>
|
||||
|
||||
### Operation configuration
|
||||
|
||||
We do not want to expose endpoints to delete a fridge (seriously, who would ever want that?!). Fortunately, `elk` lets
|
||||
us configure what endpoints to generate and which to ignore. `elk`s default policy is to expose all routes. You can
|
||||
either change this behaviour to not expose any route but those explicitly asked for, or you can just tell `elk` to
|
||||
exclude the DELETE operation on the Fridge by using an `elk.SchemaAnnotation`:
|
||||
|
||||
```go title="ent/schema/fridge.go"
|
||||
// Annotations of the Fridge.
|
||||
func (Fridge) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
elk.DeletePolicy(elk.Exclude),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
And voilà! the DELETE operation is gone.
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="DELETE operation is gone" src="https://entgo.io/images/assets/elkopa/4.png" />
|
||||
<p style={{fontSize: 12}}>DELETE operation is gone</p>
|
||||
</div>
|
||||
|
||||
For more information about how `elk`'s policies work and what you can do with
|
||||
it, have a look at the [godoc](https://pkg.go.dev/github.com/masseelch/elk).
|
||||
|
||||
### Extend specification
|
||||
|
||||
The one thing I should be interested the most in this example is the current contents of a fridge. You can customize the
|
||||
generated OAS to any extend you like by using [Hooks](https://pkg.go.dev/github.com/masseelch/elk#Hook). However, this
|
||||
would exceed the scope of this post. An example of how to add an endpoint `fridges/{id}/contents` to the generated OAS
|
||||
file can be found [here](https://github.com/masseelch/elk/tree/master/internal/fridge/ent/entc.go).
|
||||
|
||||
### Generating an OAS-implementing server
|
||||
|
||||
I promised you in the beginning we'd create a server behaving as described in the OAS. `elk` makes this easy, all you
|
||||
have to do is call `elk.GenerateHandlers()` when you configure the extension:
|
||||
|
||||
```diff title="ent/entc.go"
|
||||
[...]
|
||||
func main() {
|
||||
ex, err := elk.NewExtension(
|
||||
elk.GenerateSpec(
|
||||
[...]
|
||||
),
|
||||
+ elk.GenerateHandlers(),
|
||||
)
|
||||
[...]
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
Next, re-run code generation:
|
||||
|
||||
```shell
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Observe, that a new directory named `ent/http` was created.
|
||||
|
||||
```shell
|
||||
» tree ent/http
|
||||
ent/http
|
||||
├── create.go
|
||||
├── delete.go
|
||||
├── easyjson.go
|
||||
├── handler.go
|
||||
├── list.go
|
||||
├── read.go
|
||||
├── relations.go
|
||||
├── request.go
|
||||
├── response.go
|
||||
└── update.go
|
||||
|
||||
0 directories, 10 files
|
||||
```
|
||||
|
||||
You can spin-up the generated server with this very simple `main.go`:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"net/http"
|
||||
|
||||
"<your-project>/ent"
|
||||
elk "<your-project>/ent/http"
|
||||
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
"go.uber.org/zap"
|
||||
)
|
||||
|
||||
func main() {
|
||||
// Create the ent client.
|
||||
c, err := ent.Open("sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to sqlite: %v", err)
|
||||
}
|
||||
defer c.Close()
|
||||
// Run the auto migration tool.
|
||||
if err := c.Schema.Create(context.Background()); err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
// Start listen to incoming requests.
|
||||
if err := http.ListenAndServe(":8080", elk.NewHandler(c, zap.NewExample())); err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```shell
|
||||
go run -mod=mod main.go
|
||||
```
|
||||
|
||||
Our Fridge API server is up and running. With the generated OAS file and the Swagger Tooling you can now generate a client stub
|
||||
in any supported language and forget about writing a RESTful client ever _ever_ again.
|
||||
|
||||
### Wrapping Up
|
||||
|
||||
In this post we introduced a new feature of `elk` - automatic OpenAPI Specification generation. This feature connects
|
||||
between Ent's code-generation capabilities and OpenAPI/Swagger's rich tooling ecosystem.
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack/).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
@@ -0,0 +1,460 @@
|
||||
---
|
||||
title: Generating Ent Schemas from Existing SQL Databases
|
||||
author: Zeev Manilovich
|
||||
authorURL: "https://github.com/zeevmoney"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/7361100?v=4"
|
||||
---
|
||||
|
||||
A few months ago the Ent project announced
|
||||
the [Schema Import Initiative](https://entgo.io/blog/2021/05/04/announcing-schema-imports), its goal is to help support
|
||||
many use cases for generating Ent schemas from external resources. Today, I'm happy to share a project I’ve been working
|
||||
on: **entimport** - an _importent_ (pun intended) command line tool designed to create Ent schemas from existing SQL
|
||||
databases. This is a feature that has been requested by the community for some time, so I hope many people find it
|
||||
useful. It can help ease the transition of an existing setup from another language or ORM to Ent. It can also help with
|
||||
use cases where you would like to access the same data from different platforms (such as to automatically sync between
|
||||
them).
|
||||
The first version supports both MySQL and PostgreSQL databases, with some limitations described below. Support for other
|
||||
relational databases such as SQLite is in the works.
|
||||
|
||||
## Getting Started
|
||||
|
||||
To give you an idea of how `entimport` works, I want to share a quick example of end to end usage with a MySQL database.
|
||||
On a high-level, this is what we’re going to do:
|
||||
|
||||
1. Create a Database and Schema - we want to show how `entimport` can generate an Ent schema for an existing database.
|
||||
We will first create a database, then define some tables in it that we can import into Ent.
|
||||
2. Initialize an Ent Project - we will use the Ent CLI to create the needed directory structure and an Ent schema
|
||||
generation script.
|
||||
3. Install `entimport`
|
||||
4. Run `entimport` against our demo database - next, we will import the database schema that we’ve created into our Ent
|
||||
project.
|
||||
5. Explain how to use Ent with our generated schemas.
|
||||
|
||||
Let's get started.
|
||||
|
||||
### Create a Database
|
||||
|
||||
We’re going to start by creating a database. The way I prefer to do it is to use
|
||||
a [Docker](https://docs.docker.com/get-docker/) container. We will use a `docker-compose` which will automatically pass
|
||||
all needed parameters to the MySQL container.
|
||||
|
||||
Start the project in a new directory called `entimport-example`. Create a file named `docker-compose.yaml` and paste the
|
||||
following content inside:
|
||||
|
||||
```yaml
|
||||
version: "3.7"
|
||||
|
||||
services:
|
||||
|
||||
mysql8:
|
||||
platform: linux/amd64
|
||||
image: mysql
|
||||
environment:
|
||||
MYSQL_DATABASE: entimport
|
||||
MYSQL_ROOT_PASSWORD: pass
|
||||
healthcheck:
|
||||
test: mysqladmin ping -ppass
|
||||
ports:
|
||||
- "3306:3306"
|
||||
```
|
||||
|
||||
This file contains the service configuration for a MySQL docker container. Run it with the following command:
|
||||
|
||||
```shell
|
||||
docker-compose up -d
|
||||
```
|
||||
|
||||
Next, we will create a simple schema. For this example we will use a relation between two entities:
|
||||
|
||||
- User
|
||||
- Car
|
||||
|
||||
Connect to the database using MySQL shell, you can do it with the following command:
|
||||
> Make sure you run it from the root project directory
|
||||
|
||||
```shell
|
||||
docker-compose exec mysql8 mysql --database=entimport -ppass
|
||||
```
|
||||
|
||||
```sql
|
||||
create table users
|
||||
(
|
||||
id bigint auto_increment primary key,
|
||||
age bigint not null,
|
||||
name varchar(255) not null,
|
||||
last_name varchar(255) null comment 'surname'
|
||||
);
|
||||
|
||||
create table cars
|
||||
(
|
||||
id bigint auto_increment primary key,
|
||||
model varchar(255) not null,
|
||||
color varchar(255) not null,
|
||||
engine_size mediumint not null,
|
||||
user_id bigint null,
|
||||
constraint cars_owners foreign key (user_id) references users (id) on delete set null
|
||||
);
|
||||
```
|
||||
|
||||
Let's validate that we've created the tables mentioned above, in your MySQL shell, run:
|
||||
|
||||
```sql
|
||||
show tables;
|
||||
+---------------------+
|
||||
| Tables_in_entimport |
|
||||
+---------------------+
|
||||
| cars |
|
||||
| users |
|
||||
+---------------------+
|
||||
```
|
||||
|
||||
We should see two tables: `users` & `cars`
|
||||
|
||||
### Initialize Ent Project
|
||||
|
||||
Now that we've created our database, and a baseline schema to demonstrate our example, we need to create
|
||||
a [Go](https://golang.org/doc/install) project with Ent. In this phase I will explain how to do it. Since eventually we
|
||||
would like to use our imported schema, we need to create the Ent directory structure.
|
||||
|
||||
Initialize a new Go project inside a directory called `entimport-example`
|
||||
|
||||
```shell
|
||||
go mod init entimport-example
|
||||
```
|
||||
|
||||
Run Ent Init:
|
||||
|
||||
```shell
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new
|
||||
```
|
||||
|
||||
The project should look like this:
|
||||
|
||||
```
|
||||
├── docker-compose.yaml
|
||||
├── ent
|
||||
│ ├── generate.go
|
||||
│ └── schema
|
||||
└── go.mod
|
||||
```
|
||||
|
||||
### Install entimport
|
||||
|
||||
OK, now the fun begins! We are finally ready to install `entimport` and see it in action.
|
||||
Let’s start by running `entimport`:
|
||||
|
||||
```shell
|
||||
go run -mod=mod ariga.io/entimport/cmd/entimport -h
|
||||
```
|
||||
|
||||
`entimport` will be downloaded and the command will print:
|
||||
|
||||
```
|
||||
Usage of entimport:
|
||||
-dialect string
|
||||
database dialect (default "mysql")
|
||||
-dsn string
|
||||
data source name (connection information)
|
||||
-schema-path string
|
||||
output path for ent schema (default "./ent/schema")
|
||||
-tables value
|
||||
comma-separated list of tables to inspect (all if empty)
|
||||
```
|
||||
|
||||
### Run entimport
|
||||
|
||||
We are now ready to import our MySQL schema to Ent!
|
||||
|
||||
We will do it with the following command:
|
||||
> This command will import all tables in our schema, you can also limit to specific tables using `-tables` flag.
|
||||
|
||||
```shell
|
||||
go run ariga.io/entimport/cmd/entimport -dialect mysql -dsn "root:pass@tcp(localhost:3306)/entimport"
|
||||
```
|
||||
|
||||
Like many unix tools, `entimport` doesn't print anything on a successful run. To verify that it ran properly, we will
|
||||
check the file system, and more specifically `ent/schema` directory.
|
||||
|
||||
```console {5-6}
|
||||
├── docker-compose.yaml
|
||||
├── ent
|
||||
│ ├── generate.go
|
||||
│ └── schema
|
||||
│ ├── car.go
|
||||
│ └── user.go
|
||||
├── go.mod
|
||||
└── go.sum
|
||||
```
|
||||
|
||||
Let’s see what this gives us - remember that we had two schemas: the `users` schema and the `cars` schema with a one to
|
||||
many relationship. Let’s see how `entimport` performed.
|
||||
|
||||
```go title="entimport-example/ent/schema/user.go"
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{field.Int("id"), field.Int("age"), field.String("name"), field.String("last_name").Optional().Comment("surname")}
|
||||
}
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{edge.To("cars", Car.Type)}
|
||||
}
|
||||
func (User) Annotations() []schema.Annotation {
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
```go title="entimport-example/ent/schema/car.go"
|
||||
type Car struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (Car) Fields() []ent.Field {
|
||||
return []ent.Field{field.Int("id"), field.String("model"), field.String("color"), field.Int32("engine_size"), field.Int("user_id").Optional()}
|
||||
}
|
||||
func (Car) Edges() []ent.Edge {
|
||||
return []ent.Edge{edge.From("user", User.Type).Ref("cars").Unique().Field("user_id")}
|
||||
}
|
||||
func (Car) Annotations() []schema.Annotation {
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
> **`entimport` successfully created entities and their relation!**
|
||||
|
||||
So far looks good, now let’s actually try them out. First we must generate the Ent schema. We do it because Ent is a
|
||||
**schema first** ORM that [generates](https://entgo.io/docs/code-gen) Go code for interacting with different databases.
|
||||
|
||||
To run the Ent code generation:
|
||||
|
||||
```shell
|
||||
go generate ./ent
|
||||
```
|
||||
|
||||
Let's see our `ent` directory:
|
||||
|
||||
```
|
||||
...
|
||||
├── ent
|
||||
│ ├── car
|
||||
│ │ ├── car.go
|
||||
│ │ └── where.go
|
||||
...
|
||||
│ ├── schema
|
||||
│ │ ├── car.go
|
||||
│ │ └── user.go
|
||||
...
|
||||
│ ├── user
|
||||
│ │ ├── user.go
|
||||
│ │ └── where.go
|
||||
...
|
||||
```
|
||||
|
||||
### Ent Example
|
||||
|
||||
Let’s run a quick example to verify that our schema works:
|
||||
|
||||
Create a file named `example.go` in the root of the project, with the following content:
|
||||
|
||||
> This part of the example can be found [here](https://github.com/zeevmoney/entimport-example/blob/master/part1/example.go)
|
||||
|
||||
```go title="entimport-example/example.go"
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"fmt"
|
||||
"log"
|
||||
|
||||
"entimport-example/ent"
|
||||
|
||||
"entgo.io/ent/dialect"
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open(dialect.MySQL, "root:pass@tcp(localhost:3306)/entimport?parseTime=True")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
example(ctx, client)
|
||||
}
|
||||
```
|
||||
|
||||
Let's try to add a user, write the following code at the end of the file:
|
||||
|
||||
```go title="entimport-example/example.go"
|
||||
func example(ctx context.Context, client *ent.Client) {
|
||||
// Create a User.
|
||||
zeev := client.User.
|
||||
Create().
|
||||
SetAge(33).
|
||||
SetName("Zeev").
|
||||
SetLastName("Manilovich").
|
||||
SaveX(ctx)
|
||||
fmt.Println("User created:", zeev)
|
||||
}
|
||||
```
|
||||
|
||||
Then run:
|
||||
|
||||
```shell
|
||||
go run example.go
|
||||
```
|
||||
|
||||
This should output:
|
||||
|
||||
`# User created: User(id=1, age=33, name=Zeev, last_name=Manilovich)`
|
||||
|
||||
Let's check with the database if the user was really added
|
||||
|
||||
```sql
|
||||
SELECT *
|
||||
FROM users
|
||||
WHERE name = 'Zeev';
|
||||
|
||||
+--+---+----+----------+
|
||||
|id|age|name|last_name |
|
||||
+--+---+----+----------+
|
||||
|1 |33 |Zeev|Manilovich|
|
||||
+--+---+----+----------+
|
||||
```
|
||||
|
||||
Great! now let's play a little more with Ent and add some relations, add the following code at the end of
|
||||
the `example()` func:
|
||||
> make sure you add `"entimport-example/ent/user"` to the import() declaration
|
||||
|
||||
```go title="entimport-example/example.go"
|
||||
// Create Car.
|
||||
vw := client.Car.
|
||||
Create().
|
||||
SetModel("volkswagen").
|
||||
SetColor("blue").
|
||||
SetEngineSize(1400).
|
||||
SaveX(ctx)
|
||||
fmt.Println("First car created:", vw)
|
||||
|
||||
// Update the user - add the car relation.
|
||||
client.User.Update().Where(user.ID(zeev.ID)).AddCars(vw).SaveX(ctx)
|
||||
|
||||
// Query all cars that belong to the user.
|
||||
cars := zeev.QueryCars().AllX(ctx)
|
||||
fmt.Println("User cars:", cars)
|
||||
|
||||
// Create a second Car.
|
||||
delorean := client.Car.
|
||||
Create().
|
||||
SetModel("delorean").
|
||||
SetColor("silver").
|
||||
SetEngineSize(9999).
|
||||
SaveX(ctx)
|
||||
fmt.Println("Second car created:", delorean)
|
||||
|
||||
// Update the user - add another car relation.
|
||||
client.User.Update().Where(user.ID(zeev.ID)).AddCars(delorean).SaveX(ctx)
|
||||
|
||||
// Traverse the sub-graph.
|
||||
cars = delorean.
|
||||
QueryUser().
|
||||
QueryCars().
|
||||
AllX(ctx)
|
||||
fmt.Println("User cars:", cars)
|
||||
```
|
||||
|
||||
> This part of the example can be found [here](https://github.com/zeevmoney/entimport-example/blob/master/part2/example.go)
|
||||
|
||||
Now do: `go run example.go`.
|
||||
After Running the code above, the database should hold a user with 2 cars in a O2M relation.
|
||||
|
||||
```sql
|
||||
SELECT *
|
||||
FROM users;
|
||||
|
||||
+--+---+----+----------+
|
||||
|id|age|name|last_name |
|
||||
+--+---+----+----------+
|
||||
|1 |33 |Zeev|Manilovich|
|
||||
+--+---+----+----------+
|
||||
|
||||
SELECT *
|
||||
FROM cars;
|
||||
|
||||
+--+----------+------+-----------+-------+
|
||||
|id|model |color |engine_size|user_id|
|
||||
+--+----------+------+-----------+-------+
|
||||
|1 |volkswagen|blue |1400 |1 |
|
||||
|2 |delorean |silver|9999 |1 |
|
||||
+--+----------+------+-----------+-------+
|
||||
```
|
||||
|
||||
### Syncing DB changes
|
||||
|
||||
Since we want to keep the database in sync, we want `entimport` to be able to change the schema after the database was
|
||||
changed. Let's see how it works.
|
||||
|
||||
Run the following SQL code to add a `phone` column with a `unique` index to the `users` table:
|
||||
|
||||
```sql
|
||||
alter table users
|
||||
add phone varchar(255) null;
|
||||
|
||||
create unique index users_phone_uindex
|
||||
on users (phone);
|
||||
```
|
||||
|
||||
The table should look like this:
|
||||
|
||||
```sql
|
||||
describe users;
|
||||
+-----------+--------------+------+-----+---------+----------------+
|
||||
| Field | Type | Null | Key | Default | Extra |
|
||||
+-----------+--------------+------+-----+---------+----------------+
|
||||
| id | bigint | NO | PRI | NULL | auto_increment |
|
||||
| age | bigint | NO | | NULL | |
|
||||
| name | varchar(255) | NO | | NULL | |
|
||||
| last_name | varchar(255) | YES | | NULL | |
|
||||
| phone | varchar(255) | YES | UNI | NULL | |
|
||||
+-----------+--------------+------+-----+---------+----------------+
|
||||
```
|
||||
|
||||
Now let's run `entimport` again to get the latest schema from our database:
|
||||
|
||||
```shell
|
||||
go run -mod=mod ariga.io/entimport/cmd/entimport -dialect mysql -dsn "root:pass@tcp(localhost:3306)/entimport"
|
||||
```
|
||||
|
||||
We can see that the `user.go` file was changed:
|
||||
|
||||
```go title="entimport-example/ent/schema/user.go"
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{field.Int("id"), ..., field.String("phone").Optional().Unique()}
|
||||
}
|
||||
```
|
||||
|
||||
Now we can run `go generate ./ent` again and use the new schema to add a `phone` to the User entity.
|
||||
|
||||
## Future Plans
|
||||
|
||||
As mentioned above this initial version supports MySQL and PostgreSQL databases.
|
||||
It also supports all types of SQL relations. I have plans to further upgrade the tool and add features such as missing
|
||||
PostgreSQL fields, default values, and more.
|
||||
|
||||
## Wrapping Up
|
||||
|
||||
In this post, I presented `entimport`, a tool that was anticipated and requested many times by the Ent community. I
|
||||
showed an example of how to use it with Ent. This tool is another addition to Ent schema import tools, which are
|
||||
designed to make the integration of ent even easier. For discussion and
|
||||
support, [open an issue](https://github.com/ariga/entimport/issues/new). The full example can be
|
||||
found [in here](https://github.com/zeevmoney/entimport-example). I hope you found this blog post useful!
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
183
doc/website/blog/2021-10-14-introducing-entcache.md
Normal file
183
doc/website/blog/2021-10-14-introducing-entcache.md
Normal file
@@ -0,0 +1,183 @@
|
||||
---
|
||||
title: Announcing entcache - a Cache Driver for Ent
|
||||
author: Ariel Mashraki
|
||||
authorURL: "https://github.com/a8m"
|
||||
authorImageURL: "https://avatars0.githubusercontent.com/u/7413593"
|
||||
authorTwitter: arielmashraki
|
||||
---
|
||||
|
||||
While working on [Ariga's](https://ariga.io) operational data graph query engine, we saw the opportunity to greatly
|
||||
improve the performance of many use cases by building a robust caching library. As heavy users of Ent, it was only
|
||||
natural for us to implement this layer as an extension to Ent. In this post, I will briefly explain what caches are,
|
||||
how they fit into software architectures, and present `entcache` - a cache driver for Ent.
|
||||
|
||||
Caching is a popular strategy for improving application performance. It is based on the observation that the speed for
|
||||
retrieving data using different types of media can vary within many orders of magnitude.
|
||||
[Jeff Dean](https://twitter.com/jeffdean?lang=en) famously presented the following numbers in a
|
||||
[lecture](http://static.googleusercontent.com/media/research.google.com/en/us/people/jeff/stanford-295-talk.pdf) about
|
||||
"Software Engineering Advice from Building Large-Scale Distributed Systems":
|
||||
|
||||

|
||||
|
||||
These numbers show things that experienced software engineers know intuitively: reading from memory is faster than
|
||||
reading from disk, retrieving data from the same data center is faster than going out to the internet to fetch it.
|
||||
We add to that, that some calculations are expensive and slow, and that fetching a precomputed result can be much faster
|
||||
(and less expensive) than recomputing it every time.
|
||||
|
||||
The collective intelligence of [Wikipedia](https://en.wikipedia.org/wiki/Cache_(computing)) tells us that a Cache is
|
||||
"a hardware or software component that stores data so that future requests for that data can be served faster".
|
||||
In other words, if we can store a query result in RAM, we can fulfill a request that depends on it much faster than
|
||||
if we need to go over the network to our database, have it read data from disk, run some computation on it, and only
|
||||
then send it back to us (over a network).
|
||||
|
||||
However, as software engineers, we should remember that caching is a notoriously complicated topic. As the phrase
|
||||
coined by early-day Netscape engineer [Phil Karlton](https://martinfowler.com/bliki/TwoHardThings.html) says: _"There
|
||||
are only two hard things in Computer Science: cache invalidation and naming things"_. For instance, in systems that rely
|
||||
on strong consistency, a cache entry may be stale, therefore causing the system to behave incorrectly. For this reason,
|
||||
take great care and pay attention to detail when you are designing caches into your system architectures.
|
||||
|
||||
### Presenting `entcache`
|
||||
|
||||
The `entcache` package provides its users with a new Ent driver that can wrap one of the existing SQL drivers available
|
||||
for Ent. On a high level, it decorates the Query method of the given driver, and for each call:
|
||||
|
||||
1. Generates a cache key (i.e. hash) from its arguments (i.e. statement and parameters).
|
||||
|
||||
2. Checks the cache to see if the results for this query are already available. If they are (this is called a
|
||||
cache-hit), the database is skipped and results are returned to the caller from memory.
|
||||
|
||||
3. If the cache does not contain an entry for the query, the query is passed to the database.
|
||||
|
||||
4. After the query is executed, the driver records the raw values of the returned rows (`sql.Rows`), and stores them in
|
||||
the cache with the generated cache key.
|
||||
|
||||
The package provides a variety of options to configure the TTL of the cache entries, control the hash function, provide
|
||||
custom and multi-level cache stores, evict and skip cache entries. See the full documentation in
|
||||
[https://pkg.go.dev/ariga.io/entcache](https://pkg.go.dev/ariga.io/entcache).
|
||||
|
||||
As we mentioned above, correctly configuring caching for an application is a delicate task, and so `entcache` provides
|
||||
developers with different caching levels that can be used with it:
|
||||
|
||||
1. A `context.Context`-based cache. Usually, attached to a request and does not work with other cache levels.
|
||||
It is used to eliminate duplicate queries that are executed by the same request.
|
||||
|
||||
2. A driver-level cache used by the `ent.Client`. An application usually creates a driver per database,
|
||||
and therefore, we treat it as a process-level cache.
|
||||
|
||||
3. A remote cache. For example, a Redis database that provides a persistence layer for storing and sharing cache
|
||||
entries between multiple processes. A remote cache layer is resistant to application deployment changes or failures,
|
||||
and allows reducing the number of identical queries executed on the database by different process.
|
||||
|
||||
4. A cache hierarchy, or multi-level cache allows structuring the cache in hierarchical way. The hierarchy of cache
|
||||
stores is mostly based on access speeds and cache sizes. For example, a 2-level cache that composed of an LRU-cache
|
||||
in the application memory, and a remote-level cache backed by a Redis database.
|
||||
|
||||
Let's demonstrate this by explaining the `context.Context` based cache.
|
||||
|
||||
### Context-Level Cache
|
||||
|
||||
The `ContextLevel` option configures the driver to work with a `context.Context` level cache. The context is usually
|
||||
attached to a request (e.g. `*http.Request`) and is not available in multi-level mode. When this option is used as
|
||||
a cache store, the attached `context.Context` carries an LRU cache (can be configured differently), and the driver
|
||||
stores and searches entries in the LRU cache when queries are executed.
|
||||
|
||||
This option is ideal for applications that require strong consistency, but still want to avoid executing duplicate
|
||||
database queries on the same request. For example, given the following GraphQL query:
|
||||
|
||||
```graphql
|
||||
query($ids: [ID!]!) {
|
||||
nodes(ids: $ids) {
|
||||
... on User {
|
||||
id
|
||||
name
|
||||
todos {
|
||||
id
|
||||
owner {
|
||||
id
|
||||
name
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
A naive solution for resolving the above query will execute, 1 for getting N users, another N queries for getting
|
||||
the todos of each user, and a query for each todo item for getting its owner (read more about the
|
||||
[_N+1 Problem_](https://entgo.io/docs/tutorial-todo-gql-field-collection/#problem)).
|
||||
|
||||
However, Ent provides a unique approach for resolving such queries(read more in
|
||||
[Ent website](https://entgo.io/docs/tutorial-todo-gql-field-collection)) and therefore, only 3 queries will be executed
|
||||
in this case. 1 for getting N users, 1 for getting the todo items of **all** users, and 1 query for getting the owners
|
||||
of **all** todo items.
|
||||
|
||||
With `entcache`, the number of queries may be reduced to 2, as the first and last queries are identical (see
|
||||
[code example](https://github.com/ariga/entcache/blob/master/internal/examples/ctxlevel/main_test.go)).
|
||||
|
||||

|
||||
|
||||
The different levels are explained in depth in the repository
|
||||
[README](https://github.com/ariga/entcache/blob/master/README.md).
|
||||
|
||||
### Getting Started
|
||||
|
||||
> If you are not familiar with how to set up a new Ent project, complete Ent
|
||||
> [Setting Up tutorial](https://entgo.io/docs/tutorial-setup) first.
|
||||
|
||||
First, `go get` the package using the following command.
|
||||
|
||||
```shell
|
||||
go get ariga.io/entcache
|
||||
```
|
||||
|
||||
After installing `entcache`, you can easily add it to your project with the snippet below:
|
||||
|
||||
```go
|
||||
// Open the database connection.
|
||||
db, err := sql.Open(dialect.SQLite, "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatal("opening database", err)
|
||||
}
|
||||
// Decorates the sql.Driver with entcache.Driver.
|
||||
drv := entcache.NewDriver(db)
|
||||
// Create an ent.Client.
|
||||
client := ent.NewClient(ent.Driver(drv))
|
||||
|
||||
// Tell the entcache.Driver to skip the caching layer
|
||||
// when running the schema migration.
|
||||
if client.Schema.Create(entcache.Skip(ctx)); err != nil {
|
||||
log.Fatal("running schema migration", err)
|
||||
}
|
||||
|
||||
// Run queries.
|
||||
if u, err := client.User.Get(ctx, id); err != nil {
|
||||
log.Fatal("querying user", err)
|
||||
}
|
||||
// The query below is cached.
|
||||
if u, err := client.User.Get(ctx, id); err != nil {
|
||||
log.Fatal("querying user", err)
|
||||
}
|
||||
```
|
||||
|
||||
To see more advanced examples, head over to the repo's
|
||||
[examples directory](https://github.com/ariga/entcache/tree/master/internal/examples).
|
||||
|
||||
### Wrapping Up
|
||||
|
||||
In this post, I presented “entcache” a new cache driver for Ent that I developed while working on [Ariga's Operational
|
||||
Data Graph](https://ariga.io) query engine. We started the discussion by briefly mentioning the motivation for including
|
||||
caches in software systems. Following that, we described the features and capabilities of `entcache` and concluded with
|
||||
a short example of how you can set it up in your application.
|
||||
|
||||
There are a few features we are working on, and wish to work on, but need help from the community to design them
|
||||
properly (solving cache invalidation, anyone? ;)). If you are interested to contribute, reach out to me on the Ent
|
||||
Slack channel.
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
130
doc/website/blog/2021-10-19-sqlcomment-support-for-ent.md
Normal file
130
doc/website/blog/2021-10-19-sqlcomment-support-for-ent.md
Normal file
@@ -0,0 +1,130 @@
|
||||
---
|
||||
title: Introducing sqlcomment - Database Performance Analysis with Ent and Google's Sqlcommenter
|
||||
author: Amit Shani
|
||||
authorURL: "https://github.com/hedwigz"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/8277210?v=4"
|
||||
authorTwitter: itsamitush
|
||||
image: https://entgo.io/images/assets/sqlcomment/share.png
|
||||
---
|
||||
|
||||
Ent is a powerful Entity framework that helps developers write neat code that is translated into (possibly complex) database queries. As the usage of your application grows, it doesn’t take long until you stumble upon performance issues with your database.
|
||||
Troubleshooting database performance issues is notoriously hard, especially when you’re not equipped with the right tools.
|
||||
|
||||
The following example shows how Ent query code is translated into an SQL query.
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="ent example 1" src="https://entgo.io/images/assets/sqlcomment/pipeline.png" />
|
||||
<p style={{fontSize: 12}}>Example 1 - ent code is translated to SQL query</p>
|
||||
</div>
|
||||
|
||||
Traditionally, it has been very difficult to correlate between poorly performing database queries and the application code that is generating them. Database performance analysis tools could help point out slow queries by analyzing database server logs, but how could they be traced back to the application?
|
||||
|
||||
### Sqlcommenter
|
||||
Earlier this year, [Google introduced](https://cloud.google.com/blog/topics/developers-practitioners/introducing-sqlcommenter-open-source-orm-auto-instrumentation-library) Sqlcommenter. Sqlcommenter is
|
||||
|
||||
> <em>an open source library that addresses the gap between the ORM libraries and understanding database performance. Sqlcommenter gives application developers visibility into which application code is generating slow queries and maps application traces to database query plans</em>
|
||||
|
||||
In other words, Sqlcommenter adds application context metadata to SQL queries. This information can then be used to provide meaningful insights. It does so by adding [SQL comments](https://en.wikipedia.org/wiki/SQL_syntax#Comments) to the query that carry metadata but are ignored by the database during query execution.
|
||||
For example, the following query contains a comment that carries metadata about the application that issued it (`users-mgr`), which controller and route triggered it (`users` and `user_rename`, respectively), and the database driver that was used (`ent:v0.9.1`):
|
||||
|
||||
```sql
|
||||
update users set username = ‘hedwigz’ where id = 88
|
||||
/*application='users-mgr',controller='users',route='user_rename',db_driver='ent:v0.9.1'*/
|
||||
```
|
||||
|
||||
To get a taste of how the analysis of metadata collected from Sqlcommenter metadata can help us better understand performance issues of our application, consider the following example: Google Cloud recently launched [Cloud SQL Insights](https://cloud.google.com/blog/products/databases/get-ahead-of-database-performance-issues-with-cloud-sql-insights), a cloud-based SQL performance analysis product. In the image below, we see a screenshot from the Cloud SQL Insights Dashboard that shows that the HTTP route 'api/users' is causing many locks on the database. We can also see that this query got called 16,067 times in the last 6 hours.
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Cloud SQL insights" src="https://entgo.io/images/assets/sqlcomment/ginsights.png" />
|
||||
<p style={{fontSize: 12}}>Screenshot from Cloud SQL Insights Dashboard</p>
|
||||
</div>
|
||||
|
||||
This is the power of SQL tags - they provide you correlation between your application-level information and your Database monitors.
|
||||
|
||||
### sqlcomment
|
||||
|
||||
[sqlcomm**ent**](https://github.com/ariga/sqlcomment) is an Ent driver that adds metadata to SQL queries using comments following the [sqlcommenter specification](https://google.github.io/sqlcommenter/spec/). By wrapping an existing Ent driver with `sqlcomment`, users can leverage any tool that supports the standard to triage query performance issues.
|
||||
Without further ado, let’s see `sqlcomment` in action.
|
||||
|
||||
First, to install sqlcomment run:
|
||||
```bash
|
||||
go get ariga.io/sqlcomment
|
||||
```
|
||||
|
||||
`sqlcomment` is wrapping an underlying SQL driver, therefore, we need to open our SQL connection using ent’s `sql` module, instead of Ent's popular helper `ent.Open`.
|
||||
|
||||
:::info
|
||||
Make sure to import `entgo.io/ent/dialect/sql` in the following snippet
|
||||
:::
|
||||
|
||||
```go
|
||||
// Create db driver.
|
||||
db, err := sql.Open("sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatalf("Failed to connect to database: %v", err)
|
||||
}
|
||||
|
||||
// Create sqlcomment driver which wraps sqlite driver.
|
||||
drv := sqlcomment.NewDriver(db,
|
||||
sqlcomment.WithDriverVerTag(),
|
||||
sqlcomment.WithTags(sqlcomment.Tags{
|
||||
sqlcomment.KeyApplication: "my-app",
|
||||
sqlcomment.KeyFramework: "net/http",
|
||||
}),
|
||||
)
|
||||
|
||||
// Create and configure ent client.
|
||||
client := ent.NewClient(ent.Driver(drv))
|
||||
```
|
||||
|
||||
Now, whenever we execute a query, `sqlcomment` will suffix our SQL query with the tags we set up. If we were to run the following query:
|
||||
|
||||
```go
|
||||
client.User.
|
||||
Update().
|
||||
Where(
|
||||
user.Or(
|
||||
user.AgeGT(30),
|
||||
user.Name("bar"),
|
||||
),
|
||||
user.HasFollowers(),
|
||||
).
|
||||
SetName("foo").
|
||||
Save()
|
||||
```
|
||||
|
||||
Ent would output the following commented SQL query:
|
||||
|
||||
```sql
|
||||
UPDATE `users`
|
||||
SET `name` = ?
|
||||
WHERE (
|
||||
`users`.`age` > ?
|
||||
OR `users`.`name` = ?
|
||||
)
|
||||
AND `users`.`id` IN (
|
||||
SELECT `user_following`.`follower_id`
|
||||
FROM `user_following`
|
||||
)
|
||||
/*application='my-app',db_driver='ent:v0.9.1',framework='net%2Fhttp'*/
|
||||
```
|
||||
|
||||
As you can see, Ent outputted an SQL query with a comment at the end, containing all the relevant information associated with that query.
|
||||
|
||||
sqlcomm**ent** supports more tags, and has integrations with [OpenTelemetry](https://opentelemetry.io) and [OpenCensus](https://opencensus.io).
|
||||
To see more examples and scenarios, please visit the [github repo](https://github.com/ariga/sqlcomment).
|
||||
|
||||
### Wrapping-Up
|
||||
|
||||
In this post I showed how adding metadata to queries using SQL comments can help correlate between source code and database queries. Next, I introduced `sqlcomment` - an Ent driver that adds SQL tags to all of your queries. Finally, I got to see `sqlcomment` in action, by installing and configuring it with Ent. If you like the code and/or want to contribute - feel free to checkout the [project on GitHub](https://github.com/ariga/sqlcomment).
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack/).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
@@ -0,0 +1,306 @@
|
||||
---
|
||||
title: Sync Changes to External Data Systems using Ent Hooks
|
||||
author: Ariel Mashraki
|
||||
authorURL: https://github.com/a8m
|
||||
authorImageURL: "https://avatars0.githubusercontent.com/u/7413593"
|
||||
authorTwitter: arielmashraki
|
||||
image: https://entgo.io/images/assets/sync-hook/share.png
|
||||
---
|
||||
|
||||
One of the common questions we get from the Ent community is how to synchronize objects or references between the
|
||||
database backing an Ent application (e.g. MySQL or PostgreSQL) with external services. For example, users would like
|
||||
to create or delete a record from within their CRM when a user is created or deleted in Ent, publish a message to a
|
||||
[Pub/Sub system](https://en.wikipedia.org/wiki/Publish%E2%80%93subscribe_pattern) when an entity is updated, or verify
|
||||
references to blobs in object storage such as AWS S3 or Google Cloud Storage.
|
||||
|
||||
Ensuring consistency between two separate data systems is not a simple task. When we want to propagate, for example,
|
||||
the deletion of a record in one system to another, there is no obvious way to guarantee that the two systems will end in
|
||||
a synchronized state, since one of them may fail, and the network link between them may be slow or down. Having said
|
||||
that, and especially with the prominence of microservices-architectures, these problems have become more common, and
|
||||
distributed systems researchers have come up with patterns to solve them, such as the
|
||||
[Saga Pattern](https://microservices.io/patterns/data/saga.html).
|
||||
|
||||
The application of these patterns is usually complex and difficult, and so in many cases architects do not go after a
|
||||
"perfect" design, and instead go after simpler solutions that involve either the acceptance of some inconsistency
|
||||
between the systems or background reconciliation procedures.
|
||||
|
||||
In this post, we will not discuss how to solve distributed transactions or implement the Saga pattern with Ent.
|
||||
Instead, we will limit our scope to study how to hook into Ent mutations before and after they occur, and run our
|
||||
custom logic there.
|
||||
|
||||
### Propagating Mutations to External Systems
|
||||
|
||||
In our example, we are going to create a simple `User` schema with 2 immutable string fields, `"name"` and
|
||||
`"avatar_url"`. Let's run the `ent init` command for creating a skeleton schema for our `User`:
|
||||
|
||||
```shell
|
||||
go run entgo.io/ent/cmd/ent new User
|
||||
```
|
||||
|
||||
Then, add the `name` and the `avatar_url` fields and run `go generate` to generate the assets.
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name").
|
||||
Immutable(),
|
||||
field.String("avatar_url").
|
||||
Immutable(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```shell
|
||||
go generate ./ent
|
||||
```
|
||||
|
||||
### The Problem
|
||||
|
||||
The `avatar_url` field defines a URL to an image in a bucket on our object storage (e.g. AWS S3). For the purpose of
|
||||
this discussion we want to make sure that:
|
||||
|
||||
- When a user is created, an image with the URL stored in `"avatar_url"` exists in our bucket.
|
||||
- Orphan images are deleted from the bucket. This means that when a user is deleted from our system, its avatar image
|
||||
is deleted as well.
|
||||
|
||||
For interacting with blobs, we will use the [`gocloud.dev/blob`](https://gocloud.dev/howto/blob) package. This package
|
||||
provides abstraction for reading, writing, deleting and listing blobs in a bucket. Similar to the `database/sql`
|
||||
package, it allows interacting with variety of object storages with the same API by configuring its driver URL.
|
||||
For example:
|
||||
|
||||
```go
|
||||
// Open an in-memory bucket.
|
||||
if bucket, err := blob.OpenBucket(ctx, "mem://photos/"); err != nil {
|
||||
log.Fatal("failed opening in-memory bucket:", err)
|
||||
}
|
||||
|
||||
// Open an S3 bucket named photos.
|
||||
if bucket, err := blob.OpenBucket(ctx, "s3://photos"); err != nil {
|
||||
log.Fatal("failed opening s3 bucket:", err)
|
||||
}
|
||||
|
||||
// Open a bucket named photos in Google Cloud Storage.
|
||||
if bucket, err := blob.OpenBucket(ctx, "gs://my-bucket"); err != nil {
|
||||
log.Fatal("failed opening gs bucket:", err)
|
||||
}
|
||||
```
|
||||
|
||||
### Schema Hooks
|
||||
|
||||
[Hooks](https://entgo.io/docs/hooks) are a powerful feature of Ent that allows adding custom logic before and after
|
||||
operations that mutate the graph.
|
||||
|
||||
Hooks can be either defined dynamically using `client.Use` (called "Runtime Hooks"), or explicitly on the schema
|
||||
(called "Schema Hooks") as follows:
|
||||
|
||||
```go
|
||||
// Hooks of the User.
|
||||
func (User) Hooks() []ent.Hook {
|
||||
return []ent.Hook{
|
||||
EnsureImageExists(),
|
||||
DeleteOrphans(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
As you can imagine, the `EnsureImageExists` hook will be responsible for ensuring that when a user is created, their
|
||||
avatar URL exists in the bucket, and the `DeleteOrphans` will ensure that orphan images are deleted. Let's start
|
||||
writing them.
|
||||
|
||||
```go title="ent/schema/hooks.go"
|
||||
func EnsureImageExists() ent.Hook {
|
||||
hk := func(next ent.Mutator) ent.Mutator {
|
||||
return hook.UserFunc(func(ctx context.Context, m *ent.UserMutation) (ent.Value, error) {
|
||||
avatarURL, exists := m.AvatarURL()
|
||||
if !exists {
|
||||
return nil, errors.New("avatar field is missing")
|
||||
}
|
||||
// TODO:
|
||||
// 1. Verify that "avatarURL" points to a real object in the bucket.
|
||||
// 2. Otherwise, fail.
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
}
|
||||
// Limit the hook only to "Create" operations.
|
||||
return hook.On(hk, ent.OpCreate)
|
||||
}
|
||||
|
||||
func DeleteOrphans() ent.Hook {
|
||||
hk := func(next ent.Mutator) ent.Mutator {
|
||||
return hook.UserFunc(func(ctx context.Context, m *ent.UserMutation) (ent.Value, error) {
|
||||
id, exists := m.ID()
|
||||
if !exists {
|
||||
return nil, errors.New("id field is missing")
|
||||
}
|
||||
// TODO:
|
||||
// 1. Get the AvatarURL field of the deleted user.
|
||||
// 2. Cascade the deletion to object storage.
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
}
|
||||
// Limit the hook only to "DeleteOne" operations.
|
||||
return hook.On(hk, ent.OpDeleteOne)
|
||||
}
|
||||
```
|
||||
|
||||
Now, you may ask yourself, _how do we access the blob client from the mutations hooks?_ You are going to find out in
|
||||
the next section.
|
||||
|
||||
### Injecting Dependencies
|
||||
|
||||
The [entc.Dependency](https://entgo.io/docs/code-gen/#external-dependencies) option allows extending the generated
|
||||
builders with external dependencies as struct fields, and provides options for injecting them on client initialization.
|
||||
|
||||
To inject a `blob.Bucket` to be available inside our hooks, we can follow the tutorial about external dependencies in
|
||||
[the website](https://entgo.io/docs/code-gen/#external-dependencies), and define the
|
||||
[`gocloud.dev/blob.Bucket`](https://pkg.go.dev/gocloud.dev/blob#Bucket) as a dependency.
|
||||
|
||||
```go title="ent/entc.go" {3-6}
|
||||
func main() {
|
||||
opts := []entc.Option{
|
||||
entc.Dependency(
|
||||
entc.DependencyName("Bucket"),
|
||||
entc.DependencyType(&blob.Bucket{}),
|
||||
),
|
||||
}
|
||||
if err := entc.Generate("./schema", &gen.Config{}, opts...); err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Next, re-run code generation:
|
||||
|
||||
```shell
|
||||
go generate ./ent
|
||||
```
|
||||
|
||||
We can now access the Bucket API from all generated builders. Let's finish the implementations of the above hooks.
|
||||
|
||||
```go title="ent/schema/hooks.go"
|
||||
// EnsureImageExists ensures the avatar_url points
|
||||
// to a real object in the bucket.
|
||||
func EnsureImageExists() ent.Hook {
|
||||
hk := func(next ent.Mutator) ent.Mutator {
|
||||
return hook.UserFunc(func(ctx context.Context, m *ent.UserMutation) (ent.Value, error) {
|
||||
avatarURL, exists := m.AvatarURL()
|
||||
if !exists {
|
||||
return nil, errors.New("avatar field is missing")
|
||||
}
|
||||
switch exists, err := m.Bucket.Exists(ctx, avatarURL); {
|
||||
case err != nil:
|
||||
return nil, fmt.Errorf("check key existence: %w", err)
|
||||
case !exists:
|
||||
return nil, fmt.Errorf("key %q does not exist in the bucket", avatarURL)
|
||||
default:
|
||||
return next.Mutate(ctx, m)
|
||||
}
|
||||
})
|
||||
}
|
||||
return hook.On(hk, ent.OpCreate)
|
||||
}
|
||||
|
||||
// DeleteOrphans cascades the user deletion to the bucket.
|
||||
// Hence, when a user is deleted, its avatar image is deleted
|
||||
// as well.
|
||||
func DeleteOrphans() ent.Hook {
|
||||
hk := func(next ent.Mutator) ent.Mutator {
|
||||
return hook.UserFunc(func(ctx context.Context, m *ent.UserMutation) (ent.Value, error) {
|
||||
id, exists := m.ID()
|
||||
if !exists {
|
||||
return nil, errors.New("id field is missing")
|
||||
}
|
||||
u, err := m.Client().User.Get(ctx, id)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("getting deleted user: %w", err)
|
||||
}
|
||||
if err := m.Bucket.Delete(ctx, u.AvatarURL); err != nil {
|
||||
return nil, fmt.Errorf("deleting user avatar from bucket: %w", err)
|
||||
}
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
}
|
||||
return hook.On(hk, ent.OpDeleteOne)
|
||||
}
|
||||
```
|
||||
|
||||
Now, it's time to test our hooks! Let's write a testable example that verifies that our 2 hooks work as expected.
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"fmt"
|
||||
"log"
|
||||
|
||||
"github.com/a8m/ent-sync-example/ent"
|
||||
_ "github.com/a8m/ent-sync-example/ent/runtime"
|
||||
|
||||
"entgo.io/ent/dialect"
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
"gocloud.dev/blob"
|
||||
_ "gocloud.dev/blob/memblob"
|
||||
)
|
||||
|
||||
func Example_SyncCreate() {
|
||||
ctx := context.Background()
|
||||
// Open an in-memory bucket.
|
||||
bucket, err := blob.OpenBucket(ctx, "mem://photos/")
|
||||
if err != nil {
|
||||
log.Fatal("failed opening bucket:", err)
|
||||
}
|
||||
client, err := ent.Open(
|
||||
dialect.SQLite,
|
||||
"file:ent?mode=memory&cache=shared&_fk=1",
|
||||
// Inject the blob.Bucket on client initialization.
|
||||
ent.Bucket(bucket),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatal("failed opening connection to sqlite:", err)
|
||||
}
|
||||
defer client.Close()
|
||||
if err := client.Schema.Create(ctx); err != nil {
|
||||
log.Fatal("failed creating schema resources:", err)
|
||||
}
|
||||
if err := client.User.Create().SetName("a8m").SetAvatarURL("a8m.png").Exec(ctx); err == nil {
|
||||
log.Fatal("expect user creation to fail because the image does not exist in the bucket")
|
||||
}
|
||||
if err := bucket.WriteAll(ctx, "a8m.png", []byte{255, 255, 255}, nil); err != nil {
|
||||
log.Fatalf("failed uploading image to the bucket: %v", err)
|
||||
}
|
||||
fmt.Printf("%q\n", keys(ctx, bucket))
|
||||
|
||||
// User creation should pass as image was uploaded to the bucket.
|
||||
u := client.User.Create().SetName("a8m").SetAvatarURL("a8m.png").SaveX(ctx)
|
||||
|
||||
// Deleting a user, should delete also its image from the bucket.
|
||||
client.User.DeleteOne(u).ExecX(ctx)
|
||||
fmt.Printf("%q\n", keys(ctx, bucket))
|
||||
|
||||
// Output:
|
||||
// ["a8m.png"]
|
||||
// []
|
||||
}
|
||||
```
|
||||
|
||||
### Wrapping Up
|
||||
|
||||
Great! We have configured Ent to extend our generated code and inject the `blob.Bucket` as an
|
||||
[External Dependency](https://entgo.io/docs/code-gen#external-dependencies). Next, we defined two mutation hooks and
|
||||
used the `blob.Bucket` API to ensure our product constraints are satisfied.
|
||||
|
||||
The code for this example is available at [github.com/a8m/ent-sync-example](https://github.com/a8m/ent-sync-example).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
319
doc/website/blog/2021-11-15-announcing-entoas.md
Normal file
319
doc/website/blog/2021-11-15-announcing-entoas.md
Normal file
@@ -0,0 +1,319 @@
|
||||
---
|
||||
title: Announcing "entoas" - An Extension to Automatically Generate OpenAPI Specification Documents from Ent Schemas
|
||||
author: MasseElch
|
||||
authorURL: "https://github.com/masseelch"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/12862103?v=4"
|
||||
image: https://entgo.io/images/assets/elkopa/entoas-code.png
|
||||
---
|
||||
|
||||
The OpenAPI Specification (OAS, formerly known as Swagger Specification) is a technical specification defining a standard, language-agnostic
|
||||
interface description for REST APIs. This allows both humans and automated tools to understand the described service
|
||||
without the actual source code or additional documentation. Combined with the [Swagger Tooling](https://swagger.io/) you
|
||||
can generate both server and client boilerplate code for more than 20 languages, just by passing in the OAS document.
|
||||
|
||||
In a [previous blogpost](https://entgo.io/blog/2021/09/10/openapi-generator), we presented to you a new
|
||||
feature of the Ent extension [`elk`](https://github.com/masseelch/elk): a fully
|
||||
compliant [OpenAPI Specification](https://swagger.io/resources/open-api/) document generator.
|
||||
|
||||
Today, we are very happy to announce, that the specification generator is now an official extension to the Ent project
|
||||
and has been moved to the [`ent/contrib`](https://github.com/ent/contrib/tree/master/entoas) repository. In addition, we
|
||||
have listened to the feedback of the community and have made some changes to the generator, that we hope you will like.
|
||||
|
||||
### Getting Started
|
||||
|
||||
To use the `entoas` extension use the `entc` (ent codegen) package as
|
||||
described [here](https://entgo.io/docs/code-gen#use-entc-as-a-package). First install the extension to your Go module:
|
||||
|
||||
```shell
|
||||
go get entgo.io/contrib/entoas
|
||||
```
|
||||
|
||||
Now follow the next two steps to enable it and to configure Ent to work with the `entoas` extension:
|
||||
|
||||
1\. Create a new Go file named `ent/entc.go` and paste the following content:
|
||||
|
||||
```go
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/contrib/entoas"
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ex, err := entoas.NewExtension()
|
||||
if err != nil {
|
||||
log.Fatalf("creating entoas extension: %v", err)
|
||||
}
|
||||
err = entc.Generate("./schema", &gen.Config{}, entc.Extensions(ex))
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
2\. Edit the `ent/generate.go` file to execute the `ent/entc.go` file:
|
||||
|
||||
```go
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entc.go
|
||||
```
|
||||
|
||||
With these steps complete, all is set up for generating an OAS document from your schema! If you are new to Ent and want
|
||||
to learn more about it, how to connect to different types of databases, run migrations or work with entities, then head
|
||||
over to the [Setup Tutorial](https://entgo.io/docs/tutorial-setup/).
|
||||
|
||||
### Generate an OAS document
|
||||
|
||||
The first step on our way to the OAS document is to create an Ent schema graph. For the sake of brevity here is an
|
||||
example schema to use:
|
||||
|
||||
```go title="ent/schema/schema.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/edge"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// Fridge holds the schema definition for the Fridge entity.
|
||||
type Fridge struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Fridge.
|
||||
func (Fridge) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("title"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Fridge.
|
||||
func (Fridge) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("compartments", Compartment.Type),
|
||||
}
|
||||
}
|
||||
|
||||
// Compartment holds the schema definition for the Compartment entity.
|
||||
type Compartment struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Compartment.
|
||||
func (Compartment) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Compartment.
|
||||
func (Compartment) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("fridge", Fridge.Type).
|
||||
Ref("compartments").
|
||||
Unique(),
|
||||
edge.To("contents", Item.Type),
|
||||
}
|
||||
}
|
||||
|
||||
// Item holds the schema definition for the Item entity.
|
||||
type Item struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Item.
|
||||
func (Item) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Item.
|
||||
func (Item) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("compartment", Compartment.Type).
|
||||
Ref("contents").
|
||||
Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The code above is the Ent-way to describe a schema-graph. In this particular case we created three Entities: Fridge,
|
||||
Compartment and Item. Additionally, we added some edges to the graph: A Fridge can have many Compartments and a
|
||||
Compartment can contain many Items.
|
||||
|
||||
Now run the code generator:
|
||||
|
||||
```shell
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
In addition to the files Ent normally generates, another file named `ent/openapi.json` has been created. Here is a sneak peek into the file:
|
||||
|
||||
```json title="ent/openapi.json"
|
||||
{
|
||||
"info": {
|
||||
"title": "Ent Schema API",
|
||||
"description": "This is an auto generated API description made out of an Ent schema definition",
|
||||
"termsOfService": "",
|
||||
"contact": {},
|
||||
"license": {
|
||||
"name": ""
|
||||
},
|
||||
"version": "0.0.0"
|
||||
},
|
||||
"paths": {
|
||||
"/compartments": {
|
||||
"get": {
|
||||
[...]
|
||||
```
|
||||
|
||||
If you feel like it, copy its contents and paste them into the [Swagger Editor](https://editor.swagger.io/). It should
|
||||
look like this:
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Swagger Editor" src="https://entgo.io/images/assets/elkopa/1.png" />
|
||||
<p style={{fontSize: 12}}>Swagger Editor</p>
|
||||
</div>
|
||||
|
||||
### Basic Configuration
|
||||
|
||||
The description of our API does not yet reflect what it does, but `entoas` lets you change that! Open up `ent/entc.go`
|
||||
and pass in the updated title and description of our Fridge API:
|
||||
|
||||
```go {16-18} title="ent/entc.go"
|
||||
//go:build ignore
|
||||
// +build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/contrib/entoas"
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
)
|
||||
|
||||
func main() {
|
||||
ex, err := entoas.NewExtension(
|
||||
entoas.SpecTitle("Fridge CMS"),
|
||||
entoas.SpecDescription("API to manage fridges and their cooled contents. **ICY!**"),
|
||||
entoas.SpecVersion("0.0.1"),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("creating entoas extension: %v", err)
|
||||
}
|
||||
err = entc.Generate("./schema", &gen.Config{}, entc.Extensions(ex))
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Rerunning the code generator will create an updated OAS document.
|
||||
|
||||
```json {3-4,10} title="ent/openapi.json"
|
||||
{
|
||||
"info": {
|
||||
"title": "Fridge CMS",
|
||||
"description": "API to manage fridges and their cooled contents. **ICY!**",
|
||||
"termsOfService": "",
|
||||
"contact": {},
|
||||
"license": {
|
||||
"name": ""
|
||||
},
|
||||
"version": "0.0.1"
|
||||
},
|
||||
"paths": {
|
||||
"/compartments": {
|
||||
"get": {
|
||||
[...]
|
||||
```
|
||||
|
||||
### Operation configuration
|
||||
|
||||
There are times when you do not want to generate endpoints for every operation for every node. Fortunately, `entoas`
|
||||
lets us configure what endpoints to generate and which to ignore. `entoas`' default policy is to expose all routes. You
|
||||
can either change this behaviour to not expose any route but those explicitly asked for, or you can just tell `entoas`
|
||||
to exclude a specific operation by using an `entoas.Annotation`. Policies are used to enable / disable the generation
|
||||
of sub-resource operations as well:
|
||||
|
||||
```go {5-10,14-20} title="ent/schema/fridge.go"
|
||||
// Edges of the Fridge.
|
||||
func (Fridge) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("compartments", Compartment.Type).
|
||||
// Do not generate an endpoint for POST /fridges/{id}/compartments
|
||||
Annotations(
|
||||
entoas.CreateOperation(
|
||||
entoas.OperationPolicy(entoas.PolicyExclude),
|
||||
),
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
// Annotations of the Fridge.
|
||||
func (Fridge) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
// Do not generate an endpoint for DELETE /fridges/{id}
|
||||
entoas.DeleteOperation(entoas.OperationPolicy(entoas.PolicyExclude)),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
And voilà! the operations are gone.
|
||||
|
||||
For more information about how `entoas`'s policies work and what you can do with
|
||||
it, have a look at the [godoc](https://pkg.go.dev/entgo.io/contrib/entoas#Config).
|
||||
|
||||
### Simple Models
|
||||
|
||||
By default `entoas` generates one response-schema per endpoint. To learn about the naming strategy have a look at
|
||||
the [godoc](https://pkg.go.dev/entgo.io/contrib/entoas#Config).
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="One Schema per Endpoint" src="https://entgo.io/images/assets/elkopa/6.png" />
|
||||
<p style={{fontSize: 12}}>One Schema per Endpoint</p>
|
||||
</div>
|
||||
|
||||
Many users have requested to change this behaviour to simply map the Ent schema to the OAS document. Therefore, you now
|
||||
can configure `entoas` to do that:
|
||||
|
||||
```go {5}
|
||||
ex, err := entoas.NewExtension(
|
||||
entoas.SpecTitle("Fridge CMS"),
|
||||
entoas.SpecDescription("API to manage fridges and their cooled contents. **ICY!**"),
|
||||
entoas.SpecVersion("0.0.1"),
|
||||
entoas.SimpleModels(),
|
||||
)
|
||||
```
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Simple Schemas" src="https://entgo.io/images/assets/elkopa/5.png" />
|
||||
<p style={{fontSize: 12}}>Simple Schemas</p>
|
||||
</div>
|
||||
|
||||
### Wrapping Up
|
||||
|
||||
In this post we announced `entoas`, the official integration of the former `elk` OpenAPI Specification generation into
|
||||
Ent. This feature connects between Ent's code-generation capabilities and OpenAPI/Swagger's rich tooling ecosystem.
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack/).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
@@ -0,0 +1,253 @@
|
||||
---
|
||||
title: "What I learned contributing my first feature to Ent's gRPC plugin"
|
||||
author: Jeremy Vesperman
|
||||
authorURL: "https://github.com/jeremyv2014"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/9276415?v=4"
|
||||
image: https://entgo.io/images/assets/grpc/ent_party.png
|
||||
---
|
||||
|
||||
I've been writing software for years, but, until recently, I didn't know what an ORM was. I learned many things
|
||||
obtaining my B.S. in Computer Engineering, but Object-Relational Mapping was not one of those; I was too focused on
|
||||
building things out of bits and bytes to be bothered with something that high-level. It shouldn't be too surprising
|
||||
then, that when I found myself tasked with helping to build a distributed web application, I ended up outside my comfort
|
||||
zone.
|
||||
|
||||
One of the difficulties with developing software for someone else is, that you aren't able to see inside their head. The
|
||||
requirements aren't always clear and asking questions only helps you understand so much of what they are looking for.
|
||||
Sometimes, you just have to build a prototype and demonstrate it to get useful feedback.
|
||||
|
||||
The issue with this approach, of course, is that it takes time to develop prototypes, and you need to pivot frequently.
|
||||
If you were like me and didn't know what an ORM was, you would waste a lot of time doing simple, but time-consuming
|
||||
tasks:
|
||||
1. Re-define the data model with new customer feedback.
|
||||
2. Re-create the test database.
|
||||
3. Re-write the SQL statements for interfacing with the database.
|
||||
4. Re-define the gRPC interface between the backend and frontend services.
|
||||
5. Re-design the frontend and web interface.
|
||||
6. Demonstrate to customer and get feedback
|
||||
7. Repeat
|
||||
|
||||
Hundreds of hours of work only to find out that everything needs to be re-written. So frustrating! I think you can
|
||||
imagine my relief (and also embarrassment), when a senior developer asked me why I wasn't using an ORM
|
||||
like Ent.
|
||||
|
||||
|
||||
### Discovering Ent
|
||||
It only took one day to re-implement our current data model with Ent. I couldn't believe I had been doing all this work
|
||||
by hand when such a framework existed! The gRPC integration through entproto was the icing on the cake! I could perform
|
||||
basic CRUD operations over gRPC just by adding a few annotations to my schema. This allows me to skip all the steps
|
||||
between data model definition and re-designing the web interface! There was, however, just one problem for my use case:
|
||||
How do you get the details of entities over the gRPC interface if you don't know their IDs ahead of time? I see that
|
||||
Ent can query all, but where is the `GetAll` method for entproto?
|
||||
|
||||
### Becoming an Open-Source Contributor
|
||||
I was surprised to find it didn't exist! I could have added it to my project by implementing the feature in a separate
|
||||
service, but it seemed like a generic enough method to be generally useful. For years, I had wanted
|
||||
to find an open-source project that I could meaningfully contribute to; this seemed like the perfect opportunity!
|
||||
|
||||
So, after poking around entproto's source into the early morning hours, I managed to hack the feature in! Feeling
|
||||
accomplished, I opened a pull request and headed off to sleep, not realizing the learning experience I had just signed
|
||||
myself up for.
|
||||
|
||||
In the morning, I awoke to the disappointment of my pull request being closed by [Rotem](https://github.com/rotemtam),
|
||||
but with an invitation to collaborate further to refine the idea. The reason for closing the request was obvious, my
|
||||
implementation of `GetAll` was dangerous. Returning an entire table's worth of data is only feasible if the table is
|
||||
small. Exposing this interface on a large table could have disastrous results!
|
||||
|
||||
### Optional Service Method Generation
|
||||
My solution was to make the `GetAll` method optional by passing an argument into `entproto.Service()`. This
|
||||
provides control over whether this feature is exposed. We decided that this was a desirable feature, but that
|
||||
it should be more generic. Why should `GetAll` get special treatment just because it was added last? It would be better
|
||||
if all methods could be optionally generated. Something like:
|
||||
```go
|
||||
entproto.Service(entproto.Methods(entproto.Create | entproto.Get))
|
||||
```
|
||||
However, to keep everything backwards-compatible, an empty `entproto.Service()` annotation would also need to generate
|
||||
all methods. I'm not a Go expert, so the only way I knew of to do this was with a variadic function:
|
||||
```go
|
||||
func Service(methods ...Method)
|
||||
```
|
||||
The problem with this approach is that you can only have one argument type that is variable length. What if we wanted to
|
||||
add additional options to the service annotation later on? This is where I was introduced to the powerful design pattern
|
||||
of [functional options](https://dave.cheney.net/2014/10/17/functional-options-for-friendly-apis):
|
||||
|
||||
```go
|
||||
// ServiceOption configures the entproto.Service annotation.
|
||||
type ServiceOption func(svc *service)
|
||||
|
||||
// Service annotates an ent.Schema to specify that protobuf service generation is required for it.
|
||||
func Service(opts ...ServiceOption) schema.Annotation {
|
||||
s := service{
|
||||
Generate: true,
|
||||
}
|
||||
for _, apply := range opts {
|
||||
apply(&s)
|
||||
}
|
||||
// Default to generating all methods
|
||||
if s.Methods == 0 {
|
||||
s.Methods = MethodAll
|
||||
}
|
||||
return s
|
||||
}
|
||||
```
|
||||
This approach takes in a variable number of functions that are called to set options on a struct, in this case, our
|
||||
service annotation. With this approach, we can implement any number of other options functions aside from `Methods`.
|
||||
Very cool!
|
||||
|
||||
### List: The Superior GetAll
|
||||
With optional method generation out of the way, we could return our focus to adding `GetAll`. How could we implement
|
||||
this method in a safe fashion? Rotem suggested we base the method off of Google's API Improvement Proposal (AIP) for List,
|
||||
[AIP-132](https://google.aip.dev/132). This approach allows a client to retrieve all entities, but breaks the retrieval
|
||||
up into pages. As an added bonus, it also sounds better than "GetAll"!
|
||||
|
||||
|
||||
### List Request
|
||||
With this design, a request message would look like:
|
||||
```protobuf
|
||||
message ListUserRequest {
|
||||
int32 page_size = 1;
|
||||
|
||||
string page_token = 2;
|
||||
|
||||
View view = 3;
|
||||
|
||||
enum View {
|
||||
VIEW_UNSPECIFIED = 0;
|
||||
|
||||
BASIC = 1;
|
||||
|
||||
WITH_EDGE_IDS = 2;
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
#### Page Size
|
||||
The `page_size` field allows the client to specify the maximum number of entries they want to receive in the
|
||||
response message, subject to a maximum page size of 1000. This eliminates the issue of returning more results than the
|
||||
client can handle in the initial `GetAll` implementation. Additionally, the maximum page size was implemented to prevent
|
||||
a client from overburdening the server.
|
||||
|
||||
#### Page Token
|
||||
The `page_token` field is a base64-encoded string utilized by the server to determine where the next page begins. An
|
||||
empty token means that we want the first page.
|
||||
|
||||
#### View
|
||||
The `view` field is used to specify whether the response should return the edge IDs associated with the entities.
|
||||
|
||||
|
||||
### List Response
|
||||
The response message would look like:
|
||||
```protobuf
|
||||
message ListUserResponse {
|
||||
repeated User user_list = 1;
|
||||
|
||||
string next_page_token = 2;
|
||||
}
|
||||
```
|
||||
|
||||
#### List
|
||||
The `user_list` field contains page entities.
|
||||
|
||||
#### Next Page Token
|
||||
The `next_page_token` field is a base64-encoded string that can be utilized in another List request to retrieve the next
|
||||
page of entities. An empty token means that this response contains the last page of entities.
|
||||
|
||||
|
||||
### Pagination
|
||||
With the gRPC interface determined, the challenge of implementing it began. One of the most critical design decisions
|
||||
was how to implement the pagination. The naive approach would be to use `LIMIT/OFFSET` pagination to skip over
|
||||
the entries we've already seen. However, this approach has massive [drawbacks](https://use-the-index-luke.com/no-offset);
|
||||
the most problematic being that the database has to _fetch all the rows it is skipping_ to get the rows we want.
|
||||
|
||||
#### Keyset Pagination
|
||||
Rotem proposed a much better approach: keyset pagination. This approach is slightly more
|
||||
complicated since it requires the use of a unique column (or combination of columns) to order the rows. But
|
||||
in exchange we gain a significant performance improvement. This is because we can take advantage of the sorted rows to select only entries with
|
||||
unique column(s) values that are greater (ascending order) or less (descending order) than / equal to the value(s) in
|
||||
the client-provided page token. Thus, the database doesn't have to fetch the rows we want to skip over, significantly
|
||||
speeding up queries on large tables!
|
||||
|
||||
With keyset pagination selected, the next step was to determine how to order the entities. The most straightforward
|
||||
approach for Ent was to use the `id` field; every schema will have this, and it is guaranteed to be unique for the schema.
|
||||
This is the approach we chose to use for the initial implementation. Additionally, a decision needed to be made regarding
|
||||
whether ascending or descending order should be employed. Descending order was chosen for the initial release.
|
||||
|
||||
|
||||
### Usage
|
||||
Let's take a look at how to actually use the new `List` feature:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
|
||||
"ent-grpc-example/ent/proto/entpb"
|
||||
"google.golang.org/grpc"
|
||||
"google.golang.org/grpc/status"
|
||||
)
|
||||
|
||||
func main() {
|
||||
// Open a connection to the server.
|
||||
conn, err := grpc.Dial(":5000", grpc.WithInsecure())
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to server: %s", err)
|
||||
}
|
||||
defer conn.Close()
|
||||
// Create a User service Client on the connection.
|
||||
client := entpb.NewUserServiceClient(conn)
|
||||
ctx := context.Background()
|
||||
// Initialize token for first page.
|
||||
pageToken := ""
|
||||
// Retrieve all pages of users.
|
||||
for {
|
||||
// Ask the server for the next page of users, limiting entries to 100.
|
||||
users, err := client.List(ctx, &entpb.ListUserRequest{
|
||||
PageSize: 100,
|
||||
PageToken: pageToken,
|
||||
})
|
||||
if err != nil {
|
||||
se, _ := status.FromError(err)
|
||||
log.Fatalf("failed retrieving user list: status=%s message=%s", se.Code(), se.Message())
|
||||
}
|
||||
// Check if we've reached the last page of users.
|
||||
if users.NextPageToken == "" {
|
||||
break
|
||||
}
|
||||
// Update token for next request.
|
||||
pageToken = users.NextPageToken
|
||||
log.Printf("users retrieved: %v", users)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
|
||||
### Looking Ahead
|
||||
The current implementation of `List` has a few limitations that can be addressed in future revisions. First, sorting is
|
||||
limited to the `id` column. This makes `List` compatible with any schema, but it isn't very flexible. Ideally, the client
|
||||
should be able to specify what columns to sort by. Alternatively, the sort column(s) could be defined in the schema.
|
||||
Additionally, `List` is restricted to descending order. In the future, this could be an option specified in the request.
|
||||
Finally, `List` currently only works with schemas that use `int32`, `uuid`, or `string` type `id` fields. This is because
|
||||
a separate conversion method to/from the page token must be defined for each type that Ent supports in the code generation
|
||||
template (I'm only one person!).
|
||||
|
||||
|
||||
### Wrap-up
|
||||
I was pretty nervous when I first embarked on my quest to contribute this functionality to entproto; as a newbie open-source
|
||||
contributor, I didn't know what to expect. I'm happy to share that working on the Ent project was a ton of fun!
|
||||
I got to work with awesome, knowledgeable people while helping out the open-source community. From functional
|
||||
options and keyset pagination to smaller insights gained through PR review, I learned so much about Go
|
||||
(and software development in general) in the process! I'd highly encourage anyone thinking they might want to contribute
|
||||
something to take that leap! You'll be surprised with how much you gain from the experience.
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack/).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
616
doc/website/blog/2022-01-04-serverless-graphql-using-aws.md
Normal file
616
doc/website/blog/2022-01-04-serverless-graphql-using-aws.md
Normal file
@@ -0,0 +1,616 @@
|
||||
---
|
||||
title: Serverless GraphQL using with AWS and ent
|
||||
author: Bodo Kaiser
|
||||
authorURL: "https://github.com/bodokaiser"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/1780466?v=4"
|
||||
image: https://entgo.io/images/assets/appsync/share.png
|
||||
---
|
||||
|
||||
[GraphQL][1] is a query language for HTTP APIs, providing a statically-typed interface to conveniently represent today's complex data hierarchies.
|
||||
One way to use GraphQL is to import a library implementing a GraphQL server to which one registers custom resolvers implementing the database interface.
|
||||
An alternative way is to use a GraphQL cloud service to implement the GraphQL server and register serverless cloud functions as resolvers.
|
||||
Among the many benefits of cloud services, one of the biggest practical advantages is the resolvers' independence and composability.
|
||||
For example, we can write one resolver to a relational database and another to a search database.
|
||||
|
||||
We consider such a kind of setup using [Amazon Web Services (AWS)][2] in the following. In particular, we use [AWS AppSync][3] as the GraphQL cloud service and [AWS Lambda][4] to run a relational database resolver, which we implement using [Go][5] with [Ent][6] as the entity framework.
|
||||
Compared to Nodejs, the most popular runtime for AWS Lambda, Go offers faster start times, higher performance, and, from my point of view, an improved developer experience.
|
||||
As an additional complement, Ent presents an innovative approach towards type-safe access to relational databases, which, in my opinion, is unmatched in the Go ecosystem.
|
||||
In conclusion, running Ent with AWS Lambda as AWS AppSync resolvers is an extremely powerful setup to face today's demanding API requirements.
|
||||
|
||||
In the next sections, we set up GraphQL in AWS AppSync and the AWS Lambda function running Ent.
|
||||
Subsequently, we propose a Go implementation integrating Ent and the AWS Lambda event handler, followed by performing a quick test of the Ent function.
|
||||
Finally, we register it as a data source to our AWS AppSync API and configure the resolvers, which define the mapping from GraphQL requests to AWS Lambda events.
|
||||
Be aware that this tutorial requires an AWS account and **the URL to a publicly-accessible Postgres database**, which may incur costs.
|
||||
|
||||
### Setting up AWS AppSync schema
|
||||
|
||||
To set up the GraphQL schema in AWS AppSync, sign in to your AWS account and select the AppSync service through the navbar.
|
||||
The landing page of the AppSync service should render you a "Create API" button, which you may click to arrive at the "Getting Started" page:
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of getting started with AWS AppSync from scratch" src="https://entgo.io/images/assets/appsync/from-scratch.png" />
|
||||
<p style={{fontSize: 12}}>Getting started from scratch with AWS AppSync</p>
|
||||
</div>
|
||||
|
||||
In the top panel reading "Customize your API or import from Amazon DynamoDB" select the option "Build from scratch" and click the "Start" button belonging to the panel.
|
||||
You should now see a form where you may insert the API name.
|
||||
For the present tutorial, we type "Todo", see the screenshot below, and click the "Create" button.
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of creating a new AWS AppSync API resource" src="https://entgo.io/images/assets/appsync/create-resources.png" />
|
||||
<p style={{fontSize: 12}}>Creating a new API resource in AWS AppSync</p>
|
||||
</div>
|
||||
|
||||
After creating the AppSync API, you should see a landing page showing a panel to define the schema, a panel to query the API, and a panel on integrating AppSync into your app as captured in the screenshot below.
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of the landing page of the AWS AppSync API" src="https://entgo.io/images/assets/appsync/getting-started.png" />
|
||||
<p style={{fontSize: 12}}>Landing page of the AWS AppSync API</p>
|
||||
</div>
|
||||
|
||||
Click the "Edit Schema" button in the first panel and replace the previous schema with the following GraphQL schema:
|
||||
|
||||
```graphql
|
||||
input AddTodoInput {
|
||||
title: String!
|
||||
}
|
||||
|
||||
type AddTodoOutput {
|
||||
todo: Todo!
|
||||
}
|
||||
|
||||
type Mutation {
|
||||
addTodo(input: AddTodoInput!): AddTodoOutput!
|
||||
removeTodo(input: RemoveTodoInput!): RemoveTodoOutput!
|
||||
}
|
||||
|
||||
type Query {
|
||||
todos: [Todo!]!
|
||||
todo(id: ID!): Todo
|
||||
}
|
||||
|
||||
input RemoveTodoInput {
|
||||
todoId: ID!
|
||||
}
|
||||
|
||||
type RemoveTodoOutput {
|
||||
todo: Todo!
|
||||
}
|
||||
|
||||
type Todo {
|
||||
id: ID!
|
||||
title: String!
|
||||
}
|
||||
|
||||
schema {
|
||||
query: Query
|
||||
mutation: Mutation
|
||||
}
|
||||
```
|
||||
|
||||
After replacing the schema, a short validation runs and you should be able to click the "Save Schema" button on the top right corner and find yourself with the following view:
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot AWS AppSync: Final GraphQL schema for AWS AppSync API" src="https://entgo.io/images/assets/appsync/final-schema.png" />
|
||||
<p style={{fontSize: 12}}>Final GraphQL schema of AWS AppSync API</p>
|
||||
</div>
|
||||
|
||||
If we sent GraphQL requests to our AppSync API, the API would return errors as no resolvers have been attached to the schema.
|
||||
We will configure the resolvers after deploying the Ent function via AWS Lambda.
|
||||
|
||||
Explaining the present GraphQL schema in detail is beyond the scope of this tutorial.
|
||||
In short, the GraphQL schema implements a list todos operation via `Query.todos`, a single read todo operation via `Query.todo`, a create todo operation via `Mutation.createTodo`, and a delete operation via `Mutation.deleteTodo`.
|
||||
The GraphQL API is similar to a simple REST API design of an `/todos` resource, where we would use `GET /todos`, `GET /todos/:id`, `POST /todos`, and `DELETE /todos/:id`.
|
||||
For details on the GraphQL schema design, e.g., the arguments and returns from the `Query` and `Mutation` objects, I follow the practices from the [GitHub GraphQL API](https://docs.github.com/en/graphql/reference/queries).
|
||||
|
||||
### Setting up AWS Lambda
|
||||
|
||||
With the AppSync API in place, our next stop is the AWS Lambda function to run Ent.
|
||||
For this, we navigate to the AWS Lambda service through the navbar, which leads us to the landing page of the AWS Lambda service listing our functions:
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of AWS Lambda landing page listing functions" src="https://entgo.io/images/assets/appsync/function-list.png" />
|
||||
<p style={{fontSize: 12}}>AWS Lambda landing page showing functions.</p>
|
||||
</div>
|
||||
|
||||
We click the "Create function" button on the top right and select "Author from scratch" in the upper panel.
|
||||
Furthermore, we name the function "ent", set the runtime to "Go 1.x", and click the "Create function" button at the bottom.
|
||||
We should then find ourselves viewing the landing page of our "ent" function:
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of AWS Lambda landing page listing functions" src="https://entgo.io/images/assets/appsync/function-overview.png" />
|
||||
<p style={{fontSize: 12}}>AWS Lambda function overview of the Ent function.</p>
|
||||
</div>
|
||||
|
||||
Before reviewing the Go code and uploading the compiled binary, we need to adjust some default settings of the "ent" function.
|
||||
First, we change the default handler name from `hello` to `main`, which equals the filename of the compiled Go binary:
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of AWS Lambda landing page listing functions" src="https://entgo.io/images/assets/appsync/runtime-settings.png" />
|
||||
<p style={{fontSize: 12}}>AWS Lambda runtime settings of Ent function.</p>
|
||||
</div>
|
||||
|
||||
Second, we add an environment the variable `DATABASE_URL` encoding the database network parameters and credentials:
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of AWS Lambda landing page listing functions" src="https://entgo.io/images/assets/appsync/envars.png" />
|
||||
<p style={{fontSize: 12}}>AWS Lambda environment variables settings of Ent function.</p>
|
||||
</div>
|
||||
|
||||
To open a connection to the database, pass in a [DSN](https://en.wikipedia.org/wiki/Data_source_name), e.g., `postgres://username:password@hostname/dbname`.
|
||||
By default, AWS Lambda encrypts the environment variables, making them a fast and safe mechanism to supply database connection parameters.
|
||||
Alternatively, one can use the AWS Secretsmanager service and dynamically request credentials during the Lambda function's cold start, allowing, among others, rotating credentials.
|
||||
A third option is to use AWS IAM to handle the database authorization.
|
||||
|
||||
If you created your Postgres database in AWS RDS, the default username and database name is `postgres`.
|
||||
The password can be reset by modifying the AWS RDS instance.
|
||||
|
||||
### Setting up Ent and deploying AWS Lambda
|
||||
|
||||
We now review, compile and deploy the database Go binary to the "ent" function.
|
||||
You can find the complete source code in [bodokaiser/entgo-aws-appsync](https://github.com/bodokaiser/entgo-aws-appsync).
|
||||
|
||||
First, we create an empty directory to which we change:
|
||||
|
||||
```console
|
||||
mkdir entgo-aws-appsync
|
||||
cd entgo-aws-appsync
|
||||
```
|
||||
|
||||
Second, we initiate a new Go module to contain our project:
|
||||
|
||||
```console
|
||||
go mod init entgo-aws-appsync
|
||||
```
|
||||
|
||||
Third, we create the `Todo` schema while pulling in the ent dependencies:
|
||||
|
||||
```console
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new Todo
|
||||
```
|
||||
|
||||
and add the `title` field:
|
||||
|
||||
```go {15-17} title="ent/schema/todo.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// Todo holds the schema definition for the Todo entity.
|
||||
type Todo struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Todo.
|
||||
func (Todo) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("title"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Todo.
|
||||
func (Todo) Edges() []ent.Edge {
|
||||
return nil
|
||||
}
|
||||
```
|
||||
Finally, we perform the Ent code generation:
|
||||
```console
|
||||
go generate ./ent
|
||||
```
|
||||
|
||||
Using Ent, we write a set of resolver functions, which implement the create, read, and delete operations on the todos:
|
||||
|
||||
```go title="internal/handler/resolver.go"
|
||||
package resolver
|
||||
|
||||
import (
|
||||
"context"
|
||||
"fmt"
|
||||
"strconv"
|
||||
|
||||
"entgo-aws-appsync/ent"
|
||||
"entgo-aws-appsync/ent/todo"
|
||||
)
|
||||
|
||||
// TodosInput is the input to the Todos query.
|
||||
type TodosInput struct{}
|
||||
|
||||
// Todos queries all todos.
|
||||
func Todos(ctx context.Context, client *ent.Client, input TodosInput) ([]*ent.Todo, error) {
|
||||
return client.Todo.
|
||||
Query().
|
||||
All(ctx)
|
||||
}
|
||||
|
||||
// TodoByIDInput is the input to the TodoByID query.
|
||||
type TodoByIDInput struct {
|
||||
ID string `json:"id"`
|
||||
}
|
||||
|
||||
// TodoByID queries a single todo by its id.
|
||||
func TodoByID(ctx context.Context, client *ent.Client, input TodoByIDInput) (*ent.Todo, error) {
|
||||
tid, err := strconv.Atoi(input.ID)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("failed parsing todo id: %w", err)
|
||||
}
|
||||
return client.Todo.
|
||||
Query().
|
||||
Where(todo.ID(tid)).
|
||||
Only(ctx)
|
||||
}
|
||||
|
||||
// AddTodoInput is the input to the AddTodo mutation.
|
||||
type AddTodoInput struct {
|
||||
Title string `json:"title"`
|
||||
}
|
||||
|
||||
// AddTodoOutput is the output to the AddTodo mutation.
|
||||
type AddTodoOutput struct {
|
||||
Todo *ent.Todo `json:"todo"`
|
||||
}
|
||||
|
||||
// AddTodo adds a todo and returns it.
|
||||
func AddTodo(ctx context.Context, client *ent.Client, input AddTodoInput) (*AddTodoOutput, error) {
|
||||
t, err := client.Todo.
|
||||
Create().
|
||||
SetTitle(input.Title).
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("failed creating todo: %w", err)
|
||||
}
|
||||
return &AddTodoOutput{Todo: t}, nil
|
||||
}
|
||||
|
||||
// RemoveTodoInput is the input to the RemoveTodo mutation.
|
||||
type RemoveTodoInput struct {
|
||||
TodoID string `json:"todoId"`
|
||||
}
|
||||
|
||||
// RemoveTodoOutput is the output to the RemoveTodo mutation.
|
||||
type RemoveTodoOutput struct {
|
||||
Todo *ent.Todo `json:"todo"`
|
||||
}
|
||||
|
||||
// RemoveTodo removes a todo and returns it.
|
||||
func RemoveTodo(ctx context.Context, client *ent.Client, input RemoveTodoInput) (*RemoveTodoOutput, error) {
|
||||
t, err := TodoByID(ctx, client, TodoByIDInput{ID: input.TodoID})
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("failed querying todo with id %q: %w", input.TodoID, err)
|
||||
}
|
||||
err = client.Todo.
|
||||
DeleteOne(t).
|
||||
Exec(ctx)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("failed deleting todo with id %q: %w", input.TodoID, err)
|
||||
}
|
||||
return &RemoveTodoOutput{Todo: t}, nil
|
||||
}
|
||||
```
|
||||
|
||||
Using input structs for the resolver functions allows for mapping the GraphQL request arguments.
|
||||
Using output structs allows for returning multiple objects for more complex operations.
|
||||
|
||||
To map the Lambda event to a resolver function, we implement a Handler, which performs the mapping according to an `action` field in the event:
|
||||
|
||||
```go title="internal/handler/handler.go"
|
||||
package handler
|
||||
|
||||
import (
|
||||
"context"
|
||||
"encoding/json"
|
||||
"fmt"
|
||||
"log"
|
||||
|
||||
"entgo-aws-appsync/ent"
|
||||
"entgo-aws-appsync/internal/resolver"
|
||||
)
|
||||
|
||||
// Action specifies the event type.
|
||||
type Action string
|
||||
|
||||
// List of supported event actions.
|
||||
const (
|
||||
ActionMigrate Action = "migrate"
|
||||
|
||||
ActionTodos = "todos"
|
||||
ActionTodoByID = "todoById"
|
||||
ActionAddTodo = "addTodo"
|
||||
ActionRemoveTodo = "removeTodo"
|
||||
)
|
||||
|
||||
// Event is the argument of the event handler.
|
||||
type Event struct {
|
||||
Action Action `json:"action"`
|
||||
Input json.RawMessage `json:"input"`
|
||||
}
|
||||
|
||||
// Handler handles supported events.
|
||||
type Handler struct {
|
||||
client *ent.Client
|
||||
}
|
||||
|
||||
// Returns a new event handler.
|
||||
func New(c *ent.Client) *Handler {
|
||||
return &Handler{
|
||||
client: c,
|
||||
}
|
||||
}
|
||||
|
||||
// Handle implements the event handling by action.
|
||||
func (h *Handler) Handle(ctx context.Context, e Event) (interface{}, error) {
|
||||
log.Printf("action %s with payload %s\n", e.Action, e.Input)
|
||||
|
||||
switch e.Action {
|
||||
case ActionMigrate:
|
||||
return nil, h.client.Schema.Create(ctx)
|
||||
case ActionTodos:
|
||||
var input resolver.TodosInput
|
||||
return resolver.Todos(ctx, h.client, input)
|
||||
case ActionTodoByID:
|
||||
var input resolver.TodoByIDInput
|
||||
if err := json.Unmarshal(e.Input, &input); err != nil {
|
||||
return nil, fmt.Errorf("failed parsing %s params: %w", ActionTodoByID, err)
|
||||
}
|
||||
return resolver.TodoByID(ctx, h.client, input)
|
||||
case ActionAddTodo:
|
||||
var input resolver.AddTodoInput
|
||||
if err := json.Unmarshal(e.Input, &input); err != nil {
|
||||
return nil, fmt.Errorf("failed parsing %s params: %w", ActionAddTodo, err)
|
||||
}
|
||||
return resolver.AddTodo(ctx, h.client, input)
|
||||
case ActionRemoveTodo:
|
||||
var input resolver.RemoveTodoInput
|
||||
if err := json.Unmarshal(e.Input, &input); err != nil {
|
||||
return nil, fmt.Errorf("failed parsing %s params: %w", ActionRemoveTodo, err)
|
||||
}
|
||||
return resolver.RemoveTodo(ctx, h.client, input)
|
||||
}
|
||||
|
||||
return nil, fmt.Errorf("invalid action %q", e.Action)
|
||||
}
|
||||
```
|
||||
|
||||
In addition to the resolver actions, we also added a migration action, which is a convenient way to expose database migrations.
|
||||
|
||||
Finally, we need to register an instance of the `Handler` type to the AWS Lambda library.
|
||||
|
||||
```go title="lambda/main.go"
|
||||
package main
|
||||
|
||||
import (
|
||||
"database/sql"
|
||||
"log"
|
||||
"os"
|
||||
|
||||
"entgo.io/ent/dialect"
|
||||
entsql "entgo.io/ent/dialect/sql"
|
||||
|
||||
"github.com/aws/aws-lambda-go/lambda"
|
||||
_ "github.com/jackc/pgx/v4/stdlib"
|
||||
|
||||
"entgo-aws-appsync/ent"
|
||||
"entgo-aws-appsync/internal/handler"
|
||||
)
|
||||
|
||||
func main() {
|
||||
// open the database connection using the pgx driver
|
||||
db, err := sql.Open("pgx", os.Getenv("DATABASE_URL"))
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening database connection: %v", err)
|
||||
}
|
||||
|
||||
// initiate the ent database client for the Postgres database
|
||||
client := ent.NewClient(ent.Driver(entsql.OpenDB(dialect.Postgres, db)))
|
||||
defer client.Close()
|
||||
|
||||
// register our event handler to listen on Lambda events
|
||||
lambda.Start(handler.New(client).Handle)
|
||||
}
|
||||
```
|
||||
|
||||
The function body of `main` is executed whenever an AWS Lambda performs a cold start.
|
||||
After the cold start, a Lambda function is considered "warm," with only the event handler code being executed, making Lambda executions very efficient.
|
||||
|
||||
To compile and deploy the Go code, we run:
|
||||
|
||||
```console
|
||||
GOOS=linux go build -o main ./lambda
|
||||
zip function.zip main
|
||||
aws lambda update-function-code --function-name ent --zip-file fileb://function.zip
|
||||
```
|
||||
|
||||
The first command creates a compiled binary named `main`.
|
||||
The second command compresses the binary to a ZIP archive, required by AWS Lambda.
|
||||
The third command replaces the function code of the AWS Lambda named `ent` with the new ZIP archive.
|
||||
If you work with multiple AWS accounts you want to use the `--profile <your aws profile>` switch.
|
||||
|
||||
After you successfully deployed the AWS Lambda, open the "Test" tab of the "ent" function in the web console and invoke it with a "migrate" action:
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of invoking the Ent Lambda with a migrate action" src="https://entgo.io/images/assets/appsync/execution-result.png" />
|
||||
<p style={{fontSize: 12}}>Invoking Lambda with a "migrate" action</p>
|
||||
</div>
|
||||
|
||||
On success, you should get a green feedback box and test the result of a "todos" action:
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of invoking the Ent Lambda with a todos action" src="https://entgo.io/images/assets/appsync/execution-result2.png" />
|
||||
<p style={{fontSize: 12}}>Invoking Lambda with a "todos" action</p>
|
||||
</div>
|
||||
|
||||
In case the test executions fail, you most probably have an issue with your database connection.
|
||||
|
||||
### Configuring AWS AppSync resolvers
|
||||
|
||||
With the "ent" function successfully deployed, we are left to register the ent Lambda as a data source to our AppSync API and configure the schema resolvers to map the AppSync requests to Lambda events.
|
||||
First, open our AWS AppSync API in the web console and move to "Data Sources", which you find in the navigation pane on the left.
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of the list of data sources registered to the AWS AppSync API" src="https://entgo.io/images/assets/appsync/data-sources.png" />
|
||||
<p style={{fontSize: 12}}>List of data sources registered to the AWS AppSync API</p>
|
||||
</div>
|
||||
|
||||
Click the "Create data source" button in the top right to start registering the "ent" function as data source:
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot registering the ent Lambda as data source to the AWS AppSync API" src="https://entgo.io/images/assets/appsync/new-data-source.png" />
|
||||
<p style={{fontSize: 12}}>Registering the ent Lambda as data source to the AWS AppSync API</p>
|
||||
</div>
|
||||
|
||||
Now, open the GraphQL schema of the AppSync API and search for the `Query` type in the sidebar to the right.
|
||||
Click the "Attach" button next to the `Query.Todos` type:
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot attaching a resolver to Query type in the AWS AppSync API" src="https://entgo.io/images/assets/appsync/todo-schema.png" />
|
||||
<p style={{fontSize: 12}}>Attaching a resolver for the todos Query in the AWS AppSync API</p>
|
||||
</div>
|
||||
|
||||
In the resolver view for `Query.todos`, select the Lambda function as data source, enable the request mapping template option,
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot configuring the resolver mapping for the todos Query in the AWS AppSync API" src="https://entgo.io/images/assets/appsync/edit-resolver.png" />
|
||||
<p style={{fontSize: 12}}>Configuring the resolver mapping for the todos Query in the AWS AppSync API</p>
|
||||
</div>
|
||||
|
||||
and copy the following template:
|
||||
|
||||
```vtl title="Query.todos"
|
||||
{
|
||||
"version" : "2017-02-28",
|
||||
"operation": "Invoke",
|
||||
"payload": {
|
||||
"action": "todos"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Repeat the same procedure for the remaining `Query` and `Mutation` types:
|
||||
|
||||
|
||||
```vtl title="Query.todo"
|
||||
{
|
||||
"version" : "2017-02-28",
|
||||
"operation": "Invoke",
|
||||
"payload": {
|
||||
"action": "todo",
|
||||
"input": $util.toJson($context.args.input)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```vtl title="Mutation.addTodo"
|
||||
{
|
||||
"version" : "2017-02-28",
|
||||
"operation": "Invoke",
|
||||
"payload": {
|
||||
"action": "addTodo",
|
||||
"input": $util.toJson($context.args.input)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```vtl title="Mutation.removeTodo"
|
||||
{
|
||||
"version" : "2017-02-28",
|
||||
"operation": "Invoke",
|
||||
"payload": {
|
||||
"action": "removeTodo",
|
||||
"input": $util.toJson($context.args.input)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The request mapping templates let us construct the event objects with which we invoke the Lambda functions.
|
||||
Through the `$context` object, we have access to the GraphQL request and the authentication session.
|
||||
In addition, it is possible to arrange multiple resolvers sequentially and reference the respective outputs via the `$context` object.
|
||||
In principle, it is also possible to define response mapping templates.
|
||||
However, in most cases it is sufficient enough to return the response object "as is".
|
||||
|
||||
### Testing AppSync using the Query explorer
|
||||
|
||||
The easiest way to test the API is to use the Query Explorer in AWS AppSync.
|
||||
Alternatively, one can register an API key in the settings of their AppSync API and use any standard GraphQL client.
|
||||
|
||||
Let us first create a todo with the title `foo`:
|
||||
|
||||
```graphql
|
||||
mutation MyMutation {
|
||||
addTodo(input: {title: "foo"}) {
|
||||
todo {
|
||||
id
|
||||
title
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of an executed addTodo Mutation using the AppSync Query Explorer" src="https://entgo.io/images/assets/appsync/todo-queries.png" />
|
||||
<p style={{fontSize: 12}}>"addTodo" Mutation using the AppSync Query Explorer</p>
|
||||
</div>
|
||||
|
||||
Requesting a list of the todos should return a single todo with title `foo`:
|
||||
|
||||
```graphql
|
||||
query MyQuery {
|
||||
todos {
|
||||
title
|
||||
id
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of an executed addTodo Mutation using the AppSync Query Explorer" src="https://entgo.io/images/assets/appsync/todo-queries-3.png" />
|
||||
<p style={{fontSize: 12}}>"addTodo" Mutation using the AppSync Query Explorer</p>
|
||||
</div>
|
||||
|
||||
Requesting the `foo` todo by id should work too:
|
||||
|
||||
```graphql
|
||||
query MyQuery {
|
||||
todo(id: "1") {
|
||||
title
|
||||
id
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Screenshot of an executed addTodo Mutation using the AppSync Query Explorer" src="https://entgo.io/images/assets/appsync/todo-queries-4.png" />
|
||||
<p style={{fontSize: 12}}>"addTodo" Mutation using the AppSync Query Explorer</p>
|
||||
</div>
|
||||
|
||||
### Wrapping Up
|
||||
|
||||
We successfully deployed a serverless GraphQL API for managing simple todos using AWS AppSync, AWS Lambda, and Ent.
|
||||
In particular, we provided step-by-step instructions on configuring AWS AppSync and AWS Lambda through the web console.
|
||||
In addition, we discussed a proposal for how to structure our Go code.
|
||||
|
||||
We did not cover testing and setting up a database infrastructure in AWS.
|
||||
These aspects become more challenging in the serverless than the traditional paradigm.
|
||||
For example, when many Lambda functions are cold started in parallel, we quickly exhaust the database's connection pool and need some database proxy.
|
||||
In addition, we need to rethink testing as we only have access to local and end-to-end tests because we cannot run cloud services easily in isolation.
|
||||
|
||||
Nevertheless, the proposed GraphQL server scales well into the complex demands of real-world applications benefiting from the serverless infrastructure and Ent's pleasurable developer experience.
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or Slack channel](https://entgo.io/docs/slack/).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
|
||||
[1]: https://graphql.org
|
||||
[2]: https://aws.amazon.com
|
||||
[3]: https://aws.amazon.com/appsync/
|
||||
[4]: https://aws.amazon.com/lambda/
|
||||
[5]: https://go.dev
|
||||
[6]: https://entgo.io
|
||||
235
doc/website/blog/2022-01-20-announcing-new-migration-engine.md
Normal file
235
doc/website/blog/2022-01-20-announcing-new-migration-engine.md
Normal file
@@ -0,0 +1,235 @@
|
||||
---
|
||||
title: "Announcing v0.10: Ent gets a brand-new migration engine"
|
||||
author: Ariel Mashraki
|
||||
authorURL: https://github.com/a8m
|
||||
authorImageURL: https://avatars0.githubusercontent.com/u/7413593
|
||||
authorTwitter: arielmashraki
|
||||
---
|
||||
Dear community,
|
||||
|
||||
I'm very happy to announce the release of the next version of Ent: v0.10. It has been
|
||||
almost six months since v0.9.1, so naturally there's a ton of new stuff in this release.
|
||||
Still, I wanted to take the time to discuss one major improvement we have been working
|
||||
on for the past few months: a brand-new migration engine.
|
||||
|
||||
### Enter: [Atlas](https://github.com/ariga/atlas)
|
||||
|
||||
<img src="https://atlasgo.io/uploads/gopher.svg" width="200" />
|
||||
|
||||
Ent's current migration engine is great, and it does some pretty neat stuff which our
|
||||
community has been using in production for years now, but as time went on issues
|
||||
which we could not resolve with the existing architecture started piling up. In addition,
|
||||
we feel that existing database migration frameworks leave much to be desired. We have
|
||||
learned so much as an industry about safely managing changes to production systems in
|
||||
the past decade with principles such as Infrastructure-as-Code and declarative configuration
|
||||
management, that simply did not exist when most of these projects were conceived.
|
||||
|
||||
Seeing that these problems were fairly generic and relevant to application regardless of the framework
|
||||
or programming language it was written in, we saw the opportunity to fix them as common
|
||||
infrastructure that any project could use. For this reason, instead of just rewriting
|
||||
Ent's migration engine, we decided to extract the solution to a new open-source project,
|
||||
[Atlas](https://atlasgo.io) ([GitHub](https://ariga.io/atlas)).
|
||||
|
||||
Atlas is distributed as a CLI tool that uses a new [DDL](https://atlasgo.io/ddl/intro) based
|
||||
on HCL (similar to Terraform), but can also be used as a [Go package](https://pkg.go.dev/ariga.io/atlas).
|
||||
Just as Ent, Atlas is licensed under the [Apache License 2.0](https://github.com/ariga/atlas/blob/master/LICENSE).
|
||||
|
||||
Finally, after much work and testing, the Atlas integration for Ent is finally ready to use. This is
|
||||
great news to many of our users who opened issues (such as [#1652](https://github.com/ent/ent/issues/1652),
|
||||
[#1631](https://github.com/ent/ent/issues/1631), [#1625](https://github.com/ent/ent/issues/1625),
|
||||
[#1546](https://github.com/ent/ent/issues/1546) and [#1845](https://github.com/ent/ent/issues/1845))
|
||||
that could not be well addressed using the existing migration system, but are now resolved using the Atlas engine.
|
||||
|
||||
As with any substantial change, using Atlas as the migration engine for your project is currently opt-in.
|
||||
In the near future, we will switch to an opt-out mode, and finally deprecate the existing engine.
|
||||
Naturally, this transition will be made slowly, and we will progress as we get positive indications
|
||||
from the community.
|
||||
|
||||
### Getting started with Atlas migrations for Ent
|
||||
|
||||
First, upgrade to the latest version of Ent:
|
||||
|
||||
```shell
|
||||
go get entgo.io/ent@v0.10.0
|
||||
```
|
||||
|
||||
Next, in order to execute a migration with the Atlas engine, use the `WithAtlas(true)` option.
|
||||
|
||||
```go {17}
|
||||
package main
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"<project>/ent"
|
||||
"<project>/ent/migrate"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
)
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Run migration.
|
||||
err = client.Schema.Create(ctx, schema.WithAtlas(true))
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
And that's it!
|
||||
|
||||
One of the great improvements of the Atlas engine over the existing Ent code,
|
||||
is it's layered structure, that cleanly separates between ***inspection*** (understanding
|
||||
the current state of a database), ***diffing*** (calculating the difference between the
|
||||
current and desired state), ***planning*** (calculating a concrete plan for remediating
|
||||
the diff), and ***applying***. This diagram demonstrates the way Ent uses Atlas:
|
||||
|
||||

|
||||
|
||||
In addition to the standard options (e.g. `WithDropColumn`,
|
||||
`WithGlobalUniqueID`), the Atlas integration provides additional options for
|
||||
hooking into schema migration steps.
|
||||
|
||||
Here are two examples that show how to hook into the Atlas `Diff` and `Apply` steps.
|
||||
|
||||
```go
|
||||
package main
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"<project>/ent"
|
||||
"<project>/ent/migrate"
|
||||
"ariga.io/atlas/sql/migrate"
|
||||
atlas "ariga.io/atlas/sql/schema"
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
)
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/test")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Run migration.
|
||||
err := client.Schema.Create(
|
||||
ctx,
|
||||
// Hook into Atlas Diff process.
|
||||
schema.WithDiffHook(func(next schema.Differ) schema.Differ {
|
||||
return schema.DiffFunc(func(current, desired *atlas.Schema) ([]atlas.Change, error) {
|
||||
// Before calculating changes.
|
||||
changes, err := next.Diff(current, desired)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
// After diff, you can filter
|
||||
// changes or return new ones.
|
||||
return changes, nil
|
||||
})
|
||||
}),
|
||||
// Hook into Atlas Apply process.
|
||||
schema.WithApplyHook(func(next schema.Applier) schema.Applier {
|
||||
return schema.ApplyFunc(func(ctx context.Context, conn dialect.ExecQuerier, plan *migrate.Plan) error {
|
||||
// Example to hook into the apply process, or implement
|
||||
// a custom applier. For example, write to a file.
|
||||
//
|
||||
// for _, c := range plan.Changes {
|
||||
// fmt.Printf("%s: %s", c.Comment, c.Cmd)
|
||||
// if err := conn.Exec(ctx, c.Cmd, c.Args, nil); err != nil {
|
||||
// return err
|
||||
// }
|
||||
// }
|
||||
//
|
||||
return next.Apply(ctx, conn, plan)
|
||||
})
|
||||
}),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### What's next: v0.11
|
||||
|
||||
I know we took a while to get this release out the door, but the next one is right around
|
||||
the corner. Here's what's in store for v0.11:
|
||||
|
||||
* [Add support for edge/relation schemas](https://github.com/ent/ent/issues/1949) - supporting attaching metadata fields to relations.
|
||||
* Reimplementing the GraphQL integration to be fully compatible with the Relay spec.
|
||||
Supporting generating GraphQL assets (schemas or full servers) from Ent schemas.
|
||||
* Adding support for "Migration Authoring": the Atlas libraries have infrastructure for creating "versioned"
|
||||
migration directories, as is commonly used in many migration frameworks (such as Flyway, Liquibase, go-migrate, etc.).
|
||||
Many users have built solutions for integrating with these kinds of systems, and we plan to use Atlas to provide solid
|
||||
infrastructure for these flows.
|
||||
* Query hooks (interceptors) - currently hooks are only supported for [Mutations](https://entgo.io/docs/hooks/#hooks).
|
||||
Many users have requested adding support for read operations as well.
|
||||
* Polymorphic edges - The issue about adding support for polymorphism has been [open for over a year](https://github.com/ent/ent/issues/1048).
|
||||
With Go Generic Types support landing in 1.18, we want to re-open the discussion about a possible implementation using
|
||||
them.
|
||||
|
||||
### Wrapping up
|
||||
|
||||
Aside from the exciting announcement about the new migration engine, this release is huge
|
||||
in size and contents, featuring [199 commits from 42 unique contributors](https://github.com/ent/ent/releases/tag/v0.10.0). Ent is a community
|
||||
effort and keeps getting better every day thanks to all of you. So here's huge thanks and infinite
|
||||
kudos to everyone who took part in this release (alphabetically sorted):
|
||||
|
||||
[attackordie](https://github.com/attackordie),
|
||||
[bbkane](https://github.com/bbkane),
|
||||
[bodokaiser](https://github.com/bodokaiser),
|
||||
[cjraa](https://github.com/cjraa),
|
||||
[dakimura](https://github.com/dakimura),
|
||||
[dependabot](https://github.com/dependabot),
|
||||
[EndlessIdea](https://github.com/EndlessIdea),
|
||||
[ernado](https://github.com/ernado),
|
||||
[evanlurvey](https://github.com/evanlurvey),
|
||||
[freb](https://github.com/freb),
|
||||
[genevieve](https://github.com/genevieve),
|
||||
[giautm](https://github.com/giautm),
|
||||
[grevych](https://github.com/grevych),
|
||||
[hedwigz](https://github.com/hedwigz),
|
||||
[heliumbrain](https://github.com/heliumbrain),
|
||||
[hilakashai](https://github.com/hilakashai),
|
||||
[HurSungYun](https://github.com/HurSungYun),
|
||||
[idc77](https://github.com/idc77),
|
||||
[isoppp](https://github.com/isoppp),
|
||||
[JeremyV2014](https://github.com/JeremyV2014),
|
||||
[Laconty](https://github.com/Laconty),
|
||||
[lenuse](https://github.com/lenuse),
|
||||
[masseelch](https://github.com/masseelch),
|
||||
[mattn](https://github.com/mattn),
|
||||
[mookjp](https://github.com/mookjp),
|
||||
[msal4](https://github.com/msal4),
|
||||
[naormatania](https://github.com/naormatania),
|
||||
[odeke-em](https://github.com/odeke-em),
|
||||
[peanut-cc](https://github.com/peanut-cc),
|
||||
[posener](https://github.com/posener),
|
||||
[RiskyFeryansyahP](https://github.com/RiskyFeryansyahP),
|
||||
[rotemtam](https://github.com/rotemtam),
|
||||
[s-takehana](https://github.com/s-takehana),
|
||||
[sadmansakib](https://github.com/sadmansakib),
|
||||
[sashamelentyev](https://github.com/sashamelentyev),
|
||||
[seiichi1101](https://github.com/seiichi1101),
|
||||
[sivchari](https://github.com/sivchari),
|
||||
[storyicon](https://github.com/storyicon),
|
||||
[tarrencev](https://github.com/tarrencev),
|
||||
[ThinkontrolSY](https://github.com/ThinkontrolSY),
|
||||
[timoha](https://github.com/timoha),
|
||||
[vecpeng](https://github.com/vecpeng),
|
||||
[yonidavidson](https://github.com/yonidavidson), and
|
||||
[zeevmoney](https://github.com/zeevmoney).
|
||||
|
||||
Best,
|
||||
Ariel
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
@@ -0,0 +1,574 @@
|
||||
---
|
||||
title: Auto generate REST CRUD with Ent and ogen
|
||||
author: MasseElch
|
||||
authorURL: "https://github.com/masseelch"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/12862103?v=4"
|
||||
image: "https://entgo.io/images/assets/ogent/1.png"
|
||||
---
|
||||
|
||||
In the end of 2021 we announced that [Ent](https://entgo.io) got a new official extension to generate a fully
|
||||
compliant [OpenAPI Specification](https://swagger.io/resources/open-api/)
|
||||
document: [`entoas`](https://github.com/ent/contrib/tree/master/entoas).
|
||||
|
||||
Today, we are very happy to announce that there is a new extension built to work
|
||||
with `entoas`: [`ogent`](https://github.com/ariga/ogent). It utilizes the power
|
||||
of [`ogen`](https://github.com/ogen-go/ogen) ([website](https://ogen.dev/docs/intro/)) to provide a type-safe,
|
||||
reflection-free implementation of the OpenAPI Specification document generated by `entoas`.
|
||||
|
||||
`ogen` is an opinionated Go code generator for OpenAPI Specification v3 documents. `ogen` generates both server and
|
||||
client implementations for a given OpenAPI Specification document. The only thing left to do for the user is to
|
||||
implement an interface to access the data layer of any application. `ogen` has many cool features, one of which is
|
||||
integration with [OpenTelemetry](https://opentelemetry.io/). Make sure to check it out and leave some love.
|
||||
|
||||
The extension presented in this post serves as a bridge between Ent and the code generated
|
||||
by [`ogen`](https://github.com/ogen-go/ogen). It uses the configuration of `entoas` to generate the missing parts of
|
||||
the `ogen` code.
|
||||
|
||||
The following diagram shows how Ent interacts with both the extensions `entoas` and `ogent` and how `ogen` is involved.
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Diagram" src="https://entgo.io/images/assets/ogent/1.png" />
|
||||
<p style={{fontSize: 12}}>Diagram</p>
|
||||
</div>
|
||||
|
||||
If you are new to Ent and want to learn more about it, how to connect to different types of databases, run migrations or
|
||||
work with entities, then head over to the [Setup Tutorial](https://entgo.io/docs/tutorial-setup/)
|
||||
|
||||
The code in this post is available in the modules [examples](https://github.com/ariga/ogent/tree/main/example/todo).
|
||||
|
||||
### Getting Started
|
||||
|
||||
:::note
|
||||
While Ent does support Go versions 1.16+ `ogen` requires you to have at least version 1.17.
|
||||
:::
|
||||
|
||||
To use the `ogent` extension use the `entc` (ent codegen) package as
|
||||
described [here](https://entgo.io/docs/code-gen#use-entc-as-a-package). First install both `entoas` and `ogent`
|
||||
extensions to your Go module:
|
||||
|
||||
```shell
|
||||
go get ariga.io/ogent@main
|
||||
```
|
||||
|
||||
Now follow the next two steps to enable them and to configure Ent to work with the extensions:
|
||||
|
||||
1\. Create a new Go file named `ent/entc.go` and paste the following content:
|
||||
|
||||
```go title="ent/entc.go"
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"ariga.io/ogent"
|
||||
"entgo.io/contrib/entoas"
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
"github.com/ogen-go/ogen"
|
||||
)
|
||||
|
||||
func main() {
|
||||
spec := new(ogen.Spec)
|
||||
oas, err := entoas.NewExtension(entoas.Spec(spec))
|
||||
if err != nil {
|
||||
log.Fatalf("creating entoas extension: %v", err)
|
||||
}
|
||||
ogent, err := ogent.NewExtension(spec)
|
||||
if err != nil {
|
||||
log.Fatalf("creating ogent extension: %v", err)
|
||||
}
|
||||
err = entc.Generate("./schema", &gen.Config{}, entc.Extensions(ogent, oas))
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
2\. Edit the `ent/generate.go` file to execute the `ent/entc.go` file:
|
||||
|
||||
```go title="ent/generate.go"
|
||||
package ent
|
||||
|
||||
//go:generate go run -mod=mod entc.go
|
||||
```
|
||||
|
||||
With these steps complete, all is set up for generating an OAS document and implementing server code from your schema!
|
||||
|
||||
### Generate a CRUD HTTP API Server
|
||||
|
||||
The first step on our way to the HTTP API server is to create an Ent schema graph. For the sake of brevity, here is an
|
||||
example schema to use:
|
||||
|
||||
```go title="ent/schema/todo.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// Todo holds the schema definition for the Todo entity.
|
||||
type Todo struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Todo.
|
||||
func (Todo) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("title"),
|
||||
field.Bool("done"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The code above is the "Ent way" to describe a schema-graph. In this particular case we created a todo entity.
|
||||
|
||||
Now run the code generator:
|
||||
|
||||
```shell
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
You should see a bunch of files generated by the Ent code generator. The file named `ent/openapi.json` has been
|
||||
generated by the `entoas` extension. Here is a sneak peek into it:
|
||||
|
||||
```json title="ent/openapi.json"
|
||||
{
|
||||
"info": {
|
||||
"title": "Ent Schema API",
|
||||
"description": "This is an auto generated API description made out of an Ent schema definition",
|
||||
"termsOfService": "",
|
||||
"contact": {},
|
||||
"license": {
|
||||
"name": ""
|
||||
},
|
||||
"version": "0.0.0"
|
||||
},
|
||||
"paths": {
|
||||
"/todos": {
|
||||
"get": {
|
||||
[...]
|
||||
```
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Swagger Editor Example" src="https://entgo.io/images/assets/ogent/2.png" />
|
||||
<p style={{fontSize: 12}}>Swagger Editor Example</p>
|
||||
</div>
|
||||
|
||||
However, this post focuses on the server implementation part therefore we are interested in the directory
|
||||
named `ent/ogent`. All the files ending in `_gen.go` are generated by `ogen`. The file named `oas_server_gen.go`
|
||||
contains the interface `ogen`-users need to implement in order to run the server.
|
||||
|
||||
```go title="ent/ogent/oas_server_gen.go"
|
||||
// Handler handles operations described by OpenAPI v3 specification.
|
||||
type Handler interface {
|
||||
// CreateTodo implements createTodo operation.
|
||||
//
|
||||
// Creates a new Todo and persists it to storage.
|
||||
//
|
||||
// POST /todos
|
||||
CreateTodo(ctx context.Context, req CreateTodoReq) (CreateTodoRes, error)
|
||||
// DeleteTodo implements deleteTodo operation.
|
||||
//
|
||||
// Deletes the Todo with the requested ID.
|
||||
//
|
||||
// DELETE /todos/{id}
|
||||
DeleteTodo(ctx context.Context, params DeleteTodoParams) (DeleteTodoRes, error)
|
||||
// ListTodo implements listTodo operation.
|
||||
//
|
||||
// List Todos.
|
||||
//
|
||||
// GET /todos
|
||||
ListTodo(ctx context.Context, params ListTodoParams) (ListTodoRes, error)
|
||||
// ReadTodo implements readTodo operation.
|
||||
//
|
||||
// Finds the Todo with the requested ID and returns it.
|
||||
//
|
||||
// GET /todos/{id}
|
||||
ReadTodo(ctx context.Context, params ReadTodoParams) (ReadTodoRes, error)
|
||||
// UpdateTodo implements updateTodo operation.
|
||||
//
|
||||
// Updates a Todo and persists changes to storage.
|
||||
//
|
||||
// PATCH /todos/{id}
|
||||
UpdateTodo(ctx context.Context, req UpdateTodoReq, params UpdateTodoParams) (UpdateTodoRes, error)
|
||||
}
|
||||
```
|
||||
|
||||
`ogent` adds an implementation for
|
||||
that handler in the file `ogent.go`. To see how you can define what routes to generate and what edges to eager load
|
||||
please head over to the `entoas` [documentation](https://github.com/ent/contrib/entoas).
|
||||
|
||||
The following shows an example for a generated READ route:
|
||||
|
||||
```go
|
||||
// ReadTodo handles GET /todos/{id} requests.
|
||||
func (h *OgentHandler) ReadTodo(ctx context.Context, params ReadTodoParams) (ReadTodoRes, error) {
|
||||
q := h.client.Todo.Query().Where(todo.IDEQ(params.ID))
|
||||
e, err := q.Only(ctx)
|
||||
if err != nil {
|
||||
switch {
|
||||
case ent.IsNotFound(err):
|
||||
return &R404{
|
||||
Code: http.StatusNotFound,
|
||||
Status: http.StatusText(http.StatusNotFound),
|
||||
Errors: rawError(err),
|
||||
}, nil
|
||||
case ent.IsNotSingular(err):
|
||||
return &R409{
|
||||
Code: http.StatusConflict,
|
||||
Status: http.StatusText(http.StatusConflict),
|
||||
Errors: rawError(err),
|
||||
}, nil
|
||||
default:
|
||||
// Let the server handle the error.
|
||||
return nil, err
|
||||
}
|
||||
}
|
||||
return NewTodoRead(e), nil
|
||||
}
|
||||
```
|
||||
|
||||
### Run the server
|
||||
|
||||
The next step is to create a `main.go` file and wire up all the ends to create an application-server to serve the
|
||||
Todo-API. The following main function initializes a SQLite in-memory database, runs the migrations to create all the
|
||||
tables needed and serves the API as described in the `ent/openapi.json` file on `localhost:8080`:
|
||||
|
||||
```go title="main.go"
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"net/http"
|
||||
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
"<your-project>/ent"
|
||||
"<your-project>/ent/ogent"
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
)
|
||||
|
||||
func main() {
|
||||
// Create ent client.
|
||||
client, err := ent.Open(dialect.SQLite, "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
// Run the migrations.
|
||||
if err := client.Schema.Create(context.Background(), schema.WithAtlas(true)); err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
// Start listening.
|
||||
srv, err := ogent.NewServer(ogent.NewOgentHandler(client))
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
if err := http.ListenAndServe(":8080", srv); err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
After you run the server with `go run -mod=mod main.go` you can work with the API.
|
||||
|
||||
First, let's create a new Todo. For
|
||||
demonstration purpose we do not send a request body:
|
||||
|
||||
```shell
|
||||
↪ curl -X POST -H "Content-Type: application/json" localhost:8080/todos
|
||||
{
|
||||
"error_message": "body required"
|
||||
}
|
||||
```
|
||||
|
||||
As you can see `ogen` handles that case for you since `entoas` marked the body as required when attempting to create a
|
||||
new resource. Let's try again, but this time provide a request body:
|
||||
|
||||
```shell
|
||||
↪ curl -X POST -H "Content-Type: application/json" -d '{"title":"Give ogen and ogent a Star on GitHub"}' localhost:8080/todos
|
||||
{
|
||||
"error_message": "decode CreateTodo:application/json request: invalid: done (field required)"
|
||||
}
|
||||
```
|
||||
|
||||
Ooops! What went wrong? `ogen` has your back: the field `done` is required. To fix this head over to your schema
|
||||
definition and mark the done field as optional:
|
||||
|
||||
```go {18} title="ent/schema/todo.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// Todo holds the schema definition for the Todo entity.
|
||||
type Todo struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Todo.
|
||||
func (Todo) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("title"),
|
||||
field.Bool("done").
|
||||
Optional(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Since we made a change to our configuration, we have to re-run code generation and restart the server:
|
||||
|
||||
```shell
|
||||
go generate ./...
|
||||
go run -mod=mod main.go
|
||||
```
|
||||
|
||||
Now, if we attempt to create the Todo again, see what happens:
|
||||
|
||||
```shell
|
||||
↪ curl -X POST -H "Content-Type: application/json" -d '{"title":"Give ogen and ogent a Star on GitHub"}' localhost:8080/todos
|
||||
{
|
||||
"id": 1,
|
||||
"title": "Give ogen and ogent a Star on GitHub",
|
||||
"done": false
|
||||
}
|
||||
```
|
||||
|
||||
Voila, there is a new Todo item in the database!
|
||||
|
||||
Assume you have completed your Todo and starred both [`ogen`](https://github.com/ogen-go/ogen)
|
||||
and [`ogent`](https://github.com/ariga/ogent) (**you really should!**), mark the todo as done by raising a PATCH
|
||||
request:
|
||||
|
||||
```shell
|
||||
↪ curl -X PATCH -H "Content-Type: application/json" -d '{"done":true}' localhost:8080/todos/1
|
||||
{
|
||||
"id": 1,
|
||||
"title": "Give ogen and ogent a Star on GitHub",
|
||||
"done": true
|
||||
}
|
||||
```
|
||||
|
||||
### Add custom endpoints
|
||||
|
||||
As you can see the Todo is now marked as done. Though it would be cooler to have an extra route for marking a Todo as
|
||||
done: `PATCH todos/:id/done`. To make this happen we have to do two things: document the new route in our OAS document
|
||||
and implement the route. We can tackle the first by using the `entoas` mutation builder. Edit your `ent/entc.go` file
|
||||
and add the route description:
|
||||
|
||||
```go {17-37} title="ent/entc.go"
|
||||
//go:build ignore
|
||||
|
||||
package main
|
||||
|
||||
import (
|
||||
"log"
|
||||
|
||||
"entgo.io/contrib/entoas"
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
"github.com/ariga/ogent"
|
||||
"github.com/ogen-go/ogen"
|
||||
)
|
||||
|
||||
func main() {
|
||||
spec := new(ogen.Spec)
|
||||
oas, err := entoas.NewExtension(
|
||||
entoas.Spec(spec),
|
||||
entoas.Mutations(func(_ *gen.Graph, spec *ogen.Spec) error {
|
||||
spec.AddPathItem("/todos/{id}/done", ogen.NewPathItem().
|
||||
SetDescription("Mark an item as done").
|
||||
SetPatch(ogen.NewOperation().
|
||||
SetOperationID("markDone").
|
||||
SetSummary("Marks a todo item as done.").
|
||||
AddTags("Todo").
|
||||
AddResponse("204", ogen.NewResponse().SetDescription("Item marked as done")),
|
||||
).
|
||||
AddParameters(ogen.NewParameter().
|
||||
InPath().
|
||||
SetName("id").
|
||||
SetRequired(true).
|
||||
SetSchema(ogen.Int()),
|
||||
),
|
||||
)
|
||||
return nil
|
||||
}),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatalf("creating entoas extension: %v", err)
|
||||
}
|
||||
ogent, err := ogent.NewExtension(spec)
|
||||
if err != nil {
|
||||
log.Fatalf("creating ogent extension: %v", err)
|
||||
}
|
||||
err = entc.Generate("./schema", &gen.Config{}, entc.Extensions(ogent, oas))
|
||||
if err != nil {
|
||||
log.Fatalf("running ent codegen: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
After running the code generator (`go generate ./...`) there should be a new entry in the `ent/openapi.json` file:
|
||||
|
||||
```json
|
||||
"/todos/{id}/done": {
|
||||
"description": "Mark an item as done",
|
||||
"patch": {
|
||||
"tags": [
|
||||
"Todo"
|
||||
],
|
||||
"summary": "Marks a todo item as done.",
|
||||
"operationId": "markDone",
|
||||
"responses": {
|
||||
"204": {
|
||||
"description": "Item marked as done"
|
||||
}
|
||||
}
|
||||
},
|
||||
"parameters": [
|
||||
{
|
||||
"name": "id",
|
||||
"in": "path",
|
||||
"schema": {
|
||||
"type": "integer"
|
||||
},
|
||||
"required": true
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<img alt="Custom Endpoint" src="https://entgo.io/images/assets/ogent/3.png" />
|
||||
<p style={{fontSize: 12}}>Custom Endpoint</p>
|
||||
</div>
|
||||
|
||||
The above mentioned `ent/ogent/oas_server_gen.go` file generated by `ogen` will reflect the changes as well:
|
||||
|
||||
```go {21-24} title="ent/ogent/oas_server_gen.go"
|
||||
// Handler handles operations described by OpenAPI v3 specification.
|
||||
type Handler interface {
|
||||
// CreateTodo implements createTodo operation.
|
||||
//
|
||||
// Creates a new Todo and persists it to storage.
|
||||
//
|
||||
// POST /todos
|
||||
CreateTodo(ctx context.Context, req CreateTodoReq) (CreateTodoRes, error)
|
||||
// DeleteTodo implements deleteTodo operation.
|
||||
//
|
||||
// Deletes the Todo with the requested ID.
|
||||
//
|
||||
// DELETE /todos/{id}
|
||||
DeleteTodo(ctx context.Context, params DeleteTodoParams) (DeleteTodoRes, error)
|
||||
// ListTodo implements listTodo operation.
|
||||
//
|
||||
// List Todos.
|
||||
//
|
||||
// GET /todos
|
||||
ListTodo(ctx context.Context, params ListTodoParams) (ListTodoRes, error)
|
||||
// MarkDone implements markDone operation.
|
||||
//
|
||||
// PATCH /todos/{id}/done
|
||||
MarkDone(ctx context.Context, params MarkDoneParams) (MarkDoneNoContent, error)
|
||||
// ReadTodo implements readTodo operation.
|
||||
//
|
||||
// Finds the Todo with the requested ID and returns it.
|
||||
//
|
||||
// GET /todos/{id}
|
||||
ReadTodo(ctx context.Context, params ReadTodoParams) (ReadTodoRes, error)
|
||||
// UpdateTodo implements updateTodo operation.
|
||||
//
|
||||
// Updates a Todo and persists changes to storage.
|
||||
//
|
||||
// PATCH /todos/{id}
|
||||
UpdateTodo(ctx context.Context, req UpdateTodoReq, params UpdateTodoParams) (UpdateTodoRes, error)
|
||||
}
|
||||
```
|
||||
|
||||
If you'd try to run the server now, the Go compiler will complain about it, because the `ogent` code generator does not
|
||||
know how to implement the new route. You have to do this by hand. Replace the current `main.go` with the following file
|
||||
to implement the new method.
|
||||
|
||||
```go {15-22,34-38,40} title="main.go"
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"net/http"
|
||||
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
"github.com/ariga/ogent/example/todo/ent"
|
||||
"github.com/ariga/ogent/example/todo/ent/ogent"
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
)
|
||||
|
||||
type handler struct {
|
||||
*ogent.OgentHandler
|
||||
client *ent.Client
|
||||
}
|
||||
|
||||
func (h handler) MarkDone(ctx context.Context, params ogent.MarkDoneParams) (ogent.MarkDoneNoContent, error) {
|
||||
return ogent.MarkDoneNoContent{}, h.client.Todo.UpdateOneID(params.ID).SetDone(true).Exec(ctx)
|
||||
}
|
||||
|
||||
func main() {
|
||||
// Create ent client.
|
||||
client, err := ent.Open(dialect.SQLite, "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
// Run the migrations.
|
||||
if err := client.Schema.Create(context.Background(), schema.WithAtlas(true)); err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
// Create the handler.
|
||||
h := handler{
|
||||
OgentHandler: ogent.NewOgentHandler(client),
|
||||
client: client,
|
||||
}
|
||||
// Start listening.
|
||||
srv := ogent.NewServer(h)
|
||||
if err := http.ListenAndServe(":8180", srv); err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
If you restart your server you can then raise the following request to mark a todo item as done:
|
||||
|
||||
```shell
|
||||
↪ curl -X PATCH localhost:8180/todos/1/done
|
||||
```
|
||||
|
||||
### Yet to come
|
||||
|
||||
There are some improvements planned for `ogent`, most notably a code generated, type-safe way to add filtering
|
||||
capabilities to the LIST routes. We want to hear your feedback first.
|
||||
|
||||
### Wrapping Up
|
||||
|
||||
In this post we announced `ogent`, the official implementation generator for `entoas` generated OpenAPI Specification
|
||||
documents. This extension uses the power of [`ogen`](https://github.com/ogen-go/ogen), a very powerful and feature-rich
|
||||
Go code generator for OpenAPI v3 documents, to provide a ready-to-use, extensible server RESTful HTTP API servers.
|
||||
|
||||
Please note, that both `ogen` and `entoas`/`ogent` have not reached their first major release yet, and it is work in
|
||||
progress. Nevertheless, the API can be considered stable.
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack/).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
364
doc/website/blog/2022-03-14-announcing-versioned-migrations.md
Normal file
364
doc/website/blog/2022-03-14-announcing-versioned-migrations.md
Normal file
@@ -0,0 +1,364 @@
|
||||
---
|
||||
title: Announcing Versioned Migrations Authoring
|
||||
author: MasseElch
|
||||
authorURL: "https://github.com/masseelch"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/12862103?v=4"
|
||||
image: "https://entgo.io/images/assets/migrate/versioned-share.png"
|
||||
---
|
||||
|
||||
When [Ariel](https://github.com/a8m) released Ent v0.10.0 at the end of January,
|
||||
he [introduced](2022-01-20-announcing-new-migration-engine.md) a new migration engine for Ent based on another
|
||||
open-source project called [Atlas](https://github.com/ariga/atlas).
|
||||
|
||||
Initially, Atlas supported a style of managing database schemas that we call "declarative migrations". With declarative
|
||||
migrations, the desired state of the database schema is given as input to the migration engine, which plans and executes
|
||||
a set of actions to change the database to its desired state. This approach has been popularized in the field of
|
||||
cloud native infrastructure by projects such as Kubernetes and Terraform. It works great in many cases, in
|
||||
fact it has served the Ent framework very well in the past few years. However, database migrations are a very sensitive
|
||||
topic, and many projects require a more controlled approach.
|
||||
|
||||
For this reason, most industry standard solutions, like [Flyway](https://flywaydb.org/)
|
||||
, [Liquibase](https://liquibase.org/), or [golang-migrate/migrate](https://github.com/golang-migrate/migrate) (which is
|
||||
common in the Go ecosystem), support a workflow that they call "versioned migrations".
|
||||
|
||||
With versioned migrations (sometimes called "change base migrations") instead of describing the desired state ("what the
|
||||
database should look like"), you describe the changes itself ("how to reach the state"). Most of the time this is done
|
||||
by creating a set of SQL files containing the statements needed. Each of the files is assigned a unique version and a
|
||||
description of the changes. Tools like the ones mentioned earlier are then able to interpret the migration files and to
|
||||
apply (some of) them in the correct order to transition to the desired database structure.
|
||||
|
||||
In this post, I want to showcase a new kind of migration workflow that has recently been added to Atlas and Ent. We call
|
||||
it "versioned migration authoring" and it's an attempt to combine the simplicity and expressiveness of the declarative
|
||||
approach with the safety and explicitness of versioned migrations. With versioned migration authoring, users still
|
||||
declare their desired state and use the Atlas engine to plan a safe migration from the existing to the new state.
|
||||
However, instead of coupling the planning and execution, it is instead written into a file which can be checked into
|
||||
source control, fine-tuned manually and reviewed in normal code review processes.
|
||||
|
||||
As an example, I will demonstrate the workflow with `golang-migrate/migrate`.
|
||||
|
||||
### Getting Started
|
||||
|
||||
The very first thing to do, is to make sure you have an up-to-date Ent version:
|
||||
|
||||
```shell
|
||||
go get -u entgo.io/ent@master
|
||||
```
|
||||
|
||||
There are two ways to have Ent generate migration files for schema changes. The first one is to use an instantiated Ent
|
||||
client and the second one to generate the changes from a parsed schema graph. This post will take the second approach,
|
||||
if you want to learn how to use the first one you can have a look at
|
||||
the [documentation](./docs/versioned-migrations#from-client).
|
||||
|
||||
### Generating Versioned Migration Files
|
||||
|
||||
Since we have enabled the versioned migrations feature now, let's create a small schema and generate the initial set of
|
||||
migration files. Consider the following schema for a fresh Ent project:
|
||||
|
||||
```go title="ent/schema/user.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/field"
|
||||
"entgo.io/ent/schema/index"
|
||||
)
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("username"),
|
||||
}
|
||||
}
|
||||
|
||||
// Indexes of the User.
|
||||
func (User) Indexes() []ent.Index {
|
||||
return []ent.Index{
|
||||
index.Fields("username").Unique(),
|
||||
}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
As I stated before, we want to use the parsed schema graph to compute the difference between our schema and the
|
||||
connected database. Here is an example of a (semi-)persistent MySQL docker container to use if you want to follow along:
|
||||
|
||||
```shell
|
||||
docker run --rm --name ent-versioned-migrations --detach --env MYSQL_ROOT_PASSWORD=pass --env MYSQL_DATABASE=ent -p 3306:3306 mysql
|
||||
```
|
||||
|
||||
Once you are done, you can shut down the container and remove all resources with `docker stop ent-versioned-migrations`.
|
||||
|
||||
Now, let's create a small function that loads the schema graph and generates the migration files. Create a new Go file
|
||||
named `main.go` and copy the following contents:
|
||||
|
||||
```go title="main.go"
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"os"
|
||||
|
||||
"ariga.io/atlas/sql/migrate"
|
||||
"entgo.io/ent/dialect/sql"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
"entgo.io/ent/entc"
|
||||
"entgo.io/ent/entc/gen"
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
// We need a name for the new migration file.
|
||||
if len(os.Args) < 2 {
|
||||
log.Fatalln("no name given")
|
||||
}
|
||||
// Create a local migration directory.
|
||||
dir, err := migrate.NewLocalDir("migrations")
|
||||
if err != nil {
|
||||
log.Fatalln(err)
|
||||
}
|
||||
// Load the graph.
|
||||
graph, err := entc.LoadGraph("./ent/schema", &gen.Config{})
|
||||
if err != nil {
|
||||
log.Fatalln(err)
|
||||
}
|
||||
tbls, err := graph.Tables()
|
||||
if err != nil {
|
||||
log.Fatalln(err)
|
||||
}
|
||||
// Open connection to the database.
|
||||
drv, err := sql.Open("mysql", "root:pass@tcp(localhost:3306)/ent")
|
||||
if err != nil {
|
||||
log.Fatalln(err)
|
||||
}
|
||||
// Inspect the current database state and compare it with the graph.
|
||||
m, err := schema.NewMigrate(drv, schema.WithDir(dir))
|
||||
if err != nil {
|
||||
log.Fatalln(err)
|
||||
}
|
||||
if err := m.NamedDiff(context.Background(), os.Args[1], tbls...); err != nil {
|
||||
log.Fatalln(err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
All we have to do now is create the migration directory and execute the above Go file:
|
||||
|
||||
```shell
|
||||
mkdir migrations
|
||||
go run -mod=mod main.go initial
|
||||
```
|
||||
|
||||
You will now see two new files in the `migrations` directory: `<timestamp>_initial.down.sql`
|
||||
and `<timestamp>_initial.up.sql`. The `x.up.sql` files are used to create the database version `x` and `x.down.sql` to
|
||||
roll back to the previous version.
|
||||
|
||||
```sql title="<timestamp>_initial.up.sql"
|
||||
CREATE TABLE `users` (`id` bigint NOT NULL AUTO_INCREMENT, `username` varchar(191) NOT NULL, PRIMARY KEY (`id`), UNIQUE INDEX `user_username` (`username`)) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
```
|
||||
|
||||
```sql title="<timestamp>_initial.down.sql"
|
||||
DROP TABLE `users`;
|
||||
```
|
||||
|
||||
### Applying Migrations
|
||||
|
||||
To apply these migrations on your database, install the `golang-migrate/migrate` tool as described in
|
||||
their [README](https://github.com/golang-migrate/migrate/blob/master/cmd/migrate/README.md). Then run the following
|
||||
command to check if everything went as it should.
|
||||
|
||||
```shell
|
||||
migrate -help
|
||||
```
|
||||
```text
|
||||
Usage: migrate OPTIONS COMMAND [arg...]
|
||||
migrate [ -version | -help ]
|
||||
|
||||
Options:
|
||||
-source Location of the migrations (driver://url)
|
||||
-path Shorthand for -source=file://path
|
||||
-database Run migrations against this database (driver://url)
|
||||
-prefetch N Number of migrations to load in advance before executing (default 10)
|
||||
-lock-timeout N Allow N seconds to acquire database lock (default 15)
|
||||
-verbose Print verbose logging
|
||||
-version Print version
|
||||
-help Print usage
|
||||
|
||||
Commands:
|
||||
create [-ext E] [-dir D] [-seq] [-digits N] [-format] NAME
|
||||
Create a set of timestamped up/down migrations titled NAME, in directory D with extension E.
|
||||
Use -seq option to generate sequential up/down migrations with N digits.
|
||||
Use -format option to specify a Go time format string.
|
||||
goto V Migrate to version V
|
||||
up [N] Apply all or N up migrations
|
||||
down [N] Apply all or N down migrations
|
||||
drop Drop everything inside database
|
||||
force V Set version V but don't run migration (ignores dirty state)
|
||||
version Print current migration version
|
||||
```
|
||||
|
||||
Now we can execute our initial migration and sync the database with our schema:
|
||||
|
||||
```shell
|
||||
migrate -source 'file://migrations' -database 'mysql://root:pass@tcp(localhost:3306)/ent' up
|
||||
```
|
||||
```text
|
||||
<timestamp>/u initial (349.256951ms)
|
||||
```
|
||||
|
||||
### Workflow
|
||||
|
||||
To demonstrate the usual workflow when using versioned migrations we will both edit our schema graph and generate the
|
||||
migration changes for it, and manually create a set of migration files to seed the database with some data. First, we
|
||||
will add a Group schema and a many-to-many relation to the existing User schema, next create an admin Group with an
|
||||
admin User in it. Go ahead and make the following changes:
|
||||
|
||||
```go title="ent/schema/user.go" {22-28}
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/edge"
|
||||
"entgo.io/ent/schema/field"
|
||||
"entgo.io/ent/schema/index"
|
||||
)
|
||||
|
||||
// User holds the schema definition for the User entity.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("username"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the User.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("groups", Group.Type).
|
||||
Ref("users"),
|
||||
}
|
||||
}
|
||||
|
||||
// Indexes of the User.
|
||||
func (User) Indexes() []ent.Index {
|
||||
return []ent.Index{
|
||||
index.Fields("username").Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```go title="ent/schema/group.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/edge"
|
||||
"entgo.io/ent/schema/field"
|
||||
"entgo.io/ent/schema/index"
|
||||
)
|
||||
|
||||
// Group holds the schema definition for the Group entity.
|
||||
type Group struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Group.
|
||||
func (Group) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Group.
|
||||
func (Group) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("users", User.Type),
|
||||
}
|
||||
}
|
||||
|
||||
// Indexes of the Group.
|
||||
func (Group) Indexes() []ent.Index {
|
||||
return []ent.Index{
|
||||
index.Fields("name").Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
Once the schema is updated, create a new set of migration files.
|
||||
|
||||
```shell
|
||||
go run -mod=mod main.go add_group_schema
|
||||
```
|
||||
|
||||
Once again there will be two new files in the `migrations` directory: `<timestamp>_add_group_schema.down.sql`
|
||||
and `<timestamp>_add_group_schema.up.sql`.
|
||||
|
||||
```sql title="<timestamp>_add_group_schema.up.sql"
|
||||
CREATE TABLE `groups` (`id` bigint NOT NULL AUTO_INCREMENT, `name` varchar(191) NOT NULL, PRIMARY KEY (`id`), UNIQUE INDEX `group_name` (`name`)) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
CREATE TABLE `group_users` (`group_id` bigint NOT NULL, `user_id` bigint NOT NULL, PRIMARY KEY (`group_id`, `user_id`), CONSTRAINT `group_users_group_id` FOREIGN KEY (`group_id`) REFERENCES `groups` (`id`) ON DELETE CASCADE, CONSTRAINT `group_users_user_id` FOREIGN KEY (`user_id`) REFERENCES `users` (`id`) ON DELETE CASCADE) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
```
|
||||
|
||||
```sql title="<timestamp>_add_group_schema.down.sql"
|
||||
DROP TABLE `group_users`;
|
||||
DROP TABLE `groups`;
|
||||
```
|
||||
|
||||
Now you can either edit the generated files to add the seed data or create new files for it. I chose the latter:
|
||||
|
||||
```shell
|
||||
migrate create -format unix -ext sql -dir migrations seed_admin
|
||||
```
|
||||
```text
|
||||
[...]/ent-versioned-migrations/migrations/<timestamp>_seed_admin.up.sql
|
||||
[...]/ent-versioned-migrations/migrations/<timestamp>_seed_admin.down.sql
|
||||
```
|
||||
|
||||
You can now edit those files and add statements to create an admin Group and User.
|
||||
|
||||
```sql title="migrations/<timestamp>_seed_admin.up.sql"
|
||||
INSERT INTO `groups` (`id`, `name`) VALUES (1, 'Admins');
|
||||
INSERT INTO `users` (`id`, `username`) VALUES (1, 'admin');
|
||||
INSERT INTO `group_users` (`group_id`, `user_id`) VALUES (1, 1);
|
||||
```
|
||||
|
||||
```sql title="migrations/<timestamp>_seed_admin.down.sql"
|
||||
DELETE FROM `group_users` where `group_id` = 1 and `user_id` = 1;
|
||||
DELETE FROM `groups` where id = 1;
|
||||
DELETE FROM `users` where id = 1;
|
||||
```
|
||||
|
||||
Apply the migrations once more, and you are done:
|
||||
|
||||
```shell
|
||||
migrate -source file://migrations -database 'mysql://root:pass@tcp(localhost:3306)/ent' up
|
||||
```
|
||||
|
||||
```text
|
||||
<timestamp>/u add_group_schema (417.434415ms)
|
||||
<timestamp>/u seed_admin (674.189872ms)
|
||||
```
|
||||
|
||||
### Wrapping Up
|
||||
|
||||
In this post, we demonstrated the general workflow when using Ent Versioned Migrations with `golang-migate/migrate`. We
|
||||
created a small example schema, generated the migration files for it and learned how to apply them. We now know the
|
||||
workflow and how to add custom migration files.
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join our [Discord server](https://discord.gg/qZmPgTE6RX) or [Slack channel](https://entgo.io/docs/slack/).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
@@ -0,0 +1,96 @@
|
||||
---
|
||||
title: Announcing preview support for TiDB
|
||||
author: Amit Shani
|
||||
authorURL: "https://github.com/hedwigz"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/8277210?v=4"
|
||||
authorTwitter: itsamitush
|
||||
---
|
||||
|
||||
We [previously announced](2022-01-20-announcing-new-migration-engine.md) Ent's new migration engine - Atlas.
|
||||
Using Atlas, it has become easier than ever to add support for new databases to Ent.
|
||||
Today, I am happy to announce that preview support for [TiDB](https://en.pingcap.com/tidb/) is now available, using the latest version of Ent with Atlas enabled.
|
||||
|
||||
Ent can be used to access data in many types of databases, both graph-oriented and relational. Most commonly, users have been using standard open-source relational databases such as MySQL, MariaDB, and PostgreSQL. As teams building Ent-based applications become more successful and need to deal with traffic on larger scales, these single-node databases often become the bottleneck for scaling out. For this reason, many members of the Ent community have requested support for [NewSQL](https://en.wikipedia.org/wiki/NewSQL) databases such as TiDB.
|
||||
|
||||
### TiDB
|
||||
[TiDB](https://en.pingcap.com/tidb/) is an [open-source](https://github.com/pingcap/tidb) NewSQL database. It provides many features that traditional databases don't, such as:
|
||||
1. **Horizontal scaling** - for many years software architects needed to choose between the familiarity and guarantees that relational databases provide and the scaling-out capability of _NoSQL_ databases (such as MongoDB or Cassandra). TiDB supports horizontal scaling while maintaining good compatibility with MySQL features.
|
||||
2. **HTAP (Hybrid transactional/analytical processing)** - In addition, databases are traditionally divided into analytical (OLAP) and transactional (OLTP) databases. TiDB breaks this dichotomy by enabling both analytics and transactional workloads on the same database.
|
||||
3. **Pre-packed monitoring** w/ Prometheus+Grafana - TiDB is built on Cloud-native paradigms from the ground up, and natively supports the standard CNCF observability stack.
|
||||
|
||||
To read more about it, check out the official [TiDB Introduction](https://docs.pingcap.com/tidb/stable).
|
||||
|
||||
### Hello World with TiDB
|
||||
|
||||
For a quick "Hello World" application with Ent+TiDB, follow these steps:
|
||||
1. Spin up a local TiDB server by using Docker:
|
||||
```shell
|
||||
docker run -p 4000:4000 pingcap/tidb
|
||||
```
|
||||
Now you should have a running instance of TiDB listening on port 4000.
|
||||
|
||||
2. Clone the example [`hello world` repository](https://github.com/hedwigz/tidb-hello-world):
|
||||
```shell
|
||||
git clone https://github.com/hedwigz/tidb-hello-world.git
|
||||
```
|
||||
In this example repository we defined a simple schema `User`:
|
||||
```go title="ent/schema/user.go"
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Time("created_at").
|
||||
Default(time.Now),
|
||||
field.String("name"),
|
||||
field.Int("age"),
|
||||
}
|
||||
}
|
||||
```
|
||||
Then, we connected Ent with TiDB:
|
||||
```go title="main.go"
|
||||
client, err := ent.Open("mysql", "root@tcp(localhost:4000)/test?parseTime=true")
|
||||
if err != nil {
|
||||
log.Fatalf("failed opening connection to tidb: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
// Run the auto migration tool, with Atlas.
|
||||
if err := client.Schema.Create(context.Background(), schema.WithAtlas(true)); err != nil {
|
||||
log.Fatalf("failed printing schema changes: %v", err)
|
||||
}
|
||||
```
|
||||
Note that in line `1` we connect to the TiDB server using a `mysql` dialect. This is possible due to the fact that TiDB is [MySQL compatible](https://docs.pingcap.com/tidb/stable/mysql-compatibility), and it does not require any special driver.
|
||||
Having said that, there are some differences between TiDB and MySQL, especially when pertaining to schema migrations, such as information schema inspection and migration planning. For this reason, `Atlas` automatically detects if it is connected to `TiDB` and handles the migration accordingly.
|
||||
In addition, note that in line `7` we used `schema.WithAtlas(true)`, which flags Ent to use `Atlas` as its
|
||||
migration engine.
|
||||
|
||||
Finally, we create a user and save the record to TiDB to later be queried and printed.
|
||||
```go title="main.go"
|
||||
client.User.Create().
|
||||
SetAge(30).
|
||||
SetName("hedwigz").
|
||||
SaveX(context.Background())
|
||||
user := client.User.Query().FirstX(context.Background())
|
||||
fmt.Printf("the user: %s is %d years old\n", user.Name, user.Age)
|
||||
```
|
||||
3. Run the example program:
|
||||
```go
|
||||
$ go run main.go
|
||||
the user: hedwigz is 30 years old
|
||||
```
|
||||
|
||||
Woohoo! In this quick walk-through we managed to:
|
||||
* Spin up a local instance of TiDB.
|
||||
* Connect Ent with TiDB.
|
||||
* Migrate our Ent schema with Atlas.
|
||||
* Insert and query from TiDB using Ent.
|
||||
|
||||
### Preview support
|
||||
The integration of Atlas with TiDB is well tested with TiDB version `v5.4.0` (at the time of writing, `latest`) and we will extend that in the future.
|
||||
If you're using other versions of TiDB or looking for help, don't hesitate to [file an issue](https://github.com/ariga/atlas/issues) or join our [Discord channel](https://discord.gg/zZ6sWVg6NT).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
128
doc/website/blog/2022-04-07-how-twitter-can-implement.md
Normal file
128
doc/website/blog/2022-04-07-how-twitter-can-implement.md
Normal file
@@ -0,0 +1,128 @@
|
||||
---
|
||||
title: How to implement the Twitter edit button with Ent
|
||||
author: Amit Shani
|
||||
authorURL: "https://github.com/hedwigz"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/8277210?v=4"
|
||||
authorTwitter: itsamitush
|
||||
image: "https://entgo.io/images/assets/enthistory/share.png"
|
||||
---
|
||||
|
||||
Twitter's "Edit Button" feature has reached the headlines with Elon Musk's poll tweet asking whether users want the feature or not.
|
||||
|
||||
[](https://twitter.com/elonmusk/status/1511143607385874434)
|
||||
|
||||
Without a doubt, this is one of Twitter's most requested features.
|
||||
|
||||
As a software developer, I immediately began to think about how I would implement this myself. The tracking/auditing problem is very common in many applications. If you have an entity (say, a `Tweet`) and you want to track changes to one of its fields (say, the `content` field), there are many common solutions. Some databases even have proprietary solutions like Microsoft's change tracking and MariaDB's System Versioned Tables. However, in most use-cases you'd have to "stitch" it yourself. Luckily, Ent provides a modular extensions system that lets you plug in features like this with just a few lines of code.
|
||||
|
||||

|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<p style={{fontSize: 12}}>if only</p>
|
||||
</div>
|
||||
|
||||
### Introduction to Ent
|
||||
Ent is an Entity framework for Go that makes developing large applications a breeze. Ent comes pre-packed with awesome features out of the box, such as:
|
||||
* Type-safe generated [CRUD API](https://entgo.io/docs/crud)
|
||||
* Complex [Graph traversals](https://entgo.io/docs/traversals) (SQL joins made easy)
|
||||
* [Paging](https://entgo.io/docs/paging)
|
||||
* [Privacy](https://entgo.io/docs/privacy)
|
||||
* Safe DB [migrations](https://entgo.io/blog/2022/03/14/announcing-versioned-migrations).
|
||||
|
||||
With Ent's code generation engine and advanced [extensions system](https://entgo.io/blog/2021/09/02/ent-extension-api/), you can easily modularize your Ent's client with advanced features that are usually time-consuming to implement manually. For example:
|
||||
* Generate [REST](https://entgo.io/blog/2022/02/15/generate-rest-crud-with-ent-and-ogen), [gRPC](https://entgo.io/docs/grpc-intro), and [GraphQL](https://entgo.io/docs/graphql) server.
|
||||
* [Caching](http://entgo.io/blog/2021/10/14/introducing-entcache)
|
||||
* Monitoring with [sqlcommenter](https://entgo.io/blog/2021/10/19/sqlcomment-support-for-ent)
|
||||
|
||||
### Enthistory
|
||||
`enthistory` is an extension that we started developing when we wanted to add an "Activity & History" panel to one of our web services. The panel's role is to show who changed what and when (aka auditing). In [Atlas](https://atlasgo.io/), a tool for managing databases using declarative HCL files, we have an entity called "schema" which is essentially a large text blob. Any change to the schema is logged and can later be viewed in the "Activity & History" panel.
|
||||
|
||||

|
||||
|
||||
<div style={{textAlign: 'center'}}>
|
||||
<p style={{fontSize: 12}}>The "Activity & History" screen in Atlas</p>
|
||||
</div>
|
||||
|
||||
This feature is very common and can be found in many apps, such as Google docs, GitHub PRs, and Facebook posts, but is unfortunately missing in the very popular and beloved Twitter.
|
||||
|
||||
Over 3 million people voted in favor of adding the "edit button" to Twitter, so let me show you how Twitter can make their users happy without breaking a sweat!
|
||||
|
||||
With Enthistory, all you have to do is simply annotate your Ent schema like so:
|
||||
|
||||
```go
|
||||
func (Tweet) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("content").
|
||||
Annotations(enthistory.TrackField()),
|
||||
field.Time("created").
|
||||
Default(time.Now),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Enthistory hooks into your Ent client to ensure that every CRUD operation to "Tweet" is recorded into the "tweets_history" table, with no code modifications and provides an API to consume these records:
|
||||
|
||||
```go
|
||||
// Creating a new Tweet doesn't change. enthistory automatically modifies
|
||||
// your transaction on the fly to record this event in the history table
|
||||
client.Tweet.Create().SetContent("hello world!").SaveX(ctx)
|
||||
|
||||
// Querying history changes is as easy as querying any other entity's edge.
|
||||
t, _ := client.Tweet.Get(ctx, id)
|
||||
hs := client.Tweet.QueryHistory(t).WithChanges().AllX(ctx)
|
||||
```
|
||||
|
||||
Let's see what you'd have to do if you weren't using Enthistory: For example, consider an app similar to Twitter. It has a table called "tweets" and one of its columns is the tweet content.
|
||||
|
||||
| id | content | created_at | author_id |
|
||||
| ----------- | ----------- | ----------- | ----------- |
|
||||
| 1 | Hello Twitter! | 2022-04-06T13:45:34+00:00 | 123 |
|
||||
| 2 | Hello Gophers! | 2022-04-06T14:03:54+00:00 | 456 |
|
||||
|
||||
Now, assume that we want to allow users to edit the content, and simultaneously display the changes in the frontend. There are several common approaches for solving this problem, each with its own pros and cons, but we will dive into those in another technical post. For now, a possible solution for this is to create a table "tweets_history" which records the changes of a tweet:
|
||||
|
||||
| id | tweet_id | timestamp | event | content |
|
||||
| ----------- | ----------- | ----------- | ----------- | ----------- |
|
||||
| 1 | 1 | 2022-04-06T12:30:00+00:00 | CREATED | hello world! |
|
||||
| 2 | 2 | 2022-04-06T13:45:34+00:00 | UPDATED | hello Twitter! |
|
||||
|
||||
With a table similar to the one above, we can record changes to the original tweet "1" and if requested, we can show that it was originally tweeted at 12:30:00 with the content "hello world!" and was modified at 13:45:34 to "hello Twitter!".
|
||||
|
||||
To implement this, we will have to change every `UPDATE` statement for "tweets" to include an `INSERT` to "tweets_history". For correctness, we will need to wrap both statements in a transaction to avoid corrupting the history. in case the first statement succeeds but the subsequent one fails. We'd also need to make sure every `INSERT` to "tweets" is coupled with an `INSERT` to "tweets_history"
|
||||
|
||||
```diff
|
||||
# INSERT is logged as "CREATE" history event
|
||||
- INSERT INTO tweets (`content`) VALUES ('Hello World!');
|
||||
+BEGIN;
|
||||
+INSERT INTO tweets (`content`) VALUES ('Hello World!');
|
||||
+INSERT INTO tweets_history (`content`, `timestamp`, `record_id`, `event`)
|
||||
+VALUES ('Hello World!', NOW(), 1, 'CREATE');
|
||||
+COMMIT;
|
||||
|
||||
# UPDATE is logged as "UPDATE" history event
|
||||
- UPDATE tweets SET `content` = 'Hello World!' WHERE id = 1;
|
||||
+BEGIN;
|
||||
+UPDATE tweets SET `content` = 'Hello World!' WHERE id = 1;
|
||||
+INSERT INTO tweets_history (`content`, `timestamp`, `record_id`, `event`)
|
||||
+VALUES ('Hello World!', NOW(), 1, 'UPDATE');
|
||||
+COMMIT;
|
||||
```
|
||||
|
||||
This method is nice but you'd have to create another table for different entities ("comment_history", "settings_history"). To prevent that, Enthistory creates a single "history" and a single "changes" table and records all the tracked fields there. It also supports many type of fields without needing to add more columns.
|
||||
|
||||
### Pre release
|
||||
Enthistory is still in early design stages and is being internally tested. Therefore, we haven't released it to open-source yet, though we plan to do so very soon.
|
||||
If you want to play with a pre-release version of Enthistory, I wrote a simple React application with GraphQL+Enthistory to demonstrate how a tweet edit could look like. You can check it out [here](https://github.com/hedwigz/edit-twitter-example-app). Please feel free to share your feedback.
|
||||
|
||||
### Wrapping up
|
||||
We saw how Ent's modular extension system lets you streamline advanced features as if they were just a package install away. Developing your own extension [is fun, easy and educating](https://entgo.io/blog/2021/12/09/contributing-my-first-feature-to-ent-grpc-plugin)! I invite you to try it yourself!
|
||||
In the future, Enthistory will be used to track changes to Edges (aka foreign-keyed tables), integrate with OpenAPI and GraphQL extensions, and provide more methods for its underlying implementation.
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
247
doc/website/blog/2022-05-09-versioned-migrations-sum-file.md
Normal file
247
doc/website/blog/2022-05-09-versioned-migrations-sum-file.md
Normal file
@@ -0,0 +1,247 @@
|
||||
---
|
||||
title: Versioned Migrations Management and Migration Directory Integrity
|
||||
author: Jannik Clausen (MasseElch)
|
||||
authorURL: "https://github.com/masseelch"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/12862103?v=4"
|
||||
image: "https://entgo.io/images/assets/migrate/atlas-validate.png"
|
||||
---
|
||||
|
||||
Five weeks ago we released a long awaited feature for managing database changes in Ent: **Versioned Migrations**. In
|
||||
the [announcement blog post](2022-03-14-announcing-versioned-migrations.md) we gave a brief introduction into both the
|
||||
declarative and change-based approach to keep database schemas in sync with the consuming applications, as well as their
|
||||
drawbacks and why [Atlas'](https://atlasgo.io) (Ents underlying migration engine) attempt of bringing the best of both
|
||||
worlds into one workflow is worth a try. We call it **Versioned Migration Authoring** and if you haven't read it, now is
|
||||
a good time!
|
||||
|
||||
With versioned migration authoring, the resulting migration files are still "change-based", but have been safely planned
|
||||
by the Atlas engine. This means that you can still use your favorite migration management tool,
|
||||
like [Flyway](https://flywaydb.org/), [Liquibase](https://liquibase.org/),
|
||||
[golang-migrate/migrate](https://github.com/golang-migrate/migrate), or
|
||||
[pressly/goose](https://github.com/pressly/goose) when developing services with Ent.
|
||||
|
||||
In this blog post I want to show you another new feature of the Atlas project we call the **Migration Directory
|
||||
Integrity File**, which is now supported in Ent, and how you can use it with any of the migration management tools you
|
||||
are already used to and like.
|
||||
|
||||
### The Problem
|
||||
|
||||
When using versioned migrations, developers need to be careful of doing the following in order to not break the database:
|
||||
|
||||
1. Retroactively changing migrations that have already run.
|
||||
2. Accidentally changing the order in which migrations are organized.
|
||||
3. Checking in semantically incorrect SQL scripts.
|
||||
Theoretically, code review should guard teams from merging migrations with these issues. In my experience, however, there are many kinds of errors that can slip the human eye, making this approach error-prone.
|
||||
Therefore, an automated way of preventing these errors is much safer.
|
||||
|
||||
The first issue (changing history) is addressed by most management tools by saving a hash of the applied migration file to the managed
|
||||
database and comparing it with the files. If they don't match, the migration can be aborted. However, this happens in a
|
||||
very late stage in the development cycle (during deployment), and it could save both time and resources if this can be detected
|
||||
earlier.
|
||||
|
||||
For the second (and third) issue, consider the following scenario:
|
||||
|
||||

|
||||
|
||||
This diagram shows two possible errors that go undetected. The first one being the order of the migration files.
|
||||
|
||||
Team A and Team B both branch a feature roughly at the same time. Team B generates a migration file with a version
|
||||
timestamp **x** and continues to work on the feature. Team A generates a migration file at a later point in time and
|
||||
therefore has the migration version timestamp **x+1**. Team A finishes the feature and merges it into master,
|
||||
possibly automatically deploying it in production with the migration version **x+1** applied. No problem so far.
|
||||
|
||||
Now, Team B merges its feature with the migration version **x**, which predates the already applied version **x+1**. If the code
|
||||
review process does not detect this, the migration file lands in production, and it now depends on the specific migration
|
||||
management tool to decide what happens.
|
||||
|
||||
Most tools have their own solution to that problem, `pressly/goose` for example takes an approach they
|
||||
call [hybrid versioning](https://github.com/pressly/goose/issues/63#issuecomment-428681694). Before I introduce you to
|
||||
Atlas' (Ent's) unique way of handling this problem, let's have a quick look at the third issue:
|
||||
|
||||
If both Team A and Team B develop a feature where they need new tables or columns, and they give them the same name, (e.g.
|
||||
`users`) they could both generate a statement to create that table. While the team that merges first will have a
|
||||
successful migration, the second team's migration will fail since the table or column already exists.
|
||||
|
||||
### The Solution
|
||||
|
||||
Atlas has a unique way of handling the above problems. The goal is to raise awareness about the issues as soon as
|
||||
possible. In our opinion, the best place to do so is in version control and continuous integration (CI) parts of a
|
||||
product. Atlas' solution to this is the introduction of a new file we call the **Migration Directory Integrity File**.
|
||||
It is simply another file named `atlas.sum` that is stored together with the migration files and contains some
|
||||
metadata about the migration directory. Its format is inspired by the `go.sum` file of a Go module, and it would look
|
||||
similar to this:
|
||||
|
||||
```text
|
||||
h1:KRFsSi68ZOarsQAJZ1mfSiMSkIOZlMq4RzyF//Pwf8A=
|
||||
20220318104614_team_A.sql h1:EGknG5Y6GQYrc4W8e/r3S61Aqx2p+NmQyVz/2m8ZNwA=
|
||||
```
|
||||
|
||||
The `atlas.sum` file contains a sum of the whole directory as its first entry, and a checksum for each of the migration
|
||||
files (implemented by a reverse, one branch merkle hash tree). Let's see how we can use this file to detect the cases
|
||||
above in version control and CI. Our goal is to raise awareness that both teams added migrations and that they most
|
||||
likely have to be checked before proceeding the merge.
|
||||
|
||||
:::note
|
||||
To follow along, run the following commands to quickly have an example to work with. They will:
|
||||
|
||||
1. Create a Go module and download all needed dependencies
|
||||
2. Create a very basic User schema
|
||||
3. Enable the versioned migrations feature
|
||||
4. Run the codegen
|
||||
5. Start a MySQL docker container to use (remove with `docker stop atlas-sum`)
|
||||
|
||||
```shell
|
||||
mkdir ent-sum-file
|
||||
cd ent-sum-file
|
||||
go mod init ent-sum-file
|
||||
go install entgo.io/ent/cmd/ent@master
|
||||
go run entgo.io/ent/cmd/ent new User
|
||||
sed -i -E 's|^//go(.*)$|//go\1 --feature sql/versioned-migration|' ent/generate.go
|
||||
go generate ./...
|
||||
docker run --rm --name atlas-sum --detach --env MYSQL_ROOT_PASSWORD=pass --env MYSQL_DATABASE=ent -p 3306:3306 mysql
|
||||
```
|
||||
:::
|
||||
|
||||
The first step is to tell the migration engine to create and manage the `atlas.sum` by using the `schema.WithSumFile()`
|
||||
option. The below example uses an [instantiated Ent client](/docs/versioned-migrations#from-client) to generate new
|
||||
migration files:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"log"
|
||||
"os"
|
||||
|
||||
"ent-sum-file/ent"
|
||||
|
||||
"ariga.io/atlas/sql/migrate"
|
||||
"entgo.io/ent/dialect/sql/schema"
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client, err := ent.Open("mysql", "root:pass@tcp(localhost:3306)/ent")
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
ctx := context.Background()
|
||||
// Create a local migration directory.
|
||||
dir, err := migrate.NewLocalDir("migrations")
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating atlas migration directory: %v", err)
|
||||
}
|
||||
// Write migration diff.
|
||||
// highlight-start
|
||||
err = client.Schema.NamedDiff(ctx, os.Args[1], schema.WithDir(dir), schema.WithSumFile())
|
||||
// highlight-end
|
||||
if err != nil {
|
||||
log.Fatalf("failed creating schema resources: %v", err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
After creating a migrations directory and running the above commands you should see `golang-migrate/migrate` compatible
|
||||
migration files and in addition, the `atlas.sum` file with the following contents:
|
||||
|
||||
```shell
|
||||
mkdir migrations
|
||||
go run -mod=mod main.go initial
|
||||
```
|
||||
|
||||
```sql title="20220504114411_initial.up.sql"
|
||||
-- create "users" table
|
||||
CREATE TABLE `users` (`id` bigint NOT NULL AUTO_INCREMENT, PRIMARY KEY (`id`)) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
|
||||
```
|
||||
|
||||
```sql title="20220504114411_initial.down.sql"
|
||||
-- reverse: create "users" table
|
||||
DROP TABLE `users`;
|
||||
|
||||
```
|
||||
|
||||
```text title="atlas.sum"
|
||||
h1:SxbWjP6gufiBpBjOVtFXgXy7q3pq1X11XYUxvT4ErxM=
|
||||
20220504114411_initial.down.sql h1:OllnelRaqecTrPbd2YpDbBEymCpY/l6ihbyd/tVDgeY=
|
||||
20220504114411_initial.up.sql h1:o/6yOczGSNYQLlvALEU9lK2/L6/ws65FrHJkEk/tjBk=
|
||||
```
|
||||
|
||||
As you can see the `atlas.sum` file contains one entry for each migration file generated. With the `atlas.sum`
|
||||
generation file enabled, both Team A and Team B will have such a file once they generate migrations for a schema change.
|
||||
Now the version control will raise a merge conflict once the second Team attempts to merge their feature.
|
||||
|
||||

|
||||
|
||||
:::note
|
||||
In the following steps we invoke the Atlas CLI by calling `go run -mod=mod ariga.io/atlas/cmd/atlas`, but you can also
|
||||
install the CLI globally (and then simply invoke it by calling `atlas`) to your system by following the installation
|
||||
instructions [here](https://atlasgo.io/cli/getting-started/setting-up#install-the-cli).
|
||||
:::
|
||||
|
||||
You can check at any time, if your `atlas.sum` file is in sync with the migration directory with the following command (
|
||||
which should not output any errors now):
|
||||
|
||||
```shell
|
||||
go run -mod=mod ariga.io/atlas/cmd/atlas migrate validate
|
||||
```
|
||||
|
||||
However, if you happen to make a manual change to your migration files, like adding a new SQL statement, editing an
|
||||
existing one or even creating a completely new file, the `atlas.sum` file is no longer in sync with the migration
|
||||
directory's contents. Attempting to generate new migration files for a schema change will now be blocked by the Atlas
|
||||
migration engine. Try it out by creating a new empty migration file and run the `main.go` once again:
|
||||
|
||||
```shell
|
||||
go run -mod=mod ariga.io/atlas/cmd/atlas migrate new migrations/manual_version.sql --format golang-migrate
|
||||
go run -mod=mod main.go initial
|
||||
# 2022/05/04 15:08:09 failed creating schema resources: validating migration directory: checksum mismatch
|
||||
# exit status 1
|
||||
|
||||
```
|
||||
|
||||
The `atlas migrate validate` command will tell you the same:
|
||||
|
||||
```shell
|
||||
go run -mod=mod ariga.io/atlas/cmd/atlas migrate validate
|
||||
# Error: checksum mismatch
|
||||
#
|
||||
# You have a checksum error in your migration directory.
|
||||
# This happens if you manually create or edit a migration file.
|
||||
# Please check your migration files and run
|
||||
#
|
||||
# 'atlas migrate hash --force'
|
||||
#
|
||||
# to re-hash the contents and resolve the error.
|
||||
#
|
||||
# exit status 1
|
||||
```
|
||||
|
||||
In order to get the `atlas.sum` file back in sync with the migration directory, we can once again use the Atlas CLI:
|
||||
|
||||
```shell
|
||||
go run -mod=mod ariga.io/atlas/cmd/atlas migrate hash --force
|
||||
```
|
||||
|
||||
As a safety measure, the Atlas CLI does not operate on a migration directory that is not in sync with its `atlas.sum`
|
||||
file. Therefore, you need to add the `--force` flag to the command.
|
||||
|
||||
For cases where a developer forgets to update the `atlas.sum` file after making a manual change, you can add
|
||||
an `atlas migrate validate` call to your CI. We are actively working on a GitHub action and CI solution, that does this
|
||||
(among and other things) for you _out-of-the-box_.
|
||||
|
||||
### Wrapping Up
|
||||
|
||||
In this post, we gave a brief introduction to common sources of schema migration when working with change based SQL
|
||||
files and introduced a solution based on the Atlas project to make migrations more safe.
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join
|
||||
our [Ent Discord Server](https://discord.gg/qZmPgTE6RX).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
:::
|
||||
307
doc/website/blog/2022-09-06-ci-for-ent.mdx
Normal file
307
doc/website/blog/2022-09-06-ci-for-ent.mdx
Normal file
@@ -0,0 +1,307 @@
|
||||
---
|
||||
title: Continuous Integration for Ent Projects
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
image: "https://entgo.io/images/assets/ent-ci-post.png"
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
To ensure the quality of their software, teams often apply _Continuous
|
||||
Integration_ workflows, commonly known as CI. With CI, teams continuously run a suite
|
||||
of automated verifications against every change to the code-base. During CI,
|
||||
teams may run many kinds of verifications:
|
||||
|
||||
* Compilation or build of the most recent version to make sure it
|
||||
isn't broken.
|
||||
* Linting to enforce any accepted code-style standards.
|
||||
* Unit tests that verify individual components work as expected
|
||||
and that changes to the codebase do not cause regressions in
|
||||
other areas.
|
||||
* Security scans to make sure no known vulnerabilities are introduced
|
||||
to the codebase.
|
||||
* And much more!
|
||||
|
||||
From our discussions with the Ent community, we have learned
|
||||
that many teams using Ent already use CI and would like to enforce some
|
||||
Ent-specific verifications into their workflows.
|
||||
|
||||
To support the community with this effort, we added a new [guide](/docs/ci) to the docs which
|
||||
documents common best practices to verify in CI and introduces
|
||||
[ent/contrib/ci](https://github.com/ent/contrib/tree/master/ci): a GitHub Action
|
||||
we maintain that codifies them.
|
||||
|
||||
In this post, I want to share some of our initial suggestions on how you
|
||||
might incorporate CI to you Ent project. Towards the end of this post
|
||||
I will share insights into projects we are working on and would like to
|
||||
get the community's feedback for.
|
||||
|
||||
## Verify all generated files are checked in
|
||||
|
||||
Ent heavily relies on code generation. In our experience, generated code
|
||||
should always be checked into source control. This is done for two reasons:
|
||||
* If generated code is checked into source control, it can be read
|
||||
along with the main application code. Having generated code present when
|
||||
the code is reviewed or when a repository is browsed is essential to get
|
||||
a complete picture of how things work.
|
||||
* Differences in development environments between team members can easily be
|
||||
spotted and remedied. This further reduces the chance of "it works on my
|
||||
machine" type issues since everyone is running the same code.
|
||||
|
||||
If you're using GitHub for source control, it's easy to verify that all generated
|
||||
files are checked in with the `ent/contrib/ci` GitHub Action.
|
||||
Otherwise, we supply a simple bash script that you can integrate in your existing
|
||||
CI flow.
|
||||
|
||||
<Tabs
|
||||
defaultValue="gh"
|
||||
values={[
|
||||
{label: 'GitHub Action', value: 'gh'},
|
||||
{label: 'Bash', value: 'bash'},
|
||||
]}>
|
||||
<TabItem value="gh">
|
||||
|
||||
Simply add a file named `.github/workflows/ent-ci.yaml` in your repository:
|
||||
|
||||
```yaml
|
||||
name: EntCI
|
||||
on:
|
||||
push:
|
||||
# Run whenever code is changed in the master.
|
||||
branches:
|
||||
- master
|
||||
# Run on PRs where something changed under the `ent/` directory.
|
||||
pull_request:
|
||||
paths:
|
||||
- 'ent/*'
|
||||
jobs:
|
||||
ent:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3.0.1
|
||||
- uses: actions/setup-go@v3
|
||||
with:
|
||||
go-version: 1.18
|
||||
- uses: ent/contrib/ci@master
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="bash">
|
||||
|
||||
```bash
|
||||
go generate ./...
|
||||
status=$(git status --porcelain)
|
||||
if [ -n "$status" ]; then
|
||||
echo "you need to run 'go generate ./...' and commit the changes"
|
||||
echo "$status"
|
||||
exit 1
|
||||
fi
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Lint migration files
|
||||
|
||||
Changes to your project's Ent schema almost always result in a modification
|
||||
of your database. If you are using [Versioned Migrations](/docs/versioned-migrations)
|
||||
to manage changes to your database schema, you can run [migration linting](https://atlasgo.io/versioned/lint)
|
||||
as part of your continuous integration flow. This is done for multiple reasons:
|
||||
|
||||
* Linting replays your migration directory on a [database container](https://atlasgo.io/concepts/dev-database) to
|
||||
make sure all SQL statements are valid and in the correct order.
|
||||
* [Migration directory integrity](/docs/versioned-migrations#atlas-migration-directory-integrity-file)
|
||||
is enforced - ensuring that history wasn't accidentally changed and that migrations that are
|
||||
planned in parallel are unified to a clean linear history.
|
||||
* Destructive changes are detected, notifying you of any potential data loss that may be
|
||||
caused by your migrations way before they reach your production database.
|
||||
* Linting detects data-dependent changes that _may_ fail upon deployment and require
|
||||
more careful review from your side.
|
||||
|
||||
If you're using GitHub, you can use the [Official Atlas Action](https://github.com/ariga/atlas-action)
|
||||
to run migration linting during CI.
|
||||
|
||||
Add `.github/workflows/atlas-ci.yaml` to your repo with the following contents:
|
||||
|
||||
<Tabs
|
||||
defaultValue="mysql"
|
||||
values={[
|
||||
{label: 'MySQL', value: 'mysql'},
|
||||
{label: 'MariaDB', value: 'maria'},
|
||||
{label: 'PostgreSQL', value: 'postgres'},
|
||||
]}>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```yaml
|
||||
name: Atlas CI
|
||||
on:
|
||||
# Run whenever code is changed in the master branch,
|
||||
# change this to your root branch.
|
||||
push:
|
||||
branches:
|
||||
- master
|
||||
# Run on PRs where something changed under the `ent/migrate/migrations/` directory.
|
||||
pull_request:
|
||||
paths:
|
||||
- 'ent/migrate/migrations/*'
|
||||
jobs:
|
||||
lint:
|
||||
services:
|
||||
# Spin up a mysql:8.0.29 container to be used as the dev-database for analysis.
|
||||
mysql:
|
||||
image: mysql:8.0.29
|
||||
env:
|
||||
MYSQL_ROOT_PASSWORD: pass
|
||||
MYSQL_DATABASE: test
|
||||
ports:
|
||||
- 3306:3306
|
||||
options: >-
|
||||
--health-cmd "mysqladmin ping -ppass"
|
||||
--health-interval 10s
|
||||
--health-start-period 10s
|
||||
--health-timeout 5s
|
||||
--health-retries 10
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3.0.1
|
||||
with:
|
||||
fetch-depth: 0 # Mandatory unless "latest" is set below.
|
||||
- uses: ariga/atlas-action@v0
|
||||
with:
|
||||
dir: ent/migrate/migrations
|
||||
dir-format: golang-migrate # Or: atlas, goose, dbmate
|
||||
dev-url: mysql://root:pass@localhost:3306/test
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="maria">
|
||||
|
||||
```yaml
|
||||
name: Atlas CI
|
||||
on:
|
||||
# Run whenever code is changed in the master branch,
|
||||
# change this to your root branch.
|
||||
push:
|
||||
branches:
|
||||
- master
|
||||
# Run on PRs where something changed under the `ent/migrate/migrations/` directory.
|
||||
pull_request:
|
||||
paths:
|
||||
- 'ent/migrate/migrations/*'
|
||||
jobs:
|
||||
lint:
|
||||
services:
|
||||
# Spin up a maria:10.7 container to be used as the dev-database for analysis.
|
||||
maria:
|
||||
image: mariadb:10.7
|
||||
env:
|
||||
MYSQL_DATABASE: test
|
||||
MYSQL_ROOT_PASSWORD: pass
|
||||
ports:
|
||||
- 3306:3306
|
||||
options: >-
|
||||
--health-cmd "mysqladmin ping -ppass"
|
||||
--health-interval 10s
|
||||
--health-start-period 10s
|
||||
--health-timeout 5s
|
||||
--health-retries 10
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3.0.1
|
||||
with:
|
||||
fetch-depth: 0 # Mandatory unless "latest" is set below.
|
||||
- uses: ariga/atlas-action@v0
|
||||
with:
|
||||
dir: ent/migrate/migrations
|
||||
dir-format: golang-migrate # Or: atlas, goose, dbmate
|
||||
dev-url: maria://root:pass@localhost:3306/test
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="postgres">
|
||||
|
||||
```yaml
|
||||
name: Atlas CI
|
||||
on:
|
||||
# Run whenever code is changed in the master branch,
|
||||
# change this to your root branch.
|
||||
push:
|
||||
branches:
|
||||
- master
|
||||
# Run on PRs where something changed under the `ent/migrate/migrations/` directory.
|
||||
pull_request:
|
||||
paths:
|
||||
- 'ent/migrate/migrations/*'
|
||||
jobs:
|
||||
lint:
|
||||
services:
|
||||
# Spin up a postgres:10 container to be used as the dev-database for analysis.
|
||||
postgres:
|
||||
image: postgres:10
|
||||
env:
|
||||
POSTGRES_DB: test
|
||||
POSTGRES_PASSWORD: pass
|
||||
ports:
|
||||
- 5432:5432
|
||||
options: >-
|
||||
--health-cmd pg_isready
|
||||
--health-interval 10s
|
||||
--health-timeout 5s
|
||||
--health-retries 5
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3.0.1
|
||||
with:
|
||||
fetch-depth: 0 # Mandatory unless "latest" is set below.
|
||||
- uses: ariga/atlas-action@v0
|
||||
with:
|
||||
dir: ent/migrate/migrations
|
||||
dir-format: golang-migrate # Or: atlas, goose, dbmate
|
||||
dev-url: postgres://postgres:pass@localhost:5432/test?sslmode=disable
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
Notice that running `atlas migrate lint` requires a clean [dev-database](https://atlasgo.io/concepts/dev-database)
|
||||
which is provided by the `services` block in the example code above.
|
||||
|
||||
## What's next for Ent CI
|
||||
|
||||
To add to this modest beginning, I want to share some features that we are experimenting
|
||||
with at [Ariga](https://ariga.io) with hope to get the community's feedback on them.
|
||||
|
||||
* *Linting for Online Migrations* - many Ent projects use the automatic schema migration
|
||||
mechanism that is available in Ent (using `ent.Schema.Create` when applications start).
|
||||
Assuming a project's source code is managed in a version control system (such as Git),
|
||||
we compare the schema in the mainline branch (`master`/`main`/etc.) with the one in the
|
||||
current feature branch and use [Atlas's schema diff capability](https://atlasgo.io/declarative/diff)
|
||||
to calculate the SQL statements that are going to be run against the database. We can then
|
||||
use [Atlas's linting capability](https://atlasgo.io/versioned/lint) to provide insights
|
||||
about possible dangers the arise from the proposed change.
|
||||
* *Change visualization* - to assist reviewers in understanding the impact of changes
|
||||
proposed in a specific pull request we generate a visual diff
|
||||
(using an ERD similar to [entviz](/blog/2021/08/26/visualizing-your-data-graph-using-entviz/)) reflect
|
||||
the changes to a project's schema.
|
||||
* *Schema Linting* - using the official [go/analysis](https://pkg.go.dev/golang.org/x/tools/go/analysis)
|
||||
package to create linters that analyze an Ent schema's Go code and enforce policies (such as naming
|
||||
or indexing conventions) on the schema definition level.
|
||||
|
||||
### Wrapping up
|
||||
|
||||
In this post, we presented the concept of CI and discussed ways in which it
|
||||
can be practiced for Ent projects. Next, we presented CI checks we are experimenting
|
||||
with internally. If you would like to see these checks become a part of Ent or have other ideas
|
||||
for providing CI tools for Ent, ping us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
:::
|
||||
|
||||
297
doc/website/blog/2022-10-10-json-append.mdx
Normal file
297
doc/website/blog/2022-10-10-json-append.mdx
Normal file
@@ -0,0 +1,297 @@
|
||||
---
|
||||
title: Appending values to JSON fields with Ent
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
image: "https://entgo.io/images/assets/ent-json-append.png"
|
||||
---
|
||||
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
### TL;DR
|
||||
|
||||
* Most relational databases support columns with unstructured JSON values.
|
||||
* Ent has great support for working with JSON values in relational databases.
|
||||
* How to append values to a JSON array in an atomic way.
|
||||
* Ent recently added support for atomically appending values to fields in JSON values.
|
||||
|
||||
### JSON values in SQL databases
|
||||
|
||||
Despite being known mostly for storing structured tabular data, virtually all
|
||||
modern relational databases support JSON columns for storing unstructured data
|
||||
in table columns. For example, in MySQL you can create a table such as:
|
||||
|
||||
```sql
|
||||
CREATE TABLE t1 (jdoc JSON);
|
||||
```
|
||||
|
||||
In this column, users may store JSON objects of an arbitrary schema:
|
||||
|
||||
```sql
|
||||
INSERT INTO t1 VALUES('{"key1": "value1", "key2": "value2"}');
|
||||
```
|
||||
|
||||
Because JSON documents can always be expressed as strings, they can
|
||||
be stored in regular VARCHAR or TEXT columns. However, when a column is declared
|
||||
with the JSON type, the database enforces the correctness of the JSON
|
||||
syntax. For example, if we try to write an incorrect JSON document to
|
||||
this MySQL table:
|
||||
```sql
|
||||
INSERT INTO t1 VALUES('[1, 2,');
|
||||
```
|
||||
We will receive this error:
|
||||
```console
|
||||
ERROR 3140 (22032) at line 2: Invalid JSON text:
|
||||
"Invalid value." at position 6 in value (or column) '[1, 2,'.
|
||||
```
|
||||
In addition, values stored inside JSON documents may be accessed
|
||||
in SELECT statements using [JSON Path](https://dev.mysql.com/doc/refman/8.0/en/json.html#json-path-syntax)
|
||||
expressions, as well as used in predicates (WHERE clauses) to filter data:
|
||||
```sql
|
||||
select c->'$.hello' as greeting from t where c->'$.hello' = 'world';;
|
||||
```
|
||||
To get:
|
||||
```text
|
||||
+--------------+
|
||||
| greeting |
|
||||
+--------------+
|
||||
| "world" |
|
||||
+--------------+
|
||||
1 row in set (0.00 sec)
|
||||
```
|
||||
|
||||
### JSON values in Ent
|
||||
|
||||
With Ent, users may define JSON fields in schemas using `field.JSON` by passing
|
||||
the desired field name as well as the backing Go type. For example:
|
||||
|
||||
```go
|
||||
type Tag struct {
|
||||
Name string `json:"name"`
|
||||
Created time.Time `json:"created"`
|
||||
}
|
||||
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.JSON("tags", []Tag{}),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Ent provides a convenient API for reading and writing values to JSON columns, as well
|
||||
as applying predicates (using [`sqljson`](https://entgo.io/docs/predicates/#json-predicates)):
|
||||
```go
|
||||
func TestEntJSON(t *testing.T) {
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
ctx := context.Background()
|
||||
// Insert a user with two comments.
|
||||
client.User.Create().
|
||||
SetTags([]schema.Tag{
|
||||
{Name: "hello", Created: time.Now()},
|
||||
{Name: "goodbye", Created: time.Now()},
|
||||
}).
|
||||
SaveX(ctx)
|
||||
|
||||
// Count how many users have more than zero tags.
|
||||
count := client.User.Query().
|
||||
Where(func(s *sql.Selector) {
|
||||
s.Where(
|
||||
sqljson.LenGT(user.FieldTags, 0),
|
||||
)
|
||||
}).
|
||||
CountX(ctx)
|
||||
fmt.Printf("count: %d", count)
|
||||
// Prints: count: 1
|
||||
}
|
||||
```
|
||||
|
||||
### Appending values to fields in JSON columns
|
||||
|
||||
In many cases, it is useful to append a value to a list in a JSON column.
|
||||
Preferably, appends are implemented in a way that is _atomic_, meaning, without
|
||||
needing to read the current value and writing the entire new value. The reason
|
||||
for this is that if two calls try to append the value concurrently, both will
|
||||
read the same _current_ value from the database, and write their own updated version
|
||||
roughly at the same time. Unless [optimistic locking](2021-07-22-database-locking-techniques-with-ent.md)
|
||||
is used, both writes will succeed, but the final result will only include one of
|
||||
the new values.
|
||||
|
||||
To overcome this race condition, we can let the database take care of the synchronization
|
||||
between both calls by using a clever UPDATE query. The intuition for this solution
|
||||
is similar to how counters are incremented in many applications. Instead of running:
|
||||
```sql
|
||||
SELECT points from leaderboard where user='rotemtam'
|
||||
```
|
||||
Reading the result (lets say its 1000), incrementing the value in process (1000+1=1001) and writing the new sum
|
||||
verbatim:
|
||||
```sql
|
||||
UPDATE leaderboard SET points=1001 where user='rotemtam'
|
||||
```
|
||||
Developers can use a query such as:
|
||||
```sql
|
||||
UPDATE leaderboard SET points=points+1 where user='rotemtam'
|
||||
```
|
||||
|
||||
To avoid the need to synchronize writes using optimistic locking
|
||||
or some other mechanism, let's see how we can similarly leverage the database's capability to
|
||||
perform them concurrently in a safe manner.
|
||||
|
||||
There are two things to note as we are constructing this query. First, the syntax for working
|
||||
with JSON values varies a bit between different database vendors, as you will see in
|
||||
the examples below. Second, a query for appending a value to a list in a JSON document
|
||||
needs to handle at least two edge cases:
|
||||
1. The field we want to append to doesn't exist yet in the JSON document.
|
||||
2. The field exists but is set to JSON `null`.
|
||||
|
||||
Here is what such a query might look like for appending a value `new_val` to a field named `a`
|
||||
in a column `c` for table `t` in different dialects:
|
||||
<Tabs
|
||||
defaultValue="mysql"
|
||||
values={[
|
||||
{label: 'MySQL', value: 'mysql'},
|
||||
{label: 'PostgeSQL', value: 'pgsql'},
|
||||
{label: 'SQLite', value: 'sqlite'},
|
||||
]}>
|
||||
<TabItem value="mysql">
|
||||
|
||||
```sql
|
||||
UPDATE `t` SET `c` = CASE
|
||||
WHEN
|
||||
(JSON_TYPE(JSON_EXTRACT(`c`, '$.a')) IS NULL
|
||||
OR JSON_TYPE(JSON_EXTRACT(`c`, '$.a')) = 'NULL')
|
||||
THEN
|
||||
JSON_SET(`c`, '$.a', JSON_ARRAY('new_val'))
|
||||
ELSE
|
||||
JSON_ARRAY_APPEND(`c`, '$.a', 'new_val')
|
||||
END
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="pgsql">
|
||||
|
||||
```sql
|
||||
UPDATE "t" SET "c" = CASE
|
||||
WHEN
|
||||
(("c"->'a')::jsonb IS NULL
|
||||
OR ("c"->'a')::jsonb = 'null'::jsonb)
|
||||
THEN
|
||||
jsonb_set("c", '{a}', 'new_val', true)
|
||||
ELSE
|
||||
jsonb_set("c", '{a}', "c"->'a' || 'new_val', true)
|
||||
END
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sqlite">
|
||||
|
||||
```sql
|
||||
UPDATE `t` SET `c` = CASE
|
||||
WHEN
|
||||
(JSON_TYPE(`c`, '$') IS NULL
|
||||
OR JSON_TYPE(`c`, '$') = 'null')
|
||||
THEN
|
||||
JSON_ARRAY(?)
|
||||
ELSE
|
||||
JSON_INSERT(`c`, '$[#]', ?)
|
||||
END
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Appending values to JSON fields with Ent
|
||||
|
||||
Ent recently added support for atomically appending values to fields in JSON
|
||||
columns. Let's see how it can be used.
|
||||
|
||||
If the backing type of the JSON field is a slice, such as:
|
||||
```go
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
// highlight-start
|
||||
field.JSON("tags", []string{}),
|
||||
// highlight-end
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Ent will generate a method `AppendTags` on the update mutation builders.
|
||||
You can use them like so:
|
||||
```go
|
||||
func TestAppend(t *testing.T) {
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
ctx := context.Background()
|
||||
// Insert a user with two tags.
|
||||
u := client.User.Create().
|
||||
SetTags([]string{"hello", "world"}).
|
||||
SaveX(ctx)
|
||||
|
||||
// highlight-start
|
||||
u.Update().AppendTags([]string{"goodbye"}).ExecX(ctx)
|
||||
// highlight-end
|
||||
|
||||
again := client.User.GetX(ctx, u.ID)
|
||||
fmt.Println(again.Tags)
|
||||
// Prints: [hello world goodbye]
|
||||
}
|
||||
```
|
||||
If the backing type of the JSON field is a struct containing a list, such as:
|
||||
|
||||
```go
|
||||
type Meta struct {
|
||||
Tags []string `json:"tags"'`
|
||||
}
|
||||
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.JSON("meta", &Meta{}),
|
||||
}
|
||||
}
|
||||
```
|
||||
You can use the custom [sql/modifier](https://entgo.io/docs/feature-flags/#custom-sql-modifiers)
|
||||
option to have Ent generate the `Modify` method which you can use this way:
|
||||
```go
|
||||
func TestAppendSubfield(t *testing.T) {
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
ctx := context.Background()
|
||||
// Insert a user with two tags.
|
||||
u := client.User.Create().
|
||||
SetMeta(&schema.Meta{
|
||||
Tags: []string{"hello", "world"},
|
||||
}).
|
||||
SaveX(ctx)
|
||||
|
||||
// highlight-start
|
||||
u.Update().
|
||||
Modify(func(u *sql.UpdateBuilder) {
|
||||
sqljson.Append(u, user.FieldMeta, []string{"goodbye"}, sqljson.Path("tags"))
|
||||
}).
|
||||
ExecX(ctx)
|
||||
// highlight-end
|
||||
|
||||
again := client.User.GetX(ctx, u.ID)
|
||||
fmt.Println(again.Meta.Tags)
|
||||
// Prints: [hello world goodbye]
|
||||
}
|
||||
```
|
||||
|
||||
### Wrapping up
|
||||
|
||||
In this post we discussed JSON fields in SQL and Ent in general. Next,
|
||||
we discussed how appending values to a JSON field can be done atomically
|
||||
in popular SQL databases. Finally, we showed how to do this using Ent.
|
||||
Do you think Remove/Slice operations are necessary? Let us know what you think!
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
:::
|
||||
|
||||
@@ -0,0 +1,247 @@
|
||||
---
|
||||
title: Changing a column’s type with zero-downtime using Atlas
|
||||
author: Ronen Lubin (ronenlu)
|
||||
authorURL: "https://github.com/ronenlu"
|
||||
authorImageURL: "https://avatars.githubusercontent.com/u/63970571?v=4"
|
||||
---
|
||||
Changing a column's type in a database schema might seem trivial at first glance, but it is actually a risky operation
|
||||
that can cause compatibility issues between the server and the database. In this blogpost,
|
||||
I will explore how developers can perform this type of change without causing downtime to their application.
|
||||
|
||||
Recently, while working on a feature for [Ariga Cloud](https://atlasgo.io/cloud/getting-started),
|
||||
I was required to change the type of an Ent field from an unstructured blob to a structured JSON field.
|
||||
Changing the column type was necessary in order to use [JSON Predicates](https://entgo.io/docs/predicates/#json-predicates)
|
||||
for more efficient queries.
|
||||
|
||||
The original schema looked like this on our cloud product’s schema visualization diagram:
|
||||
|
||||

|
||||
|
||||
In our case, we couldn't just copy the data naively to the new column, since the data is not compatible
|
||||
with the new column type (blob data may not be convertible to JSON).
|
||||
|
||||
In the past, it was considered acceptable to stop the server, migrate the database schema to the next version,
|
||||
and only then start the server with the new version that is compatible with the new database schema.
|
||||
Today, business requirements often dictate that applications must provide higher availability, leaving engineering teams
|
||||
with the challenge of executing changes like this with zero-downtime.
|
||||
|
||||
The common pattern to satisfy this kind of requirement, as defined in "[Evolutionary Database Design](https://www.martinfowler.com/articles/evodb.html)" by Martin Fowler,
|
||||
is to use a "transition phase".
|
||||
> A transition phase is "a period of time when the database supports both the old access pattern and the new ones simultaneously.
|
||||
This allows older systems time to migrate over to the new structures at their own pace", as illustrated by this diagram:
|
||||
|
||||
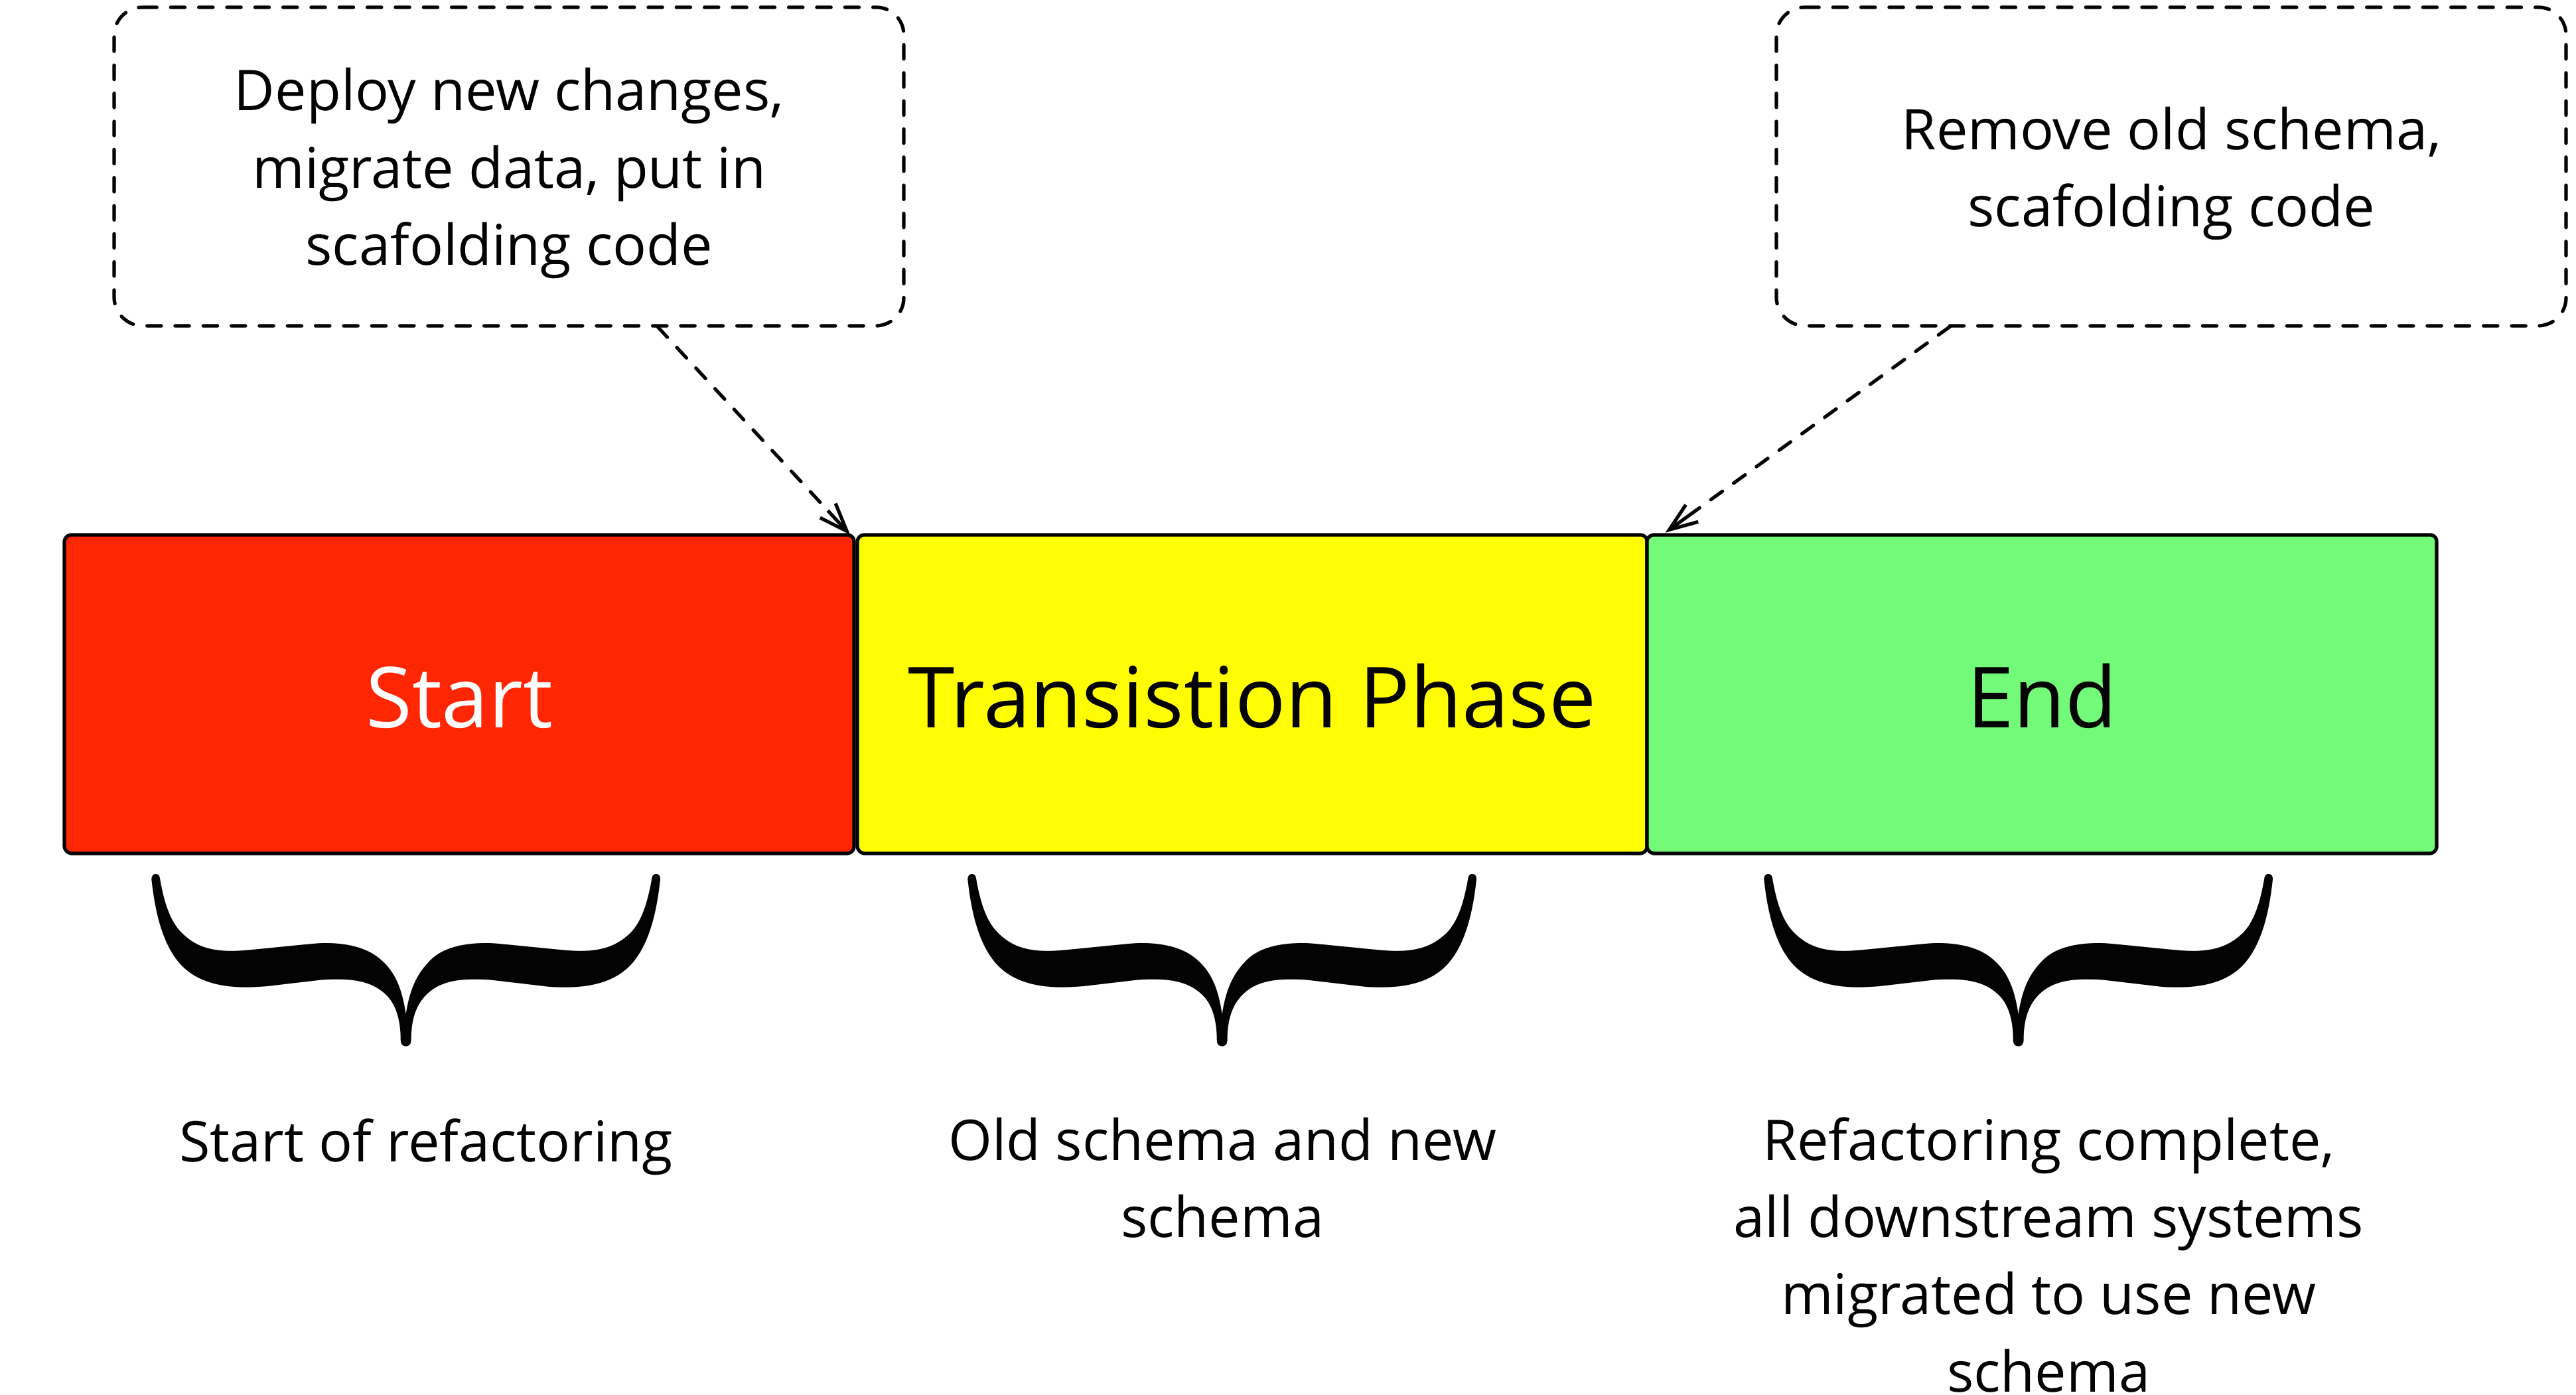
|
||||
Credit: martinfowler.com
|
||||
|
||||
We planned the change in 5 simple steps, all of which are backward-compatible:
|
||||
* Creating a new column named `meta_json` with the JSON type.
|
||||
* Deploy a version of the application that performs dual-writes. Every new record or update is written to both the new column and the old column, while reads still happen from the old column.
|
||||
* Backfill data from the old column to the new one.
|
||||
* Deploy a version of the application that reads from the new column.
|
||||
* Delete the old column.
|
||||
|
||||
### Versioned migrations
|
||||
In our project we are using Ent’s [versioned migrations](https://entgo.io/docs/versioned-migrations) workflow for
|
||||
managing the database schema. Versioned migrations provide teams with granular control on how changes to the application database schema are made.
|
||||
This level of control will be very useful in implementing our plan. If your project uses [Automatic Migrations](https://entgo.io/docs/migrate) and you would like to follow along,
|
||||
[first upgrade](https://entgo.io/docs/versioned/intro) your project to use versioned migrations.
|
||||
|
||||
:::note
|
||||
The same can be done with automatic migrations as well by using the [Data Migrations](https://entgo.io/docs/data-migrations/#automatic-migrations) feature,
|
||||
however this post is focusing on versioned migrations
|
||||
:::
|
||||
|
||||
### Creating a JSON column with Ent:
|
||||
First, we will add a new JSON Ent type to the user schema.
|
||||
|
||||
``` go title="types/types.go"
|
||||
type Meta struct {
|
||||
CreateTime time.Time `json:"create_time"`
|
||||
UpdateTime time.Time `json:"update_time"`
|
||||
}
|
||||
```
|
||||
``` go title="ent/schema/user.go"
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Bytes("meta"),
|
||||
field.JSON("meta_json", &types.Meta{}).Optional(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Next, we run codegen to update the application schema:
|
||||
``` shell
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Next, we run our [automatic migration planning](https://entgo.io/docs/versioned/auto-plan) script that generates a set of
|
||||
migration files containing the necessary SQL statements to migrate the database to the newest version.
|
||||
``` shell
|
||||
go run -mod=mod ent/migrate/main.go add_json_meta_column
|
||||
```
|
||||
|
||||
The resulted migration file describing the change:
|
||||
``` sql
|
||||
-- modify "users" table
|
||||
ALTER TABLE `users` ADD COLUMN `meta_json` json NULL;
|
||||
```
|
||||
|
||||
Now, we will apply the created migration file using [Atlas](https://atlasgo.io):
|
||||
``` shell
|
||||
atlas migrate apply \
|
||||
--dir "file://ent/migrate/migrations"
|
||||
--url mysql://root:pass@localhost:3306/ent
|
||||
```
|
||||
|
||||
As a result, we have the following schema in our database:
|
||||
|
||||

|
||||
|
||||
### Start writing to both columns
|
||||
|
||||
After generating the JSON type, we will start writing to the new column:
|
||||
``` diff
|
||||
- err := client.User.Create().
|
||||
- SetMeta(input.Meta).
|
||||
- Exec(ctx)
|
||||
+ var meta types.Meta
|
||||
+ if err := json.Unmarshal(input.Meta, &meta); err != nil {
|
||||
+ return nil, err
|
||||
+ }
|
||||
+ err := client.User.Create().
|
||||
+ SetMetaJSON(&meta).
|
||||
+ Exec(ctx)
|
||||
```
|
||||
|
||||
To ensure that values written to the new column `meta_json` are replicated to the old column, we can utilize Ent’s
|
||||
[Schema Hooks](https://entgo.io/docs/hooks/#schema-hooks) feature. This adds blank import `ent/runtime` in your main to
|
||||
[register the hook](https://entgo.io/docs/hooks/#hooks-registration) and avoid circular import:
|
||||
``` go
|
||||
// Hooks of the User.
|
||||
func (User) Hooks() []ent.Hook {
|
||||
return []ent.Hook{
|
||||
hook.On(
|
||||
func(next ent.Mutator) ent.Mutator {
|
||||
return hook.UserFunc(func(ctx context.Context, m *gen.UserMutation) (ent.Value, error) {
|
||||
meta, ok := m.MetaJSON()
|
||||
if !ok {
|
||||
return next.Mutate(ctx, m)
|
||||
}
|
||||
if b, err := json.Marshal(meta); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
m.SetMeta(b)
|
||||
return next.Mutate(ctx, m)
|
||||
})
|
||||
},
|
||||
ent.OpCreate,
|
||||
),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
After ensuring writes to both fields we can safely deploy to production.
|
||||
|
||||
### Backfill values from old column
|
||||
|
||||
Now in our production database we have two columns: one storing the meta object as a blob and another storing it as a JSON.
|
||||
The second column may have null values since the JSON column was only added recently, therefore we need to backfill it with the old column’s values.
|
||||
|
||||
To do so, we manually create a SQL migration file that will fill values in the new JSON column from the old blob column.
|
||||
|
||||
:::note
|
||||
You can also write Go code that generates this data migration file by using the [WriteDriver](https://entgo.io/docs/data-migrations#versioned-migrations).
|
||||
:::
|
||||
|
||||
Create a new empty migration file:
|
||||
``` shell
|
||||
atlas migrate new --dir file://ent/migrate/migrations
|
||||
```
|
||||
|
||||
For every row in the users table with a null JSON value (i.e: rows added before the creation of the new column), we try
|
||||
to parse the meta object into a valid JSON. If we succeed, we will fill the `meta_json` column with the resulting value, otherwise we will mark it empty.
|
||||
|
||||
Our next step is to edit the migration file:
|
||||
``` sql
|
||||
UPDATE users
|
||||
SET meta_json = CASE
|
||||
-- when meta is valid json stores it as is.
|
||||
WHEN JSON_VALID(cast(meta as char)) = 1 THEN cast(cast(meta as char) as json)
|
||||
-- if meta is not valid json, store it as an empty object.
|
||||
ELSE JSON_SET('{}')
|
||||
END
|
||||
WHERE meta_json is null;
|
||||
```
|
||||
|
||||
Rehash the migration directory after changing a migration file:
|
||||
``` shell
|
||||
atlas migrate hash --dir "file://ent/mirate/migrations"
|
||||
```
|
||||
|
||||
We can test the migration file by executing all the previous migration files on a local database, seed it with temporary data, and
|
||||
apply the last migration to ensure our migration file works as expected.
|
||||
|
||||
After testing we apply the migration file:
|
||||
``` shell
|
||||
atlas migrate apply \
|
||||
--dir "file://ent/migrate/migrations"
|
||||
--url mysql://root:pass@localhost:3306/ent
|
||||
```
|
||||
|
||||
Now, we will deploy to production once more.
|
||||
|
||||
### Redirect reads to the new column and delete old blob column
|
||||
|
||||
Now that we have values in the `meta_json` column, we can change the reads from the old field to the new field.
|
||||
|
||||
Instead of decoding the data from `user.meta` on each read, just use the `meta_json` field:
|
||||
``` diff
|
||||
- var meta types.Meta
|
||||
- if err = json.Unmarshal(user.Meta, &meta); err != nil {
|
||||
- return nil, err
|
||||
- }
|
||||
- if meta.CreateTime.Before(time.Unix(0, 0)) {
|
||||
- return nil, errors.New("invalid create time")
|
||||
- }
|
||||
+ if user.MetaJSON.CreateTime.Before(time.Unix(0, 0)) {
|
||||
+ return nil, errors.New("invalid create time")
|
||||
+ }
|
||||
```
|
||||
|
||||
After redirecting the reads we will deploy the changes to production.
|
||||
|
||||
### Delete the old column
|
||||
|
||||
It is now possible to remove the field describing the old column from the Ent schema, since as we are no longer using it.
|
||||
``` diff
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
- field.Bytes("meta"),
|
||||
field.JSON("meta_json", &types.Meta{}).Optional(),
|
||||
}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
Generate the Ent schema again with the [Drop Column](https://entgo.io/docs/migrate/#drop-resources) feature enabled.
|
||||
``` shell
|
||||
go run -mod=mod ent/migrate/main.go drop_user_meta_column
|
||||
```
|
||||
|
||||
Now that we have properly created our new field, redirected writes, backfilled it and dropped the old column -
|
||||
we are ready for the final deployment. All that’s left is to merge our code into version control and deploy to production!
|
||||
|
||||
### Wrapping up
|
||||
|
||||
In this post, we discussed how to change a column type in the production database with zero downtime using Atlas’s version migrations integrated with Ent.
|
||||
|
||||
Have questions? Need help with getting started? Feel free to join
|
||||
our [Ent Discord Server](https://discord.gg/qZmPgTE6RX).
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
:::
|
||||
106
doc/website/blog/2023-01-26-visualizing-with-entviz.md
Normal file
106
doc/website/blog/2023-01-26-visualizing-with-entviz.md
Normal file
@@ -0,0 +1,106 @@
|
||||
---
|
||||
title: Quickly visualize your Ent schemas with entviz
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
image: "https://entgo.io/images/assets/entviz-v2.png"
|
||||
---
|
||||
|
||||
### TL;DR
|
||||
|
||||
To get a public link to a visualization of your Ent schema, run:
|
||||
|
||||
```
|
||||
go run -mod=mod ariga.io/entviz ./path/to/ent/schema
|
||||
```
|
||||
|
||||

|
||||
|
||||
### Visualizing Ent schemas
|
||||
|
||||
Ent enables developers to build complex application data models
|
||||
using [graph semantics](https://en.wikipedia.org/wiki/Graph_theory): instead of defining tables, columns, association
|
||||
tables and foreign keys, Ent models are simply defined in terms of [Nodes](https://entgo.io/docs/schema-fields)
|
||||
and [Edges](https://entgo.io/docs/schema-edges):
|
||||
|
||||
```go
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/edge"
|
||||
)
|
||||
|
||||
// User schema.
|
||||
type User struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the user.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
// ...
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the user.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("pets", Pet.Type),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Modeling data this way has many benefits such as being able to
|
||||
easily [traverse](https://entgo.io/docs/traversals) an application's data graph in an intuitive API, automatically
|
||||
generating [GraphQL](https://entgo.io/docs/tutorial-todo-gql) servers and more.
|
||||
|
||||
While Ent can use a Graph database as its storage layer, most Ent users use common relational databases such as MySQL,
|
||||
PostgreSQL or MariaDB for their applications. In these use-cases, developers often ponder, *what actual database schema
|
||||
will Ent create from my application's schema?*
|
||||
|
||||
Whether you're a new Ent user learning the basics of creating Ent schemas or an expert dealing with optimizing the
|
||||
resulting database schema for performance reasons, being able to easily visualize your Ent schema's backing database
|
||||
schema can be very useful.
|
||||
|
||||
#### Introducing the new `entviz`
|
||||
|
||||
A year and a half ago
|
||||
we [shared an Ent extension named entviz](https://entgo.io/blog/2021/08/26/visualizing-your-data-graph-using-entviz),
|
||||
that extension enabled users to generate simple, local HTML documents containing entity-relationship diagrams describing
|
||||
an application's Ent schema.
|
||||
|
||||
Today, we're happy to share a [super cool tool](https://github.com/ariga/entviz) by the same name created
|
||||
by [Pedro Henrique (crossworth)](https://github.com/crossworth) which is a completely fresh take on the same problem.
|
||||
With (the new) entviz you run a simple Go command:
|
||||
|
||||
```
|
||||
go run -mod=mod ariga.io/entviz ./path/to/ent/schema
|
||||
```
|
||||
|
||||
The tool will analyze your Ent schema and create a visualization on the [Atlas Playground](https://gh.atlasgo.cloud) and
|
||||
create a shareable, public [link](https://gh.atlasgo.cloud/explore/saved/60129542154) for you:
|
||||
|
||||
```
|
||||
Here is a public link to your schema visualization:
|
||||
https://gh.atlasgo.cloud/explore/saved/60129542154
|
||||
```
|
||||
|
||||
In this link you will be able to see your schema visually as an ERD or textually as either a SQL
|
||||
or [Atlas HCL](https://atlasgo.io/atlas-schema/sql-resources) document.
|
||||
|
||||
### Wrapping up
|
||||
|
||||
In this blog post we discussed some scenarios where you might find it useful to quickly get a visualization of your Ent
|
||||
application's schema, we then showed how creating such visualizations can be achieved
|
||||
using [entviz](https://github.com/ariga/entviz). If you like the idea, we'd be super happy if you tried it today and
|
||||
gave us feedback!
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
:::
|
||||
849
doc/website/blog/2023-02-23-simple-cms-with-ent.mdx
Normal file
849
doc/website/blog/2023-02-23-simple-cms-with-ent.mdx
Normal file
@@ -0,0 +1,849 @@
|
||||
---
|
||||
title: A beginner's guide to creating a web-app in Go using Ent
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
image: "https://entgo.io/images/assets/cms-blog/share.png"
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
[Ent](https://entgo.io) is an open-source entity framework for Go. It is similar to more traditional ORMs, but has a
|
||||
few distinct features that have made it very popular in the Go community. Ent was first open-sourced by
|
||||
[Ariel](https://github.com/a8m) in 2019, when he was working at Facebook. Ent grew from the pains of managing the
|
||||
development of applications with very large and complex data models and ran successfully inside Facebook for a year
|
||||
before open-sourcing it. After graduating from Facebook Open Source, Ent joined the Linux Foundation in September 2021.
|
||||
|
||||
This tutorial is intended for Ent and Go novices who want to start by building a simple project: a very minimal content management system.
|
||||
|
||||
Over the last few years, Ent has become one of the fastest growing ORMs in Go:
|
||||
|
||||

|
||||
<div style={{textAlign: 'center'}}>
|
||||
|
||||
*Source: [@ossinsight_bot on Twitter](https://twitter.com/ossinsight_bot/status/1593182222626213888), November 2022*
|
||||
|
||||
</div>
|
||||
|
||||
Some of Ent's most cited features are:
|
||||
|
||||
* **A type-safe Go API for working with your database.** Forget about using `interface{}` or reflection to work with
|
||||
your database. Use pure Go that your editor understands and your compiler enforces.
|
||||

|
||||
* **Model your data in graph semantics** - Ent uses graph semantics to model your application's data. This makes it very easy to traverse complex datasets in a simple API.
|
||||
|
||||
Let’s say we want to get all users that are in groups that are about dogs. Here are two ways to write something like this with Ent:
|
||||
|
||||
```go
|
||||
// Start traversing from the topic.
|
||||
client.Topic.Query().
|
||||
Where(topic.Name("dogs")).
|
||||
QueryGroups().
|
||||
QueryUsers().
|
||||
All(ctx)
|
||||
|
||||
// OR: Start traversing from the users and filter.
|
||||
client.User.Query().
|
||||
Where(
|
||||
user.HasGroupsWith(
|
||||
group.HasTopicsWith(
|
||||
topic.Name("dogs"),
|
||||
),
|
||||
),
|
||||
).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
|
||||
* **Automatically generate servers** - whether you need GraphQL, gRPC or an OpenAPI compliant API layer, Ent can
|
||||
generate the necessary code you need to create a performant server on top of your database. Ent will generate
|
||||
both the third-party schemas (GraphQL types, Protobuf messages, etc.) and optimized code for the repetitive
|
||||
tasks for reading and writing from the database.
|
||||
* **Bundled with Atlas** - Ent is built with a rich integration with [Atlas](https://atlasgo.io), a robust schema
|
||||
management tool with many advanced capabilities. Atlas can automatically plan schema migrations for you as
|
||||
well as verify them in CI or deploy them to production for you. (Full disclosure: Ariel and I are the creators and maintainers)
|
||||
|
||||
#### Prerequisites
|
||||
* [Install Go](https://go.dev/doc/install)
|
||||
* [Install Docker](https://docs.docker.com/get-docker/)
|
||||
|
||||
:::info Supporting repo
|
||||
|
||||
You can find of the code shown in this tutorial in [this repo](https://github.com/rotemtam/ent-blog-example).
|
||||
|
||||
:::
|
||||
|
||||
### Step 1: Setting up the database schema
|
||||
|
||||
You can find the code described in this step in [this commit](https://github.com/rotemtam/ent-blog-example/commit/d4e4916231f05aa9a4b9ce93e75afdb72ab25799).
|
||||
|
||||
Let's start by initializing our project using `go mod init`:
|
||||
```
|
||||
go mod init github.com/rotemtam/ent-blog-example
|
||||
```
|
||||
|
||||
Go confirms our new module was created:
|
||||
```
|
||||
go: creating new go.mod: module github.com/rotemtam/ent-blog-example
|
||||
```
|
||||
|
||||
The first thing we will handle in our demo project will be to setup our database. We create our application data model using Ent. Let's fetch it using `go get`:
|
||||
|
||||
```
|
||||
go get -u entgo.io/ent@master
|
||||
```
|
||||
|
||||
Once installed, we can use the Ent CLI to initialize the models for the two types of entities we will be dealing with in this tutorial: the `User` and the `Post`.
|
||||
```
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new User Post
|
||||
```
|
||||
|
||||
Notice that a few files are created:
|
||||
|
||||
```
|
||||
.
|
||||
`-- ent
|
||||
|-- generate.go
|
||||
`-- schema
|
||||
|-- post.go
|
||||
`-- user.go
|
||||
|
||||
2 directories, 3 files
|
||||
```
|
||||
|
||||
Ent created the basic structure for our project:
|
||||
* `generate.go` - we will see in a bit how this file is used to invoke Ent's code-generation engine.
|
||||
* The `schema` directory, with a bare `ent.Schema` for each of the entities we requested.
|
||||
|
||||
Let's continue by defining the schema for our entities. This is the schema definition for `User`:
|
||||
```go
|
||||
// Fields of the User.
|
||||
func (User) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("name"),
|
||||
field.String("email").
|
||||
Unique(),
|
||||
field.Time("created_at").
|
||||
Default(time.Now),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the User.
|
||||
func (User) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("posts", Post.Type),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Observe that we defined three fields, `name`, `email` and `created_at` (which takes the default value of `time.Now()`).
|
||||
Since we expect emails to be unique in our system we added that constraint on the `email` field. In addition, we
|
||||
defined an edge named `posts` to the `Post` type. Edges are used in Ent to define relationships between entities.
|
||||
When working with a relational database, edges are translated into foreign keys and association tables.
|
||||
|
||||
```go
|
||||
// Post holds the schema definition for the Post entity.
|
||||
type Post struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Post.
|
||||
func (Post) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("title"),
|
||||
field.Text("body"),
|
||||
field.Time("created_at").
|
||||
Default(time.Now),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Post.
|
||||
func (Post) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("author", User.Type).
|
||||
Unique().
|
||||
Ref("posts"),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
On the `Post` schema, we defined three fields as well: `title`, `body` and `created_at`. In addition, we defined an edge named `author` from `Post` to the `User` entity. We marked this edge as `Unique` because in our budding system, each post can have only one author. We used `Ref` to tell Ent that this edge's back reference is the `posts` edge on the `User`.
|
||||
|
||||
Ent's power stems from it's code-generation engine. When developing with Ent, whenever we make any change to our application schema, we must invoke Ent's code-gen engine to regenerate our database access code. This is what allows Ent to maintain a type-safe and efficient Go API for us.
|
||||
|
||||
Let's see this in action, run:
|
||||
```
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Observe that a whole *lot* of new Go files were created for us:
|
||||
|
||||
```
|
||||
.
|
||||
`-- ent
|
||||
|-- client.go
|
||||
|-- context.go
|
||||
|-- ent.go
|
||||
|-- enttest
|
||||
| `-- enttest.go
|
||||
/// .. Truncated for brevity
|
||||
|-- user_query.go
|
||||
`-- user_update.go
|
||||
|
||||
9 directories, 29 files
|
||||
```
|
||||
|
||||
:::info
|
||||
If you're interested to see what the actual database schema for our application looks like, you can use a useful tool called `entviz`:
|
||||
```
|
||||
go run -mod=mod ariga.io/entviz ./ent/schema
|
||||
```
|
||||
To view the result, [click here](https://gh.atlasgo.cloud/explore/a0e79415).
|
||||
:::
|
||||
|
||||
Once we have our data model defined, let's create the database schema for it.
|
||||
|
||||
|
||||
To install the latest release of Atlas, simply run one of the following commands in your terminal, or check out the
|
||||
[Atlas website](https://atlasgo.io/getting-started#installation):
|
||||
|
||||
<Tabs
|
||||
defaultValue="apple-intel-plain+linux"
|
||||
values={[
|
||||
{label: 'macOS + Linux', value: 'apple-intel-plain+linux'},
|
||||
{label: 'Homebrew', value: 'apple-intel-brew'},
|
||||
{label: 'Go', value: 'go'},
|
||||
{label: 'Docker', value: 'docker'},
|
||||
{label: 'Windows', value: 'windows'},
|
||||
]}>
|
||||
<TabItem value="apple-intel-plain+linux">
|
||||
|
||||
```shell
|
||||
curl -sSf https://atlasgo.sh | sh
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="apple-intel-brew">
|
||||
|
||||
```shell
|
||||
brew install ariga/tap/atlas
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="go">
|
||||
|
||||
```shell
|
||||
go install ariga.io/atlas/cmd/atlas@master
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="docker">
|
||||
|
||||
```shell
|
||||
docker pull arigaio/atlas
|
||||
docker run --rm arigaio/atlas --help
|
||||
```
|
||||
|
||||
If the container needs access to the host network or a local directory, use the `--net=host` flag and mount the desired
|
||||
directory:
|
||||
|
||||
```shell
|
||||
docker run --rm --net=host \
|
||||
-v $(pwd)/migrations:/migrations \
|
||||
arigaio/atlas migrate apply
|
||||
--url "mysql://root:pass@:3306/test"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="windows">
|
||||
|
||||
Download the [latest release](https://release.ariga.io/atlas/atlas-windows-amd64-latest.exe) and
|
||||
move the atlas binary to a file location on your system PATH.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
With Atlas installed, we can create the initial migration script:
|
||||
```
|
||||
atlas migrate diff add_users_posts \
|
||||
--dir "file://ent/migrate/migrations" \
|
||||
--to "ent://ent/schema" \
|
||||
--dev-url "docker://mysql/8/ent"
|
||||
```
|
||||
Observe that two new files were created:
|
||||
```
|
||||
ent/migrate/migrations
|
||||
|-- 20230226150934_add_users_posts.sql
|
||||
`-- atlas.sum
|
||||
```
|
||||
|
||||
The SQL file (the actual file name will vary on your machine depending on the timestamp in which you run `atlas migrate diff`) contains the SQL DDL statements required to set up the database schema on an empty MySQL database:
|
||||
```sql
|
||||
-- create "users" table
|
||||
CREATE TABLE `users` (`id` bigint NOT NULL AUTO_INCREMENT, `name` varchar(255) NOT NULL, `email` varchar(255) NOT NULL, `created_at` timestamp NOT NULL, PRIMARY KEY (`id`), UNIQUE INDEX `email` (`email`)) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
-- create "posts" table
|
||||
CREATE TABLE `posts` (`id` bigint NOT NULL AUTO_INCREMENT, `title` varchar(255) NOT NULL, `body` longtext NOT NULL, `created_at` timestamp NOT NULL, `user_posts` bigint NULL, PRIMARY KEY (`id`), INDEX `posts_users_posts` (`user_posts`), CONSTRAINT `posts_users_posts` FOREIGN KEY (`user_posts`) REFERENCES `users` (`id`) ON UPDATE NO ACTION ON DELETE SET NULL) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
```
|
||||
|
||||
To setup our development environment, let's use Docker to run a local `mysql` container:
|
||||
```
|
||||
docker run --rm --name entdb -d -p 3306:3306 -e MYSQL_DATABASE=ent -e MYSQL_ROOT_PASSWORD=pass mysql:8
|
||||
```
|
||||
|
||||
Finally, let's run the migration script on our local database:
|
||||
```
|
||||
atlas migrate apply --dir file://ent/migrate/migrations \
|
||||
--url mysql://root:pass@localhost:3306/ent
|
||||
```
|
||||
Atlas reports that it successfully created the tables:
|
||||
```
|
||||
Migrating to version 20230220115943 (1 migrations in total):
|
||||
|
||||
-- migrating version 20230220115943
|
||||
-> CREATE TABLE `users` (`id` bigint NOT NULL AUTO_INCREMENT, `name` varchar(255) NOT NULL, `email` varchar(255) NOT NULL, `created_at` timestamp NOT NULL, PRIMARY KEY (`id`), UNIQUE INDEX `email` (`email`)) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
-> CREATE TABLE `posts` (`id` bigint NOT NULL AUTO_INCREMENT, `title` varchar(255) NOT NULL, `body` longtext NOT NULL, `created_at` timestamp NOT NULL, `post_author` bigint NULL, PRIMARY KEY (`id`), INDEX `posts_users_author` (`post_author`), CONSTRAINT `posts_users_author` FOREIGN KEY (`post_author`) REFERENCES `users` (`id`) ON UPDATE NO ACTION ON DELETE SET NULL) CHARSET utf8mb4 COLLATE utf8mb4_bin;
|
||||
-- ok (55.972329ms)
|
||||
|
||||
-------------------------
|
||||
-- 67.18167ms
|
||||
-- 1 migrations
|
||||
-- 2 sql statements
|
||||
|
||||
```
|
||||
|
||||
### Step 2: Seeding our database
|
||||
|
||||
:::info
|
||||
|
||||
The code for this step can be found in [this commit](https://github.com/rotemtam/ent-blog-example/commit/eae0c881a4edfbe04e6aa074d4c165e8ff3656b1).
|
||||
|
||||
:::
|
||||
|
||||
While we are developing our content management system, it would be sad to load a web page for our system and not see content for it. Let's start by seeding data into our database and learn some Ent concepts.
|
||||
|
||||
To access our local MySQL database, we need a driver for it, use `go get` to fetch it:
|
||||
```
|
||||
go get -u github.com/go-sql-driver/mysql
|
||||
```
|
||||
|
||||
Create a file named `main.go` and add this basic seeding script.
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"flag"
|
||||
"fmt"
|
||||
"log"
|
||||
|
||||
"github.com/rotemtam/ent-blog-example/ent"
|
||||
|
||||
_ "github.com/go-sql-driver/mysql"
|
||||
"github.com/rotemtam/ent-blog-example/ent/user"
|
||||
)
|
||||
|
||||
func main() {
|
||||
// Read the connection string to the database from a CLI flag.
|
||||
var dsn string
|
||||
flag.StringVar(&dsn, "dsn", "", "database DSN")
|
||||
flag.Parse()
|
||||
|
||||
// Instantiate the Ent client.
|
||||
client, err := ent.Open("mysql", dsn)
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
|
||||
ctx := context.Background()
|
||||
// If we don't have any posts yet, seed the database.
|
||||
if !client.Post.Query().ExistX(ctx) {
|
||||
if err := seed(ctx, client); err != nil {
|
||||
log.Fatalf("failed seeding the database: %v", err)
|
||||
}
|
||||
}
|
||||
// ... Continue with server start.
|
||||
}
|
||||
|
||||
func seed(ctx context.Context, client *ent.Client) error {
|
||||
// Check if the user "rotemtam" already exists.
|
||||
r, err := client.User.Query().
|
||||
Where(
|
||||
user.Name("rotemtam"),
|
||||
).
|
||||
Only(ctx)
|
||||
switch {
|
||||
// If not, create the user.
|
||||
case ent.IsNotFound(err):
|
||||
r, err = client.User.Create().
|
||||
SetName("rotemtam").
|
||||
SetEmail("r@hello.world").
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed creating user: %v", err)
|
||||
}
|
||||
case err != nil:
|
||||
return fmt.Errorf("failed querying user: %v", err)
|
||||
}
|
||||
// Finally, create a "Hello, world" blogpost.
|
||||
return client.Post.Create().
|
||||
SetTitle("Hello, World!").
|
||||
SetBody("This is my first post").
|
||||
SetAuthor(r).
|
||||
Exec(ctx)
|
||||
}
|
||||
```
|
||||
|
||||
As you can see, this program first checks if any `Post` entity exists in the database, if it does not it invokes the `seed` function. This function uses Ent to retrieve the user named `rotemtam` from the database and in case it does not exist, tries to create it. Finally, the function creates a blog post with this user as its author.
|
||||
|
||||
Run it:
|
||||
```
|
||||
go run main.go -dsn "root:pass@tcp(localhost:3306)/ent?parseTime=true"
|
||||
```
|
||||
|
||||
### Step 3: Creating the home page
|
||||
|
||||
:::info
|
||||
The code described in this step can be found in [this commit](https://github.com/rotemtam/ent-blog-example/commit/8196bb50400bbaed53d5a722e987fcd50ea1628f)
|
||||
:::
|
||||
|
||||
Let's now create the home page of the blog. This will consist of a few parts:
|
||||
1. **The view** - this is a Go html/template that renders the actual HTML the user will see.
|
||||
2. **The server code** - this contains the HTTP request handlers that our users' browsers will communicate with and will render our templates with data they retrieve from the database.
|
||||
3. **The router** - registers different paths to handlers.
|
||||
4. **A unit test** - to verify our server behaves correctly.
|
||||
|
||||
#### The view
|
||||
|
||||
Go has an excellent templating engine that comes in two flavors: `text/template` for rendering general purpose text and `html/template` which had some extra security features to prevent code injection when working with HTML documents. Read more about it [here](https://pkg.go.dev/html/template) .
|
||||
|
||||
Let's create our first template that will be used to display a list of blog posts. Create a new file named `templates/list.tmpl`:
|
||||
|
||||
```gotemplate
|
||||
<html>
|
||||
<head>
|
||||
<title>My Blog</title>
|
||||
<link href="https://cdn.jsdelivr.net/npm/bootstrap@5.3.0-alpha1/dist/css/bootstrap.min.css" rel="stylesheet"
|
||||
integrity="sha384-GLhlTQ8iRABdZLl6O3oVMWSktQOp6b7In1Zl3/Jr59b6EGGoI1aFkw7cmDA6j6gD" crossorigin="anonymous">
|
||||
|
||||
</head>
|
||||
<body>
|
||||
<div class="col-lg-8 mx-auto p-4 py-md-5">
|
||||
<header class="d-flex align-items-center pb-3 mb-5 border-bottom">
|
||||
<a href="/" class="d-flex align-items-center text-dark text-decoration-none">
|
||||
<span class="fs-4">Ent Blog Demo</span>
|
||||
</a>
|
||||
</header>
|
||||
|
||||
<main>
|
||||
<div class="row g-5">
|
||||
<div class="col-md-12">
|
||||
{{- range . }}
|
||||
<h2>{{ .Title }}</h2>
|
||||
<p>
|
||||
{{ .CreatedAt.Format "2006-01-02" }} by {{ .Edges.Author.Name }}
|
||||
</p>
|
||||
<p>
|
||||
{{ .Body }}
|
||||
</p>
|
||||
{{- end }}
|
||||
</div>
|
||||
|
||||
</div>
|
||||
</main>
|
||||
<footer class="pt-5 my-5 text-muted border-top">
|
||||
<p>
|
||||
This is the Ent Blog Demo. It is a simple blog application built with Ent and Go. Get started:
|
||||
</p>
|
||||
<pre>go get entgo.io/ent</pre>
|
||||
</footer>
|
||||
</div>
|
||||
|
||||
<script src="https://cdn.jsdelivr.net/npm/bootstrap@5.3.0-alpha1/dist/js/bootstrap.bundle.min.js"
|
||||
integrity="sha384-w76AqPfDkMBDXo30jS1Sgez6pr3x5MlQ1ZAGC+nuZB+EYdgRZgiwxhTBTkF7CXvN"
|
||||
crossorigin="anonymous"></script>
|
||||
</body>
|
||||
</html>
|
||||
```
|
||||
|
||||
Here we are using a modified version of the [Bootstrap Starter Template](https://getbootstrap.com/docs/5.3/examples/starter-template/) as the basis of our UI. Let's highlight the important parts. As you will see below, in our `index` handler, we will pass this template a slice of `Post` objects.
|
||||
|
||||
Inside the Go-template, whatever we pass to it as data is available as "`.`", this explains this line, where we use `range` to iterate over each post:
|
||||
```
|
||||
{{- range . }}
|
||||
```
|
||||
Next, we print the title, creation time and the author name, via the `Author` edge:
|
||||
```
|
||||
<h2>{{ .Title }}</h2>
|
||||
<p>
|
||||
{{ .CreatedAt.Format "2006-01-02" }} by {{ .Edges.Author.Name }}
|
||||
</p>
|
||||
```
|
||||
Finally, we print the post body and close the loop.
|
||||
```
|
||||
<p>
|
||||
{{ .Body }}
|
||||
</p>
|
||||
{{- end }}
|
||||
```
|
||||
|
||||
After defining the template, we need to make it available to our program. We embed this template into our binary using the `embed` package ([docs](https://pkg.go.dev/embed)):
|
||||
|
||||
```go
|
||||
var (
|
||||
//go:embed templates/*
|
||||
resources embed.FS
|
||||
tmpl = template.Must(template.ParseFS(resources, "templates/*"))
|
||||
)
|
||||
```
|
||||
|
||||
#### Server code
|
||||
|
||||
We continue by defining a type named `server` and a constructor for it, `newServer`. This struct will have receiver methods for each HTTP handler we create and binds the Ent client we created at init to the server code.
|
||||
```go
|
||||
type server struct {
|
||||
client *ent.Client
|
||||
}
|
||||
|
||||
func newServer(client *ent.Client) *server {
|
||||
return &server{client: client}
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
Next, let's define the handler for our blog home page. This page should contain a list of all available blog posts:
|
||||
|
||||
```go
|
||||
// index serves the blog home page
|
||||
func (s *server) index(w http.ResponseWriter, r *http.Request) {
|
||||
posts, err := s.client.Post.
|
||||
Query().
|
||||
WithAuthor().
|
||||
All(r.Context())
|
||||
if err != nil {
|
||||
http.Error(w, err.Error(), http.StatusInternalServerError)
|
||||
return
|
||||
}
|
||||
if err := tmpl.Execute(w, posts); err != nil {
|
||||
http.Error(w, err.Error(), http.StatusInternalServerError)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Let's zoom in on the Ent code here that is used to retrieve the posts from the database:
|
||||
```go
|
||||
// s.client.Post contains methods for interacting with Post entities
|
||||
s.client.Post.
|
||||
// Begin a query.
|
||||
Query().
|
||||
// Retrieve the entities using the `Author` edge. (a `User` instance)
|
||||
WithAuthor().
|
||||
// Run the query against the database using the request context.
|
||||
All(r.Context())
|
||||
```
|
||||
|
||||
#### The router
|
||||
|
||||
To manage the routes for our application, let's use `go-chi`, a popular routing library for Go.
|
||||
|
||||
```
|
||||
go get -u github.com/go-chi/chi/v5
|
||||
```
|
||||
|
||||
We define the `newRouter` function that sets up our router:
|
||||
|
||||
```go
|
||||
// newRouter creates a new router with the blog handlers mounted.
|
||||
func newRouter(srv *server) chi.Router {
|
||||
r := chi.NewRouter()
|
||||
r.Use(middleware.Logger)
|
||||
r.Use(middleware.Recoverer)
|
||||
r.Get("/", srv.index)
|
||||
return r
|
||||
}
|
||||
```
|
||||
|
||||
In this function, we first instantiate a new `chi.Router`, then register two middlewares:
|
||||
* `middleware.Logger` is a basic access logger that prints out some information on every request our server handles.
|
||||
* `middleware.Recoverer` recovers from when our handlers panic, preventing a case where our entire server will crash because of an application error.
|
||||
|
||||
Finally, we register the `index` function of the `server` struct to handle `GET` requests to the `/` path of our server.
|
||||
|
||||
#### A unit test
|
||||
|
||||
Before wiring everything together, let's write a simple unit test to check that our code works as expected.
|
||||
|
||||
To simplify our tests we will install the SQLite driver for Go which allows us to use an in-memory database:
|
||||
```
|
||||
go get -u github.com/mattn/go-sqlite3
|
||||
```
|
||||
|
||||
Next, we install `testify`, a utility library that is commonly used for writing assertions in tests.
|
||||
|
||||
```
|
||||
go get github.com/stretchr/testify
|
||||
```
|
||||
|
||||
With these dependencies installed, create a new file named `main_test.go`:
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"io"
|
||||
"net/http"
|
||||
"net/http/httptest"
|
||||
"testing"
|
||||
|
||||
_ "github.com/mattn/go-sqlite3"
|
||||
"github.com/rotemtam/ent-blog-example/ent/enttest"
|
||||
"github.com/stretchr/testify/require"
|
||||
)
|
||||
|
||||
func TestIndex(t *testing.T) {
|
||||
// Initialize an Ent client that uses an in memory SQLite db.
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
defer client.Close()
|
||||
|
||||
// seed the database with our "Hello, world" post and user.
|
||||
err := seed(context.Background(), client)
|
||||
require.NoError(t, err)
|
||||
|
||||
// Initialize a server and router.
|
||||
srv := newServer(client)
|
||||
r := newRouter(srv)
|
||||
|
||||
// Create a test server using the `httptest` package.
|
||||
ts := httptest.NewServer(r)
|
||||
defer ts.Close()
|
||||
|
||||
// Make a GET request to the server root path.
|
||||
resp, err := ts.Client().Get(ts.URL)
|
||||
|
||||
// Assert we get a 200 OK status code.
|
||||
require.NoError(t, err)
|
||||
require.Equal(t, http.StatusOK, resp.StatusCode)
|
||||
|
||||
// Read the response body and assert it contains "Hello, world!"
|
||||
body, err := io.ReadAll(resp.Body)
|
||||
require.NoError(t, err)
|
||||
require.Contains(t, string(body), "Hello, World!")
|
||||
}
|
||||
```
|
||||
|
||||
Run the test to verify our server works correctly:
|
||||
|
||||
```
|
||||
go test ./...
|
||||
```
|
||||
|
||||
Observe our test passes:
|
||||
```
|
||||
ok github.com/rotemtam/ent-blog-example 0.719s
|
||||
? github.com/rotemtam/ent-blog-example/ent [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/enttest [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/hook [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/migrate [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/post [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/predicate [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/runtime [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/schema [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/user [no test files]
|
||||
|
||||
```
|
||||
|
||||
#### Putting everything together
|
||||
|
||||
Finally, let's update our `main` function to put everything together:
|
||||
|
||||
```go
|
||||
func main() {
|
||||
// Read the connection string to the database from a CLI flag.
|
||||
var dsn string
|
||||
flag.StringVar(&dsn, "dsn", "", "database DSN")
|
||||
flag.Parse()
|
||||
|
||||
// Instantiate the Ent client.
|
||||
client, err := ent.Open("mysql", dsn)
|
||||
if err != nil {
|
||||
log.Fatalf("failed connecting to mysql: %v", err)
|
||||
}
|
||||
defer client.Close()
|
||||
|
||||
ctx := context.Background()
|
||||
// If we don't have any posts yet, seed the database.
|
||||
if !client.Post.Query().ExistX(ctx) {
|
||||
if err := seed(ctx, client); err != nil {
|
||||
log.Fatalf("failed seeding the database: %v", err)
|
||||
}
|
||||
}
|
||||
srv := newServer(client)
|
||||
r := newRouter(srv)
|
||||
log.Fatal(http.ListenAndServe(":8080", r))
|
||||
}
|
||||
```
|
||||
|
||||
We can now run our application and stand amazed at our achievement: a working blog front page!
|
||||
|
||||
```
|
||||
go run main.go -dsn "root:pass@tcp(localhost:3306)/test?parseTime=true"
|
||||
```
|
||||
|
||||

|
||||
|
||||
### Step 4: Adding content
|
||||
|
||||
:::info
|
||||
You can follow the changes in this step in [this commit](https://github.com/rotemtam/ent-blog-example/commit/2e412ab2cda0fd251ccb512099b802174d917511).
|
||||
:::
|
||||
|
||||
No content management system would be complete without the ability, well, to manage content. Let's demonstrate how we can add support for publishing new posts on our blog.
|
||||
|
||||
Let's start by creating the backend handler:
|
||||
```go
|
||||
// add creates a new blog post.
|
||||
func (s *server) add(w http.ResponseWriter, r *http.Request) {
|
||||
author, err := s.client.User.Query().Only(r.Context())
|
||||
if err != nil {
|
||||
http.Error(w, err.Error(), http.StatusInternalServerError)
|
||||
return
|
||||
}
|
||||
if err := s.client.Post.Create().
|
||||
SetTitle(r.FormValue("title")).
|
||||
SetBody(r.FormValue("body")).
|
||||
SetAuthor(author).
|
||||
Exec(r.Context()); err != nil {
|
||||
http.Error(w, err.Error(), http.StatusInternalServerError)
|
||||
}
|
||||
http.Redirect(w, r, "/", http.StatusFound)
|
||||
}
|
||||
```
|
||||
As you can see, the handler currently loads the *only* user from the `users` table (since we have yet to create a user management system or login capabilities). `Only` will fail unless exactly one result is retrieved from the database.
|
||||
|
||||
Next, our handler creates a new post, by setting the title and body fields to values retrieved from `r.FormValue`. This is where Go stores all of the form input passed to an HTTP request.
|
||||
|
||||
After creating the handler, we should wire it to our router:
|
||||
```go
|
||||
// newRouter creates a new router with the blog handlers mounted.
|
||||
func newRouter(srv *server) chi.Router {
|
||||
r := chi.NewRouter()
|
||||
r.Use(middleware.Logger)
|
||||
r.Use(middleware.Recoverer)
|
||||
r.Get("/", srv.index)
|
||||
// highlight-next-line
|
||||
r.Post("/add", srv.add)
|
||||
return r
|
||||
}
|
||||
```
|
||||
Next, we can add an HTML `<form>` component that will be used by our user to write their content:
|
||||
```html
|
||||
<div class="col-md-12">
|
||||
<hr/>
|
||||
<h2>Create a new post</h2>
|
||||
<form action="/add" method="post">
|
||||
<div class="mb-3">
|
||||
<label for="title" class="form-label">Title</label>
|
||||
<input name="title" type="text" class="form-control" id="title" placeholder="Once upon a time..">
|
||||
</div>
|
||||
<div class="mb-3">
|
||||
<label for="body" class="form-label">Body</label>
|
||||
<textarea name="body" class="form-control" id="body" rows="8"></textarea>
|
||||
</div>
|
||||
<div class="mb-3">
|
||||
<button type="submit" class="btn btn-primary mb-3">Post</button>
|
||||
</div>
|
||||
</form>
|
||||
</div>
|
||||
```
|
||||
|
||||
Also, let's add a nice touch, where we display the blog posts from newest to oldest. To do this, modify the `index` handler to order the posts in a descending order using the `created_at` column:
|
||||
```go
|
||||
posts, err := s.client.Post.
|
||||
Query().
|
||||
WithAuthor().
|
||||
// highlight-next-line
|
||||
Order(ent.Desc(post.FieldCreatedAt)).
|
||||
All(ctx)
|
||||
```
|
||||
|
||||
Finally, let's add another unit test that verifies the add post flow works as expected:
|
||||
```go
|
||||
func TestAdd(t *testing.T) {
|
||||
client := enttest.Open(t, "sqlite3", "file:ent?mode=memory&cache=shared&_fk=1")
|
||||
defer client.Close()
|
||||
err := seed(context.Background(), client)
|
||||
require.NoError(t, err)
|
||||
|
||||
srv := newServer(client)
|
||||
r := newRouter(srv)
|
||||
|
||||
ts := httptest.NewServer(r)
|
||||
defer ts.Close()
|
||||
|
||||
// Post the form.
|
||||
resp, err := ts.Client().PostForm(ts.URL+"/add", map[string][]string{
|
||||
"title": {"Testing, one, two."},
|
||||
"body": {"This is a test"},
|
||||
})
|
||||
require.NoError(t, err)
|
||||
// We should be redirected to the index page and receive 200 OK.
|
||||
require.Equal(t, http.StatusOK, resp.StatusCode)
|
||||
|
||||
body, err := io.ReadAll(resp.Body)
|
||||
require.NoError(t, err)
|
||||
|
||||
// The home page should contain our new post.
|
||||
require.Contains(t, string(body), "This is a test")
|
||||
}
|
||||
```
|
||||
|
||||
Let's run the test:
|
||||
```
|
||||
go test ./...
|
||||
```
|
||||
|
||||
And everything works!
|
||||
|
||||
```
|
||||
ok github.com/rotemtam/ent-blog-example 0.493s
|
||||
? github.com/rotemtam/ent-blog-example/ent [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/enttest [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/hook [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/migrate [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/post [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/predicate [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/runtime [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/schema [no test files]
|
||||
? github.com/rotemtam/ent-blog-example/ent/user [no test files]
|
||||
|
||||
```
|
||||
|
||||
A passing unit test is great, but let's verify our changes visually:
|
||||
|
||||
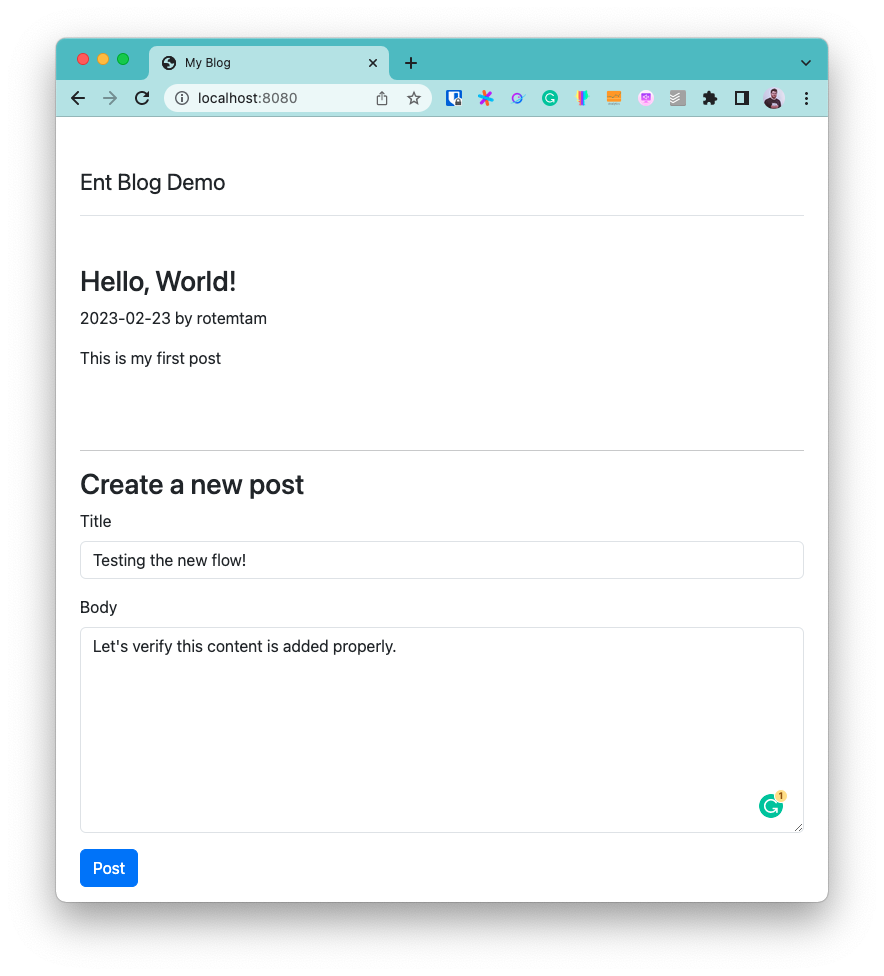
|
||||
|
||||
Our form appears - great! After submitting it:
|
||||
|
||||

|
||||
|
||||
Our new post is displayed. Well done!
|
||||
|
||||
### Wrapping up
|
||||
|
||||
In this post we demonstrated how to build a simple web application with Ent and Go. Our app is definitely bare but it deals with many of the bases that you will need to cover when building an application: defining your data model, managing your database schema, writing server code, defining routes and building a UI.
|
||||
|
||||
As things go with introductory content, we only touched the tip of the iceberg of what you can do with Ent, but I hope you got a taste for some of its core features.
|
||||
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
99
doc/website/blog/2023-08-13-visualize-with-atlas.md
Normal file
99
doc/website/blog/2023-08-13-visualize-with-atlas.md
Normal file
@@ -0,0 +1,99 @@
|
||||
---
|
||||
title: "Quickly Generate ERDs from your Ent Schemas (Updated)"
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
image: "https://atlasgo.io/uploads/ent/inspect/entviz.png"
|
||||
---
|
||||
|
||||
### TL;DR
|
||||
|
||||
Create a visualization of your Ent schema with one command:
|
||||
|
||||
```
|
||||
atlas schema inspect \
|
||||
-u ent://ent/schema \
|
||||
--dev-url "sqlite://demo?mode=memory&_fk=1" \
|
||||
--visualize
|
||||
```
|
||||
|
||||

|
||||
|
||||
|
||||
Hi Everyone!
|
||||
|
||||
A few months ago, we shared [entviz](/blog/2023/01/26/visualizing-with-entviz), a cool
|
||||
tool that enables you to visualize your Ent schemas. Due to its success and popularity,
|
||||
we decided to integrate it directly into [Atlas](https://atlasgo.io), the migration engine
|
||||
that Ent uses.
|
||||
|
||||
Since the release of [v0.13.0](https://atlasgo.io/blog/2023/08/06/atlas-v-0-13) of Atlas,
|
||||
you can now visualize your Ent schemas directly from Atlas without needing to install an
|
||||
additional tool.
|
||||
|
||||
### Private vs. Public Visualizations
|
||||
|
||||
Previously, you could only share a visualization of your schema to the
|
||||
[Atlas Public Playground](https://gh.atlasgo.cloud/explore). While this is convenient
|
||||
for sharing your schema with others, it is not acceptable for many teams who maintain
|
||||
schemas that themselves are sensitive and cannot be shared publicly.
|
||||
|
||||
With this new release, you can easily publish your schema directly to your private
|
||||
workspace on [Atlas Cloud](https://atlasgo.cloud). This means that only you and your
|
||||
team can access the visualization of your schema.
|
||||
|
||||
### Visualizing your Ent Schema with Atlas
|
||||
|
||||
To visualize your Ent schema with Atlas, first install its latest version:
|
||||
|
||||
```
|
||||
curl -sSfL https://atlasgo.io/install.sh | sh
|
||||
```
|
||||
For other installation options, see the [Atlas installation docs](https://atlasgo.io/getting-started#installation).
|
||||
|
||||
Next, run the following command to generate a visualization of your Ent schema:
|
||||
|
||||
```
|
||||
atlas schema inspect \
|
||||
-u ent://ent/schema \
|
||||
--dev-url "sqlite://demo?mode=memory&_fk=1" \
|
||||
--visualize
|
||||
```
|
||||
|
||||
Let's break this command down:
|
||||
* `atlas schema inspect` - this command can be used to inspect schemas from a variety of sources and outputs
|
||||
them in various formats. In this case, we are using it to inspect an Ent schema.
|
||||
* `-u ent://ent/schema` - this is the URL to the Ent schema we want to inspect. In this case, we are using the
|
||||
`ent://` schema loader to point to a local Ent schema in the `./ent/schema` directory.
|
||||
* `--dev-url "sqlite://demo?mode=memory&_fk=1"` - Atlas relies on having an empty database called the
|
||||
[Dev Database](https://atlasgo.io/concepts/dev-database) to normalize schemas and make various calculations.
|
||||
In this case, we are using an in memory SQLite database; but, if you are using a different driver, you can use
|
||||
`docker://mysql/8/dev` (for MySQL) or `docker://postgres/15/?search_path=public` (for PostgreSQL).
|
||||
|
||||
Once you run this command, you should see the following output:
|
||||
|
||||
```text
|
||||
Use the arrow keys to navigate: ↓ ↑ → ←
|
||||
? Where would you like to share your schema visualization?:
|
||||
▸ Publicly (gh.atlasgo.cloud)
|
||||
Your personal workspace (requires 'atlas login')
|
||||
```
|
||||
|
||||
If you want to share your schema publicly, you can select the first option. If you want to share it privately, you
|
||||
can select the second option and then run `atlas login` to log in to your (free) Atlas account.
|
||||
|
||||
### Wrapping up
|
||||
|
||||
In this post, we showed how you can easily visualize your Ent schema with Atlas. We hope you find this feature useful
|
||||
and we look forward to hearing your feedback!
|
||||
|
||||
|
||||
:::note For more Ent news and updates:
|
||||
|
||||
- Subscribe to our [Newsletter](https://entgo.substack.com/)
|
||||
- Follow us on [Twitter](https://twitter.com/entgo_io)
|
||||
- Join us on #ent on the [Gophers Slack](https://entgo.io/docs/slack)
|
||||
- Join us on the [Ent Discord Server](https://discord.gg/qZmPgTE6RX)
|
||||
|
||||
:::
|
||||
831
doc/website/blog/2025-02-12-rag-with-ent-atlas-pgvector.mdx
Normal file
831
doc/website/blog/2025-02-12-rag-with-ent-atlas-pgvector.mdx
Normal file
@@ -0,0 +1,831 @@
|
||||
---
|
||||
title: "Building RAG systems in Go with Ent, Atlas, and pgvector"
|
||||
author: Rotem Tamir
|
||||
authorURL: "https://github.com/rotemtam"
|
||||
authorImageURL: "https://s.gravatar.com/avatar/36b3739951a27d2e37251867b7d44b1a?s=80"
|
||||
authorTwitter: _rtam
|
||||
image: "https://atlasgo.io/uploads/entrag.png"
|
||||
---
|
||||
In this blog post, we will explore how to build a [RAG](https://en.wikipedia.org/wiki/Retrieval-augmented_generation)
|
||||
(Retrieval Augmented Generation) system using [Ent](https://entgo.io), [Atlas](https://atlasgo.io), and
|
||||
[pgvector](https://github.com/pgvector/pgvector).
|
||||
|
||||
RAG is a technique that augments the power of generative models by incorporating a retrieval step. Instead of relying
|
||||
solely on the model’s internal knowledge, we can retrieve relevant documents or data from an external source and use
|
||||
that information to produce more accurate, context-aware responses. This approach is particularly useful when building
|
||||
applications such as question-answering systems, chatbots, or any scenario where up-to-date or domain-specific knowledge
|
||||
is needed.
|
||||
|
||||
### Setting Up our Ent schema
|
||||
|
||||
Let's begin our tutorial by initializing the Go module which we will be using for our project:
|
||||
|
||||
```bash
|
||||
go mod init github.com/rotemtam/entrag # Feel free to replace the module path with your own
|
||||
```
|
||||
|
||||
In this project we will use [Ent](/), an entity framework for Go, to define our database schema. The database will store
|
||||
the documents we want to retrieve (chunked to a fixed size) and the vectors representing each chunk. Initialize the Ent
|
||||
project by running the following command:
|
||||
|
||||
```bash
|
||||
go run -mod=mod entgo.io/ent/cmd/ent new Embedding Chunk
|
||||
```
|
||||
|
||||
This command creates placeholders for our data models. Our project should look like this:
|
||||
|
||||
```
|
||||
├── ent
|
||||
│ ├── generate.go
|
||||
│ └── schema
|
||||
│ ├── chunk.go
|
||||
│ └── embedding.go
|
||||
├── go.mod
|
||||
└── go.sum
|
||||
```
|
||||
|
||||
Next, let's define the schema for the `Chunk` model. Open the `ent/schema/chunk.go` file and define the schema as follows:
|
||||
|
||||
```go title="ent/schema/chunk.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/schema/edge"
|
||||
"entgo.io/ent/schema/field"
|
||||
)
|
||||
|
||||
// Chunk holds the schema definition for the Chunk entity.
|
||||
type Chunk struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Chunk.
|
||||
func (Chunk) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.String("path"),
|
||||
field.Int("nchunk"),
|
||||
field.Text("data"),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Chunk.
|
||||
func (Chunk) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.To("embedding", Embedding.Type).StorageKey(edge.Column("chunk_id")).Unique(),
|
||||
}
|
||||
}
|
||||
```
|
||||
This schema defines a `Chunk` entity with three fields: `path`, `nchunk`, and `data`. The `path` field stores the path
|
||||
of the document, `nchunk` stores the chunk number, and `data` stores the chunked text data. We also define an edge to
|
||||
the `Embedding` entity, which will store the vector representation of the chunk.
|
||||
|
||||
Before we proceed, let's install the `pgvector` package. `pgvector` is a PostgreSQL extension that provides support for
|
||||
vector operations and similarity search. We will need it to store and retrieve the vector representations of our chunks.
|
||||
|
||||
```bash
|
||||
go get github.com/pgvector/pgvector-go
|
||||
```
|
||||
|
||||
Next, let's define the schema for the `Embedding` model. Open the `ent/schema/embedding.go` file and define the schema
|
||||
as follows:
|
||||
|
||||
```go title="ent/schema/embedding.go"
|
||||
package schema
|
||||
|
||||
import (
|
||||
"entgo.io/ent"
|
||||
"entgo.io/ent/dialect"
|
||||
"entgo.io/ent/dialect/entsql"
|
||||
"entgo.io/ent/schema/edge"
|
||||
"entgo.io/ent/schema/field"
|
||||
"entgo.io/ent/schema/index"
|
||||
"github.com/pgvector/pgvector-go"
|
||||
)
|
||||
|
||||
// Embedding holds the schema definition for the Embedding entity.
|
||||
type Embedding struct {
|
||||
ent.Schema
|
||||
}
|
||||
|
||||
// Fields of the Embedding.
|
||||
func (Embedding) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Other("embedding", pgvector.Vector{}).
|
||||
SchemaType(map[string]string{
|
||||
dialect.Postgres: "vector(1536)",
|
||||
}),
|
||||
}
|
||||
}
|
||||
|
||||
// Edges of the Embedding.
|
||||
func (Embedding) Edges() []ent.Edge {
|
||||
return []ent.Edge{
|
||||
edge.From("chunk", Chunk.Type).Ref("embedding").Unique().Required(),
|
||||
}
|
||||
}
|
||||
|
||||
func (Embedding) Indexes() []ent.Index {
|
||||
return []ent.Index{
|
||||
index.Fields("embedding").
|
||||
Annotations(
|
||||
entsql.IndexType("hnsw"),
|
||||
entsql.OpClass("vector_l2_ops"),
|
||||
),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
This schema defines an `Embedding` entity with a single field `embedding` of type `pgvector.Vector`. The `embedding`
|
||||
field stores the vector representation of the chunk. We also define an edge to the `Chunk` entity and an index on the
|
||||
`embedding` field using the `hnsw` index type and `vector_l2_ops` operator class. This index will enable us to perform
|
||||
efficient similarity searches on the embeddings.
|
||||
|
||||
Finally, let's generate the Ent code by running the following commands:
|
||||
|
||||
```bash
|
||||
go mod tidy
|
||||
go generate ./...
|
||||
```
|
||||
|
||||
Ent will generate the necessary code for our models based on the schema definitions.
|
||||
|
||||
### Setting Up the database
|
||||
|
||||
Next, let's set up the PostgreSQL database. We will use Docker to run a PostgreSQL instance locally. As we need the
|
||||
`pgvector` extension, we will use the `pgvector/pgvector:pg17` Docker image, which comes with the extension
|
||||
pre-installed.
|
||||
|
||||
```bash
|
||||
docker run --rm --name postgres -e POSTGRES_PASSWORD=pass -p 5432:5432 -d pgvector/pgvector:pg17
|
||||
```
|
||||
|
||||
We will be using [Atlas](https://atlasgo.io), a database schema-as-code tool that integrates with Ent, to manage our
|
||||
database schema. Install Atlas by running the following command:
|
||||
|
||||
```
|
||||
curl -sSfL https://atlasgo.io/install.sh | sh
|
||||
```
|
||||
|
||||
For other installation options, see the [Atlas installation docs](https://atlasgo.io/getting-started#installation).
|
||||
|
||||
As we are going to managing extensions, we need an Atlas Pro account. You can sign up for a free trial by running:
|
||||
|
||||
```
|
||||
atlas login
|
||||
```
|
||||
|
||||
:::note Working without a migration tool
|
||||
|
||||
If you would like to skip using Atlas, you can apply the required schema directly to the database
|
||||
using the statements in [this file](https://github.com/rotemtam/entrag/blob/e91722c0fbe011b03dbd6b9e68415547c8b7bba4/setup.sql#L1)
|
||||
|
||||
:::
|
||||
|
||||
Now, let's create our base configuration `base.pg.hcl` which provides the vector extension for the public schema:
|
||||
|
||||
```hcl title="base.pg.hcl"
|
||||
schema "public" {
|
||||
}
|
||||
|
||||
extension "vector" {
|
||||
schema = schema.public
|
||||
}
|
||||
```
|
||||
|
||||
Now, let's create our Atlas configuration which composes the base.pg.hcl file with the Ent schema:
|
||||
|
||||
```hcl title="atlas.hcl"
|
||||
data "composite_schema" "schema" {
|
||||
schema {
|
||||
url = "file://base.pg.hcl"
|
||||
}
|
||||
schema "public" {
|
||||
url = "ent://ent/schema"
|
||||
}
|
||||
}
|
||||
|
||||
env "local" {
|
||||
url = getenv("DB_URL")
|
||||
schema {
|
||||
src = data.composite_schema.schema.url
|
||||
}
|
||||
dev = "docker://pgvector/pg17/dev"
|
||||
}
|
||||
```
|
||||
|
||||
This configuration defines a composite schema that includes the `base.pg.hcl` file and the Ent schema. We also define an
|
||||
environment named `local` that uses the composite schema which we will use for local development. The `dev` field specifies
|
||||
the [Dev Database](https://atlasgo.io/concepts/dev-database) URL, which is used by Atlas to normalize schemas and make
|
||||
various calculations.
|
||||
|
||||
Next, let's apply the schema to the database by running the following command:
|
||||
|
||||
```bash
|
||||
export DB_URL='postgresql://postgres:pass@localhost:5432/postgres?sslmode=disable'
|
||||
atlas schema apply --env local
|
||||
```
|
||||
Atlas will load the desired state of the database from our configuration, compare it to the current state of the database,
|
||||
and create a migration plan to bring the database to the desired state:
|
||||
|
||||
```
|
||||
Planning migration statements (5 in total):
|
||||
|
||||
-- create extension "vector":
|
||||
-> CREATE EXTENSION "vector" WITH SCHEMA "public" VERSION "0.8.0";
|
||||
-- create "chunks" table:
|
||||
-> CREATE TABLE "public"."chunks" (
|
||||
"id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY,
|
||||
"path" character varying NOT NULL,
|
||||
"nchunk" bigint NOT NULL,
|
||||
"data" text NOT NULL,
|
||||
PRIMARY KEY ("id")
|
||||
);
|
||||
-- create "embeddings" table:
|
||||
-> CREATE TABLE "public"."embeddings" (
|
||||
"id" bigint NOT NULL GENERATED BY DEFAULT AS IDENTITY,
|
||||
"embedding" public.vector(1536) NOT NULL,
|
||||
"chunk_id" bigint NOT NULL,
|
||||
PRIMARY KEY ("id"),
|
||||
CONSTRAINT "embeddings_chunks_embedding" FOREIGN KEY ("chunk_id") REFERENCES "public"."chunks" ("id") ON UPDATE NO ACTION ON DELETE NO ACTION
|
||||
);
|
||||
-- create index "embedding_embedding" to table: "embeddings":
|
||||
-> CREATE INDEX "embedding_embedding" ON "public"."embeddings" USING hnsw ("embedding" vector_l2_ops);
|
||||
-- create index "embeddings_chunk_id_key" to table: "embeddings":
|
||||
-> CREATE UNIQUE INDEX "embeddings_chunk_id_key" ON "public"."embeddings" ("chunk_id");
|
||||
|
||||
-------------------------------------------
|
||||
|
||||
Analyzing planned statements (5 in total):
|
||||
|
||||
-- non-optimal columns alignment:
|
||||
-- L4: Table "chunks" has 8 redundant bytes of padding per row. To reduce disk space,
|
||||
the optimal order of the columns is as follows: "id", "nchunk", "path",
|
||||
"data" https://atlasgo.io/lint/analyzers#PG110
|
||||
-- ok (370.25µs)
|
||||
|
||||
-------------------------
|
||||
-- 114.306667ms
|
||||
-- 5 schema changes
|
||||
-- 1 diagnostic
|
||||
|
||||
-------------------------------------------
|
||||
|
||||
? Approve or abort the plan:
|
||||
▸ Approve and apply
|
||||
Abort
|
||||
```
|
||||
|
||||
In addition to planning the change, Atlas will also provide diagnostics and suggestions for optimizing the schema. In this
|
||||
case it suggests reordering the columns in the `chunks` table to reduce disk space. As we are not concerned with disk space
|
||||
in this tutorial, we can proceed with the migration by selecting `Approve and apply`.
|
||||
|
||||
Finally, we can verify that our schema was applied successfully, we can re-run the `atlas schema apply` command. Atlas
|
||||
will output:
|
||||
|
||||
```bash
|
||||
Schema is synced, no changes to be made
|
||||
```
|
||||
|
||||
### Scaffolding the CLI
|
||||
|
||||
Now that our database schema is set up, let's scaffold our CLI application. For this tutorial, we will be using
|
||||
the [`alecthomas/kong`](https://github.com/alecthomas/kong) library to build a small app that can load, index
|
||||
and query the documents in our database.
|
||||
|
||||
First, install the `kong` library:
|
||||
|
||||
```bash
|
||||
go get github.com/alecthomas/kong
|
||||
```
|
||||
|
||||
Next, create a new file named `cmd/entrag/main.go` and define the CLI application as follows:
|
||||
|
||||
```go title="cmd/entrag/main.go"
|
||||
package main
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"os"
|
||||
|
||||
"github.com/alecthomas/kong"
|
||||
)
|
||||
|
||||
// CLI holds global options and subcommands.
|
||||
type CLI struct {
|
||||
// DBURL is read from the environment variable DB_URL.
|
||||
DBURL string `kong:"env='DB_URL',help='Database URL for the application.'"`
|
||||
OpenAIKey string `kong:"env='OPENAI_KEY',help='OpenAI API key for the application.'"`
|
||||
|
||||
// Subcommands
|
||||
Load *LoadCmd `kong:"cmd,help='Load command that accepts a path.'"`
|
||||
Index *IndexCmd `kong:"cmd,help='Create embeddings for any chunks that do not have one.'"`
|
||||
Ask *AskCmd `kong:"cmd,help='Ask a question about the indexed documents'"`
|
||||
}
|
||||
|
||||
func main() {
|
||||
var cli CLI
|
||||
app := kong.Parse(&cli,
|
||||
kong.Name("entrag"),
|
||||
kong.Description("Ask questions about markdown files."),
|
||||
kong.UsageOnError(),
|
||||
)
|
||||
if err := app.Run(&cli); err != nil {
|
||||
fmt.Fprintf(os.Stderr, "Error: %s\n", err)
|
||||
os.Exit(1)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Create an additional file named `cmd/entrag/rag.go` with the following content:
|
||||
|
||||
```go title="cmd/entrag/rag.go"
|
||||
package main
|
||||
|
||||
type (
|
||||
// LoadCmd loads the markdown files into the database.
|
||||
LoadCmd struct {
|
||||
Path string `help:"path to dir with markdown files" type:"existingdir" required:""`
|
||||
}
|
||||
// IndexCmd creates the embedding index on the database.
|
||||
IndexCmd struct {
|
||||
}
|
||||
// AskCmd is another leaf command.
|
||||
AskCmd struct {
|
||||
// Text is the positional argument for the ask command.
|
||||
Text string `kong:"arg,required,help='Text for the ask command.'"`
|
||||
}
|
||||
)
|
||||
```
|
||||
|
||||
Verify our scaffolded CLI application works by running:
|
||||
|
||||
```bash
|
||||
go run ./cmd/entrag --help
|
||||
```
|
||||
|
||||
If everything is set up correctly, you should see the help output for the CLI application:
|
||||
|
||||
```
|
||||
Usage: entrag <command> [flags]
|
||||
|
||||
Ask questions about markdown files.
|
||||
|
||||
Flags:
|
||||
-h, --help Show context-sensitive help.
|
||||
--dburl=STRING Database URL for the application ($DB_URL).
|
||||
--open-ai-key=STRING OpenAI API key for the application ($OPENAI_KEY).
|
||||
|
||||
Commands:
|
||||
load --path=STRING [flags]
|
||||
Load command that accepts a path.
|
||||
|
||||
index [flags]
|
||||
Create embeddings for any chunks that do not have one.
|
||||
|
||||
ask <text> [flags]
|
||||
Ask a question about the indexed documents
|
||||
|
||||
Run "entrag <command> --help" for more information on a command.
|
||||
```
|
||||
|
||||
### Load the documents into the database
|
||||
|
||||
Next, we need some markdown files to load into the database. Create a directory named `data` and add some markdown files
|
||||
to it. For this example, I downloaded the [`ent/ent`](https://github.com/ent/ent) repository and used the `docs` directory
|
||||
as the source of markdown files.
|
||||
|
||||
Now, let's implement the `LoadCmd` command to load the markdown files into the database. Open the `cmd/entrag/rag.go` file
|
||||
and add the following code:
|
||||
|
||||
```go title="cmd/entrag/rag.go"
|
||||
const (
|
||||
tokenEncoding = "cl100k_base"
|
||||
chunkSize = 1000
|
||||
)
|
||||
|
||||
// Run is the method called when the "load" command is executed.
|
||||
func (cmd *LoadCmd) Run(ctx *CLI) error {
|
||||
client, err := ctx.entClient()
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed opening connection to postgres: %w", err)
|
||||
}
|
||||
tokTotal := 0
|
||||
return filepath.WalkDir(ctx.Load.Path, func(path string, d fs.DirEntry, err error) error {
|
||||
if filepath.Ext(path) == ".mdx" || filepath.Ext(path) == ".md" {
|
||||
chunks := breakToChunks(path)
|
||||
for i, chunk := range chunks {
|
||||
tokTotal += len(chunk)
|
||||
client.Chunk.Create().
|
||||
SetData(chunk).
|
||||
SetPath(path).
|
||||
SetNchunk(i).
|
||||
SaveX(context.Background())
|
||||
}
|
||||
}
|
||||
return nil
|
||||
})
|
||||
}
|
||||
|
||||
func (c *CLI) entClient() (*ent.Client, error) {
|
||||
return ent.Open("postgres", c.DBURL)
|
||||
}
|
||||
```
|
||||
|
||||
This code defines the `Run` method for the `LoadCmd` command. The method reads the markdown files from the specified
|
||||
path, breaks them into chunks of 1000 tokens each, and saves them to the database. We use the `entClient` method to
|
||||
create a new Ent client using the database URL specified in the CLI options.
|
||||
|
||||
For the implementation of `breakToChunks`, see the [full code](https://github.com/rotemtam/entrag/blob/93291e0c8479ecabd5f2a2e49fbaa8c49f995e70/cmd/entrag/rag.go#L157)
|
||||
in the [`entrag` repository](https://github.com/rotemtam/entrag), which is based almost entirely on
|
||||
[Eli Bendersky's intro to RAG in Go](https://eli.thegreenplace.net/2023/retrieval-augmented-generation-in-go/).
|
||||
|
||||
Finally, let's run the `load` command to load the markdown files into the database:
|
||||
|
||||
```bash
|
||||
go run ./cmd/entrag load --path=data
|
||||
```
|
||||
|
||||
After the command completes, you should see the chunks loaded into the database. To verify run:
|
||||
|
||||
```bash
|
||||
docker exec -it postgres psql -U postgres -d postgres -c "SELECT COUNT(*) FROM chunks;"
|
||||
```
|
||||
|
||||
You should see something similar to:
|
||||
|
||||
```
|
||||
count
|
||||
-------
|
||||
276
|
||||
(1 row)
|
||||
```
|
||||
|
||||
### Indexing the embeddings
|
||||
|
||||
Now that we have loaded the documents into the database, we need to create embeddings for each chunk. We will use the
|
||||
OpenAI API to generate embeddings for the chunks. To do this, we need to install the `openai` package:
|
||||
|
||||
```bash
|
||||
go get github.com/sashabaranov/go-openai
|
||||
```
|
||||
|
||||
If you do not have an OpenAI API key, you can sign up for an account on the
|
||||
[OpenAI Platform](https://platform.openai.com/signup) and [generate an API key](https://platform.openai.com/api-keys).
|
||||
|
||||
We will be reading this key from the environment variable `OPENAI_KEY`, so let's set it:
|
||||
|
||||
```bash
|
||||
export OPENAI_KEY=<your OpenAI API key>
|
||||
```
|
||||
|
||||
Next, let's implement the `IndexCmd` command to create embeddings for the chunks. Open the `cmd/entrag/rag.go` file and
|
||||
add the following code:
|
||||
|
||||
```go title="cmd/entrag/rag.go"
|
||||
// Run is the method called when the "index" command is executed.
|
||||
func (cmd *IndexCmd) Run(cli *CLI) error {
|
||||
client, err := cli.entClient()
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed opening connection to postgres: %w", err)
|
||||
}
|
||||
ctx := context.Background()
|
||||
chunks := client.Chunk.Query().
|
||||
Where(
|
||||
chunk.Not(
|
||||
chunk.HasEmbedding(),
|
||||
),
|
||||
).
|
||||
Order(ent.Asc(chunk.FieldID)).
|
||||
AllX(ctx)
|
||||
for _, ch := range chunks {
|
||||
log.Println("Created embedding for chunk", ch.Path, ch.Nchunk)
|
||||
embedding := getEmbedding(ch.Data)
|
||||
_, err := client.Embedding.Create().
|
||||
SetEmbedding(pgvector.NewVector(embedding)).
|
||||
SetChunk(ch).
|
||||
Save(ctx)
|
||||
if err != nil {
|
||||
return fmt.Errorf("error creating embedding: %v", err)
|
||||
}
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// getEmbedding invokes the OpenAI embedding API to calculate the embedding
|
||||
// for the given string. It returns the embedding.
|
||||
func getEmbedding(data string) []float32 {
|
||||
client := openai.NewClient(os.Getenv("OPENAI_KEY"))
|
||||
queryReq := openai.EmbeddingRequest{
|
||||
Input: []string{data},
|
||||
Model: openai.AdaEmbeddingV2,
|
||||
}
|
||||
queryResponse, err := client.CreateEmbeddings(context.Background(), queryReq)
|
||||
if err != nil {
|
||||
log.Fatalf("Error getting embedding: %v", err)
|
||||
}
|
||||
return queryResponse.Data[0].Embedding
|
||||
}
|
||||
```
|
||||
|
||||
We have defined the `Run` method for the `IndexCmd` command. The method queries the database for chunks that do not have
|
||||
embeddings, generates embeddings for each chunk using the OpenAI API, and saves the embeddings to the database.
|
||||
|
||||
Finally, let's run the `index` command to create embeddings for the chunks:
|
||||
|
||||
```bash
|
||||
go run ./cmd/entrag index
|
||||
```
|
||||
|
||||
You should see logs similar to:
|
||||
|
||||
```
|
||||
2025/02/13 13:04:42 Created embedding for chunk /Users/home/entr/data/md/aggregate.md 0
|
||||
2025/02/13 13:04:43 Created embedding for chunk /Users/home/entr/data/md/ci.mdx 0
|
||||
2025/02/13 13:04:44 Created embedding for chunk /Users/home/entr/data/md/ci.mdx 1
|
||||
2025/02/13 13:04:45 Created embedding for chunk /Users/home/entr/data/md/ci.mdx 2
|
||||
2025/02/13 13:04:46 Created embedding for chunk /Users/home/entr/data/md/code-gen.md 0
|
||||
2025/02/13 13:04:47 Created embedding for chunk /Users/home/entr/data/md/code-gen.md 1
|
||||
```
|
||||
|
||||
### Asking questions
|
||||
|
||||
Now that we have loaded the documents and created embeddings for the chunks, we can implement
|
||||
the `AskCmd` command to ask questions about the indexed documents. Open the `cmd/entrag/rag.go` file and add the following code:
|
||||
|
||||
```go title="cmd/entrag/rag.go"
|
||||
// Run is the method called when the "ask" command is executed.
|
||||
func (cmd *AskCmd) Run(ctx *CLI) error {
|
||||
client, err := ctx.entClient()
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed opening connection to postgres: %w", err)
|
||||
}
|
||||
question := cmd.Text
|
||||
emb := getEmbedding(question)
|
||||
embVec := pgvector.NewVector(emb)
|
||||
embs := client.Embedding.
|
||||
Query().
|
||||
Order(func(s *sql.Selector) {
|
||||
s.OrderExpr(sql.ExprP("embedding <-> $1", embVec))
|
||||
}).
|
||||
WithChunk().
|
||||
Limit(5).
|
||||
AllX(context.Background())
|
||||
b := strings.Builder{}
|
||||
for _, e := range embs {
|
||||
chnk := e.Edges.Chunk
|
||||
b.WriteString(fmt.Sprintf("From file: %v\n", chnk.Path))
|
||||
b.WriteString(chnk.Data)
|
||||
}
|
||||
query := fmt.Sprintf(`Use the below information from the ent docs to answer the subsequent question.
|
||||
Information:
|
||||
%v
|
||||
|
||||
Question: %v`, b.String(), question)
|
||||
oac := openai.NewClient(ctx.OpenAIKey)
|
||||
resp, err := oac.CreateChatCompletion(
|
||||
context.Background(),
|
||||
openai.ChatCompletionRequest{
|
||||
Model: openai.GPT4o,
|
||||
Messages: []openai.ChatCompletionMessage{
|
||||
|
||||
{
|
||||
Role: openai.ChatMessageRoleUser,
|
||||
Content: query,
|
||||
},
|
||||
},
|
||||
},
|
||||
)
|
||||
if err != nil {
|
||||
return fmt.Errorf("error creating chat completion: %v", err)
|
||||
}
|
||||
choice := resp.Choices[0]
|
||||
out, err := glamour.Render(choice.Message.Content, "dark")
|
||||
fmt.Print(out)
|
||||
return nil
|
||||
}
|
||||
```
|
||||
This is where all of the parts come together. After preparing our database with the documents and their embeddings, we
|
||||
can now ask questions about them. Let's break down the `AskCmd` command:
|
||||
|
||||
```go
|
||||
emb := getEmbedding(question)
|
||||
embVec := pgvector.NewVector(emb)
|
||||
embs := client.Embedding.
|
||||
Query().
|
||||
Order(func(s *sql.Selector) {
|
||||
s.OrderExpr(sql.ExprP("embedding <-> $1", embVec))
|
||||
}).
|
||||
WithChunk().
|
||||
Limit(5).
|
||||
AllX(context.Background())
|
||||
```
|
||||
|
||||
We begin by transforming the user's question into a vector using the OpenAI API. Using this vector we would like
|
||||
to find the most similar embeddings in our database. We query the database for the embeddings, order them by similarity
|
||||
using `pgvector`'s `<->` operator, and limit the results to the top 5.
|
||||
|
||||
```go
|
||||
for _, e := range embs {
|
||||
chnk := e.Edges.Chunk
|
||||
b.WriteString(fmt.Sprintf("From file: %v\n", chnk.Path))
|
||||
b.WriteString(chnk.Data)
|
||||
}
|
||||
query := fmt.Sprintf(`Use the below information from the ent docs to answer the subsequent question.
|
||||
Information:
|
||||
%v
|
||||
|
||||
Question: %v`, b.String(), question)
|
||||
```
|
||||
Next, we prepare the information from the top 5 chunks to be used as context for the question. We then format the
|
||||
question and the context into a single string.
|
||||
|
||||
```go
|
||||
oac := openai.NewClient(ctx.OpenAIKey)
|
||||
resp, err := oac.CreateChatCompletion(
|
||||
context.Background(),
|
||||
openai.ChatCompletionRequest{
|
||||
Model: openai.GPT4o,
|
||||
Messages: []openai.ChatCompletionMessage{
|
||||
|
||||
{
|
||||
Role: openai.ChatMessageRoleUser,
|
||||
Content: query,
|
||||
},
|
||||
},
|
||||
},
|
||||
)
|
||||
if err != nil {
|
||||
return fmt.Errorf("error creating chat completion: %v", err)
|
||||
}
|
||||
choice := resp.Choices[0]
|
||||
out, err := glamour.Render(choice.Message.Content, "dark")
|
||||
fmt.Print(out)
|
||||
```
|
||||
Then, we use the OpenAI API to generate a response to the question. We pass the question and context to the API
|
||||
and receive a response. We then render the response using the `glamour` package to display it in the terminal.
|
||||
|
||||
Before running the `ask` command, let's install the `glamour` package:
|
||||
|
||||
```bash
|
||||
go get github.com/charmbracelet/glamour
|
||||
```
|
||||
|
||||
Finally, let's run the `ask` command to ask a question about the indexed documents:
|
||||
|
||||
```bash
|
||||
go run ./cmd/entrag ask "tl;dr What is Ent?"
|
||||
```
|
||||
|
||||
And our RAG system responds:
|
||||
|
||||
```
|
||||
Ent is an open-source entity framework (ORM) for the Go programming language. It
|
||||
allows developers to define data models or graph-structures in Go code. Ent
|
||||
emphasizes principles such as schema as code, a statically typed and explicit
|
||||
API generated through codegen, simple queries and graph traversals, statically
|
||||
typed predicates, and storage agnosticism. It supports various databases,
|
||||
including MySQL, MariaDB, PostgreSQL, SQLite, and Gremlin-based graph databases,
|
||||
and aims to enhance productivity in Go development.
|
||||
```
|
||||
|
||||
Amazing! We have successfully built a RAG system using Ent, Atlas, and pgvector.
|
||||
We can now ask questions about the documents we loaded into the database and receive context-aware responses.
|
||||
|
||||
Here are some more Q&As with our nifty RAG system:
|
||||
|
||||
<details>
|
||||
<summary>go run ./cmd/entrag ask "how to define order field in entgql"</summary>
|
||||
To define an order field in entgql , you need to annotate a field in your Ent
|
||||
schema using the entgql.Annotation with the OrderField . Here's a step-by-
|
||||
step
|
||||
guide on how you can do it:
|
||||
|
||||
1. Choose a Comparable Field: Select the field in your schema that you want to
|
||||
be orderable. This could be a text field, a timestamp, an integer, an enum, etc.
|
||||
2. Annotate the Field: Use the entgql.OrderField annotation on the chosen
|
||||
field. The order field name should be uppercase and match its corresponding enum
|
||||
value in the GraphQL schema.
|
||||
3. Update your Schema: Here’s an example of how to annotate your fields in the
|
||||
ent/schema :
|
||||
```go
|
||||
func (Todo) Fields() []ent.Field {
|
||||
return []ent.Field{
|
||||
field.Text("text").
|
||||
NotEmpty().
|
||||
Annotations(
|
||||
entgql.OrderField("TEXT"),
|
||||
),
|
||||
field.Time("created_at").
|
||||
Default(time.Now).
|
||||
Immutable().
|
||||
Annotations(
|
||||
entgql.OrderField("CREATED_AT"),
|
||||
),
|
||||
field.Enum("status").
|
||||
NamedValues(
|
||||
"InProgress", "IN_PROGRESS",
|
||||
"Completed", "COMPLETED",
|
||||
).
|
||||
Default("IN_PROGRESS").
|
||||
Annotations(
|
||||
entgql.OrderField("STATUS"),
|
||||
),
|
||||
field.Int("priority").
|
||||
Default(0).
|
||||
Annotations(
|
||||
entgql.OrderField("PRIORITY"),
|
||||
),
|
||||
}
|
||||
}
|
||||
```
|
||||
4. Alternatively, Multiple Order Fields: If you want to enable ordering by
|
||||
multiple fields, you can use the entgql.MultiOrder() annotation:
|
||||
```go
|
||||
func (Todo) Annotations() []schema.Annotation {
|
||||
return []schema.Annotation{
|
||||
entgql.MultiOrder(),
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
5. Generate GraphQL Types: Ensure that the GraphQL types match this setup in
|
||||
your GraphQL schema, for example:
|
||||
```graphql
|
||||
enum OrderDirection {
|
||||
ASC
|
||||
DESC
|
||||
}
|
||||
enum TodoOrderField {
|
||||
CREATED_AT
|
||||
PRIORITY
|
||||
STATUS
|
||||
TEXT
|
||||
}
|
||||
input TodoOrder {
|
||||
direction: OrderDirection!
|
||||
field: TodoOrderField
|
||||
}
|
||||
```
|
||||
|
||||
6. Add orderBy Argument to Queries: Include the orderBy parameter in your
|
||||
GraphQL queries to allow clients to sort items:
|
||||
```graphql
|
||||
type Query {
|
||||
todos(
|
||||
after: Cursor
|
||||
first: Int
|
||||
before: Cursor
|
||||
last: Int
|
||||
orderBy: TodoOrder
|
||||
): TodoConnection!
|
||||
}
|
||||
```
|
||||
|
||||
By following these steps, you ensure that your Ent-based application can support
|
||||
sorting in your GraphQL API based on various fields.
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary> go run ./cmd/entrag ask "what's the difference between privacy rules and interceptors" </summary>
|
||||
Privacy rules and interceptors serve different purposes within the Ent
|
||||
framework, each providing distinct functionalities:
|
||||
|
||||
1. Privacy Rules:
|
||||
* Purpose: Privacy rules are primarily concerned with enforcing access
|
||||
control policies for data queries and mutations. They determine whether an
|
||||
operation is allowed or denied based on predefined rules.
|
||||
* Implementation: They are implemented as part of a privacy policy using the
|
||||
ent.Policy interface which includes EvalQuery and EvalMutation methods.
|
||||
* Operation: Privacy rules evaluate whether specific conditions are met
|
||||
before allowing or denying access to the data. They can return decisions
|
||||
like privacy.Allow , privacy.Deny , or privacy.Skip to control the flow
|
||||
of evaluation.
|
||||
* Use Case: Ideal for managing access control by ensuring that users can
|
||||
only perform certain operations if they meet the specified criteria.
|
||||
2. Interceptors:
|
||||
* Purpose: Interceptors act as middleware for Ent queries, allowing
|
||||
modification and customization of query behaviors. They can be used to
|
||||
augment or modify queries during different stages of their lifecycle.
|
||||
* Implementation: Implemented as interfaces or using the ent.InterceptFunc
|
||||
adapter. They intercept and potentially modify queries by working on the
|
||||
read-path.
|
||||
* Operation: Interceptors modify or enhance queries, typically without the
|
||||
access control logic inherent in privacy rules. They provide hooks to
|
||||
execute custom logic pre and post query execution.
|
||||
* Use Case: Suitable for generic transformations or modifications to queries,
|
||||
such as adding default filters, query limitations, or logging operations
|
||||
without focusing on access control.
|
||||
|
||||
|
||||
In summary, while privacy rules focus on access control, interceptors are about
|
||||
managing and modifying the query execution process.
|
||||
</details>
|
||||
|
||||
### Wrapping up
|
||||
|
||||
In this blog post, we explored how to build a RAG system using Ent, Atlas, and pgvector. Special thanks to
|
||||
[Eli Bendersky](https://eli.thegreenplace.net/2023/retrieval-augmented-generation-in-go/) for the informative
|
||||
blog post and for his great Go writing over the years!
|
||||
34
doc/website/crowdin.yaml
Normal file
34
doc/website/crowdin.yaml
Normal file
@@ -0,0 +1,34 @@
|
||||
#
|
||||
# Crowdin credentials
|
||||
#
|
||||
"project_id" : "446988"
|
||||
"api_token_env" : "CROWDIN_TOKEN"
|
||||
"base_path" : ".."
|
||||
"base_url" : "https://api.crowdin.com"
|
||||
|
||||
#
|
||||
# Choose file structure in Crowdin
|
||||
# e.g. true or false
|
||||
#
|
||||
"preserve_hierarchy": true
|
||||
|
||||
#
|
||||
# Files configuration
|
||||
#
|
||||
files: [
|
||||
# JSON translation files
|
||||
{
|
||||
source: '/website/i18n/en/**/*',
|
||||
translation: '/website/i18n/%two_letters_code%/**/%original_file_name%',
|
||||
},
|
||||
# Docs Markdown files
|
||||
{
|
||||
source: '/md/**/*',
|
||||
translation: '/website/i18n/%two_letters_code%/docusaurus-plugin-content-docs/current/**/%original_file_name%',
|
||||
},
|
||||
# Blog Markdown files
|
||||
{
|
||||
source: '/website/blog/**/*',
|
||||
translation: '/website/i18n/%two_letters_code%/docusaurus-plugin-content-blog/**/%original_file_name%',
|
||||
},
|
||||
]
|
||||
246
doc/website/docusaurus.config.js
Normal file
246
doc/website/docusaurus.config.js
Normal file
@@ -0,0 +1,246 @@
|
||||
const TwitterSvg =
|
||||
'<svg style="fill: #1DA1F2; vertical-align: middle;" width="16" height="16" xmlns="http://www.w3.org/2000/svg" viewBox="0 0 512 512"><path d="M459.37 151.716c.325 4.548.325 9.097.325 13.645 0 138.72-105.583 298.558-298.558 298.558-59.452 0-114.68-17.219-161.137-47.106 8.447.974 16.568 1.299 25.34 1.299 49.055 0 94.213-16.568 130.274-44.832-46.132-.975-84.792-31.188-98.112-72.772 6.498.974 12.995 1.624 19.818 1.624 9.421 0 18.843-1.3 27.614-3.573-48.081-9.747-84.143-51.98-84.143-102.985v-1.299c13.969 7.797 30.214 12.67 47.431 13.319-28.264-18.843-46.781-51.005-46.781-87.391 0-19.492 5.197-37.36 14.294-52.954 51.655 63.675 129.3 105.258 216.365 109.807-1.624-7.797-2.599-15.918-2.599-24.04 0-57.828 46.782-104.934 104.934-104.934 30.213 0 57.502 12.67 76.67 33.137 23.715-4.548 46.456-13.32 66.599-25.34-7.798 24.366-24.366 44.833-46.132 57.827 21.117-2.273 41.584-8.122 60.426-16.243-14.292 20.791-32.161 39.308-52.628 54.253z"></path></svg>';
|
||||
|
||||
const config = {
|
||||
"title": "ent",
|
||||
"i18n": {
|
||||
"defaultLocale": 'en',
|
||||
"locales": ['en', 'zh', 'ja', 'he'],
|
||||
"localeConfigs": {
|
||||
"en": {
|
||||
"label": 'English',
|
||||
"direction": 'ltr',
|
||||
},
|
||||
"zh": {
|
||||
"label": 'Chinese',
|
||||
"direction": 'ltr',
|
||||
},
|
||||
"ja": {
|
||||
"label": 'Japanese',
|
||||
"direction": 'ltr',
|
||||
},
|
||||
"he": {
|
||||
"label": 'Hebrew',
|
||||
"direction": 'rtl',
|
||||
},
|
||||
},
|
||||
},
|
||||
"tagline": "An entity framework for Go",
|
||||
"url": "https://entgo.io",
|
||||
"baseUrl": "/",
|
||||
"organizationName": "ent",
|
||||
"projectName": "ent",
|
||||
"scripts": [
|
||||
"https://cdnjs.cloudflare.com/ajax/libs/clipboard.js/2.0.0/clipboard.min.js",
|
||||
"/js/code-block-buttons.js",
|
||||
"/js/custom.js"
|
||||
],
|
||||
"favicon": "img/favicon.ico",
|
||||
"customFields": {
|
||||
"users": [
|
||||
],
|
||||
"slackChannel": "/docs/community#slack",
|
||||
"newsletter": "https://entgo.substack.com/",
|
||||
"githubRepo": "https://github.com/ent/ent"
|
||||
},
|
||||
"onBrokenLinks": "log",
|
||||
"onBrokenMarkdownLinks": "log",
|
||||
"presets": [
|
||||
[
|
||||
"@docusaurus/preset-classic",
|
||||
{
|
||||
"docs": {
|
||||
path: "../md",
|
||||
editUrl: 'https://github.com/ent/ent/edit/master/doc/md/',
|
||||
showLastUpdateAuthor: true,
|
||||
showLastUpdateTime: true,
|
||||
sidebarPath: require.resolve('./sidebars.js'),
|
||||
},
|
||||
gtag: {
|
||||
trackingID: "UA-189726777-1",
|
||||
},
|
||||
"blog": {
|
||||
"feedOptions": {
|
||||
"type": 'all',
|
||||
"copyright": `Copyright © ${new Date().getFullYear()}, The Ent Authors.`,
|
||||
},
|
||||
"path": "blog",
|
||||
"blogSidebarCount": 'ALL',
|
||||
"blogSidebarTitle": 'All our posts',
|
||||
},
|
||||
"theme": {
|
||||
"customCss": require.resolve('./src/css/custom.css'),
|
||||
}
|
||||
}
|
||||
]
|
||||
],
|
||||
"plugins": [
|
||||
[
|
||||
`@docusaurus/plugin-client-redirects`,{
|
||||
redirects: [
|
||||
{
|
||||
to:'/docs/community',
|
||||
from:'/docs/slack',
|
||||
},
|
||||
],
|
||||
},
|
||||
]
|
||||
],
|
||||
"themeConfig": {
|
||||
prism: {
|
||||
additionalLanguages: ['gotemplate', 'protobuf', "hcl"],
|
||||
magicComments: [
|
||||
{
|
||||
className: 'theme-code-block-highlighted-line',
|
||||
line: 'highlight-next-line',
|
||||
block: {start: 'highlight-start', end: 'highlight-end'},
|
||||
},
|
||||
{
|
||||
className: 'code-block-error-message',
|
||||
line: 'highlight-next-line-error-message',
|
||||
},
|
||||
{
|
||||
className: 'code-block-info-line',
|
||||
line: 'highlight-next-line-info',
|
||||
block: {start: 'highlight-info-start', end: 'highlight-info-end'},
|
||||
},
|
||||
],
|
||||
},
|
||||
algolia: {
|
||||
appId: "8OIT9XHKR1",
|
||||
apiKey: "42c78b88ab39bda9adad782eba9e2aa2",
|
||||
indexName: "entgo",
|
||||
},
|
||||
colorMode: {
|
||||
disableSwitch: false,
|
||||
},
|
||||
"navbar": {
|
||||
"title": "",
|
||||
"logo": {
|
||||
"src": "img/logo.png"
|
||||
},
|
||||
"items": [
|
||||
{
|
||||
"to": "docs/getting-started",
|
||||
"label": "Docs",
|
||||
"position": "left"
|
||||
},
|
||||
{
|
||||
"to": "docs/tutorial-setup",
|
||||
"label": "Tutorials",
|
||||
"position": "left"
|
||||
},
|
||||
{
|
||||
"href": "https://pkg.go.dev/entgo.io/ent?tab=doc",
|
||||
"label": "GoDoc",
|
||||
"position": "left",
|
||||
"className": "header-godoc-link",
|
||||
},
|
||||
{to: 'blog', label: 'Blog', position: 'left'},
|
||||
{
|
||||
href: '/docs/community#slack',
|
||||
position: 'right',
|
||||
className: 'header-slack-link',
|
||||
'aria-label': 'Slack channel',
|
||||
},
|
||||
{
|
||||
href: 'https://discord.gg/qZmPgTE6RX',
|
||||
position: 'right',
|
||||
className: 'header-discord-link',
|
||||
'aria-label': 'Discord Server',
|
||||
},
|
||||
{
|
||||
href: 'https://entgo.substack.com/',
|
||||
position: 'right',
|
||||
className: 'header-newsletter-link',
|
||||
'aria-label': 'Newsletter page',
|
||||
},
|
||||
{
|
||||
href: 'https://twitter.com/entgo_io',
|
||||
position: 'right',
|
||||
className: 'header-twitter-link',
|
||||
'aria-label': 'Twitter page',
|
||||
},
|
||||
{
|
||||
href: 'https://github.com/ent/ent',
|
||||
position: 'right',
|
||||
className: 'header-github-link',
|
||||
'aria-label': 'GitHub repository',
|
||||
},
|
||||
{
|
||||
type: 'localeDropdown',
|
||||
position: 'right',
|
||||
dropdownItemsAfter: [
|
||||
{
|
||||
to: '/docs/translations',
|
||||
label: 'Help Us Translate',
|
||||
},
|
||||
],
|
||||
},
|
||||
]
|
||||
},
|
||||
"image": "img/undraw_online.svg",
|
||||
ogImage: 'img/undraw_online.svg',
|
||||
twitterImage: 'img/undraw_tweetstorm.svg',
|
||||
"footer": {
|
||||
"links": [
|
||||
{
|
||||
"title": "Docs",
|
||||
"items": [
|
||||
{"label": "Getting Started", "to": "/docs/getting-started"},
|
||||
{"label": "Schema Guide", "to": "/docs/schema-def"},
|
||||
{"label": "Code Generation", "to": "/docs/code-gen"},
|
||||
{"label": "GraphQL Integration", "to": "/docs/graphql"},
|
||||
{"label": "Schema Migration", "to": "/docs/migrate"},
|
||||
]
|
||||
},
|
||||
{
|
||||
"title": "Community",
|
||||
"items": [
|
||||
{"label": "GitHub", "to": "https://github.com/ent/ent"},
|
||||
{"label": "Slack", "to": "/docs/community#slack"},
|
||||
{"label": "Discord", "to": "https://discord.gg/qZmPgTE6RX"},
|
||||
{"label": "Newsletter", "to": "https://entgo.substack.com/"},
|
||||
{"label": "Discussions", "to": "https://github.com/ent/ent/discussions"},
|
||||
{
|
||||
"label": "Twitter",
|
||||
"to": "https://twitter.com/entgo_io"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"title": "Social",
|
||||
"items": [
|
||||
{"html": `
|
||||
<a href="https://github.com/ent/ent/stargazers">
|
||||
<img src="https://img.shields.io/github/stars/ent/ent?style=social"/>
|
||||
</a>`},
|
||||
{"html": `
|
||||
<a href="https://twitter.com/entgo_io">
|
||||
<img src="https://img.shields.io/twitter/follow/entgo_io?style=social"/>
|
||||
</a>`}
|
||||
]
|
||||
}
|
||||
],
|
||||
copyright: `
|
||||
Copyright © ${new Date().getFullYear()}, The Ent Authors.
|
||||
The Go gopher was designed by <a href="http://reneefrench.blogspot.com/">Renee French</a>.
|
||||
<br/>
|
||||
The design is licensed under the Creative Commons 3.0 Attributions license. Read this
|
||||
<a href="https://go.dev/blog/gopher">article</a> for more details.
|
||||
<br/>
|
||||
Design by Moriah Rich, illustration by Ariel Mashraki.
|
||||
`,
|
||||
},
|
||||
announcementBar: {
|
||||
id: 'announcementBar-2', // Increment on change
|
||||
// content: `⭐️ If you like Ent, give it a star on <a target="_blank" rel="noopener noreferrer" href="https://github.com/ent/ent">GitHub</a> and follow us on <a target="_blank" rel="noopener noreferrer" href="https://twitter.com/entgo_io" >Twitter</a> ${TwitterSvg}`,
|
||||
content: `<a style="text-decoration: none;" target="_blank" rel="noopener noreferrer" href="https://twitter.com/Israel/status/1713931519620788538">The Ent Team Stands With Israel 🇮🇱</a>`,
|
||||
backgroundColor: '#fafbfc',
|
||||
textColor: '#404756',
|
||||
isCloseable: false,
|
||||
},
|
||||
}
|
||||
};
|
||||
|
||||
module.exports = config;
|
||||
35
doc/website/package.json
Normal file
35
doc/website/package.json
Normal file
@@ -0,0 +1,35 @@
|
||||
{
|
||||
"scripts": {
|
||||
"examples": "docusaurus-examples",
|
||||
"start": "NODE_OPTIONS=--openssl-legacy-provider docusaurus start",
|
||||
"build": "docusaurus build",
|
||||
"publish-gh-pages": "docusaurus-publish",
|
||||
"write-translations": "docusaurus write-translations",
|
||||
"version": "docusaurus-version",
|
||||
"rename-version": "docusaurus-rename-version",
|
||||
"swizzle": "docusaurus swizzle",
|
||||
"deploy": "docusaurus deploy",
|
||||
"docusaurus": "docusaurus",
|
||||
"crowdin": "crowdin",
|
||||
"crowdin:sync": "docusaurus write-translations && crowdin upload && crowdin download"
|
||||
},
|
||||
"dependencies": {
|
||||
"@crowdin/cli": "3",
|
||||
"@docusaurus/core": "^2.4.3",
|
||||
"@docusaurus/plugin-client-redirects": "^2.4.3",
|
||||
"@docusaurus/preset-classic": "^2.4.3",
|
||||
"clsx": "^1.1.1",
|
||||
"docusaurus": "^1.14.7",
|
||||
"react": "^17.0.1",
|
||||
"react-dom": "^17.0.1",
|
||||
"react-github-btn": "^1.2.0"
|
||||
},
|
||||
"resolutions": {
|
||||
"glob-parent": "^5.1.2",
|
||||
"trim": "^0.0.3",
|
||||
"browserslist": "^4.16.5",
|
||||
"axios": "0.21.3",
|
||||
"set-value": "^4.0.1",
|
||||
"immer": "^9.0.6"
|
||||
}
|
||||
}
|
||||
167
doc/website/sidebars.js
Normal file
167
doc/website/sidebars.js
Normal file
@@ -0,0 +1,167 @@
|
||||
module.exports = {
|
||||
md: [
|
||||
{
|
||||
type: 'category',
|
||||
label: 'Getting Started',
|
||||
items: [
|
||||
'getting-started',
|
||||
],
|
||||
collapsed: false,
|
||||
},
|
||||
{
|
||||
type: 'category',
|
||||
label: 'Schema',
|
||||
items: [
|
||||
'schema-def',
|
||||
'schema-fields',
|
||||
'schema-edges',
|
||||
'schema-indexes',
|
||||
'schema-views',
|
||||
'schema-mixin',
|
||||
'schema-annotations',
|
||||
],
|
||||
collapsed: false,
|
||||
},
|
||||
{
|
||||
type: 'category',
|
||||
label: 'Code Generation',
|
||||
items: [
|
||||
'code-gen',
|
||||
'crud',
|
||||
'traversals',
|
||||
'eager-load',
|
||||
'hooks',
|
||||
'interceptors',
|
||||
'privacy',
|
||||
'transactions',
|
||||
'predicates',
|
||||
'aggregate',
|
||||
'paging',
|
||||
],
|
||||
collapsed: false,
|
||||
},
|
||||
{
|
||||
type: 'category',
|
||||
label: 'Migration',
|
||||
items: [
|
||||
'versioned-migrations',
|
||||
{
|
||||
type: 'category',
|
||||
label: 'External Objects',
|
||||
items: [
|
||||
{type: 'doc', id: 'migration/composite', label: 'Composite Types'},
|
||||
{type: 'doc', id: 'migration/domain', label: 'Domain Types'},
|
||||
{type: 'doc', id: 'migration/enum', label: 'Enum Types'},
|
||||
{type: 'doc', id: 'migration/extension', label: 'Extensions'},
|
||||
{type: 'doc', id: 'migration/functional-indexes', label: 'Functional Indexes'},
|
||||
{type: 'doc', id: 'migration/rls', label: 'Row-Level Security'},
|
||||
{type: 'doc', id: 'migration/trigger', label: 'Triggers'},
|
||||
],
|
||||
collapsed: false,
|
||||
},
|
||||
'multischema-migrations',
|
||||
'migrate',
|
||||
'data-migrations',
|
||||
'dialects',
|
||||
],
|
||||
collapsed: false,
|
||||
},
|
||||
{
|
||||
type: 'category',
|
||||
label: 'Misc',
|
||||
items: [
|
||||
'templates',
|
||||
'extensions',
|
||||
'graphql',
|
||||
'sql-integration',
|
||||
'ci',
|
||||
'testing',
|
||||
'faq',
|
||||
'feature-flags',
|
||||
'generating-ent-schemas',
|
||||
'translations',
|
||||
'contributors',
|
||||
'writing-docs',
|
||||
'community'
|
||||
],
|
||||
collapsed: false,
|
||||
},
|
||||
],
|
||||
tutorial: [
|
||||
{
|
||||
type: 'category',
|
||||
label: 'First Steps',
|
||||
items: [
|
||||
'tutorial-setup',
|
||||
'tutorial-todo-crud',
|
||||
],
|
||||
collapsed: false,
|
||||
},
|
||||
{
|
||||
type: 'category',
|
||||
label: 'GraphQL Basics',
|
||||
items: [
|
||||
'tutorial-todo-gql',
|
||||
'tutorial-todo-gql-node',
|
||||
'tutorial-todo-gql-paginate',
|
||||
'tutorial-todo-gql-field-collection',
|
||||
'tutorial-todo-gql-tx-mutation',
|
||||
'tutorial-todo-gql-mutation-input',
|
||||
'tutorial-todo-gql-filter-input',
|
||||
'tutorial-todo-gql-schema-generator',
|
||||
],
|
||||
collapsed: false,
|
||||
},
|
||||
{
|
||||
type: 'category',
|
||||
collapsed: false,
|
||||
label: 'gRPC',
|
||||
items: [
|
||||
'grpc-intro',
|
||||
'grpc-setting-up',
|
||||
'grpc-generating-proto',
|
||||
'grpc-generating-a-service',
|
||||
'grpc-server-and-client',
|
||||
'grpc-edges',
|
||||
'grpc-optional-fields',
|
||||
'grpc-service-generation-options',
|
||||
'grpc-external-service',
|
||||
]
|
||||
},
|
||||
{
|
||||
type: 'category',
|
||||
collapsed: false,
|
||||
label: 'Versioned Migrations',
|
||||
items: [
|
||||
{
|
||||
type: 'doc',
|
||||
id: 'versioned/intro',
|
||||
},
|
||||
{
|
||||
type: 'doc',
|
||||
id: 'versioned/auto-plan',
|
||||
},
|
||||
{
|
||||
type: 'doc',
|
||||
id: 'versioned/upgrade-prod',
|
||||
},
|
||||
{
|
||||
type: 'doc',
|
||||
id: 'versioned/new-migration',
|
||||
},
|
||||
{
|
||||
type: 'doc',
|
||||
id: 'versioned/custom-migrations',
|
||||
},
|
||||
{
|
||||
type: 'doc',
|
||||
id: 'versioned/verifying-safety',
|
||||
},
|
||||
{
|
||||
type: 'doc',
|
||||
id: 'versioned/programmatically',
|
||||
},
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
39
doc/website/src/css/code-block-buttons.css
Normal file
39
doc/website/src/css/code-block-buttons.css
Normal file
@@ -0,0 +1,39 @@
|
||||
/* "Copy" code block button */
|
||||
pre {
|
||||
position: relative;
|
||||
}
|
||||
|
||||
pre .btnIcon {
|
||||
position: absolute;
|
||||
top: 4px;
|
||||
z-index: 2;
|
||||
cursor: pointer;
|
||||
border: 1px solid transparent;
|
||||
padding: 0;
|
||||
color: #fff;
|
||||
background-color: transparent;
|
||||
height: 30px;
|
||||
transition: all .25s ease-out;
|
||||
}
|
||||
|
||||
pre .btnIcon:hover {
|
||||
text-decoration: none;
|
||||
}
|
||||
|
||||
.btnIcon__body {
|
||||
align-items: center;
|
||||
display: flex;
|
||||
}
|
||||
|
||||
.btnIcon svg {
|
||||
fill: currentColor;
|
||||
margin-right: .4em;
|
||||
}
|
||||
|
||||
.btnIcon__label {
|
||||
font-size: 11px;
|
||||
}
|
||||
|
||||
.btnClipboard {
|
||||
right: 10px;
|
||||
}
|
||||
819
doc/website/src/css/custom.css
Normal file
819
doc/website/src/css/custom.css
Normal file
File diff suppressed because one or more lines are too long
BIN
doc/website/src/img/favicon.ico
Normal file
BIN
doc/website/src/img/favicon.ico
Normal file
Binary file not shown.
|
After Width: | Height: | Size: 806 B |
BIN
doc/website/src/img/logo.png
Normal file
BIN
doc/website/src/img/logo.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 1.3 KiB |
47
doc/website/src/js/code-block-buttons.js
Normal file
47
doc/website/src/js/code-block-buttons.js
Normal file
@@ -0,0 +1,47 @@
|
||||
// Turn off ESLint for this file because it's sent down to users as-is.
|
||||
/* eslint-disable */
|
||||
window.addEventListener('load', function() {
|
||||
function button(label, ariaLabel, icon, className) {
|
||||
const btn = document.createElement('button');
|
||||
btn.classList.add('btnIcon', className);
|
||||
btn.setAttribute('type', 'button');
|
||||
btn.setAttribute('aria-label', ariaLabel);
|
||||
btn.innerHTML =
|
||||
'<div class="btnIcon__body">' +
|
||||
icon +
|
||||
'<strong class="btnIcon__label">' +
|
||||
label +
|
||||
'</strong>' +
|
||||
'</div>';
|
||||
return btn;
|
||||
}
|
||||
|
||||
function addButtons(codeBlockSelector, btn) {
|
||||
document.querySelectorAll(codeBlockSelector).forEach(function(code) {
|
||||
code.parentNode.appendChild(btn.cloneNode(true));
|
||||
});
|
||||
}
|
||||
|
||||
const copyIcon =
|
||||
'<svg width="12" height="12" viewBox="340 364 14 15" xmlns="http://www.w3.org/2000/svg"><path fill="currentColor" d="M342 375.974h4v.998h-4v-.998zm5-5.987h-5v.998h5v-.998zm2 2.994v-1.995l-3 2.993 3 2.994v-1.996h5v-1.995h-5zm-4.5-.997H342v.998h2.5v-.997zm-2.5 2.993h2.5v-.998H342v.998zm9 .998h1v1.996c-.016.28-.11.514-.297.702-.187.187-.422.28-.703.296h-10c-.547 0-1-.452-1-.998v-10.976c0-.546.453-.998 1-.998h3c0-1.107.89-1.996 2-1.996 1.11 0 2 .89 2 1.996h3c.547 0 1 .452 1 .998v4.99h-1v-2.995h-10v8.98h10v-1.996zm-9-7.983h8c0-.544-.453-.996-1-.996h-1c-.547 0-1-.453-1-.998 0-.546-.453-.998-1-.998-.547 0-1 .452-1 .998 0 .545-.453.998-1 .998h-1c-.547 0-1 .452-1 .997z" fill-rule="evenodd"/></svg>';
|
||||
|
||||
addButtons(
|
||||
'.hljs',
|
||||
button('Copy', 'Copy code to clipboard', copyIcon, 'btnClipboard'),
|
||||
);
|
||||
|
||||
const clipboard = new ClipboardJS('.btnClipboard', {
|
||||
target: function(trigger) {
|
||||
return trigger.parentNode.querySelector('code');
|
||||
},
|
||||
});
|
||||
|
||||
clipboard.on('success', function(event) {
|
||||
event.clearSelection();
|
||||
const textEl = event.trigger.querySelector('.btnIcon__label');
|
||||
textEl.textContent = 'Copied';
|
||||
setTimeout(function() {
|
||||
textEl.textContent = 'Copy';
|
||||
}, 2000);
|
||||
});
|
||||
});
|
||||
17
doc/website/src/js/custom.js
Normal file
17
doc/website/src/js/custom.js
Normal file
@@ -0,0 +1,17 @@
|
||||
|
||||
/**
|
||||
* Copyright 2019-present Facebook Inc. All rights reserved.
|
||||
*
|
||||
* This source code is licensed under the Apache 2.0 license found
|
||||
* in the LICENSE file in the root directory of this source tree.
|
||||
*
|
||||
* @format
|
||||
*/
|
||||
|
||||
/* eslint-disable */
|
||||
window.addEventListener('load', function() {
|
||||
// add an id tag for images based on their alt attribute.
|
||||
document.querySelectorAll('.container img').forEach(function(el) {
|
||||
el.id = el.alt;
|
||||
});
|
||||
});
|
||||
201
doc/website/src/pages/index.js
Normal file
201
doc/website/src/pages/index.js
Normal file
@@ -0,0 +1,201 @@
|
||||
|
||||
/**
|
||||
* Copyright 2019-present Facebook Inc. All rights reserved.
|
||||
*
|
||||
* This source code is licensed under the Apache 2.0 license found
|
||||
* in the LICENSE file in the root directory of this source tree.
|
||||
*
|
||||
* @format
|
||||
*/
|
||||
|
||||
const React = require('react');
|
||||
import LayoutProvider from '@theme/Layout/Provider';
|
||||
import Footer from '@theme/Footer';
|
||||
import Link from '@docusaurus/Link';
|
||||
|
||||
|
||||
const CompLibrary = {
|
||||
Container: props => <div {...props}></div>,
|
||||
GridBlock: props => <div {...props}></div>,
|
||||
MarkdownBlock: props => <div {...props}></div>
|
||||
};
|
||||
|
||||
import Layout from "@theme/Layout";
|
||||
|
||||
const MarkdownBlock = CompLibrary.MarkdownBlock;/* Used to read markdown */
|
||||
const Container = CompLibrary.Container;
|
||||
const GridBlock = CompLibrary.GridBlock;
|
||||
|
||||
const arrow = '\u2192';
|
||||
|
||||
const Block = props => (
|
||||
<div className="block">
|
||||
<div className="blockTitle">
|
||||
<a href={props.link}>
|
||||
<div className="blockTitleText">{props.title}</div>{' '}
|
||||
</a>
|
||||
<a className="yellowArrow" href={props.link}>{arrow}</a>
|
||||
</div>
|
||||
<div className="blockContent">{props.content}</div>
|
||||
</div>
|
||||
);
|
||||
|
||||
const Features = () => (
|
||||
<div className="features">
|
||||
<Block
|
||||
title="Schema As Code"
|
||||
content="Simple API for modeling any database schema as Go objects"
|
||||
link="docs/schema-def"
|
||||
/>
|
||||
<Block
|
||||
title="Easily Traverse Any Graph"
|
||||
content="Run queries, aggregations and traverse any graph structure easily"
|
||||
link="docs/traversals"
|
||||
/>
|
||||
<Block
|
||||
title="Statically Typed And Explicit API"
|
||||
content="100% statically typed and explicit API using code generation"
|
||||
link="docs/code-gen"
|
||||
/>
|
||||
</div>
|
||||
);
|
||||
|
||||
class HomeSplash extends React.Component {
|
||||
render() {
|
||||
const {siteConfig, language = ''} = this.props;
|
||||
const {baseUrl, docsUrl} = siteConfig;
|
||||
const docsPart = `${docsUrl ? `${docsUrl}/` : ''}`;
|
||||
const langPart = `${language ? `${language}/` : ''}`;
|
||||
const docUrl = doc => `${baseUrl}${docsPart}${langPart}${doc}`;
|
||||
|
||||
const SplashContainer = props => (
|
||||
<div className="homeContainer">
|
||||
<div className="homeSplashFade">
|
||||
<div className="wrapper homeWrapper">{props.children}</div>
|
||||
</div>
|
||||
</div>
|
||||
);
|
||||
|
||||
const Logo = props => (
|
||||
<div className="projectLogo">
|
||||
<img src={props.img_src} alt="Project Logo" />
|
||||
</div>
|
||||
);
|
||||
|
||||
const ProjectTitle = () => (
|
||||
<div>
|
||||
<div className="projectTitleContainer">
|
||||
<img src="https://entgo.io/images/assets/logo.png" />
|
||||
<div className="projectTitle">
|
||||
<p>{siteConfig.tagline}</p>
|
||||
</div>
|
||||
</div>
|
||||
<p className="projectDesc">
|
||||
Simple, yet powerful ORM for modeling and querying data.
|
||||
</p>
|
||||
</div>
|
||||
);
|
||||
|
||||
const PromoSection = props => (
|
||||
<div className="section promoSection">
|
||||
<div className="promoRow">
|
||||
<div className="pluginRowBlock">{props.children}</div>
|
||||
</div>
|
||||
</div>
|
||||
);
|
||||
|
||||
const Button = props => (
|
||||
<div className="pluginWrapper buttonWrapper">
|
||||
<a className="button" href={props.href} target={props.target}>
|
||||
{props.children}
|
||||
</a>
|
||||
</div>
|
||||
);
|
||||
|
||||
return (
|
||||
<SplashContainer>
|
||||
{/*<Logo img_src={`${baseUrl}img/undraw_monitor.svg`} />*/}
|
||||
<div className="inner">
|
||||
<ProjectTitle siteConfig={siteConfig} />
|
||||
<div className="gettingStartedButton">
|
||||
<a href="./docs/getting-started">
|
||||
<div className="gettingStartedButtonText">
|
||||
<div className="gettingStartedText">{'Getting Started '}</div>
|
||||
<div className="gettingStartedButtonArrow">{arrow}</div>
|
||||
</div>
|
||||
</a>
|
||||
</div>
|
||||
<div className="gopherGraph">
|
||||
<img src="https://entgo.io/images/assets/gopher_graph.png" />
|
||||
</div>
|
||||
<Features />
|
||||
</div>
|
||||
</SplashContainer>
|
||||
);
|
||||
}
|
||||
}
|
||||
|
||||
class HomeNav extends React.Component {
|
||||
render() {
|
||||
return <ul className="home-nav">
|
||||
<li className=""><Link to={"/docs/getting-started"}>Docs</Link></li>
|
||||
<li className=""><Link to="/docs/tutorial-setup">Tutorial</Link></li>
|
||||
<li className="header-godoc-link"><a href="https://pkg.go.dev/entgo.io/ent?tab=doc" target="_blank">GoDoc</a></li>
|
||||
<li className=""><a href="https://github.com/ent/ent" target="_blank">Github</a></li>
|
||||
<li className=""><Link to="/blog/">Blog</Link></li>
|
||||
</ul>
|
||||
}
|
||||
}
|
||||
|
||||
class Index extends React.Component {
|
||||
render() {
|
||||
const {config: siteConfig, language = ''} = this.props;
|
||||
const {baseUrl} = siteConfig;
|
||||
|
||||
const Showcase = () => {
|
||||
if ((siteConfig.users || []).length === 0) {
|
||||
return null;
|
||||
}
|
||||
|
||||
const showcase = siteConfig.users
|
||||
.filter(user => user.pinned)
|
||||
.map(user => (
|
||||
<a href={user.infoLink} key={user.infoLink}>
|
||||
<img src={user.image} alt={user.caption} title={user.caption} />
|
||||
</a>
|
||||
));
|
||||
|
||||
const pageUrl = page => baseUrl + (language ? `${language}/` : '') + page;
|
||||
|
||||
return (
|
||||
<div className="productShowcaseSection paddingBottom">
|
||||
<h2>Who is Using This?</h2>
|
||||
<p>This project is used by all these people</p>
|
||||
<div className="logos">{showcase}</div>
|
||||
<div className="more-users">
|
||||
<a className="button" href={pageUrl('users.html')}>
|
||||
More {siteConfig.title} Users
|
||||
</a>
|
||||
</div>
|
||||
</div>
|
||||
);
|
||||
};
|
||||
|
||||
return (
|
||||
<div className={"home-splash-container section_index"}>
|
||||
<HomeSplash siteConfig={siteConfig} language={language} />
|
||||
</div>
|
||||
);
|
||||
}
|
||||
}
|
||||
|
||||
export default function (props) {
|
||||
return <LayoutProvider>
|
||||
{/*<div className={"section_index"}>*/}
|
||||
{/* <Navbar/>*/}
|
||||
{/*</div>*/}
|
||||
<HomeNav />
|
||||
<Index {...props} />
|
||||
<Footer/>
|
||||
</LayoutProvider>;
|
||||
};
|
||||
12
doc/website/src/static/contrib/index.html
Normal file
12
doc/website/src/static/contrib/index.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta http-equiv="Content-Type" content="text/html; charset=utf-8"/>
|
||||
<meta name="go-import" content="entgo.io/contrib git https://github.com/ent/contrib">
|
||||
<meta name="go-source" content="entgo.io/contrib https://github.com/ent/contrib https://github.com/ent/contrib/tree/master{/dir} https://github.com/ent/contrib/blob/master{/dir}/{file}#L{line}">
|
||||
<meta http-equiv="refresh" content="0; url=https://pkg.go.dev/entgo.io/contrib">
|
||||
</head>
|
||||
<body>
|
||||
Nothing to see here; <a href="https://pkg.go.dev/entgo.io/contrib">move along</a>.
|
||||
</body>
|
||||
</html>
|
||||
12
doc/website/src/static/ent/cmd/ent/index.html
Normal file
12
doc/website/src/static/ent/cmd/ent/index.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta http-equiv="Content-Type" content="text/html; charset=utf-8"/>
|
||||
<meta name="go-import" content="entgo.io/ent git https://github.com/ent/ent">
|
||||
<meta name="go-source" content="entgo.io/ent https://github.com/ent/ent https://github.com/ent/ent/tree/master{/dir} https://github.com/ent/ent/blob/master{/dir}/{file}#L{line}">
|
||||
<meta http-equiv="refresh" content="0; url=https://pkg.go.dev/entgo.io/ent/cmd/ent">
|
||||
</head>
|
||||
<body>
|
||||
Nothing to see here; <a href="https://pkg.go.dev/entgo.io/ent/cmd/ent">move along</a>.
|
||||
</body>
|
||||
</html>
|
||||
12
doc/website/src/static/ent/cmd/entfix/index.html
Normal file
12
doc/website/src/static/ent/cmd/entfix/index.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta http-equiv="Content-Type" content="text/html; charset=utf-8"/>
|
||||
<meta name="go-import" content="entgo.io/ent git https://github.com/ent/ent">
|
||||
<meta name="go-source" content="entgo.io/ent https://github.com/ent/ent https://github.com/ent/ent/tree/master{/dir} https://github.com/ent/ent/blob/master{/dir}/{file}#L{line}">
|
||||
<meta http-equiv="refresh" content="0; url=https://pkg.go.dev/entgo.io/ent/entfix">
|
||||
</head>
|
||||
<body>
|
||||
Nothing to see here; <a href="https://pkg.go.dev/entgo.io/ent/entfix">move along</a>.
|
||||
</body>
|
||||
</html>
|
||||
12
doc/website/src/static/ent/entc/gen/index.html
Normal file
12
doc/website/src/static/ent/entc/gen/index.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta http-equiv="Content-Type" content="text/html; charset=utf-8"/>
|
||||
<meta name="go-import" content="entgo.io/ent git https://github.com/ent/ent">
|
||||
<meta name="go-source" content="entgo.io/ent https://github.com/ent/ent https://github.com/ent/ent/tree/master{/dir} https://github.com/ent/ent/blob/master{/dir}/{file}#L{line}">
|
||||
<meta http-equiv="refresh" content="0; url=https://pkg.go.dev/entgo.io/ent/entc/gen">
|
||||
</head>
|
||||
<body>
|
||||
Nothing to see here; <a href="https://pkg.go.dev/entgo.io/ent/entc/gen">move along</a>.
|
||||
</body>
|
||||
</html>
|
||||
12
doc/website/src/static/ent/entc/index.html
Normal file
12
doc/website/src/static/ent/entc/index.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta http-equiv="Content-Type" content="text/html; charset=utf-8"/>
|
||||
<meta name="go-import" content="entgo.io/ent git https://github.com/ent/ent">
|
||||
<meta name="go-source" content="entgo.io/ent https://github.com/ent/ent https://github.com/ent/ent/tree/master{/dir} https://github.com/ent/ent/blob/master{/dir}/{file}#L{line}">
|
||||
<meta http-equiv="refresh" content="0; url=https://pkg.go.dev/entgo.io/ent/entc">
|
||||
</head>
|
||||
<body>
|
||||
Nothing to see here; <a href="https://pkg.go.dev/entgo.io/ent/entc">move along</a>.
|
||||
</body>
|
||||
</html>
|
||||
12
doc/website/src/static/ent/index.html
Normal file
12
doc/website/src/static/ent/index.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta http-equiv="Content-Type" content="text/html; charset=utf-8"/>
|
||||
<meta name="go-import" content="entgo.io/ent git https://github.com/ent/ent">
|
||||
<meta name="go-source" content="entgo.io/ent https://github.com/ent/ent https://github.com/ent/ent/tree/master{/dir} https://github.com/ent/ent/blob/master{/dir}/{file}#L{line}">
|
||||
<meta http-equiv="refresh" content="0; url=https://pkg.go.dev/entgo.io/ent">
|
||||
</head>
|
||||
<body>
|
||||
Nothing to see here; <a href="https://pkg.go.dev/entgo.io/ent">move along</a>.
|
||||
</body>
|
||||
</html>
|
||||
83
doc/website/src/theme/prism-include-languages.js
Normal file
83
doc/website/src/theme/prism-include-languages.js
Normal file
@@ -0,0 +1,83 @@
|
||||
|
||||
/**
|
||||
* Copyright 2019-present Facebook Inc. All rights reserved.
|
||||
*
|
||||
* This source code is licensed under the Apache 2.0 license found
|
||||
* in the LICENSE file in the root directory of this source tree.
|
||||
*
|
||||
* @format
|
||||
*/
|
||||
|
||||
import ExecutionEnvironment from '@docusaurus/ExecutionEnvironment';
|
||||
|
||||
export default function(Prism) {
|
||||
Prism.languages.gotemplate = {
|
||||
'comment': [
|
||||
{
|
||||
pattern: /(^|[^\\])\/\*[\s\S]*?(?:\*\/|$)/,
|
||||
lookbehind: true,
|
||||
greedy: true
|
||||
},
|
||||
{
|
||||
pattern: /(^|[^\\:])\/\/.*/,
|
||||
lookbehind: true,
|
||||
greedy: true
|
||||
},
|
||||
/{{\/\*[\s\S]*\*\/}}/
|
||||
],
|
||||
'string': {
|
||||
pattern: /(["'])(?:\\(?:\r\n|[\s\S])|(?!\1)[^\\\r\n])*\1/,
|
||||
greedy: true
|
||||
},
|
||||
'boolean': /\b(?:_|iota|nil|true|false)\b/,
|
||||
'number': /(?:\b0x[a-f\d]+|(?:\b\d+(?:\.\d*)?|\B\.\d+)(?:e[-+]?\d+)?)i?/i,
|
||||
'operator': /[*\/%^!=]=?|\+[=+]?|-[=-]?|\|[=|]?|&(?:=|&|\^=?)?|>(?:>=?|=)?|<(?:<=?|=|-)?|:=|\.\.\./,
|
||||
'builtin': /\b(?:bool|byte|complex(?:64|128)|error|float(?:32|64)|rune|string|u?int(?:8|16|32|64)?|uintptr|append|cap|close|complex|copy|delete|imag|len|make|new|panic|print(?:ln)?|real|recover)\b/,
|
||||
'keyword': /\b(?:break|default|func|interface|select|case|map|struct|chan|else|goto|package|switch|const|fallthrough|if|range|type|continue|for|import|return|var|go|defer|bool|byte|complex64|complex128|float32|float64|int8|int16|int32|int64|string|uint8|uint16|uint32|uint64|int|uint|uintptr|rune|with|define|block|end)\b/,
|
||||
};
|
||||
|
||||
Prism.languages.protobuf = Prism.languages.extend('clike', {
|
||||
'class-name': [
|
||||
{
|
||||
pattern: /(\b(?:enum|extend|message|service)\s+)[A-Za-z_]\w*(?=\s*\{)/,
|
||||
lookbehind: true
|
||||
},
|
||||
{
|
||||
pattern: /(\b(?:rpc\s+\w+|returns)\s*\(\s*(?:stream\s+)?)\.?[A-Za-z_]\w*(?:\.[A-Za-z_]\w*)*(?=\s*\))/,
|
||||
lookbehind: true
|
||||
}
|
||||
],
|
||||
'keyword': /\b(?:enum|extend|extensions|import|message|oneof|option|optional|package|public|repeated|required|reserved|returns|rpc(?=\s+\w)|service|stream|syntax|to)\b(?!\s*=\s*\d)/,
|
||||
'function': /\b[a-z_]\w*(?=\s*\()/i
|
||||
});
|
||||
|
||||
var builtinTypes = /\b(?:double|float|[su]?int(?:32|64)|s?fixed(?:32|64)|bool|string|bytes)\b/;
|
||||
|
||||
Prism.languages.insertBefore('protobuf', 'operator', {
|
||||
'map': {
|
||||
pattern: /\bmap<\s*[\w.]+\s*,\s*[\w.]+\s*>(?=\s+[a-z_]\w*\s*[=;])/i,
|
||||
alias: 'class-name',
|
||||
inside: {
|
||||
'punctuation': /[<>.,]/,
|
||||
'builtin': builtinTypes
|
||||
}
|
||||
},
|
||||
'builtin': builtinTypes,
|
||||
'positional-class-name': {
|
||||
pattern: /(?:\b|\B\.)[a-z_]\w*(?:\.[a-z_]\w*)*(?=\s+[a-z_]\w*\s*[=;])/i,
|
||||
alias: 'class-name',
|
||||
inside: {
|
||||
'punctuation': /\./
|
||||
}
|
||||
},
|
||||
'annotation': {
|
||||
pattern: /(\[\s*)[a-z_]\w*(?=\s*=)/i,
|
||||
lookbehind: true
|
||||
}
|
||||
});
|
||||
if (ExecutionEnvironment.canUseDOM) {
|
||||
window.Prism = Prism;
|
||||
require(`prismjs/components/prism-hcl`)
|
||||
delete window.Prism;
|
||||
}
|
||||
}
|
||||
12
doc/website/static/contrib/index.html
Normal file
12
doc/website/static/contrib/index.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta http-equiv="Content-Type" content="text/html; charset=utf-8"/>
|
||||
<meta name="go-import" content="entgo.io/contrib git https://github.com/ent/contrib">
|
||||
<meta name="go-source" content="entgo.io/contrib https://github.com/ent/contrib https://github.com/ent/contrib/tree/master{/dir} https://github.com/ent/contrib/blob/master{/dir}/{file}#L{line}">
|
||||
<meta http-equiv="refresh" content="0; url=https://pkg.go.dev/entgo.io/contrib">
|
||||
</head>
|
||||
<body>
|
||||
Nothing to see here; <a href="https://pkg.go.dev/entgo.io/contrib">move along</a>.
|
||||
</body>
|
||||
</html>
|
||||
12
doc/website/static/ent/cmd/ent/index.html
Normal file
12
doc/website/static/ent/cmd/ent/index.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta http-equiv="Content-Type" content="text/html; charset=utf-8"/>
|
||||
<meta name="go-import" content="entgo.io/ent git https://github.com/ent/ent">
|
||||
<meta name="go-source" content="entgo.io/ent https://github.com/ent/ent https://github.com/ent/ent/tree/master{/dir} https://github.com/ent/ent/blob/master{/dir}/{file}#L{line}">
|
||||
<meta http-equiv="refresh" content="0; url=https://pkg.go.dev/entgo.io/ent/cmd/ent">
|
||||
</head>
|
||||
<body>
|
||||
Nothing to see here; <a href="https://pkg.go.dev/entgo.io/ent/cmd/ent">move along</a>.
|
||||
</body>
|
||||
</html>
|
||||
12
doc/website/static/ent/cmd/entfix/index.html
Normal file
12
doc/website/static/ent/cmd/entfix/index.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta http-equiv="Content-Type" content="text/html; charset=utf-8"/>
|
||||
<meta name="go-import" content="entgo.io/ent git https://github.com/ent/ent">
|
||||
<meta name="go-source" content="entgo.io/ent https://github.com/ent/ent https://github.com/ent/ent/tree/master{/dir} https://github.com/ent/ent/blob/master{/dir}/{file}#L{line}">
|
||||
<meta http-equiv="refresh" content="0; url=https://pkg.go.dev/entgo.io/ent/entfix">
|
||||
</head>
|
||||
<body>
|
||||
Nothing to see here; <a href="https://pkg.go.dev/entgo.io/ent/entfix">move along</a>.
|
||||
</body>
|
||||
</html>
|
||||
12
doc/website/static/ent/entc/gen/index.html
Normal file
12
doc/website/static/ent/entc/gen/index.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta http-equiv="Content-Type" content="text/html; charset=utf-8"/>
|
||||
<meta name="go-import" content="entgo.io/ent git https://github.com/ent/ent">
|
||||
<meta name="go-source" content="entgo.io/ent https://github.com/ent/ent https://github.com/ent/ent/tree/master{/dir} https://github.com/ent/ent/blob/master{/dir}/{file}#L{line}">
|
||||
<meta http-equiv="refresh" content="0; url=https://pkg.go.dev/entgo.io/ent/entc/gen">
|
||||
</head>
|
||||
<body>
|
||||
Nothing to see here; <a href="https://pkg.go.dev/entgo.io/ent/entc/gen">move along</a>.
|
||||
</body>
|
||||
</html>
|
||||
12
doc/website/static/ent/entc/index.html
Normal file
12
doc/website/static/ent/entc/index.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta http-equiv="Content-Type" content="text/html; charset=utf-8"/>
|
||||
<meta name="go-import" content="entgo.io/ent git https://github.com/ent/ent">
|
||||
<meta name="go-source" content="entgo.io/ent https://github.com/ent/ent https://github.com/ent/ent/tree/master{/dir} https://github.com/ent/ent/blob/master{/dir}/{file}#L{line}">
|
||||
<meta http-equiv="refresh" content="0; url=https://pkg.go.dev/entgo.io/ent/entc">
|
||||
</head>
|
||||
<body>
|
||||
Nothing to see here; <a href="https://pkg.go.dev/entgo.io/ent/entc">move along</a>.
|
||||
</body>
|
||||
</html>
|
||||
12
doc/website/static/ent/index.html
Normal file
12
doc/website/static/ent/index.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta http-equiv="Content-Type" content="text/html; charset=utf-8"/>
|
||||
<meta name="go-import" content="entgo.io/ent git https://github.com/ent/ent">
|
||||
<meta name="go-source" content="entgo.io/ent https://github.com/ent/ent https://github.com/ent/ent/tree/master{/dir} https://github.com/ent/ent/blob/master{/dir}/{file}#L{line}">
|
||||
<meta http-equiv="refresh" content="0; url=https://pkg.go.dev/entgo.io/ent">
|
||||
</head>
|
||||
<body>
|
||||
Nothing to see here; <a href="https://pkg.go.dev/entgo.io/ent">move along</a>.
|
||||
</body>
|
||||
</html>
|
||||
BIN
doc/website/static/font/CalibreBold.woff
Normal file
BIN
doc/website/static/font/CalibreBold.woff
Normal file
Binary file not shown.
BIN
doc/website/static/font/CalibreLight.woff
Normal file
BIN
doc/website/static/font/CalibreLight.woff
Normal file
Binary file not shown.
BIN
doc/website/static/font/CalibreLightItalic.woff
Normal file
BIN
doc/website/static/font/CalibreLightItalic.woff
Normal file
Binary file not shown.
BIN
doc/website/static/font/CalibreMedium.woff
Normal file
BIN
doc/website/static/font/CalibreMedium.woff
Normal file
Binary file not shown.
BIN
doc/website/static/font/CalibreMediumItalic.woff
Normal file
BIN
doc/website/static/font/CalibreMediumItalic.woff
Normal file
Binary file not shown.
BIN
doc/website/static/font/CalibreRegular.woff
Normal file
BIN
doc/website/static/font/CalibreRegular.woff
Normal file
Binary file not shown.
BIN
doc/website/static/font/CalibreRegularItalic.woff
Normal file
BIN
doc/website/static/font/CalibreRegularItalic.woff
Normal file
Binary file not shown.
BIN
doc/website/static/font/CalibreSemibold.woff
Normal file
BIN
doc/website/static/font/CalibreSemibold.woff
Normal file
Binary file not shown.
BIN
doc/website/static/font/CalibreThin.woff
Normal file
BIN
doc/website/static/font/CalibreThin.woff
Normal file
Binary file not shown.
BIN
doc/website/static/font/CalibreThinItalic.woff
Normal file
BIN
doc/website/static/font/CalibreThinItalic.woff
Normal file
Binary file not shown.
BIN
doc/website/static/img/favicon.ico
Normal file
BIN
doc/website/static/img/favicon.ico
Normal file
Binary file not shown.
|
After Width: | Height: | Size: 806 B |
BIN
doc/website/static/img/logo.png
Normal file
BIN
doc/website/static/img/logo.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 1.3 KiB |
BIN
doc/website/static/img/oss_logo.png
Normal file
BIN
doc/website/static/img/oss_logo.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 4.3 KiB |
47
doc/website/static/js/code-block-buttons.js
Normal file
47
doc/website/static/js/code-block-buttons.js
Normal file
@@ -0,0 +1,47 @@
|
||||
// Turn off ESLint for this file because it's sent down to users as-is.
|
||||
/* eslint-disable */
|
||||
window.addEventListener('load', function() {
|
||||
function button(label, ariaLabel, icon, className) {
|
||||
const btn = document.createElement('button');
|
||||
btn.classList.add('btnIcon', className);
|
||||
btn.setAttribute('type', 'button');
|
||||
btn.setAttribute('aria-label', ariaLabel);
|
||||
btn.innerHTML =
|
||||
'<div class="btnIcon__body">' +
|
||||
icon +
|
||||
'<strong class="btnIcon__label">' +
|
||||
label +
|
||||
'</strong>' +
|
||||
'</div>';
|
||||
return btn;
|
||||
}
|
||||
|
||||
function addButtons(codeBlockSelector, btn) {
|
||||
document.querySelectorAll(codeBlockSelector).forEach(function(code) {
|
||||
code.parentNode.appendChild(btn.cloneNode(true));
|
||||
});
|
||||
}
|
||||
|
||||
const copyIcon =
|
||||
'<svg width="12" height="12" viewBox="340 364 14 15" xmlns="http://www.w3.org/2000/svg"><path fill="currentColor" d="M342 375.974h4v.998h-4v-.998zm5-5.987h-5v.998h5v-.998zm2 2.994v-1.995l-3 2.993 3 2.994v-1.996h5v-1.995h-5zm-4.5-.997H342v.998h2.5v-.997zm-2.5 2.993h2.5v-.998H342v.998zm9 .998h1v1.996c-.016.28-.11.514-.297.702-.187.187-.422.28-.703.296h-10c-.547 0-1-.452-1-.998v-10.976c0-.546.453-.998 1-.998h3c0-1.107.89-1.996 2-1.996 1.11 0 2 .89 2 1.996h3c.547 0 1 .452 1 .998v4.99h-1v-2.995h-10v8.98h10v-1.996zm-9-7.983h8c0-.544-.453-.996-1-.996h-1c-.547 0-1-.453-1-.998 0-.546-.453-.998-1-.998-.547 0-1 .452-1 .998 0 .545-.453.998-1 .998h-1c-.547 0-1 .452-1 .997z" fill-rule="evenodd"/></svg>';
|
||||
|
||||
addButtons(
|
||||
'.hljs',
|
||||
button('Copy', 'Copy code to clipboard', copyIcon, 'btnClipboard'),
|
||||
);
|
||||
|
||||
const clipboard = new ClipboardJS('.btnClipboard', {
|
||||
target: function(trigger) {
|
||||
return trigger.parentNode.querySelector('code');
|
||||
},
|
||||
});
|
||||
|
||||
clipboard.on('success', function(event) {
|
||||
event.clearSelection();
|
||||
const textEl = event.trigger.querySelector('.btnIcon__label');
|
||||
textEl.textContent = 'Copied';
|
||||
setTimeout(function() {
|
||||
textEl.textContent = 'Copy';
|
||||
}, 2000);
|
||||
});
|
||||
});
|
||||
17
doc/website/static/js/custom.js
Normal file
17
doc/website/static/js/custom.js
Normal file
@@ -0,0 +1,17 @@
|
||||
|
||||
/**
|
||||
* Copyright 2019-present Facebook Inc. All rights reserved.
|
||||
*
|
||||
* This source code is licensed under the Apache 2.0 license found
|
||||
* in the LICENSE file in the root directory of this source tree.
|
||||
*
|
||||
* @format
|
||||
*/
|
||||
|
||||
/* eslint-disable */
|
||||
window.addEventListener('load', function() {
|
||||
// add an id tag for images based on their alt attribute.
|
||||
document.querySelectorAll('.container img').forEach(function(el) {
|
||||
el.id = el.alt;
|
||||
});
|
||||
});
|
||||
Reference in New Issue
Block a user